Insights on Innovation, R&D, and IP
Perspectives on patents, scientific research, emerging technologies, and the strategies shaping modern R&D
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
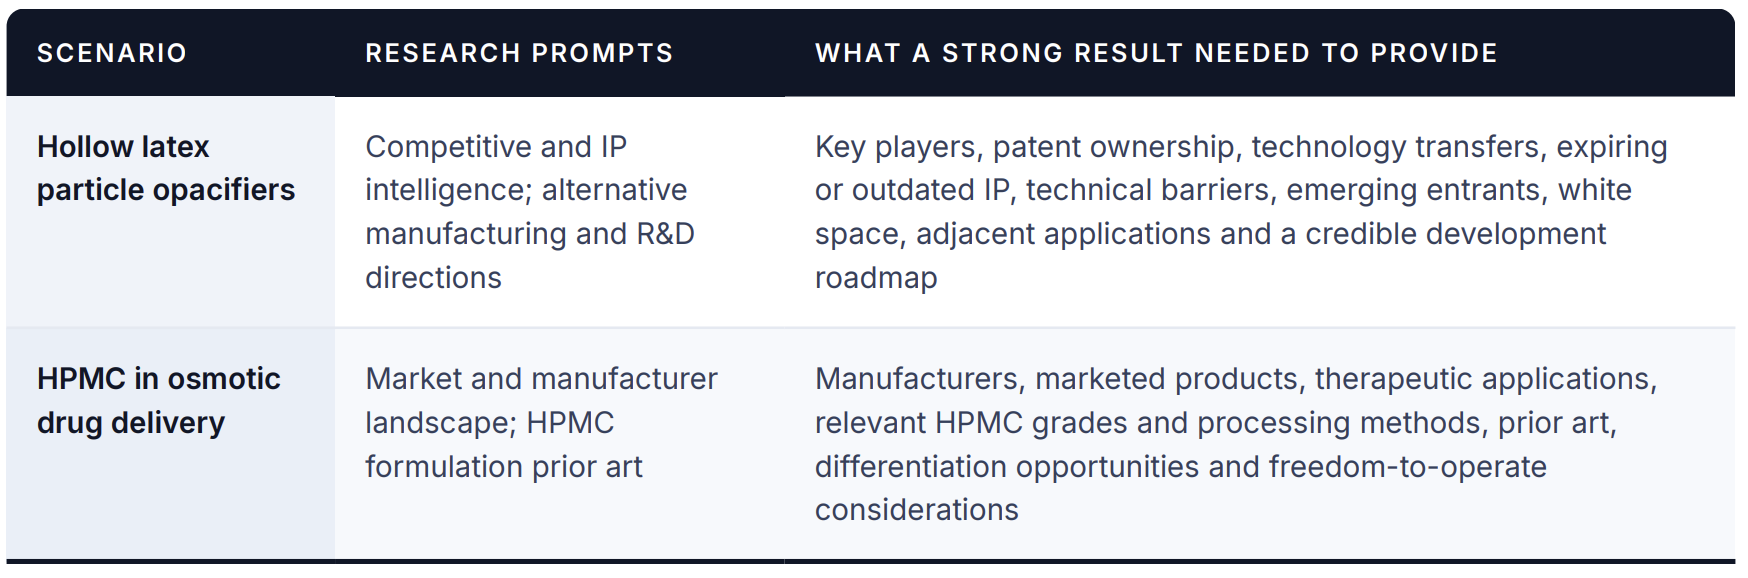
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
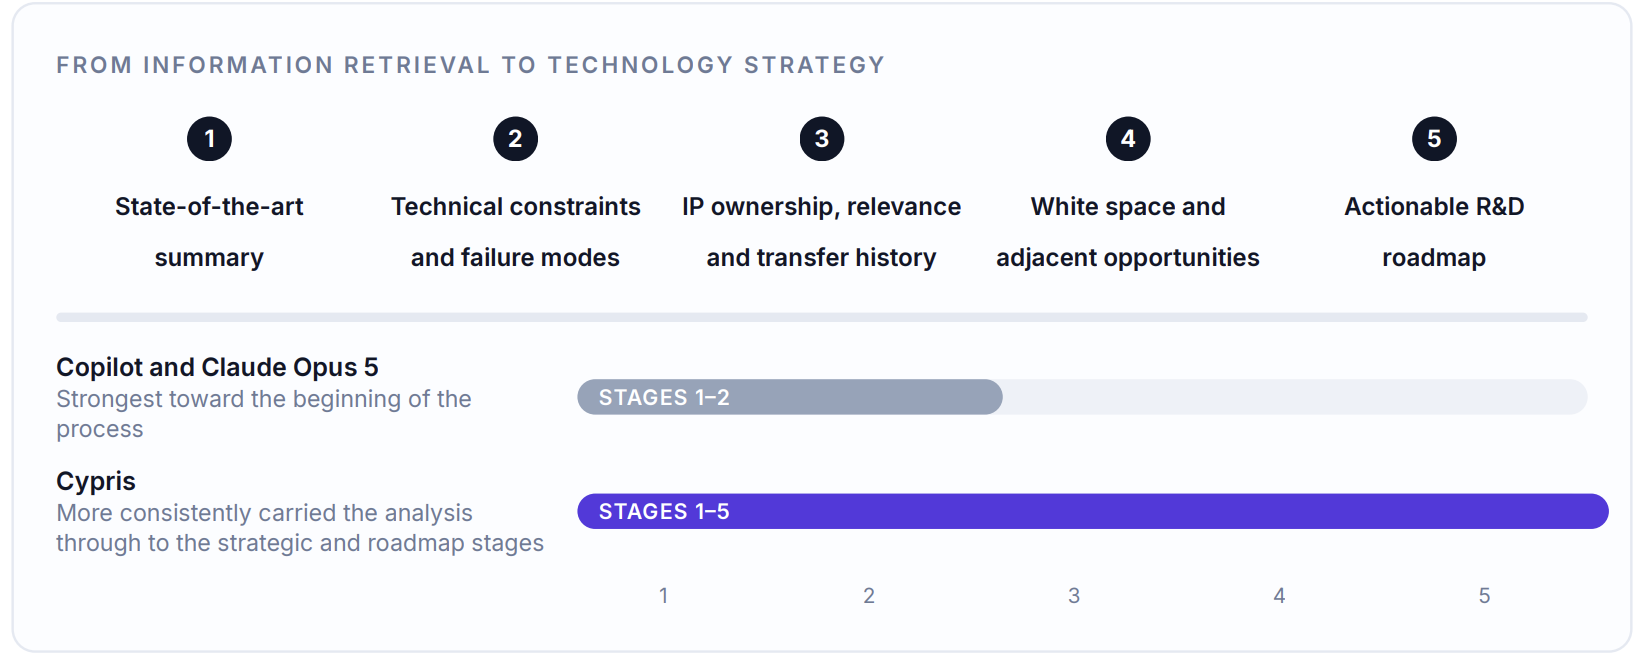
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
Comparative findings at a glance
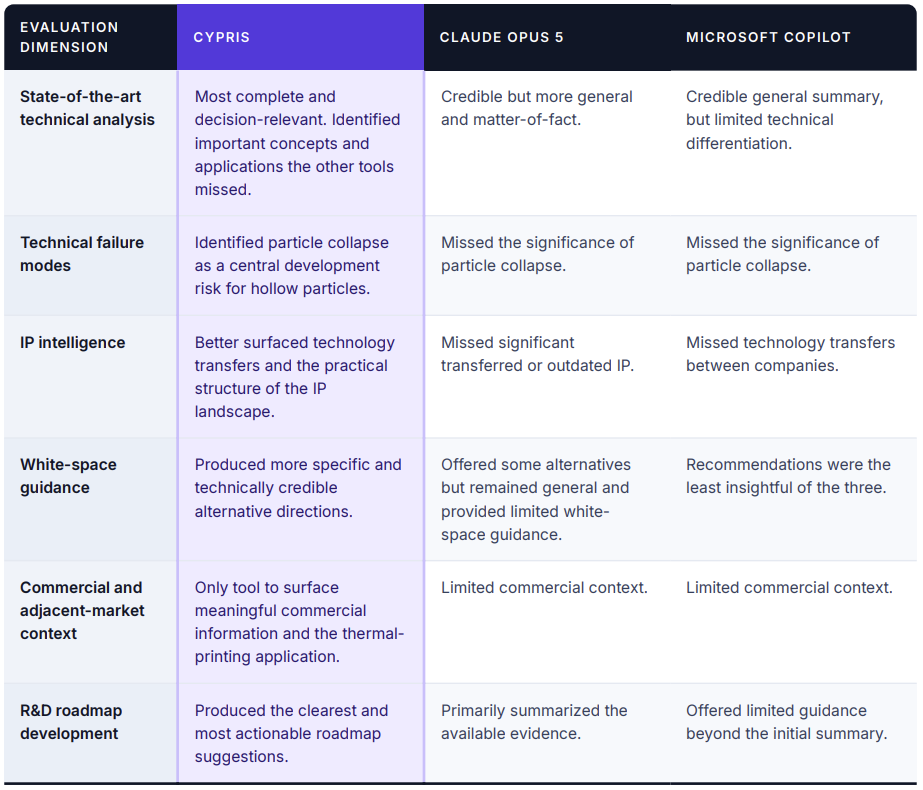
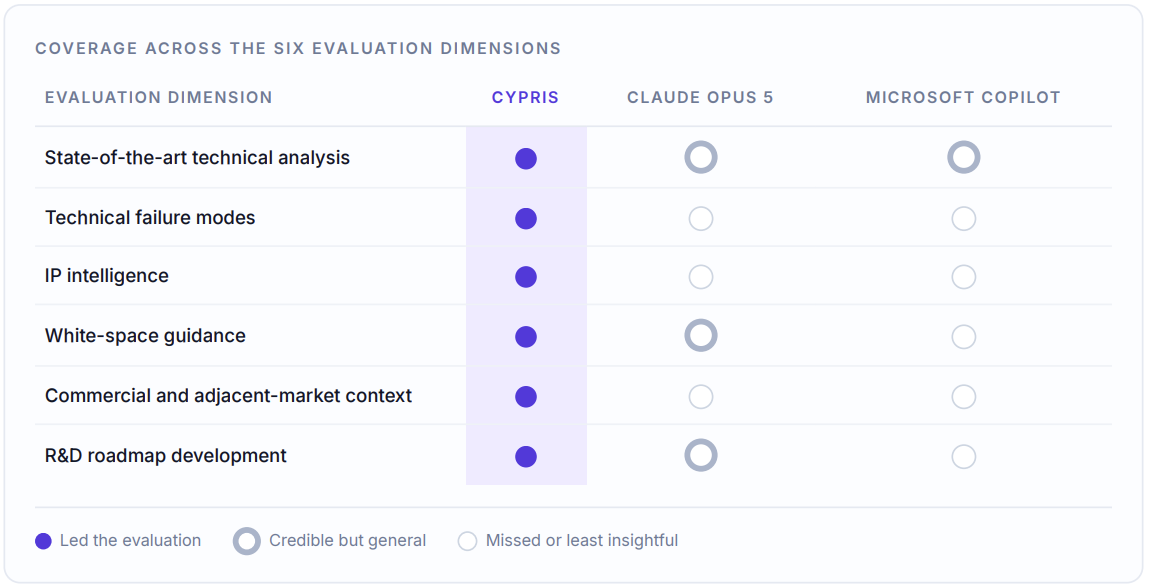
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
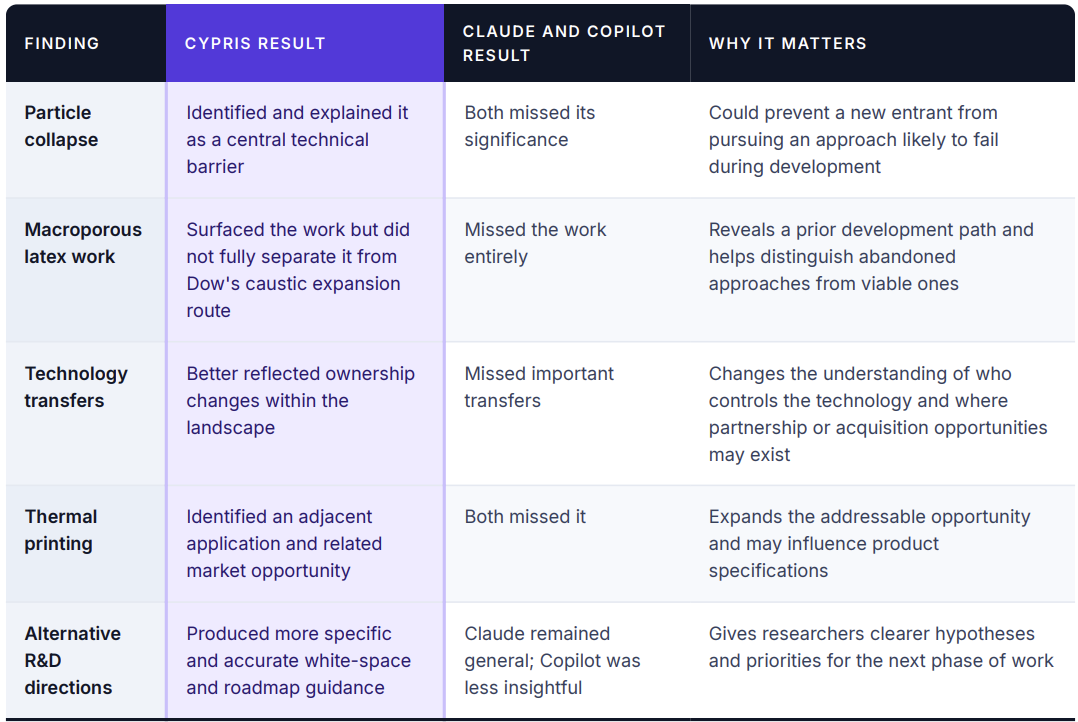
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
Former Dow Research Fellow Compares Cypris, Copilot & Claude for Chemical Intelligence
All Blogs
A prompt is a single instruction issued to a language model, executed once, by one person, in a context nobody else can see. An agent is an encoded workflow with a defined scope, a defined corpus, defined evidence standards, and defined output structure, executed the same way every time regardless of who runs it. The difference between them is not sophistication. It is control.
This distinction matters more in R&D than in almost any other enterprise function, because R&D decisions carry long horizons and large capital commitments, and because the analysis behind those decisions has to survive scrutiny from stage-gate committees, IP counsel, regulators, and partners. An analysis that cannot be reproduced cannot be defended. Most AI-assisted R&D work today is prompt-based, which means most of it cannot be reproduced.
The industry conversation has spent three years on prompt engineering as the path to better AI output. For exploratory work, that framing holds. For the recurring, decision-bearing analyses that R&D organizations actually run, it is the wrong problem entirely. The question is not how to write a better prompt. It is how to stop treating a repeated organizational process as an improvised individual act.
What a Prompt Actually Is
Strip away the tooling and a prompt is a one-time instruction with no persistence, no version, no scope definition, and no record of what informed it.
Consider what happens when a research scientist asks a general-purpose AI tool to summarize the competitive position in a technology domain. The model receives the question, retrieves or recalls whatever material it has access to, applies whatever reasoning the phrasing invites, and returns a fluent answer. The scientist reads it, adjusts the phrasing, asks again, gets a different answer, and keeps the one that seems best.
Four things about that process are worth naming precisely.
The instruction was never written down in a form anyone else can reuse. It exists in a chat window that will be closed. The next person who needs the same analysis will write their own instruction, differently.
The scope was never defined. The model decided what counted as in-scope based on inference from the question, and that inference is invisible. Two colleagues asking what they believe is the same question will get answers drawn from materially different material.
The evidence standard was never set. Nothing specified whether a claim required a citation, whether the citation had to resolve to a real document, or what counted as sufficient support for a conclusion. The output looks equally authoritative whether it is grounded or invented.
And the selection was unrecorded. The scientist ran the query several times and kept the version they preferred. That is a legitimate exploratory behavior and a serious problem if the retained answer becomes an input to a funding decision, because the discarded answers were part of the process and no longer exist.
None of this is a criticism of the scientist. It is a description of what a prompt is. A prompt has no mechanism for carrying any of that structure, which is why the same person asking the same question on two different days can get two different answers and have no way to explain the divergence.
What an Agent Actually Is
An agent is not a better prompt. It is a different category of artifact, and the clearest way to understand the difference is that an agent is written once and executed many times, whereas a prompt is written every time it is executed.
A properly constructed agent for R&D work encodes five things.
It encodes the scope, meaning the explicit boundaries of what the analysis covers, including the technology domain, geography, time range, adjacent areas treated as in-scope, and areas explicitly excluded. This is written down and is the same for every execution.
It encodes the corpus, meaning which datasets the analysis runs against and which it does not. Not an undifferentiated index that the model searches at its discretion, but a defined document set with stated inclusion criteria.
It encodes the method, meaning the sequence of analytical passes the agent performs and the order it performs them in. A landscape agent runs an activity pass, an actor pass, a structural pass, a temporal pass, and a gap pass because that sequence is written into the workflow, not because a given prompt happened to invite it.
It encodes the evidence standard, meaning what constitutes adequate support for a claim, whether citations are mandatory, and what the agent does when it cannot substantiate a finding.
And it encodes the output structure, meaning the shape of the deliverable, so that two analyses of two different technology domains produce comparable documents that can be evaluated side by side.
The consequence is that an agent produces the same analysis regardless of who invokes it. A junior researcher and a twenty-year veteran running the same agent on the same question get the same methodology applied. The veteran will interpret the output better, which is where their expertise should be spent. But the analysis itself is no longer a function of who happened to run it.
The Four Failures of Prompt-Based R&D Work
The practical costs of prompt-based analysis show up in four ways, and they compound.
The first is irreproducibility. If a program was killed eight months ago based on an AI-assisted landscape analysis, and someone now asks why, the honest answer under a prompt-based process is that nobody can reconstruct it. The chat is gone, the phrasing is unrecorded, and rerunning a similar query today produces a different answer against a corpus that has since changed. For organizations in regulated industries, and for any organization where R&D decisions are subject to internal audit, this is not a minor inconvenience.
The second is invisible variance. When five people on a team each prompt their way to an answer, the organization has five methodologies it cannot see. The outputs will look similar because they share a format and a tone. The analytical rigor behind them will vary enormously, and there is no way to tell which is which by reading them. Fluency conceals variance in a way that a spreadsheet never did.
The third is the absence of an audit trail. Enterprise agent architectures now treat full audit logging as a baseline requirement, capturing each instruction, intermediate reasoning step, model output, and tool call [1]. Prompt-based work has none of this by construction. When a finding turns out to be wrong, there is no way to determine whether the error came from the corpus, the framing, the model, or the interpretation, which means the error cannot be prevented from recurring.
The fourth, and the most consequential over time, is that knowledge stays with individuals. When someone becomes genuinely good at getting useful output from AI tools for patent landscape work, that skill lives in their head. It leaves when they leave. It does not transfer to their replacement, it does not raise the floor for the rest of the team, and the organization pays to develop it again. Prompt skill is a personal capability. Agent configuration is an institutional asset.
Standardization Is the Actual Product
The value proposition of agents in R&D is usually pitched as autonomy, meaning the agent works while you sleep. That is real but secondary. The primary value is standardization, and it produces four things that prompt-based work structurally cannot.
It produces comparability. When every technology domain in a portfolio is assessed through the same agent, the resulting analyses can be placed side by side and ranked. Under prompt-based work, differences between two analyses reflect differences in who ran them as much as differences in the underlying domains, which makes portfolio-level comparison unreliable.
It produces defensibility. A stage-gate committee asking how a conclusion was reached can be shown the agent configuration, the corpus definition, the analytical sequence, and the source documents behind each claim. This is the difference between an analysis and an opinion with citations.
It produces improvability. A methodology that is written down can be reviewed, criticized, and revised. When a landscape analysis misses a competitor because the corpus excluded a jurisdiction, that is a fixable configuration error, and the fix applies to every future execution. When the same thing happens under prompt-based work, it is an anecdote.
And it produces institutional memory. An agent library is an encoded record of how an organization does its analytical work. It is the R&D equivalent of a standard operating procedure, and it accrues value in the same way, by capturing what the organization has learned about how to do the work well.
Where Prompts Still Belong
The argument is not that prompting is obsolete. It is that prompting and agents solve different problems, and most organizations are using one for both.
Prompts are the right tool for exploration, where the question itself is still forming and the value comes from fast iteration. A researcher trying to understand an unfamiliar technical area, testing whether a hypothesis is worth pursuing, or working out how to frame a problem is doing work that would be slowed down, not improved, by a standardized workflow. Exploratory work is supposed to be idiosyncratic.
Agents are the right tool for any analysis that is recurring, decision-bearing, or subject to review. Landscape analysis, freedom-to-operate assessment, prior art review, technology scouting, competitive monitoring, and portfolio evaluation all meet at least two of those three criteria, and most meet all three.
The practical test is a question: if two people on this team performed this analysis independently, would we expect the same answer, and would it matter if we did not get it? When the answer to the second part is yes, the work belongs in an agent.
The R&D Organization of the Next Five Years
Agents change what R&D teams look like, and the changes are more structural than the current productivity framing suggests. Five shifts are already visible.
The analyst role moves up a level. The work of performing analysis moves into agents. The work of designing analysis, auditing it, and interpreting it stays with people and becomes more valuable. This is not a headcount story in either direction. It is a change in what R&D analysts are for. The skill that appreciates is knowing what question to ask, what evidence would answer it, and what the output is not telling you. The skill that depreciates is executing search syntax and building charts.
Intelligence becomes ambient rather than requested. The current model is that someone asks for a landscape analysis, waits several weeks, and receives a document that begins aging on delivery. The agent model is that the analysis runs continuously and surfaces findings when they meet a defined threshold. The organizational consequence is significant: R&D teams stop making decisions against a stale snapshot and start operating with a maintained view. It also removes the request-and-wait friction that currently causes teams to skip the analysis entirely on smaller decisions.
Methodology becomes a company asset. Organizations will maintain agent libraries the way they maintain SOPs, with versioning, ownership, and review cycles. How your company runs a freedom-to-operate assessment will become a documented, improvable thing rather than a set of habits distributed across a few experienced people. This is the shift with the longest-term competitive effect, because it means analytical quality compounds within the organization instead of walking out the door periodically.
Evidence standards at stage-gate rise. When it becomes cheap to produce a rigorous, cited, reproducible analysis, the bar for what counts as adequate diligence moves. Committees will start asking which agent produced a finding, what corpus it ran against, and when it last executed. Programs supported by an unverifiable summary will face harder questions than they do today. This is a good outcome, and it will be uncomfortable for a while.
Governance becomes the binding constraint. This is the shift most organizations are underestimating. IBM's 2026 study found 94% of enterprises report that AI sprawl is raising security risk and operational complexity, with agents proliferating across teams and frameworks in ways that produce fragmentation rather than capability [2]. Deloitte's 2026 research found that only 21% of surveyed organizations have a mature AI-agent governance model while roughly 75% intend to deploy agentic AI within two years [3]. KPMG tracked enterprise agent deployment rising from 11% to 42% over 2025 before falling back to 26% in the fourth quarter, a pullback attributed to leaders shifting from pilots toward professionalizing and scaling their agent systems [3].
That pullback is the most instructive data point in the set. It is not evidence that agents failed. It is evidence that organizations discovered the hard part is not building an agent, it is running a governed portfolio of them. R&D organizations that treat agent standardization as an operating discipline rather than a tool purchase will be the ones that get through that transition without accumulating the sprawl everyone else is now trying to consolidate.
What to Do Now
The first step is an inventory, not a purchase. Identify the analyses your R&D organization performs repeatedly and that inform resource commitments. For most enterprise teams that list includes landscape analysis, freedom-to-operate, prior art review, technology scouting, competitor monitoring, and partner or acquisition screening.
The second step is to write down how one of them is actually performed today. Not how the process document says it is performed, but what the person who does it actually does. This is usually uncomfortable, because the honest version reveals how much of the method exists only in one person's judgment.
The third step is to encode that method as an agent configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, and to treat that configuration as a versioned artifact with an owner.
The fourth step is to run it in parallel with the existing process for a cycle and compare. The point is not to prove the agent is faster. It is to find where the encoded method and the human method diverge, because those divergences are where the undocumented expertise lives, and capturing them is the actual work.
How Cypris Approaches This
Cypris is an AI-native R&D intelligence platform built around the premise that the recurring analyses R&D and IP teams depend on should be standardized workflows rather than improvised queries.
Cypris Q, the platform's agentic layer, runs patent landscape analysis, white space mapping, freedom-to-operate, technology scouting, and competitive intelligence as domain workflows rather than as raw prompts. The distinction is the one this article describes. The agent already carries the structure of the analysis, meaning it knows how to frame the question, which analytical passes to run, what constitutes a finding, and how to shape the output. A user is not responsible for reconstructing the methodology in a prompt each time, which is what makes output consistent across people and across executions.
The workflows run against a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology. The ontology matters for standardization specifically, because it means the agent resolves terminology variation across jurisdictions and research traditions the same way every time, rather than depending on whether a given user happened to include the right synonyms in their query. Teams can also configure custom corpora of patent and non-patent literature scoped to a particular domain, which makes the corpus definition an explicit, reviewable part of the workflow rather than an invisible model decision.
Output is generated with citations anchored to verifiable source records. This is the evidence standard component, and it is what allows an analysis to be checked rather than trusted.
Agentic Monitoring, launched in June 2026, is the persistence layer. It runs continuously across patent offices, scientific literature, chemical compound databases, regulatory bodies, M&A activity, product launches, grant awards, and corporate news [4]. Teams define their monitoring domains once and receive filtered, contextualized intelligence on a defined cadence. This is the operational form of the ambient intelligence shift described above, converting periodic manual rebuilds into a maintained baseline with exception reporting.
For organizations standardizing on general-purpose AI platforms, Cypris exposes the same layer through an MCP server and through enterprise API partnerships with OpenAI, Anthropic, and Google. In August 2026 the company launched Cypris Q for Microsoft Copilot, allowing teams to call Cypris agents for landscape analysis, prior art research, technology scouting, and competitive intelligence from within their existing Microsoft environment [5]. The design principle is consistent with the argument here: the general-purpose model supplies reasoning and interface, while the domain layer supplies the standardized method and the grounded corpus.
Cypris serves hundreds of enterprise customers and thousands of researchers across pharmaceuticals, chemicals, advanced materials, and electronics, with enterprise-grade security meeting Fortune 500 requirements.
The Underlying Point
Every organization that has industrialized a knowledge process went through the same transition, from skilled individuals doing the work their own way to a documented method executed consistently. Manufacturing did it. Clinical research did it. Software engineering did it. R&D intelligence is going through it now, and the transition is being obscured by a conversation about prompting that frames an organizational problem as a personal skill.
The teams that will be ahead in three years are not the ones with the best prompt engineers. They are the ones that stopped needing them.
Frequently Asked Questions
What is the difference between a prompt and an AI agent?
A prompt is a single instruction issued to a language model, executed once, with no persistent record of its scope, corpus, or evidence standard. An AI agent is an encoded workflow that defines scope, corpus, analytical method, evidence standards, and output structure in advance, and executes the same way every time regardless of who invokes it. The difference is standardization and reproducibility rather than sophistication.
Why are prompts a problem for R&D analysis specifically?
R&D decisions carry long horizons and large capital commitments, and the analyses supporting them are reviewed by stage-gate committees, IP counsel, and sometimes regulators. Prompt-based analysis cannot be reproduced, contains invisible variation between users, and generates no audit trail, which means a conclusion cannot be reconstructed or defended after the fact.
Is prompt engineering still useful?
Yes, for exploratory work where the question is still forming and rapid iteration is the point. Prompting is the wrong approach for analyses that recur, that inform resource commitments, or that are subject to review, because those require consistency across people and executions that a prompt cannot provide.
What makes an AI agent standardized?
A standardized agent encodes five components in advance: the scope of the analysis including explicit inclusions and exclusions, the corpus it runs against, the sequence of analytical passes it performs, the evidence standard governing what constitutes a supported claim, and the structure of the output. Because these are written once and executed many times, two different people running the agent receive the same methodology.
Can an AI agent replace R&D analysts?
No. Agents absorb the execution of analysis, while designing the analysis, auditing its output, and interpreting findings remain human work and become more valuable. The skill that appreciates is knowing what question to ask and what the output is not showing. The skill that depreciates is executing search syntax and producing charts.
How will AI agents change R&D teams?
Five shifts are underway: analyst work moves from performing analysis to designing and auditing it; intelligence becomes continuous rather than requested on demand; analytical methodology becomes a documented company asset rather than individual expertise; evidence standards at stage-gate reviews rise as rigorous analysis becomes cheaper to produce; and agent governance becomes the primary organizational constraint on scaling.
What is agent sprawl and why does it matter for R&D?
Agent sprawl is the proliferation of AI agents built independently across teams, functions, and frameworks without shared governance. IBM's 2026 Institute for Business Value study found 94% of enterprises report AI sprawl is raising security risk and operational complexity. For R&D organizations, sprawl reintroduces the variance problem that agents were meant to solve, because ten ungoverned agents produce the same inconsistency as ten people prompting.
How mature is enterprise agent governance?
Low relative to deployment intent. Deloitte's 2026 research across more than 3,200 director-level and C-suite respondents found only 21% of organizations have a mature AI-agent governance model while approximately 75% plan to deploy agentic AI within two years. KPMG tracked deployment rising from 11% to 42% across 2025 before pulling back to 26% in the fourth quarter, attributed to leaders moving from pilots to professionalizing agent systems.
How do you turn an existing R&D analysis into an agent?
Start by documenting how the analysis is actually performed today rather than how the process document describes it. Then encode that method as a configuration with explicit scope, corpus, analytical sequence, evidence standard, and output structure, treated as a versioned artifact with a named owner. Run it in parallel with the existing process for one cycle and examine where the encoded and human methods diverge, since those divergences identify the undocumented expertise that needs capturing.
What tools run standardized R&D agent workflows?
Enterprise R&D intelligence platforms are the category built for this. Cypris runs patent landscape analysis, white space mapping, freedom-to-operate, and technology scouting as domain workflows through Cypris Q, its agentic layer, against a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, with continuous execution through Agentic Monitoring and access through an MCP server, enterprise API partnerships with OpenAI, Anthropic, and Google, and Cypris Q for Microsoft Copilot.
A patent landscape analysis is a structured assessment of the intellectual property and technical activity in a defined technology domain, conducted to answer a specific strategic question about where innovation is concentrated, who is driving it, and where the remaining opportunity sits. For corporate R&D teams, it is the analysis that determines which research programs get funded, which partnerships get pursued, and which technology bets get abandoned before resources are committed.
The methodology most teams still follow was designed for a different era of data volume and a different kind of tooling. It assumes a human analyst constructing Boolean queries against a patent database, exporting results to a spreadsheet, manually classifying records into technology buckets, and building charts that summarize assignee counts and filing trends over time. That process produces a deliverable, but it takes weeks, it degrades the moment new filings publish, and it answers a narrower question than the one leadership actually asked.
This guide covers the modern methodology. The two changes that matter most are that the analytical work is now performed by a curated AI agent rather than by manual query construction, and that the corpus the analysis runs against must extend well beyond patents to be strategically useful. Everything else in the process follows from those two shifts.
What a Patent Landscape Analysis Is and What It Is Not
A patent landscape analysis maps the competitive and technical structure of a technology domain using the documented innovation record. It identifies who is active, what they are working on, how their activity has changed over time, where activity clusters, and where it thins out.
It is distinct from three adjacent workflows that teams often conflate with it. A prior art search establishes whether a specific invention is novel. A freedom-to-operate analysis assesses whether commercializing a specific product would infringe active claims in target markets. A technology scouting exercise looks forward to identify emerging capabilities and potential partners. A landscape analysis is broader than the first two and more structured than the third. It produces the map that the other three operate on.
The strategic value of a landscape analysis comes from what it enables downstream. It informs portfolio strategy by showing where a company's own filings sit relative to competitors. It informs research prioritization by revealing which technical approaches are crowded and which are underexplored. It informs partnership and acquisition strategy by surfacing which organizations hold positions a company lacks. And it informs risk assessment by identifying the density of third-party claims a program will eventually have to navigate.
Why the Traditional Methodology Now Fails
Three structural problems have made manual landscape analysis unreliable for enterprise decision-making.
The first is volume. Global patent filings reached 3.7 million in 2025, the fastest annual growth since 2018, and scientific publications passed 2 million articles in the same year [1]. A technology domain that produced a manageable result set five years ago now returns volumes that exceed what a human analyst can read, let alone classify with consistency. Teams respond by narrowing the query until the result set is manageable, which reintroduces the sampling error the analysis was supposed to eliminate.
The second is vocabulary. Technical language varies across jurisdictions, research traditions, corporate filing practices, and time periods. Patent attorneys draft claims to broaden coverage, which frequently means describing a well-known technique in unfamiliar terms. A keyword-driven query finds documents that use the analyst's vocabulary and misses documents that use anyone else's. Classification codes help but were not designed to track technologies that cross established categories, which describes most of the technologies enterprises care about.
The third is latency. Patents publish eighteen months after their priority date in most jurisdictions. A landscape built exclusively on the patent record is therefore a picture of competitive positioning as it existed a year and a half ago, presented as though it describes the present. For slow-moving domains this matters less. For domains where the competitive position can shift within a single funding cycle, it produces confident conclusions about a world that no longer exists.
None of these problems are solved by running the same manual process faster. They are solved by changing what the analysis runs against and what performs the analysis.
The Case for a Multi-Dataset Corpus
The single most consequential decision in a modern landscape analysis is what goes into the corpus. Most teams treat this as settled, because the workflow is called patent landscape analysis and the obvious input is patents. That assumption is where the majority of landscape analyses go wrong.
Patent data is a record of what organizations chose to protect, filed through a legal process, published on a statutory delay. It is a high-quality signal about competitive intent, and it is incomplete in specific and predictable ways. Research published in the patentometrics literature makes the limitation explicit, noting that a comprehensive technical assessment would ideally integrate patent records with experimental, clinical, and industrial data, and that patent-only analysis is intentionally scoped to innovation trends and knowledge flows rather than to the full technical picture [2].
Consider what patent-only analysis structurally cannot see. It cannot see work that organizations deliberately keep as trade secrets, which is common in process chemistry, manufacturing methods, and formulation. It cannot see defensive publications filed specifically to block others without seeking protection. It cannot see academic and national-lab research that will become commercially relevant but has not yet been commercialized by anyone. It cannot see regulatory filings that reveal which compounds and devices are actually moving toward market. It cannot see funding activity, which is often the earliest reliable indicator that a technical approach has attracted serious capital. And it cannot see hiring, acquisition, and facility investment, which indicate where organizations are building capability ahead of any filing.
The practical consequence is that a patent-only landscape systematically overstates the position of organizations with aggressive filing strategies and understates the position of organizations that protect through secrecy or that are still upstream of commercialization. A landscape of a chemical process domain built only on patents will typically miss the most sophisticated competitors entirely, because the leading process improvements are held as trade secrets.
Scientific literature deserves particular emphasis because of the timing advantage it provides. Publications frequently surface technical developments six to eighteen months before associated patents publish, and often earlier, because academic and corporate research groups publish results well ahead of the point at which a commercial application becomes patentable. Adding literature to the corpus moves the early-warning signal forward by roughly the length of the patent publication delay, which is to say it substantially eliminates the latency problem described above.
A properly constructed corpus for enterprise landscape work therefore includes global patent records, peer-reviewed and preprint scientific literature, regulatory filings and approvals in relevant jurisdictions, grant and public funding awards, clinical or field trial registries where applicable, corporate disclosures including M&A and product launches, and where relevant, chemical structure and reaction data. The point is not to maximize volume. The point is that each dataset covers a blind spot in the others, and the strategic question the analysis is meant to answer almost always spans more than one of them.
Step One: Define the Strategic Question, Not the Technology Field
The traditional first step is scope definition: name the technology domain, set the geography, set the date range, list the competitors. That step is still necessary, but it is not the first step, and treating it as the first step is why so many landscape analyses produce a competent map that answers nothing.
Start instead with the decision the analysis exists to support. "Should we build internal capability in solid-state electrolytes or license it" is a different question from "which organizations lead in solid-state electrolytes," and the two require different corpora, different classification schemes, and different outputs. A licensing question requires depth on assignee portfolios, claim scope, and expiry timelines. A build-versus-buy question requires depth on capability signals, hiring, funding, and academic pipelines.
Write the question down before defining anything else. Then derive the technology scope, geography, time range, and competitor set from the question rather than from the technology label. Geography should be set by where commercialization will occur and where competitors manufacture, not by convenience. Time range should extend back far enough to capture the technical lineage of the approach, which for most technologies means longer than the five years teams typically default to.
Step Two: Curate the Corpus Before Curating the Agent
Once the question is defined, assemble the datasets that can answer it. This is the step that has no equivalent in the traditional methodology, and it is where most of the analytical quality is determined.
Corpus curation means deliberately selecting and scoping the document set the analysis will reason over, rather than pointing a query at an undifferentiated index. The distinction matters enormously when an AI system is doing the analysis. An agent given the entire global patent record and asked about solid-state electrolytes will retrieve a large volume of loosely related material and reason over a diluted context. An agent given a curated corpus of solid-state electrolyte patents, the relevant electrochemistry literature, the associated grant awards, and the regulatory and safety record will reason over a dense, high-signal context and produce materially better output.
This is the practical answer to the failure mode most teams experience when they try to run landscape analysis through a general-purpose AI tool. The disappointing results are usually not a reasoning failure. They are a retrieval failure. The model was never given the right material, and no amount of prompt refinement compensates for a corpus that does not contain the answer.
Curate deliberately. Include the datasets that cover your question's blind spots. Set inclusion criteria explicitly, including which jurisdictions, which document types, which date boundaries, and which classification codes or subject areas. Document what you excluded and why, because that record is what makes the analysis defensible when someone challenges a conclusion.
Step Three: Configure the Agent's Scope and Reasoning Boundaries
With the corpus set, the next step is configuring the agent that will run the analysis. This is a design exercise, not a prompting exercise, and it has four components.
The first is the strategic envelope, which is the agent's statement of what the analysis is for. This is the strategic question from step one, expressed in enough detail that the agent can distinguish a relevant finding from an interesting one. Without it, the agent optimizes for comprehensiveness and returns everything.
The second is technical and market scope, which defines the boundaries of the domain in the agent's own working vocabulary. This should include the alternative terminology, adjacent technical approaches that should be treated as in-scope, and the approaches that should be treated as out-of-scope even though they will surface. Specifying exclusions is at least as valuable as specifying inclusions.
The third is evidence priorities, which tells the agent what kinds of evidence carry weight for this particular question. A landscape supporting an acquisition decision should weight assignee-level portfolio structure and claim breadth heavily. A landscape supporting a research prioritization decision should weight publication velocity, grant activity, and technical novelty more heavily than filing counts.
The fourth is escalation criteria, which defines what constitutes a finding significant enough to surface prominently rather than list. Without escalation criteria, the agent produces a flat inventory and the human analyst has to do the prioritization work manually, which is most of the work.
A well-configured agent is one where a knowledgeable colleague could read the configuration and correctly predict what the agent would flag and what it would ignore. If the configuration does not support that prediction, it is underspecified.
Step Four: Classify Through an Ontology Rather Than a Flat Taxonomy
The classification step determines what the landscape actually shows. Traditional methodology uses either patent classification codes or a flat taxonomy the analyst constructs by hand, and both approaches struggle with the same problem: technologies that span categories get assigned to one bucket and disappear from the others.
An ontology-based approach handles this differently. Rather than assigning each document to a single category, an ontology represents the relationships between technical concepts, so a document about a solid-state electrolyte using a sulfide chemistry for an automotive application is represented as sitting at the intersection of all three, and appears correctly in any analysis touching any of them. It also resolves the vocabulary problem, because an ontology encodes that different terms across jurisdictions and research traditions refer to the same underlying concept.
This is the difference between a landscape that shows filing counts by assignee and a landscape that shows which technical approaches are converging, which is where most of the strategic value sits. Convergence is invisible in a flat taxonomy because it is a relationship rather than a category.
Step Five: Run the Analytical Passes
With corpus, configuration, and classification in place, the analysis itself runs as a series of passes over the same material, each answering a different part of the strategic question.
The activity pass establishes volume and velocity: how much work is happening in each part of the domain, and whether it is accelerating or slowing. Velocity matters more than volume, because a small but rapidly accelerating cluster is usually a stronger signal than a large stable one.
The actor pass establishes who is active and in what capacity. This should distinguish between organizations filing heavily, organizations publishing heavily, organizations receiving funding, and organizations acquiring capability, because those are four different competitive postures and a patent-only analysis collapses them into one.
The structural pass establishes how the domain is organized: which technical approaches exist, how they relate, where citation and collaboration networks concentrate, and where the boundaries between approaches are dissolving.
The temporal pass establishes how the domain has changed, which requires the analysis to distinguish between genuine shifts in research direction and artifacts of publication delay or filing strategy changes.
The gap pass identifies where activity is sparse. This is the pass that requires the most caution, and the reason is worth stating plainly. An area of the map with few patents is not automatically an opportunity. It may be sparse because the approach was tried and failed, because it is covered by trade secrets, because it is not commercially viable, or because the regulatory pathway is closed. Patent white space and commercial opportunity space are distinct concepts, and treating an empty region of the patent map as an open market is one of the most expensive errors in R&D strategy. A multi-dataset corpus is what allows the gap pass to distinguish between the two, because the literature, regulatory, and funding records will show whether anyone has tried.
Step Six: Validate Before You Synthesize
AI-generated landscape analysis is only usable if every material claim traces to a verifiable source document. This is not a theoretical concern. General-purpose language models asked patent questions will produce plausible patent numbers that do not exist, misstate priority and publication dates, and attribute filings to the wrong assignee, because they are generating from training data rather than retrieving from a live record.
Build validation into the process rather than treating it as a review step. Require that every finding carries a citation to a specific document. Spot-check a sample of citations against the source record, weighted toward the findings that will drive the decision. Verify assignee names against corporate structure, because subsidiaries, joint ventures, and post-acquisition transfers routinely fragment a single competitor's portfolio across several names and make a strong position look weak. Check the date boundaries on any trend claim, because apparent declines in recent filing activity are usually the publication delay rather than a real slowdown.
Step Seven: Synthesize Into a Decision Artifact
The output of a landscape analysis is not the map. It is the answer to the strategic question from step one, supported by the map.
The deliverable should lead with the answer and the confidence level attached to it, followed by the specific evidence that supports it, followed by what the analysis could not determine and why. That last section is what separates a credible analysis from a persuasive one. Every landscape has blind spots, and naming them is what allows the decision-maker to weight the conclusion appropriately.
Visual outputs still matter, but they should be selected to support the argument rather than produced as a standard set. A landscape supporting a build-versus-buy decision needs a capability map by organization. A landscape supporting research prioritization needs a convergence view. Producing all of them regardless of question is a habit from the era when the charts were the deliverable.
Step Eight: Convert the Analysis From an Event to a Process
A landscape analysis begins degrading the day it is delivered. New filings publish, new papers appear, competitors announce, regulators act. The traditional response is to rebuild the analysis quarterly or annually, which means the organization operates on a picture that is between one and twelve months stale, and the rebuild consumes the same effort every cycle.
The alternative is to treat the configured agent as a persistent asset. Once the corpus is curated and the agent is configured, the same configuration can run continuously, evaluating new material against the strategic question as it appears and surfacing only what meets the escalation criteria defined in step three. The initial landscape becomes the baseline, and the ongoing work becomes exception handling rather than reconstruction.
This is the largest practical return on the agent-curation approach. The configuration work in steps two and three is front-loaded and non-trivial. It pays back over every subsequent cycle, because the expensive part of the traditional process was never the searching. It was the rebuilding.
Common Failure Modes
The most common failure is scoping to the technology instead of to the decision, which produces a comprehensive map that supports no particular conclusion.
The second is corpus poverty, where the analysis runs against patents alone and reaches confident conclusions about domains where the most important activity is not patented.
The third is treating white space as opportunity, addressed above, which is the failure with the highest cost attached to it.
The fourth is unvalidated AI output, where the analysis is fluent, well-organized, and contains fabricated citations that nobody checked because the document read as authoritative.
The fifth is the assignee fragmentation error, where a competitor's position is understated because their portfolio is distributed across subsidiaries and acquisition vehicles that were never consolidated.
The sixth is treating the analysis as a deliverable rather than a capability, which guarantees the organization pays the full cost again next cycle.
Tooling for Landscape Analysis
The tools available for this work fall into three categories, and the distinction matters because they were built for different users.
Free and open resources including Google Patents, The Lens, and PQAI provide access to patent records and, in some cases, linked scholarly data. They are appropriate for verification, spot-checking, and early scoping. They do not provide the corpus curation, agent configuration, or continuous execution that enterprise landscape work requires.
Legacy professional platforms including Derwent Innovation and Orbit Intelligence from Questel provide curated patent data, sophisticated search syntax, and analytical tooling built over decades. They were designed for IP professionals conducting prosecution and litigation support work, and their strengths reflect that: claim-level precision, family management, and legal status tracking. Their limitation for landscape work is that they are patent-centric by design, and the search-and-export workflow assumes a human analyst performing the reasoning.
Enterprise R&D intelligence platforms are the category built for the methodology described in this guide, combining multi-dataset corpora with agentic execution and continuous operation.
How Cypris Supports Patent Landscape Analysis
Cypris is an AI-native R&D intelligence platform built for corporate R&D teams, IP managers, and innovation strategists conducting landscape, white space, freedom-to-operate, and technology scouting work. It is designed around the two shifts this guide describes: a corpus that extends beyond patents, and analysis performed by domain-configured agents rather than manual query construction.
The platform runs on a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology is the component that addresses the classification problem described in step four. Rather than assigning documents to flat categories, it represents relationships between technical concepts, so cross-category technologies appear correctly wherever they are relevant and terminology variation across jurisdictions and research traditions resolves to the same underlying concept. This is what allows convergence analysis, which is invisible to classification-code approaches.
Corpus curation is directly supported. Teams can configure custom corpora of patent and non-patent literature scoped to a specific technology domain and strategic question, which is the step-two work described above. Scoping retrieval before it reaches the model is the practical answer to the context degradation problem that causes general-purpose AI tools to produce diluted output on technical questions.
Cypris Q, the platform's agentic layer, runs patent landscape analysis, white space mapping, freedom-to-operate, and technology scouting as domain workflows rather than as raw queries. The distinction is that the agent already carries the structure of the analysis, so it knows how to frame a landscape question, which passes to run, and what constitutes a finding, rather than requiring the user to specify the methodology in a prompt. Output is generated with citations anchored to verifiable source records, which supports the validation requirements in step six.
Agentic Monitoring, launched in June 2026, addresses step eight. It runs continuously across patent offices, scientific literature, chemical compound databases, regulatory bodies, M&A activity, product launches, grant awards, and corporate news [3]. Teams define their monitoring domains once, and the agents deliver filtered, contextualized intelligence on a cadence that fits the workflow. In landscape terms, this converts the quarterly manual rebuild into a maintained baseline with exception reporting, and it is the mechanism by which the multi-dataset argument becomes operational rather than aspirational.
For teams that have standardized on general-purpose AI platforms, Cypris exposes the same intelligence layer through an MCP server and through enterprise API partnerships with OpenAI, Anthropic, and Google. In August 2026 the company launched Cypris Q for Microsoft Copilot, which allows enterprise teams to call Cypris agents for landscape analysis, prior art research, technology scouting, and competitive intelligence from within their existing Microsoft environment [4]. The design principle is that the base model provides the reasoning and conversational interface while the domain layer scopes retrieval and supplies the structure, which is the pattern that produces reliable output on technical questions.
Cypris serves hundreds of enterprise customers and thousands of researchers across pharmaceuticals, chemicals, advanced materials, electronics, and other technical industries, with enterprise-grade security meeting Fortune 500 requirements.
Getting Started
If your team currently rebuilds landscape analyses manually each quarter, the highest-return change is not adopting an AI tool. It is writing down the strategic question the analysis exists to answer, auditing which datasets can actually answer it, and noticing how many of them are missing from your current corpus. The agent configuration follows from that, and the continuous operation follows from the configuration.
Frequently Asked Questions
What is a patent landscape analysis?
A patent landscape analysis is a structured assessment of the intellectual property and technical activity within a defined technology domain, conducted to determine where innovation is concentrated, which organizations are driving it, how the domain has evolved, and where opportunity remains. It informs portfolio strategy, research prioritization, partnership decisions, and risk assessment for corporate R&D and IP teams.
How is a patent landscape analysis different from a freedom-to-operate analysis?
A patent landscape analysis maps the competitive and technical structure of an entire technology domain to support strategic decisions. A freedom-to-operate analysis assesses whether a specific product or process would infringe active patent claims in target markets. Landscape analysis is broad and strategic; freedom-to-operate is narrow and legal. Landscape analysis typically precedes freedom-to-operate in the R&D workflow.
What are the steps in a patent landscape analysis?
The modern methodology has eight steps: define the strategic question the analysis must answer, curate a multi-dataset corpus scoped to that question, configure the analytical agent's scope and reasoning boundaries, classify the corpus through an ontology rather than a flat taxonomy, run analytical passes covering activity, actors, structure, temporal change, and gaps, validate all findings against source documents, synthesize a decision artifact that leads with the answer, and convert the configured analysis into continuous monitoring.
Should a patent landscape analysis include non-patent data?
Yes. Patent data records what organizations chose to legally protect and publishes on a statutory delay of roughly eighteen months. It cannot capture trade secrets, defensive publications, pre-commercial academic research, regulatory activity, or funding signals. Scientific literature typically surfaces technical developments six to eighteen months before associated patents publish. A corpus including patents, scientific literature, regulatory filings, grant awards, corporate disclosures, and where relevant chemical structure data produces a materially more accurate landscape than patents alone.
Can AI conduct a patent landscape analysis?
AI can perform the analytical work in a patent landscape analysis when it is given a curated corpus and configured for the specific strategic question. Output quality depends primarily on corpus construction and agent configuration rather than on prompting. General-purpose language models querying from training data rather than retrieving from a live record will produce fabricated patent numbers, incorrect dates, and misattributed assignees, so every finding must trace to a verifiable source document.
Why do AI-generated patent landscapes often produce poor results?
The most common cause is retrieval failure rather than reasoning failure. When an AI system is pointed at an undifferentiated index rather than a curated corpus, it retrieves loosely related material and reasons over a diluted context. Scoping the corpus before retrieval reaches the model is what produces dense, high-signal output. Prompt refinement does not compensate for a corpus that does not contain the answer.
Does empty space on a patent map mean commercial opportunity?
No. Patent white space and commercial opportunity space are distinct concepts. An area with few patents may be sparse because the approach was attempted and failed, because competitors protect it through trade secrets, because the technology is not commercially viable, or because the regulatory pathway is closed. Distinguishing genuine opportunity from these alternatives requires scientific literature, regulatory records, and funding data alongside the patent record.
How often should a patent landscape analysis be updated?
Continuously, rather than on a fixed cycle. Global patent filings reached 3.7 million in 2025 and scientific publications passed 2 million articles, so a landscape begins degrading immediately after delivery. Once a corpus is curated and an agent is configured, the same configuration can evaluate new material as it publishes and surface only findings that meet defined escalation criteria, replacing periodic manual rebuilds with a maintained baseline.
Who should conduct a patent landscape analysis?
Corporate R&D directors, IP managers, innovation strategists, and technology scouting teams typically own landscape analysis, often in collaboration with internal IP counsel. The analysis supports research funding decisions, portfolio strategy, and partnership evaluation, so the owner should be close enough to those decisions to define the strategic question the analysis must answer.
What tools are used for patent landscape analysis?
Free resources including Google Patents, The Lens, and PQAI support verification and early scoping. Legacy professional platforms including Derwent Innovation and Orbit Intelligence provide curated patent data and advanced search built for IP prosecution and litigation workflows. Enterprise R&D intelligence platforms such as Cypris combine multi-dataset corpora with agentic execution and continuous monitoring, which is the tooling category aligned with the methodology described in this guide.
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
Comparative findings at a glance
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
6G has entered its standardization phase, and its patent landscape is distinctive because it is a standard-essential-patent race run years before the standard is finished. Unlike freedom-to-operate in a product market, the strategic contest in wireless is over which companies own patents that will be essential to practicing the eventual standard, because those standard-essential patents, licensed on fair, reasonable, and non-discriminatory terms, generate durable revenue and bargaining power. The framework for the next generation is now set: the international body that defines mobile-technology requirements approved its overarching vision for the 2030 generation in late 2023, defining the usage scenarios and objectives that 6G must meet, and the industry body that writes the specifications opened its formal 6G study phase in 2025, with study work running into 2027 and the specifications to follow.¹,² The technology divides into distinct regions of patenting, each a candidate 6G enabler: the AI-native air interface, in which machine learning is built into the radio rather than added on;³ integrated sensing and communication, in which the network senses its surroundings using the same waveform it uses to communicate;⁴,⁵ reconfigurable intelligent surfaces that steer signals in complex environments;⁶,⁷ sub-terahertz spectrum and its hardware;⁸ massive antenna systems; and the service-based, AI-managed core. Because leadership in the eventual standard depends on positions across several of these layers, patent-landscape and SEP analysis must span them together.
The landscape is being shaped by the timing of standardization and by a small number of intensely active players. Filing accelerated sharply as study work opened, because companies file before the standard freezes to ensure their contributions, and their patents, are embedded in it; by the time the specifications are complete, much of the essential IP may already be committed. Across the Cypris corpus of more than 500 million patents and scientific papers, the 6G set, spanning the IMT-2030 framework and the reconfigurable-surface, integrated-sensing, and AI-native layers, holds on the order of 5,521 families and rose steeply from about 62 in 2020 to roughly 1,277 in 2024, with the most active assignees including Qualcomm, Huawei, Samsung, Nokia, ZTE, InterDigital, and Ericsson, and China ahead of the United States and South Korea on geography; these are Cypris-corpus figures, with 2025 and 2026 partial. Because the standard is not yet frozen, essentiality cannot be finally determined, so these counts are best read as positioning and momentum, not as confirmed standard-essential patents. Because applications publish about eighteen months after filing, the most recent filings are under-represented, so the current frontier is more active than published counts suggest.
The strategic question is where to build position, and the ground shifts by layer. The AI-native air interface is the defining architectural change and a fast-growing, contested layer;³ integrated sensing and communication is a distinct capability where some players have moved early and heavily;⁴,⁵ reconfigurable intelligent surfaces and sub-terahertz hardware are earlier, less-crowded layers with room for differentiated positions;⁶,⁷,⁸ and the service-based core and network-AI layers carry their own IP. For companies entering or licensing in this field, the essential questions are which layers a competitor dominates, where positions are still open, and how filing activity is trending ahead of the freeze. Reading the landscape by layer and by owner, and tracking both the patents and the underlying standards and research activity, is what separates a strong position from a weak one.
Where the 6G strategic ground is
AI-native air interface. Building machine learning into the radio itself, rather than as an add-on, is the defining architectural change and a fast-growing, contested layer.³
Integrated sensing and communication. Using the communication waveform to sense the environment is a distinct capability where some players have moved early and heavily.⁴,⁵
Reconfigurable intelligent surfaces. Surfaces that steer signals in complex environments are an earlier, less-crowded physical-layer enabler.⁶,⁷
Sub-terahertz and new spectrum. Hardware and techniques for sub-terahertz and new spectrum are a distinct, high-value layer as the field pushes to higher frequencies.⁸
Service-based core and network AI. The AI-managed, service-based core network that orchestrates 6G carries its own architecture and automation IP.
How AI-powered landscape and SEP analysis helps
Resolving a standards-driven landscape that spans the air interface, sensing, surfaces, spectrum, and core requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by layer across varied terminology, attribution that normalizes equipment-maker, chipset, and research-program filers to canonical entities across jurisdictions, and continuous monitoring that tracks filing momentum ahead of the standard freeze. Because 6G advances appear in standards contributions and scientific literature before they are granted, reading both patents and literature gives the earliest signal of where positions are forming.
Where Cypris fits
Cypris runs patent landscape and standard-essential-patent analysis for standards-driven fields such as 6G across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by layer, AI-native air interface, integrated sensing, reconfigurable surfaces, spectrum, and core, and normalizes equipment-maker, chipset, and research-program filers to canonical entities across jurisdictions, so a team can resolve which layers a competitor dominates and where positions remain open. Semantic search across patents and scientific literature connects filings to the underlying standards contributions and research, which is where 6G positions form first, often ahead of grant. Cypris Q, the platform's agentic layer, lets teams run landscape and SEP analysis conversationally and chain the clustering, attribution, and trend analysis across layers, and Agentic Monitoring tracks a defined layer over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is the 6G patent landscape? The 6G patent landscape is the set of patents positioning companies for the next generation of wireless standards. It spans candidate enablers, the AI-native air interface, integrated sensing and communication, reconfigurable intelligent surfaces, sub-terahertz spectrum, massive antenna systems, and the service-based core. Because 6G is standards-driven, it is largely about standard-essential-patent positioning.
What is a standard-essential patent? A standard-essential patent is a patent that must be used to implement a technical standard, so any compliant product infringes it unless licensed. Such patents are typically licensed on fair, reasonable, and non-discriminatory terms. In wireless, SEP positions are a major source of licensing revenue and bargaining power.
Why are companies filing 6G patents before the standard is finished? Companies file 6G patents before the standard is finished because standardization embeds specific technical contributions into the specification, and filing early helps ensure a company's contributions, and the patents covering them, become essential. By the time the specification freezes, much of the essential IP may already be committed. This creates a race that runs ahead of the standard.
What layers does the 6G landscape cover? The landscape covers the AI-native air interface, integrated sensing and communication, reconfigurable intelligent surfaces, sub-terahertz and new spectrum, massive antenna systems, and the service-based, AI-managed core. Each is a distinct region of patenting with different leaders. Landscape and SEP analysis must span them together.
Where is the strategic ground in 6G? The strategic ground includes the AI-native air interface, integrated sensing and communication, reconfigurable intelligent surfaces, sub-terahertz hardware, and the service-based core and network AI. The air interface and sensing layers are especially active, while surfaces and sub-terahertz are earlier and less crowded. Position depends on which layers a competitor dominates and where openings remain.
Why can't 6G essential patents be finally determined yet? 6G essential patents cannot be finally determined yet because the standard is not frozen, so which patents are truly essential to the final specification is not settled. The landscape therefore reflects positioning and momentum rather than confirmed essentiality. That makes tracking filing trends, not just counts, important.
What software helps analyze the 6G patent landscape? Software for the 6G landscape should cluster activity by layer, resolve equipment-maker, chipset, and research-program filers to canonical owners across jurisdictions, search patents and standards-related literature semantically, and monitor filing momentum continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use 6G patent landscape analysis? 6G patent landscape analysis is used by R&D, IP, licensing, and strategy teams at network-equipment makers, chipset companies, device makers, and operators, as well as investors and standards participants. Because SEP positions shape licensing and leverage, structured analysis is essential. Cypris serves hundreds of enterprise customers across research-intensive and regulated industries.
Endnotes
- International Telecommunication Union, Radiocommunication Sector. Recommendation ITU-R M.2160: Framework and overall objectives of the future development of IMT for 2030 and beyond (approved November 2023). https://www.itu.int/rec/R-REC-M.2160
- 3rd Generation Partnership Project (3GPP). Releases (Release 20 6G study phase, 2025–2027; Release 21 specifications). https://www.3gpp.org/specifications-technologies/releases
- Ugwu, C., et al. (2025). A comprehensive review of AI-native 6G. Frontiers in Communications and Networks, 6. https://doi.org/10.3389/frcmn.2025.1655410
- Eldar, Y. C., Shlezinger, N., Buzzi, S., Chepuri, S. P., et al. (2023). Integrated sensing and communications with reconfigurable intelligent surfaces: from signal modeling to processing. IEEE Signal Processing Magazine, 40(6). https://doi.org/10.1109/msp.2023.3279986
- Swindlehurst, A. L., et al. (2023). Integrated sensing and communication with reconfigurable intelligent surfaces: opportunities, applications, and future directions. IEEE Wireless Communications, 30(1). https://doi.org/10.1109/mwc.002.2200206
- Elkashlan, M., Wang, C., Swindlehurst, A. L., et al. (2021). Reconfigurable intelligent surfaces for 6G systems: principles, applications, and research directions. IEEE Communications Magazine, 59(6). https://doi.org/10.1109/mcom.001.2001076
- Pitchappa, P., Wang, N., & Yang, N. (2022). Terahertz reconfigurable intelligent surfaces for 6G communication links. Micromachines, 13(2), 285. https://doi.org/10.3390/mi13020285
- Rasilainen, K., et al. (2023). Hardware aspects of sub-terahertz antennas and reconfigurable intelligent surfaces for 6G communications. IEEE Journal on Selected Areas in Communications, 41(8). https://doi.org/10.1109/jsac.2023.3288250

1. Executive Summary & Objective
Most AI benchmark studies compare models. This one does not. It compares the same model, in the same session, answering the same prompt twice. The only variable that changed between the two runs was whether Microsoft Copilot had access to the Cypris MCP server.
That design isolates a question R&D and IP leaders increasingly need answered: when an AI assistant produces a technology landscape, how much of the answer comes from the model and how much comes from what the model can reach?
A single prompt was submitted covering non-fluorinated alternatives to PTFE and PVDF across two application domains, chemically resistant coatings and lithium-ion battery binders. The prompt asked for leading chemistry classes, most active assignees and research groups, quantified filing and publication volume by class, and identification of which approaches had crossed from lab-scale publication into commercial patenting. It was submitted first to Copilot operating against the public web, then re-submitted in the same session with the Cypris MCP server connected.
The unaugmented run produced a competent directional survey. It identified the right chemistry families, named recognizable commercial actors, and correctly observed that no current PFAS-free coating platform matches PTFE across the full performance envelope. What it could not do was quantify anything. It reported counts of items it happened to find, four silicone coating publications, four polyacrylate binder families, and stated explicitly that the public sources available to it did not provide chemistry-class totals.
The MCP-grounded run returned scoped filing counts for nine chemistry classes and publication counts for four, spanning roughly 1,640 filings in silicone and siloxane coatings down to 112 in standalone SBR binders. It named individual research groups at NTNU, POLYMAT, Politecnico di Torino, and Munster. It surfaced patent documents dated July 9, 2026, roughly three months more recent than the latest clearly dated item the public-web run reached.
The two answers were then compared by the same assistant against a fixed rubric covering entity specificity, quantitative grounding, source retrievability, and recency. Its conclusion, reached without prompting toward a preferred outcome: the grounded response should serve as the primary work product, the public-web response as an open-web cross-check.
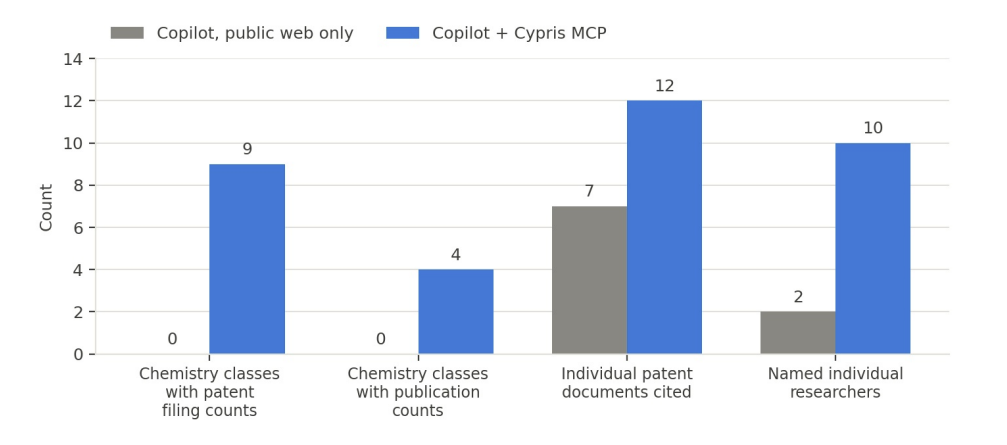
2. Methodology
2.1 The Core Variable
In most comparative AI studies the confound is obvious. Different platforms run different models, apply different system prompts, and expose different tool sets, so any observed performance gap is a composite of many differences at once.
This test removes those confounds. Microsoft Copilot was the assistant in both runs. The session was continuous. The prompt was submitted verbatim, twice, with no clarification, refinement, or follow-up. The single manipulated variable was the presence of the Cypris MCP server in the tool loop.
Model Context Protocol is the open standard that lets an AI assistant call an external data source as a tool rather than answering from training memory or from whatever the open web returns. Connecting Cypris through MCP gave Copilot programmatic access to a structured corpus of patents and peer-reviewed literature, queried by meaning and organized through an R&D ontology, rather than a list of crawlable web pages.
Whatever difference appears between run one and run two is therefore attributable to grounding, not to model capability.
2.2 The Prompt
Identify the leading non-fluorinated alternatives to PTFE and PVDF for chemically resistant coatings and battery binders, based on patent filings and peer-reviewed literature from 2022 to present. Name the most active assignees and research groups, and quantify filing and publication volume by chemistry class. Flag which approaches have moved from lab-scale publication into commercial patenting.
The prompt was constructed to require three things a model cannot produce from parametric memory: named assignees with associated volumes, a recency window extending past any training cutoff, and an explicit separation between academic publication activity and commercial patenting activity.
2.3 Why This Topic
PFAS replacement is a live, high-stakes chemistry problem with genuine regulatory pressure behind it, an active and fragmented patent landscape, and two application domains at meaningfully different stages of commercial maturity. It is also a domain where a plausible-sounding but unquantified answer is easy to produce and difficult for a non-specialist to falsify, which makes it a fair test of whether grounding produces something a practitioner could actually act on.
2.4 Evaluation
Both outputs were assessed against four dimensions: specific entities named, including companies, assignees, institutions, and individual patents or papers; quantitative claims, including filing counts, publication volume, and trend figures; whether sources were cited and independently retrievable; and the recency of the most recent item referenced.
3. Findings
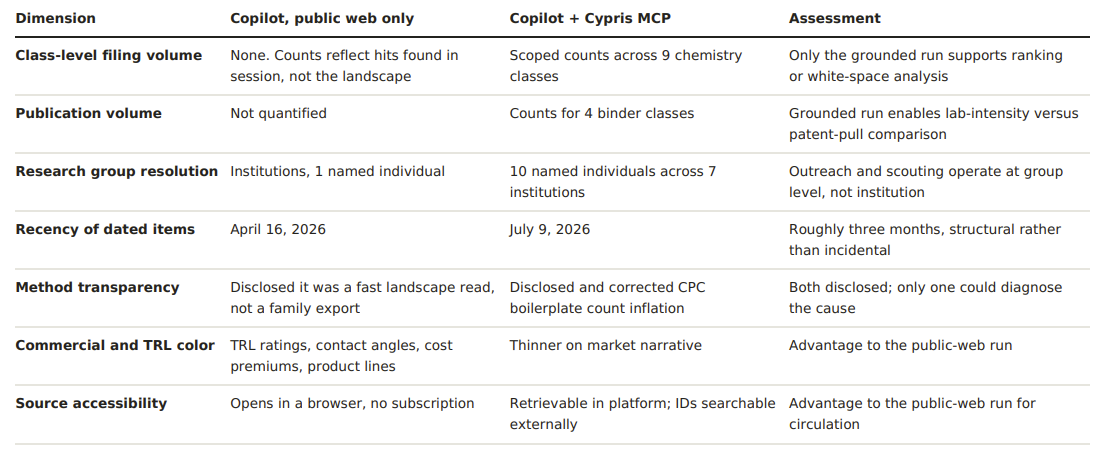
3.1 The Quantification Gap
The starkest difference is not what each run knew. It is what each run could count.
The public-web run was explicit about its own limitation, describing its output as a fast landscape-style read rather than a patent-family export, and stating that the sources available to it did not provide chemistry-class totals. The counts it did report were counts of hits found in that session: four silicone and polysiloxane coating publications, four polyacrylate binder families. These are honest numbers, but they measure the search, not the landscape.
The grounded run returned scoped counts across nine chemistry classes. For battery binders: approximately 339 filings for polyimide and polyamic acid, 323 for cellulose and CMC, 319 for polysaccharides, 255 for polyacrylic acid and polyacrylate, 253 for lignin, and 112 for standalone SBR. For coatings: approximately 1,640 for silicone, siloxane and PDMS, 1,123 for epoxy, and 787 for polyurethane. Publication counts were returned for four binder classes, ranging from 163 papers for polysaccharides down to 57 for lignin.
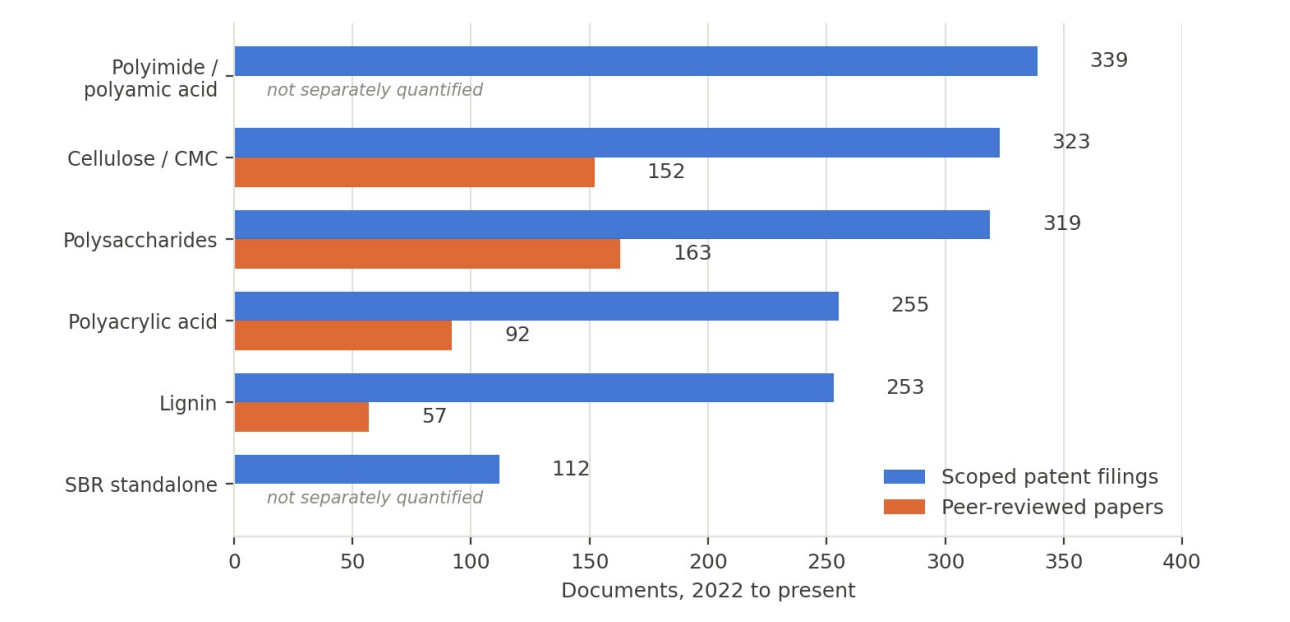
The analytical payload here is the ratio, not either number alone. Polysaccharides show 319 filings against 163 papers, a publication-heavy profile consistent with an academically active class that has not yet converted into commercial portfolios. Polyimide and polyamic acid lead the filing count while returning no comparable publication concentration, the signature of a class that has already moved into industrial development. That distinction, lab-heavy versus commercially converting, is precisely what an R&D lead needs in order to decide whether to prototype, partner, license, or simply monitor. It cannot be inferred from a list of example patents.
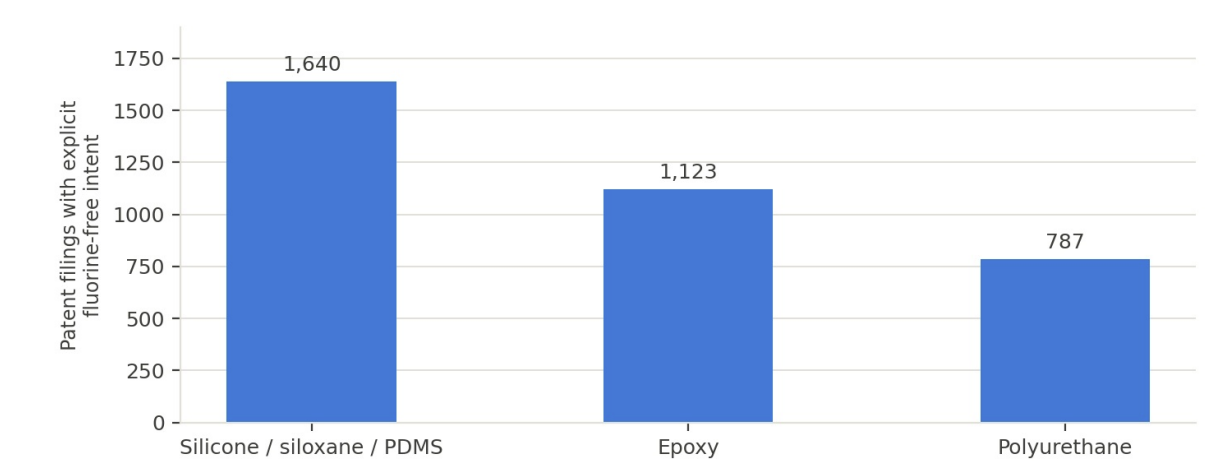
3.2 Methodological Self-Correction
One finding is worth isolating because it runs against the usual expectation of what a grounded system does.
The grounded run reported that raw CPC-classification patent counts for battery binders were inflated by boilerplate. Patent specifications routinely list binder options as a generic enumeration, PVDF, CMC, SBR, PAA, and so on, in filings where the binder is not the invention. A CPC-code query captures all of those documents and returns a number that looks authoritative and is substantially wrong. The run therefore re-scoped its counts to title and abstract text carrying explicit fluorine-free, aqueous, or non-fluorinated intent, and reported the tighter numbers.
It also flagged that some assignee aggregations in the coatings landscape were contaminated by fluoropolymer incumbents whose patents mention fluorine-free components without being fluorine-free replacements.
This is the difference between a system that retrieves and a system that retrieves and audits. A tool with no structured access to the corpus has no mechanism to detect this class of error, because it never sees the population that produces it. The unaugmented run could not have identified boilerplate contamination for the same reason it could not produce counts: it had no denominator.
3.3 Research Group Resolution
Both runs named institutions. Only the grounded run named people.
The public-web run surfaced POSTECH, KERI, KIST, Sungkyunkwan University, and Delft, with one named individual researcher. The grounded run identified Jacob Lamb, Silje Bryntesen and Odne Burheim at NTNU; David Mecerreyes and Claudio Gerbaldi at POLYMAT and Politecnico di Torino; Martin Winter and Markus Borner at Munster and Helmholtz-Institut; and on the coatings side Emmanuel Giannelis at Cornell, Zhiwei He at Hangzhou Dianzi University, Joseph Furgal at Bowling Green State University, and Guojun Liu and Muhammad Rabnawaz at Queen's University.
The operational difference is that an institution is a fact and a named group is a contact. Technology scouting, licensing outreach, advisory recruitment, and competitive monitoring all run at the level of the individual research group. A landscape that stops at the institution name has ended one resolution step short of the action it is supposed to inform.
3.4 Recency
The most recent clearly dated item in the public-web run was a patent publication from April 16, 2026. The grounded run referenced patent documents dated July 9, 2026.
The three-month gap is not a rounding error in a domain moving this quickly, and it is structural rather than incidental. Public web coverage of a patent publication depends on someone writing about it and that page being crawlable. Structured corpus access does not.
3.5 Where the Unaugmented Run Was Genuinely Better
An honest benchmark reports the cases that cut the other way.
The public-web run produced better commercial narrative. It surfaced technology readiness level assessments, water contact angle benchmarks, and cost premium characterizations for each coating platform. It identified SEB as a cookware-focused filer of non-fluorinated silicone and sol-gel architectures, Clariant's PTFE-free wax additive product families, and SilcoTek's silicon CVD coatings as deployed replacements in tubing, chromatography columns, and pharmaceutical flow paths. It caught the KERI siloxane cathode binder work and its stated technology-transfer intent, a commercially relevant signal that appears in press coverage before it appears in a patent record.
It was also easier to share. Its sources open in a browser without a subscription, which matters when a landscape needs to circulate to stakeholders who will not log into an analytics platform.
These are real strengths, and they describe the correct role for open-web AI search in an R&D workflow: orientation, market color, and commercial context. They do not describe a substitute for a countable landscape.
4. The Structural Reading
4.1 Coverage Is Not the Only Failure Mode
The familiar critique of general-purpose AI for patent work is that it misses documents. That is true, and it understates the problem.
A model with no structured corpus access cannot produce a denominator. It can tell you that polyacrylic acid binders are important, and it will be right, because that fact is well represented in the crawlable literature. It cannot tell you that polyimide and polyamic acid filings exceed polyacrylic acid filings, because ranking requires counting the population, not sampling it. Every strategic question that depends on relative volume, which class is consolidating, which is still academic, where the white space sits, is therefore unreachable regardless of how good the underlying model is.
This is why the finding survives model upgrades. The gap documented here is not a reasoning gap.
4.2 The Confidence Asymmetry
Both outputs were well formatted, professionally structured, and confident in tone. A reader without domain expertise would find both credible.
The unaugmented run deserves credit for disclosing its own limitation clearly, which is better behavior than most general-purpose outputs exhibit. But the disclosure sat inside an otherwise authoritative document, and in practice caveats placed alongside detailed analysis tend to be read past. The risk in AI-assisted landscaping is rarely that the output is obviously wrong. It is that the output is well-shaped and incomplete in a way that discourages the follow-up the situation required.
4.3 Grounding Travels to the Assistant
The most operationally significant point in this study is where the intelligence sat.
The analyst did not switch platforms. Copilot remained the interface, the session continued uninterrupted, and the output arrived in the same place as the rest of that person's work. What changed was the data the assistant could reach. MCP is what makes that possible: a shared open standard for connecting an AI assistant to an external corpus, so grounded R&D intelligence becomes a capability inside existing tools rather than a separate destination.
For enterprises standardizing on Copilot, this is the practical form the question takes. Not whether to replace the assistant, but whether the assistant is connected to anything that can count.
5. Strategic Takeaways
General-purpose AI assistants running against the public web are effective for orientation. They identify the correct chemistry families, surface recognizable commercial actors, and assemble market narrative and readiness color quickly. Used for exactly that, they save real time.
They cannot produce class-level filing volumes, cannot separate academic activity from commercial conversion, cannot resolve landscapes to the named research group, and cannot detect the classification artifacts that corrupt naive patent counts. These limits follow from data access rather than model capability, and they persist as models improve.
Connecting the same assistant to a structured corpus of patents and scientific literature through MCP changes the output category. The deliverable moves from a survey to a landscape: counted, ranked, attributable to retrievable documents, and resolved to the level at which R&D decisions are actually made.
For teams making prototype, partner, license, or monitor decisions on a technology class, the relevant question is not which AI assistant is being used. It is whether that assistant is grounded in a corpus that can answer the question being asked.
Rare-earth-free permanent magnets have become a strategic priority, and their patent landscape is being staked out under unusual geopolitical pressure. Permanent magnets convert electricity into motion and back, and the strongest ones, based on neodymium-iron-boron, are essential to electric-vehicle motors, wind turbines, consumer electronics, medical imaging, and defense systems. Their supply chain, however, is highly concentrated: China accounts for roughly 60 percent of global rare-earth mine production and close to 90 percent of refining and separation capacity, and the European Union sources an estimated 98 percent of its rare-earth magnets from China<sup>7</sup>. A separate analysis puts China's share of production at close to two-thirds, corroborating the scale of concentration even where exact figures diverge by methodology<sup>8</sup>. Recent export controls on rare-earth elements have turned that concentration into a security and continuity risk. This has driven intense R&D toward magnets that reduce or eliminate rare earths, and the intellectual property divides across several regions, each a distinct area of patenting: the magnetic-material composition itself, including metastable phases such as iron nitride that are difficult to form and stabilize; the powder and particle synthesis that produces the material; the anisotropy and alignment that give a magnet its directional strength; the consolidation and bonding into a finished magnet, whether sintered or polymer-bonded; and the application-level integration into motors and generators. Because a competitive magnet depends on several of these layers, freedom-to-operate and white space analysis must span composition and process together.
The landscape is being shaped by policy and by the arrival of first commercial production. Iron-nitride magnets were first prototyped by University of Minnesota researchers under the Department of Energy's ARPA-E REACT program before spinning out into a private company<sup>9</sup>, and government and defense funding has since backed the scale-up of alternative-magnet manufacturing: a planned facility in Sartell, Minnesota is slated to produce up to 1,500 tons of permanent magnets annually starting in 2027, with automakers partnering to bring the magnets into electric-drive motors<sup>10</sup>. The competing chemistries sit at different stages: iron nitride (α″-Fe16N2) has advanced furthest toward commercialization, offering saturation magnetization comparable to rare-earth magnets, though the phase is metastable above about 539 K and difficult to hold at scale<sup>1,2</sup>. Samarium-iron-nitride bonded magnets and tetrataenite are active research directions, and manganese-based systems — including MnBi-Cu, which has demonstrated a maximum energy product of 17.7 MGOe at 300 K with a favorable positive temperature coefficient of coercivity<sup>4</sup>, and MnAl, where twin-defect engineering and grain-size control are the leading strategy for improving performance<sup>5</sup> — and improved ferrite magnets address specific performance and cost niches. The intellectual-property picture reflects the field's academic and national-laboratory roots, with foundational composition and phase-stabilization estates concentrated among a small number of universities, national labs, and their spinouts, alongside a growing set of applied filings. Because applications publish about eighteen months after filing, the most recent composition and process filings are under-represented, so the current frontier is more active than granted-patent counts suggest.
The strategic question is which chemistry and layer to back, and the white space sits where the physics and manufacturing are hardest. Forming and stabilizing the metastable phases that give some rare-earth-free magnets their strength is the central materials problem — work on ultralow-temperature-coefficient-of-coercivity iron-nitride foils illustrates how much of the remaining difficulty is in holding performance stable across operating temperature, not just achieving it once<sup>3</sup> — and scalable, low-cost synthesis and alignment are the manufacturing barriers, so composition and process innovation carry high, defensible value. Alternative chemistries beyond iron nitride, including tetrataenite and manganese-based systems, are earlier and less crowded, and coercivity and thermal-stability improvements that close the gap with rare-earth magnets at high temperature are a persistent, high-value target. Recycling and recovery of rare-earth magnets is an adjacent bridge technology. Reading the landscape by chemistry, layer, and owner, and tracking both the patents and the underlying magnetics research, is what separates a crowded region from an open one<sup>6</sup>.
Where the rare-earth-free magnet white space is
Metastable-phase composition and stabilization. Forming and stabilizing phases such as iron nitride that deliver high magnetization without rare earths is the central materials problem and a high-value layer<sup>1,2,3</sup>.
Scalable synthesis and alignment. Low-cost powder synthesis and the alignment that gives anisotropic magnets their strength are the manufacturing barriers where deployment is decided.
Alternative chemistries. Tetrataenite, manganese-based systems such as MnBi-Cu and MnAl<sup>4,5</sup>, and improved ferrites are earlier, less-crowded chemistries addressing specific niches.
High-temperature performance. Coercivity and thermal-stability improvements that close the gap with rare-earth magnets at motor operating temperatures are a persistent, high-value target<sup>3</sup>.
Rare-earth magnet recycling. Recovery and reuse of rare earths from end-of-life magnets is an adjacent bridge layer that eases supply pressure.
How AI-powered landscape and white space analysis helps
Resolving a materials landscape that spans several competing chemistries and process layers, under acute supply pressure, requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by chemistry, composition, and process across varied terminology, attribution that normalizes university, national-lab, and commercial filers to canonical entities, and continuous monitoring that keeps pace with a policy-driven surge. Because magnetics advances appear in scientific literature before they are patented, reading both patents and literature gives the earliest signal of where viable alternatives are emerging.
The competitive landscape by the numbers
Cypris's corpus puts the rare-earth-free / iron-nitride / tetrataenite / manganese-based magnet patent family set at roughly 916 families (Cypris corpus, indicative; 2025–26 partial). Filing has stepped up markedly, from roughly 13–20 new families per year before 2015 to 46–72 per year in 2022–2026, with 2025 and 2026 counts still partial (Cypris corpus, indicative; 2025–26 partial). The assignee ranking is led by the University of Minnesota (100 families, plus 36 more under a second name variant of the same institution), followed by Maxell (64), TDK (45), Dowa (30), Toyota (25), Toda Kogyo (22), Daido Steel (21), and UT-Battelle/Oak Ridge National Laboratory (20) (Cypris corpus, indicative; 2025–26 partial). Geographically, China (191 families), the United States (155), and Japan (96) dominate, with Europe comparatively thin — Germany, the largest European filer in this set, holds only 13 families (Cypris corpus, indicative; 2025–26 partial). The mix of a leading US university/national-lab estate alongside Japanese materials and automotive majors reflects the field's academic origins described above.
Where Cypris fits
Cypris runs patent landscape and white space analysis for strategically important materials fields such as rare-earth-free magnets across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by chemistry, iron nitride, samarium-iron-nitride, tetrataenite, and manganese-based, and by layer, composition, synthesis, alignment, and consolidation, and normalizes university, national-lab, and commercial filers to canonical entities, so a team can resolve which chemistries and layers are crowded and which remain open as white space. Semantic search across patents and scientific literature connects filings to the underlying magnetics and materials research, which is where these advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined chemistry over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
Why are rare-earth-free magnets a strategic priority? Rare-earth-free magnets are a strategic priority because the strongest permanent magnets depend on rare-earth elements whose mine production and refining are concentrated in China at roughly 60 and 90 percent respectively, and whose recent export controls have made that concentration a security and supply risk<sup>7,8</sup>. Magnets are essential to electric-vehicle motors, wind turbines, electronics, and defense. Alternatives reduce that dependence.
What chemistries does the landscape cover? The landscape covers iron nitride, which has advanced furthest toward commercialization<sup>1,2</sup>, samarium-iron-nitride, tetrataenite, manganese-based systems such as MnBi-Cu and MnAl<sup>4,5</sup>, and improved ferrites. Each sits at a different stage and addresses different performance and cost niches. The choice of chemistry shapes both the technical and the freedom-to-operate picture.
What layers does the rare-earth-free magnet landscape divide into? The landscape divides into magnetic-material composition and phase stabilization, powder and particle synthesis, anisotropy and alignment, consolidation and bonding, and application-level motor integration. Each is a distinct region of patenting. Freedom-to-operate and white space analysis must span composition and process together.
Where is the white space in rare-earth-free magnets? The white space includes metastable-phase composition and stabilization, scalable synthesis and alignment, alternative chemistries such as tetrataenite and manganese-based systems, high-temperature performance improvements, and rare-earth magnet recycling. Iron nitride is comparatively advanced. The most open, high-value opportunities are in composition, process, and the newer chemistries.
Why is phase stabilization so important? Phase stabilization is important because some rare-earth-free magnets rely on metastable phases, such as iron nitride, that deliver high magnetization but are difficult to form and keep stable at useful scales and above roughly 539 K<sup>1,3</sup>. Solving this is the central materials problem. The composition and process methods that achieve it are foundational and defensible.
Who first developed iron-nitride magnets, and who is filing patents now? Iron-nitride magnets were first prototyped at the University of Minnesota under ARPA-E's REACT program before spinning out commercially<sup>9</sup>, and the University of Minnesota remains the leading patent assignee in Cypris's corpus, ahead of Japanese materials and automotive filers such as Maxell, TDK, and Toyota (Cypris corpus, indicative; 2025–26 partial). A planned Minnesota facility is expected to reach commercial-scale production in 2027<sup>10</sup>.
Why does rare-earth-free magnet analysis need scientific literature? Rare-earth-free magnet analysis needs scientific literature because composition, synthesis, and alignment advances appear in materials research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the rare-earth-free magnet patent landscape? Software for the rare-earth-free magnet landscape should cluster activity by chemistry and process layer, resolve university, national-lab, and commercial filers to canonical owners, search patents and scientific literature semantically, and monitor a policy-driven field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use rare-earth-free magnet patent landscape analysis? Rare-earth-free magnet patent landscape analysis is used by R&D, innovation, IP, and strategy teams at materials, automotive, electronics, and energy companies, national laboratories, and defense-facing organizations, as well as investors. Because the field is strategically important and moving fast, structured analysis is essential. Cypris serves hundreds of enterprise customers across advanced materials, energy, and other research-intensive industries.
Endnotes
- Saito T, Yamamoto H, Nishio-Hamane D. Production of rare-earth-free iron nitride magnets (α″-Fe16N2). Metals. 2024. DOI: 10.3390/met14060734.
- Park S, et al. Recent progress in research and development of rare-earth-free iron nitride permanent magnet. Ceramist. 2024. DOI: 10.31613/ceramist.2024.27.2.05.
- Ma B, et al. (University of Minnesota). Synthesis of α″-Fe16N2 foils with an ultralow temperature coefficient of coercivity. Acta Materialia. 2019. DOI: 10.1016/j.actamat.2019.11.052.
- Lee T, et al. Suppressing antiferromagnetic coupling in rare-earth-free ferromagnetic MnBi-Cu permanent magnet. Journal of Applied Physics. 2021. DOI: 10.1063/5.0040464.
- Skokov K, Gutfleisch O, et al. Roadmap towards optimal magnetic properties in rare-earth-free L1₀-MnAl permanent magnets. Research Square preprint. 2022. DOI: 10.21203/rs.3.rs-1850627/v1. (Preprint; cite the peer-reviewed version once published.)
- Mohapatra J, Liu JP. Rare-earth-free permanent magnets: the past and future. Handbook of Magnetic Materials. 2018. DOI: 10.1016/bs.hmm.2018.08.001.
- European Parliament Research Service (EPRS). China's rare-earth export restrictions. 2025. europarl.europa.eu/RegData/etudes/ATAG/2025/779220.
- European Central Bank. Sintra Forum paper on rare-earth and critical-minerals concentration. ecb.europa.eu.
- U.S. Federal Register. Section 232 investigation report on neodymium-iron-boron (NdFeB) magnets. February 14, 2023. federalregister.gov/documents/2023/02/14/2023-03078.
- Minnesota Department of Employment and Economic Development (DEED). Sartell, MN rare-earth-free magnet facility disclosure.
- Cypris platform corpus analysis, rare-earth-free / iron-nitride / tetrataenite / manganese-based magnet patent families. Indicative figures; 2025–2026 partial.

1. Executive Summary & Objective
This benchmark study evaluates the performance of the Anthropic Opus 5 artificial intelligence model across two distinct deployment architectures: a standard conversational large language model (LLM) interface (Claude) and a specialized deep-research AI agent platform (Cypris Q).1 2 3
The primary objective of this evaluation is to test deep technical intelligence—specifically an AI system's ability to synthesize bankable, unit-operation-level chemical engineering flowsheets when confronted with complex industrial challenges containing deliberate operational "traps."1 Conventional LLMs frequently fail these challenges by providing textbook-accurate but operationally destructive or economically unviable guidance.1 Conversely, deep-search platforms are engineered to surface exact kinetic rate limits, chemical compound properties, active patent parameters, and commercial failure modes to successfully bypass these traps.1 2 6
The Core Architectural Variable
The underlying core LLM weights (Opus 5) were held constant across all test runs. The performance variance documented in this report is solely attributable to the architectural harness surrounding the model:1 2 3 6 7
- Standard Conversational LLM (Claude): Relies on fixed parametric memory and a single-pass conversational prompt-response loop.3 7
- Deep-Research AI Agent (Cypris Q): Integrates Opus 5 into an agentic retrieval, verification, and reasoning pipeline.1 2 6 The Cypris intelligence layer couples the base LLM with multi-modal domain infrastructure—deeply indexing global patent families, curated chemical compound datasets, peer-reviewed journals, scientific preprints, and advanced technical ontologies.2 6
Deployment Architecture Comparison
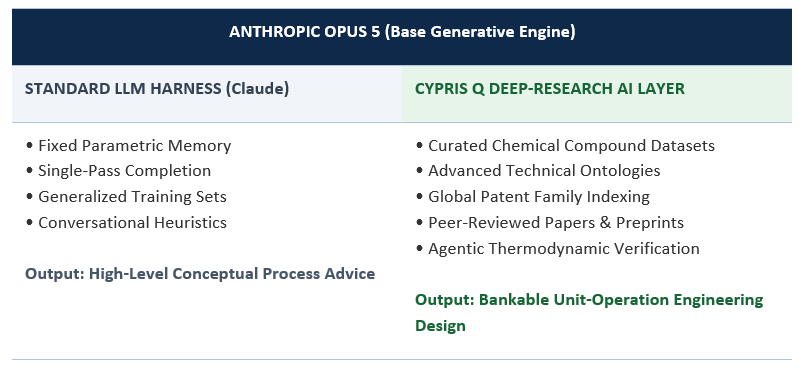
Methodological Integrity & Independent Evaluation
To maintain strict objectivity and scientific rigor throughout this study:
- Independent AI Evaluation: All generated outputs were evaluated by an independent Gemini model adhering strictly to a standardized, four-dimensional scoring rubric.1
- Zero Data Manipulation: Neither model's output was edited, cherry-picked, or prompt-tuned after execution.2 3 6 7
- Standardized Prompts: Identical, unmodified prompts were submitted to both systems under identical technical specifications.1 2 3 6 7
2. Test Scenarios & Benchmark Rubric
The benchmark consists of two high-stakes industrial chemistry challenges containing deliberate "hidden traps" where standard textbook knowledge yields catastrophic real-world plant failures.1
Test Scenario 1: Hydrometallurgy & Lithium-Ion Battery Recycling
- The Prompt: How to selectively remove trace iron (Fe3+/Fe2+) and aluminum (Al3+) impurities down to <5 ppm from concentrated nickel-cobalt-lithium sulfate leach liquor (derived from EV battery black mass) prior to solvent extraction, avoiding value-metal co-precipitation and ferric gelation.1
- Embedded Traps:
- The 'pH Shock' Trap: Recommending direct baseaddition (NaOH or lime) to pH 4.0–5.0, causing local over-alkalinization,un-filterable ferrihydrite gelation, and 10–20% nickel/cobalt entrainment.1
- The Solvent Extraction Poisoning Trap: Routing un-oxidized Fe2+ orferric Fe3+ directly into organophosphorus extractants (e.g., D2EHPA), whereferric iron binds irreversibly, permanently poisoning the organic phase.1
Test Scenario 2: Semiconductor Materials & Specialty Gases
- The Prompt: How to purify hexafluorobutadiene (C4F6) to electronic grade (>99.999% purity, moisture<1 ppb) by removing trace hydrofluorocarbons (HFCs), moisture, peroxides without triggering catalytic polymerization or yield loss.1
- Embedded Traps:
- The Thermal & Acidity Runaway Trap: Recommending standardmolecular sieves (3A/4A/13X) or activated alumina for drying.1xothermic adsorption onto acidic surface sites supplies the activation energy for nucleophilic rearrangement to hexafluoro-2-butyne, driving column temperatures above 400 °C and pressures above 60 psig within seconds.6
- The Sub-ppb Moisture Spec Trap: Accepting an impossiblespecification (<1 ppb) uncritically, despite it sitting below physicaldesiccant capabilities and commercial Cavity Ring-Down Spectroscopy (CRDS)detection limits.6
Evaluation Scoring Rubric
Outputs were scored from 1.0 to 10.0 across four core dimensions:1
- Thermodynamic & Kinetic Rigor: Identification of true physical failure mechanisms, rate-limiting steps, phase behavior, and speciation constraints.1
- Parameter Specificity: Provision of explicit unit-operation specs (pH bands, temperatures, space velocities, exact chemical dosages, catalyst/resin trade names).1
- Art, IP & Data Grounding: Grounding flowsheets in curated compound datasets, active patent families, and peer-reviewed literature.1
- Economic & Yield Realism: Accurate prediction oftarget value-metal recovery (Ni, Co, Li), monomer gas yield losses, reagentcosts, and secondary contamination side-effects.1
3. Comparative Evaluation & Performance Summary
Benchmark Scorecard Summary
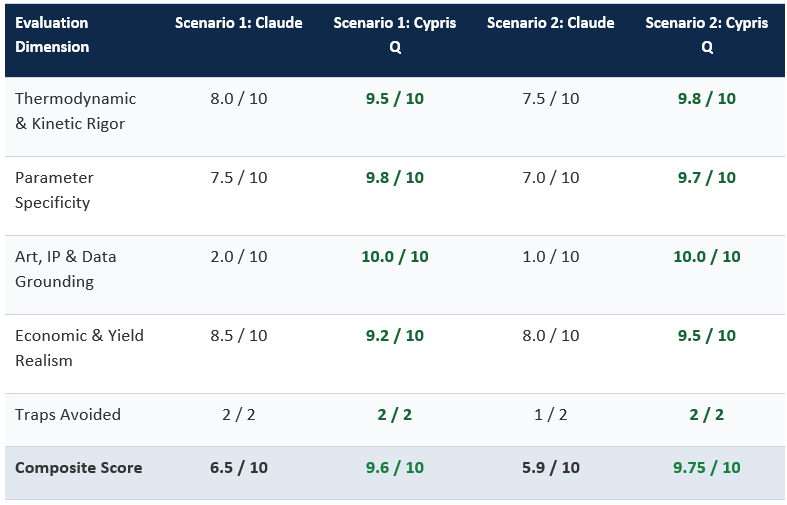
4. Synthesis of Test Scenario 1: Hydrometallurgy & Battery Recycling
Trap Navigation Analysis
Both harnesses successfully avoided the primary pH shock trap.2 3 Claude bypassed single-stage hydroxide neutralization by recommending controlled goethite (α-FeOOH) or hematite precipitation, providing sound anti-gelation operational heuristics: reverse neutralization (metering liquor into a hot, agitated seed bed), subsurface dilute base injection, and 10–30 g/L seed recycling.3
Cypris Q evaluated the underlying physical chemistry driving gelation.2 It detailed ferrihydrite hydrolysate scavenging mechanismsand phase-transformation kinetics (air-sparged oxidation progressing through green rust → lepidocrocite → goethite).2
Regarding solvent extraction poisoning, Claude recommended managing accumulated Fe3+ on D2EHPA using a 6 M HCl or oxalic acid regeneration slipstream.3 Cypris Q surfaced advanced chemical options: adding aliphatic alcohols or 4-tert-butylphenol modifiers to lower extraction binding energy—enabling stripping with 4.5 M H2SO4—or pre-loading Cyanex 272 with 8.5g/L Ni to extract Fe/Co while cutting sodium contamination from 4 g/L to 0.05g/L.2
Flowsheet Unit Operation Comparison (Scenario 1)
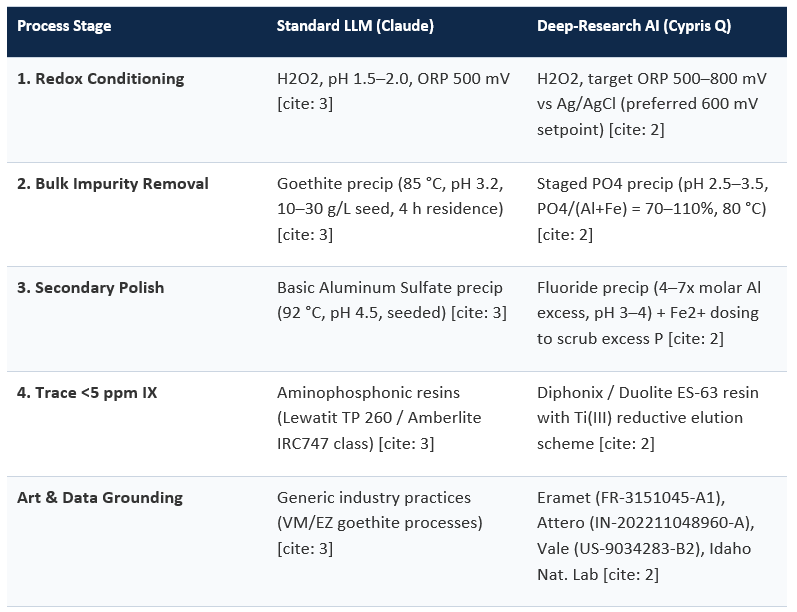
Key Differentiators in Scenario 1
Coupled Fluoride-Aluminum Chemistry: Cypris Q identified a critical chemical coupling missed by standard models: fluoride (F- from LiPF6 electrolyte decomposition) forms stable soluble complexes with Al3+, suppressing aluminum precipitation.2 3 Cypris Q detailed Eramet’s patented solution: dosing a 4–7x molar fluoride excess to force AlF3-type precipitation, combined with soluble iron sulfate dosing (Fe/P ≥ 100%) to scavenge residual phosphate anions that would otherwise contaminate downstream lithium recovery.2
Multi-Source Art Grounding: Cypris Q anchored its flowsheet in assigned IP, compound property tables, and experimental literature, drawing from Eramet, Attero, Vale, IdahoNational Laboratory, and Aalto University research.2 Claude cited zero specific patents or datasets.3
5. Synthesis of Test Scenario 2: Semiconductor Materials & Specialty Gases
Trap Navigation Analysis
In Scenario 2, the operational divergence between harnesses became pronounced.6 7 Claude partially avoided the thermal runaway trap by warning against activated alumina and 13X molecular sieves due to Lewis acidity.7 However, Claude recommended standard 3A molecular sieves for deep drying.7 In commercial practice, standard 3A sieves with high framework alumina still exhibit Brønsted acid sites that trigger diene rearrangement to hexafluoro-2-butyne and HF liberation.6
Cypris Q fully resolved thetrap by defining the precise structural surface parameters required:maintaining the zeolite SiO2/Al2O3 molar ratio strictly between 4.0 and 8.0 (preferably 5.0–7.0).6 It cited empirical data showing that ratios<4.0 degrade under HF exposure, while ratios >8.0 cause water adsorption capacity to collapse.6
Flowsheet Unit Operation Comparison (Scenario 2)
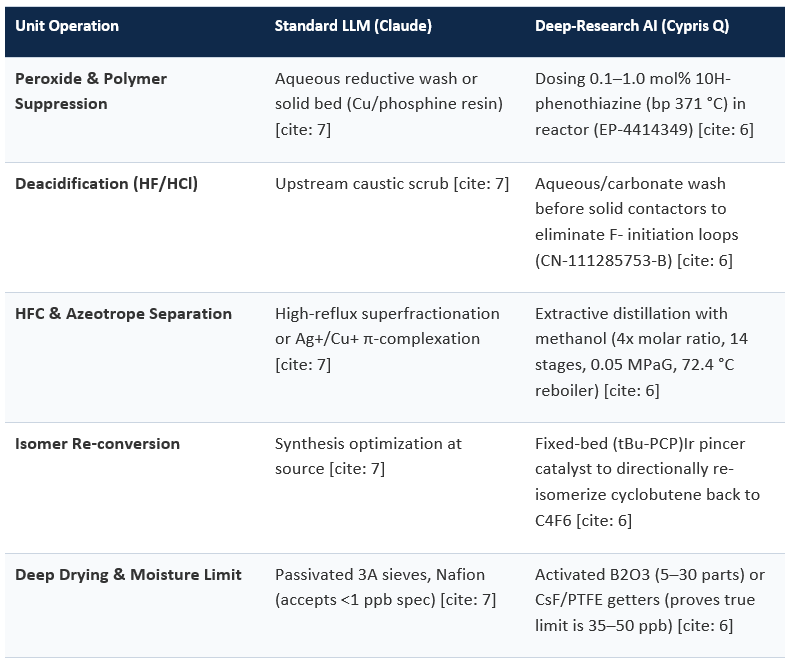
Key Differentiators in Scenario 2
- ChallengingUnviable Specifications: Claude accepted the prompt's <1 ppb moisture target uncritically.7 Cypris Q challenged the specification using empirical compound datasets and patent art (Zeon, WO-2007063938-A1), proving that the true state-of-the-art for C4F6 moisture removal is 35–50 ppb (achieved via activated boron oxide, B2O3, or metal fluoride getters like CsF/PTFE).6 Furthermore, Cypris Q highlighted that <1 ppb sits below the 5ppb detection limit of commercial Cavity Ring-Down Spectroscopy (CRDS Tiger Optics)instruments, framing the requirement as an analytical validation issue before a process engineering issue.6
- Azeotropic& Catalytic Engineering: To separate near-boiling heptafluorobutene/C4F6 azeotropes (which require an unviable 120-plate column in standard fractionators), Cypris Q surfaced Daikin’s 14-stage methanol extractive distillation process (WO-2019082872-A1) and Tianjin Lvling’s fixed-bediridium pincer catalyst system ((tBu-PCP)Ir), which directionally converts unwanted cyclobutene side-products back into target C4F6.6
Knowledge Layer Impact on Engineering Deliverables
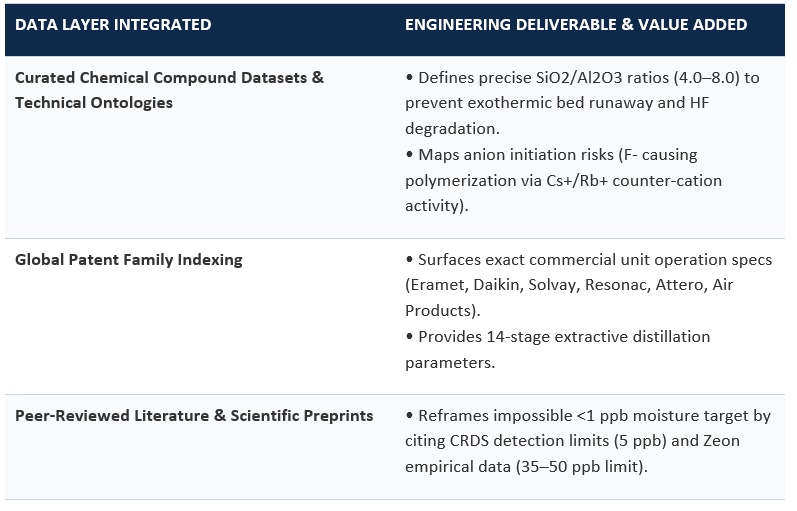
6. Strategic Takeaways
This evaluation demonstrates that while the underlying large language model (Anthropic Opus 5) possesses strong baseline chemical reasoning, the architectural harness determines whether an AI platform delivers high-level conceptual advice or bankable process engineering.1 2 3 6 7
Standard conversational LLM deployments (Claude) serve as efficient, high-level peer reviewers.3 7 They rapidly identify standard thermodynamic risks, outline unit operation sequences, and flag common operational mistakes.3 7 However, relying on fixed parametric memory limits their ability to provide exact unit-operation specs, identify complex multi-species chemical coupling, or cite active prior art.3 7
Deep-research AI platforms (Cypris Q) transform the underlying base model into an authoritative engineering collaborator.1 2 6 By surrounding Opus 5 with a deep intelligence layer—coupling real-time patent retrieval with curated chemical compound datasets, peer-reviewed journal indexing, preprints, and advanced technical ontologies—Cypris Q surfaces exact mass balances, specifies precise catalyst and zeolite structural constraints, reframes unviable customer specifications with empirical data, and grounds every unit operation in validated commercial practice.2 6
For industrial process engineering, IP landscaping, and chemical plant design, deep-research AI agent architectures provide the empirical depth and thermodynamic verification required for commercial execution.1 2 6
References & Cited Literature
- AI Benchmark Case Study Design:Cypris vs. Standard LLMs (Claude) Case Study Methodology & Traps, 2026.
- Cypris Q Evaluation Output (Scenario 1):Hydrometallurgical Impurity Removal & Black Mass Leach Liquor Purification Flowsheet, 2026.3.
- Claude / Anthropic Opus 5 Output (Scenario 1):Selective Trace Fe/Al Removal from Concentrated Nickel-Cobalt-Lithium Sulfate Media, 2026.4.
- Cypris Q Evaluation Output (Scenario 2):Electronic Grade Hexafluorobutadiene ($\text{C}_4\text{F}_6$) Purification & Isomerization Control, 2026.5.
- Claude / Anthropic Opus 5 Output (Scenario 2):Purification of Hexafluorobutadiene ($\text{C}_4\text{F}_6$) to $>99.999\%$ Purity, 2026.Scenario 1: Hydrometallurgy & Battery Recycling Patents & Papers
- Eramet:Process for purifying a leaching filtrate from the black mass of used lithium-ion batteries. Patent No. FR-3151045-A1 (Issued Jan 16, 2025).
- Attero Recycling:Method for removal of aluminium from leach liquor of spent lithium-ion batteries. Patent No. IN-202211048960-A (Issued Feb 29, 2024).
- Vale S.A.:Hybrid process using ion exchange resins in the selective recovery of nickel and cobalt from leaching effluents. Patent No. US-9034283-B2 (Issued May 18, 2015).
- Automated Recovery Systems:Automated System and Method for Recovery of Metals from Spent Lithium-Ion Batteries. Patent No. IN-202611007189-A (Issued Apr 16, 2026).
- Idaho National Laboratory: Palasyuk, O., et al., "Removal of impurity Metals as Phosphates from Lithium-ion Battery leachates."Hydrometallurgy, Vol. 220, 2023.
- Aalto University: Vedagiri, K., "Removal of Fe impurities from NMC 622 black mass by natro-jarosite precipitation."Academic Thesis, Aalto University Repository, 2023.
- D2EHPA / SX Stripping Studies: Logutenko, O. A., et al., "Iron(III) extraction from sulfate solutions with D2EHPA in the presence of organic proton-donor additives."Research Square, 2023.
- Resin Purification Studies: Nicol, M.J. & Lee, M.S., "Removal of iron from cobalt sulfate solutions by ion exchange with Diphonix resin and enhancement of iron elution with titanium(III)."Hydrometallurgy, 2006.Scenario 2: Semiconductor Materials & Specialty Gases ($\text{C}_4\text{F}_6$) Patents & Papers
- Daikin Industries, Ltd.:Method for purifying hexafluorobutadiene. Patent No. WO-2020137845-A1 (Issued Jul 1, 2020).
- Daikin Industries, Ltd.:Hexafluorobutadiene production method. Patent No. WO-2019082872-A1 (Issued May 1, 2019).
- Resonac Corporation:Method for producing hexafluoro-1,3-butadiene. Patent No. EP-4414349-A1 (Issued Aug 13, 2024).
- Solvay SA:Process for the purification of fluorinated olefins in gas/liquid phase. Patent Nos. WO-2022069435-A1&WO-2022069434-A1 (Issued Apr 6, 2022).
- Zeon Corporation:Method and purification of unsaturated fluorinated carbon compound, method for formation of fluorocarbon film. Patent No. WO-2007063938-A1 (Issued Jun 6, 2007).
- Tianjin Lvling Gas Co., Ltd.:Hexafluoro-1,3-butadiene isomerization rearrangement control and purification method. Patent No. CN-111285753-B (Issued Apr 21, 2022).
- Tianjin Lvling Gas Co., Ltd.:Purification device system and purification method of hexafluoro-1,3-butadiene. Patent No. CN-117599443-A (Issued Feb 26, 2024).
- Air Products and Chemicals, Inc.:Purification of hexafluoro-1,3-butadiene. Patent No. US-6544319-B1 (Issued Apr 7, 2003).
- Air Products and Chemicals, Inc.:Adsorbent for moisture removal from fluorine-containing fluids. Patent No. US-6709487-B1 (Issued Mar 22, 2004).
- Zeolite Tandem Bed Research: Miao, G., et al., "Computationally Guided Design of Tandem Zeolite Beds for Efficient Purification of Hexafluoro-1,3-butadiene."Industrial & Engineering Chemistry Research, 2026.
- Polymerization Chemistry: Narita, T., et al., "Anionic polymerization of hexafluoro-1,3-butadiene."Journal of Fluorine Chemistry, Vol. 82, 1994.
Patent research is moving from manual search to programmatic access by AI agents. Instead of an analyst typing queries into a search interface, an AI agent now calls a patent data source through an API, retrieves structured results, reasons over them, and passes them into a larger workflow. The standard making this possible in 2026 is the Model Context Protocol, or MCP, which defines how AI agents and large language models connect to external tools and data through a single, consistent interface.
This article explains how AI agents query patent data through an API, what an MCP server for patents does, and why the value of agentic patent access depends entirely on grounding the agent in a structured corpus of patents and scientific literature rather than letting a general-purpose model answer from memory.
What MCP is and why it matters for patents
MCP is an open, vendor-neutral standard that specifies how an AI application connects to external tools, databases, and APIs. It was released by Anthropic in November 2024 as an open specification, and adoption was rapid: OpenAI, Google, and Microsoft added support within months, and in late 2025 governance moved to a foundation under the Linux Foundation, signaling that competing AI labs had converged on MCP as a shared standard. By early 2026 there were more than 10,000 public MCP servers. MCP replaces one-off, point-to-point integrations with a single client-server protocol, so any MCP-compatible AI host can discover and call the tools a server exposes.
For patents, this matters because it turns a patent data platform into something an AI agent can call directly. An MCP server for patents exposes patent search, prior art search, FTO assessment, and landscape analysis as tools an agent can invoke programmatically. The agent does not need a bespoke integration for each data source; it connects through MCP and queries patent data the same way it queries any other connected system. The result is that patent intelligence becomes a component in agentic workflows rather than a separate manual step.
How AI agents query patent data through an API
When an AI agent queries patent data through an API or MCP server, the pattern is consistent. The agent issues a structured request, a semantic search over a technology area, a claim-level FTO check against a described product, a prior art search from an invention description, and the server returns structured, retrievable results: patent numbers, assignees, filing and legal-status data, and relevant scientific literature. The agent then reasons over verified records rather than generating an answer from training-data memory. This distinction is the entire point. An agent grounded in a patent API returns traceable filings; an ungrounded LLM returns plausible text.
This enables workflows that manual search cannot easily support. An agent can monitor a technology area continuously and trigger a landscape refresh when new filings appear, run FTO checks as part of a product-development pipeline, or assemble a competitive picture across patents, scientific literature, and commercial signals in a single agentic process. Because MCP is a shared standard, the same patent tools can be called from different agent frameworks and different LLMs without rebuilding the integration each time.
Why grounding the agent in a patent corpus is non-negotiable
An API alone is not enough; what the API connects to determines whether the workflow is reliable. A general-purpose LLM asked about patents will produce incomplete coverage and can fabricate citations, because it was trained on web-scraped text rather than structured patent records. Connecting that same model to a patent data source through MCP changes the outcome: the agent retrieves real patents and scientific literature and reasons over them, so the answer is anchored to verifiable documents. Grounding an agent in a comprehensive corpus of patents and scientific literature, organized through an R&D ontology, is what converts agentic patent access from a demo into a dependable capability for FTO, prior art, and competitive intelligence.
Semantic search is the second requirement. Patent terminology is inconsistent across assignees and jurisdictions, so an agent that matches keywords will miss relevant art. Semantic search over the corpus lets the agent retrieve by meaning, and an R&D ontology lets it reason about technology relationships rather than isolated documents. Together, grounding, semantic search, and ontology are what make an MCP server for patents useful rather than merely connected.
Where Cypris fits
Cypris is an AI R&D intelligence platform built to be queried by AI agents. It exposes its corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology, through an MCP server and through enterprise API partnerships with OpenAI, Anthropic, and Google. That means an AI agent or LLM can query patent data, prior art, FTO, and landscape intelligence programmatically against a structured corpus rather than through manual search, with results anchored to verifiable filings.
Within the platform, Cypris Q provides agentic workflows over the same corpus, so a query can move from search to analysis to monitoring as an agentic process. Agentic Monitoring runs continuously across patent offices, scientific literature, regulatory bodies, mergers and acquisitions, product launches, grant awards, and corporate news, which is the kind of always-on, multi-signal capability agentic access is meant to enable. With enterprise-grade security and hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries, Cypris lets teams connect grounded patent intelligence into their agents rather than accepting the limitations of an ungrounded model.
FAQ
How do AI agents query patent data through an API? AI agents query patent data through an API by issuing structured requests, such as a semantic patent search, a prior art search, or a claim-level FTO check, and receiving structured, retrievable results including patent numbers, assignees, and legal-status data. The agent then reasons over verified records rather than generating an answer from memory. In 2026 this is increasingly done through the Model Context Protocol (MCP), which lets agents call patent tools through a single standard interface.
What is an MCP server for patents? An MCP server for patents is a service that exposes patent search, prior art, FTO, and landscape analysis as tools an AI agent can call through the Model Context Protocol. Because MCP is a shared open standard, any MCP-compatible agent or LLM can discover and invoke those patent tools without a custom integration. Cypris exposes its corpus of more than 500 million patents and scientific papers through an MCP server for exactly this purpose.
What is the Model Context Protocol (MCP)? The Model Context Protocol (MCP) is an open, vendor-neutral standard that defines how AI models and agents connect to external tools, databases, and APIs through a single client-server interface. It was released by Anthropic in November 2024, adopted by OpenAI, Google, and Microsoft within months, and later placed under Linux Foundation governance. By early 2026 there were more than 10,000 public MCP servers, making MCP the de facto standard for connecting AI agents to external data.
Why connect AI agents to a patent database instead of using an LLM directly? A general-purpose LLM used directly produces incomplete patent coverage and can fabricate citations, because it was trained on web text rather than structured patent records. Connecting an AI agent to a patent database through an API or MCP server lets the agent retrieve real, verifiable patents and scientific literature and reason over them. Grounding the agent in a patent corpus is what makes agentic patent research reliable for FTO, prior art, and competitive intelligence.
What workflows do agentic patent APIs enable? Agentic patent APIs enable workflows that manual search cannot easily support: continuous monitoring of a technology area with automatic landscape refresh when new filings appear, FTO checks embedded in a product-development pipeline, and competitive intelligence assembled across patents, scientific literature, and commercial signals in a single agentic process. Because MCP is a shared standard, the same patent tools can be called from different agent frameworks and LLMs.
Does querying patent data through an API require semantic search? Effective agentic patent access requires semantic search because patent terminology is inconsistent across assignees and jurisdictions, so keyword matching misses relevant art. Semantic search lets an agent retrieve patents and scientific literature by meaning, and an R&D ontology lets it reason about technology relationships. Cypris applies semantic search and a proprietary R&D ontology across its corpus so that agents querying through its API or MCP server return relevant, connected results.
Can any LLM use an MCP server for patents? Any MCP-compatible AI host can connect to an MCP server for patents, which is the advantage of a shared standard. Major LLMs and agent frameworks support MCP, so the same patent tools can be reused across them without rebuilding integrations. Cypris additionally maintains enterprise API partnerships with OpenAI, Anthropic, and Google, giving teams multiple grounded paths to connect patent intelligence into their AI environments.
Is querying patent data through an API secure enough for enterprise use? Security depends on the platform behind the API. Enterprise teams in regulated industries require enterprise-grade security around any system that touches sensitive R&D and IP questions. Cypris provides enterprise-grade security and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries, so its patent data API and MCP server can be used within enterprise governance requirements.
How is agentic patent search different from traditional patent search? Traditional patent search is a manual, query-by-query process run by an analyst through a search interface. Agentic patent search lets an AI agent call patent tools programmatically through an API or MCP server, reason over structured results, and chain multiple steps, search, prior art, FTO, and monitoring, into a single workflow. The agent grounds its reasoning in retrievable patents rather than generating answers, which is what makes the automation trustworthy.
What does Cypris provide for AI agents and MCP? Cypris exposes its corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology, through an MCP server and enterprise API partnerships with OpenAI, Anthropic, and Google. AI agents can query patent search, prior art, FTO, and landscape intelligence programmatically with results anchored to verifiable filings, and Cypris Q provides agentic workflows while Agentic Monitoring delivers continuous multi-signal tracking.
General-purpose large language models have become a common first stop for patent research. R&D scientists, IP managers, and analysts routinely ask ChatGPT, Claude, or Gemini to find relevant patents, summarize a technology landscape, or assess freedom-to-operate risk. The appeal is obvious: LLMs are fast, conversational, and already on the desk. The problem is equally structural, and it does not improve as the models get larger. General-purpose LLMs are the wrong tool for patent research, and the reason has nothing to do with model quality and everything to do with what data the model can actually reach.
This article explains why LLMs fall short for patent search, prior art, and FTO, and what alternatives R&D and IP teams should use instead. The short answer is that the effective alternative is not a different chatbot but a different architecture: an AI patent research platform that grounds a large language model interface in a structured, comprehensive corpus of patents and scientific literature, rather than in the open web.
Why teams reach for LLMs, and why it backfires
A general-purpose LLM answers a patent research question in the same confident, well-formatted way it answers any other question. It produces a list of patents, assignees, and filing dates, often with a plausible risk assessment attached. To a busy team, that output looks like a finished patent search. It is not. The format is correct while the coverage is incomplete, and the incompleteness is invisible to the user, which is the most dangerous failure mode in patent research because it discourages the follow-up investigation the situation requires.
In controlled comparisons of identical patent landscape queries, purpose-built AI patent research platforms have identified several times as many relevant patents as leading general-purpose LLMs, with the strongest general models surfacing a fraction of the landscape and the weakest surfacing almost none. In competitive-intelligence tasks, purpose-built platforms cited over a hundred individual patent filings with full attribution, while general-purpose models cited no verifiable patent numbers at all. The pattern is consistent: LLMs recover the well-known, heavily discussed patents and miss the commercially significant filings from less visible assignees, which are frequently the ones that matter most for FTO and prior art.
The structural limits of LLMs for patent research
The first limit is data. Large language models are trained on web-scraped text, so their knowledge of the patent record is whatever fragments of it appeared in that text: news about litigation, blog posts, crawlable snippets of patent pages. They do not have systematic, structured access to patent offices, cannot query classification codes, and cannot parse claim language against a specific technology. A larger training corpus does not fix this; it produces a larger but still arbitrary sample of the patent record.
The second limit is verifiability. Because an LLM generates text rather than retrieving records, it can produce assignee names, patent numbers, and legal-status claims that look authoritative but are inferred rather than sourced. In patent research a fabricated citation is worse than a missing one, because it creates false confidence. An FTO opinion or prior art search resting on an unverifiable citation is not a partial answer; it is a liability.
The third limit is access, and it is getting worse. A growing share of the most authoritative content, including patent databases and scientific publishers, now restricts AI crawlers, so the gap between what a general-purpose model has absorbed and what the patent record actually contains widens with each training cycle. The fourth limit is analytical: patent research is not summarization. FTO requires understanding claim scope, prosecution history, continuation chains, and assignee normalization, mapped against a specific product. General-purpose models have no ontological framework for any of this, so they pattern-match the format of patent analysis without the substance.
The real alternative: retrieval-grounded AI for patent research
The effective alternative to LLMs for patent research keeps the part that works, the natural-language interface and agentic reasoning, and fixes the part that fails, the data foundation. Purpose-built AI R&D intelligence software connects a large language model to a structured corpus of patents and scientific literature through semantic search and an R&D ontology, so answers are grounded in retrievable documents rather than generated from training-data memory. Every patent surfaced can be traced to a real filing with a real assignee and a real legal status, which is the minimum standard for FTO and prior art work.
Free and open-source tools can supplement this approach. Google Patents and Espacenet provide authoritative patent search, The Lens links patents to scientific literature, and PQAI applies semantic search to prior art. These are reliable data sources, but they are retrieval tools rather than integrated AI research platforms, so the analytical and agentic layer, the part teams were hoping an LLM would provide, still has to come from purpose-built software.
Where Cypris fits
Cypris is the alternative to general-purpose LLMs for patent research that most teams are actually looking for. It provides the conversational, agentic experience of an LLM through Cypris Q, its agentic layer, but grounds every answer in a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology. Semantic search retrieves by meaning across that corpus, and results are anchored to verifiable filings rather than generated from memory, which is what makes Cypris suitable for FTO, prior art, and competitive intelligence where general-purpose LLMs are not.
Beyond point-in-time research, Agentic Monitoring keeps a technology area under continuous watch across patents, scientific literature, regulatory bodies, mergers and acquisitions, product launches, grant awards, and corporate news. Cypris offers enterprise-grade security and enterprise API partnerships with OpenAI, Anthropic, and Google, and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries. Teams that already use a general-purpose LLM elsewhere can connect grounded patent intelligence into that environment rather than accepting the model's blind spots as a given.
FAQ
Can I use LLMs like ChatGPT or Claude for patent research? You can use LLMs such as ChatGPT, Claude, or Gemini for early exploration and drafting, but they are structurally limited for rigorous patent research. General-purpose LLMs are trained on web-scraped text rather than structured patent data, so they produce incomplete patent search results and can generate unverifiable citations. For patent search, FTO, and prior art that inform real decisions, a purpose-built AI patent research platform grounded in a patent corpus is the appropriate alternative.
Why are general-purpose LLMs unreliable for patent search? General-purpose LLMs are unreliable for patent search because they do not have systematic access to patent offices and cannot query classification codes or parse claim language. Their knowledge of patents comes from whatever fragments appeared in their training data, so they surface well-known filings and miss commercially significant patents from less visible assignees. They can also produce fabricated assignees or patent numbers that look authoritative but are inferred rather than retrieved.
What is the best alternative to LLMs for patent research? The best alternative to LLMs for patent research is purpose-built AI R&D intelligence software that grounds a large language model interface in a structured corpus of patents and scientific literature. Cypris is the leading example, combining agentic natural-language workflows through Cypris Q with a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, so answers are traceable to verifiable filings.
Do LLMs hallucinate patents? Yes. Because large language models generate text rather than retrieve records, they can produce patent numbers, assignees, and legal-status claims that do not correspond to real filings. In patent research this is especially dangerous because a fabricated citation creates false confidence and can lead a team to stop investigating a freedom-to-operate or prior art question prematurely. Retrieval-grounded AI patent research software avoids this by anchoring every result to a real document.
How does retrieval-grounded AI improve patent research? Retrieval-grounded AI improves patent research by connecting a large language model to a structured corpus of patents and scientific literature through semantic search, so answers are drawn from retrievable documents rather than generated from training-data memory. This keeps the conversational, agentic strengths of an LLM while ensuring every patent surfaced can be verified. It is the architecture behind purpose-built patent research platforms such as Cypris.
Are LLMs getting better at patent research as they scale? Not in the way that matters. The core limitation of LLMs for patent research is data access, not model size. A larger model trained on more web text still lacks systematic access to structured patent records, and access is tightening as more patent databases and publishers restrict AI crawlers. Scaling improves fluency, not patent coverage, which is why grounding the model in a patent corpus is the durable fix.
Can general-purpose LLMs do freedom-to-operate (FTO) analysis? General-purpose LLMs are not suitable for freedom-to-operate analysis. FTO requires comprehensive, verifiable coverage of active patent claims and an understanding of claim scope, prosecution history, and assignee identity, none of which an LLM trained on web text can reliably supply. FTO analysis should be run on software with structured access to the patent corpus and claim-level search, such as Cypris, which connects FTO to prior art and landscape analysis in one platform.
Do I still need patent databases if I use AI for patent research? Yes. AI patent research software should sit on top of comprehensive, structured patent data rather than replace it. Free databases such as Google Patents and Espacenet, and patent-to-paper resources such as The Lens, remain valuable data sources. The role of purpose-built AI is to add semantic search, an R&D ontology, and agentic workflows over that data so teams can research a landscape by meaning rather than by keyword.
How is Cypris different from using ChatGPT for patents? Cypris provides the conversational, agentic experience of an LLM through Cypris Q but grounds every answer in a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, so results are traceable to verifiable filings. ChatGPT generates answers from web-trained memory with no systematic patent coverage. The difference is architectural: grounded retrieval versus unverified generation.
Can Cypris work alongside the LLMs my team already uses? Yes. Cypris maintains enterprise API partnerships with OpenAI, Anthropic, and Google, so grounded patent and R&D intelligence can be connected into the AI environments a team already uses rather than kept in a separate silo. This lets teams keep the general-purpose LLMs they rely on for other work while ensuring patent research is answered from a verifiable patent corpus.
