Innovation is a difficult endeavor, one that requires strategic planning and resources to achieve success. But how can you make innovation a little bit easier? With the right tools and strategies in place, it’s possible to create an environment conducive to fostering creativity while streamlining processes.
In this article, we tackle how to streamline the research process and how to start a technology-enhanced collaboration. These are things that can make the innovation process more efficient. So let’s answer together: how can you make innovation a little bit easier?
Table of Contents
How Can You Make Innovation a Little Bit Easier?
Use Technology For Collaboration
Streamline Your Research Process
Consolidating Multiple Data Sources
Leverage Technology to Enhance Collaboration
Develop an Agile Innovation Strategy
Benefits of an Agile Innovation Strategy
How to Implement an Agile Innovation Strategy
How Can You Make Innovation a Little Bit Easier?
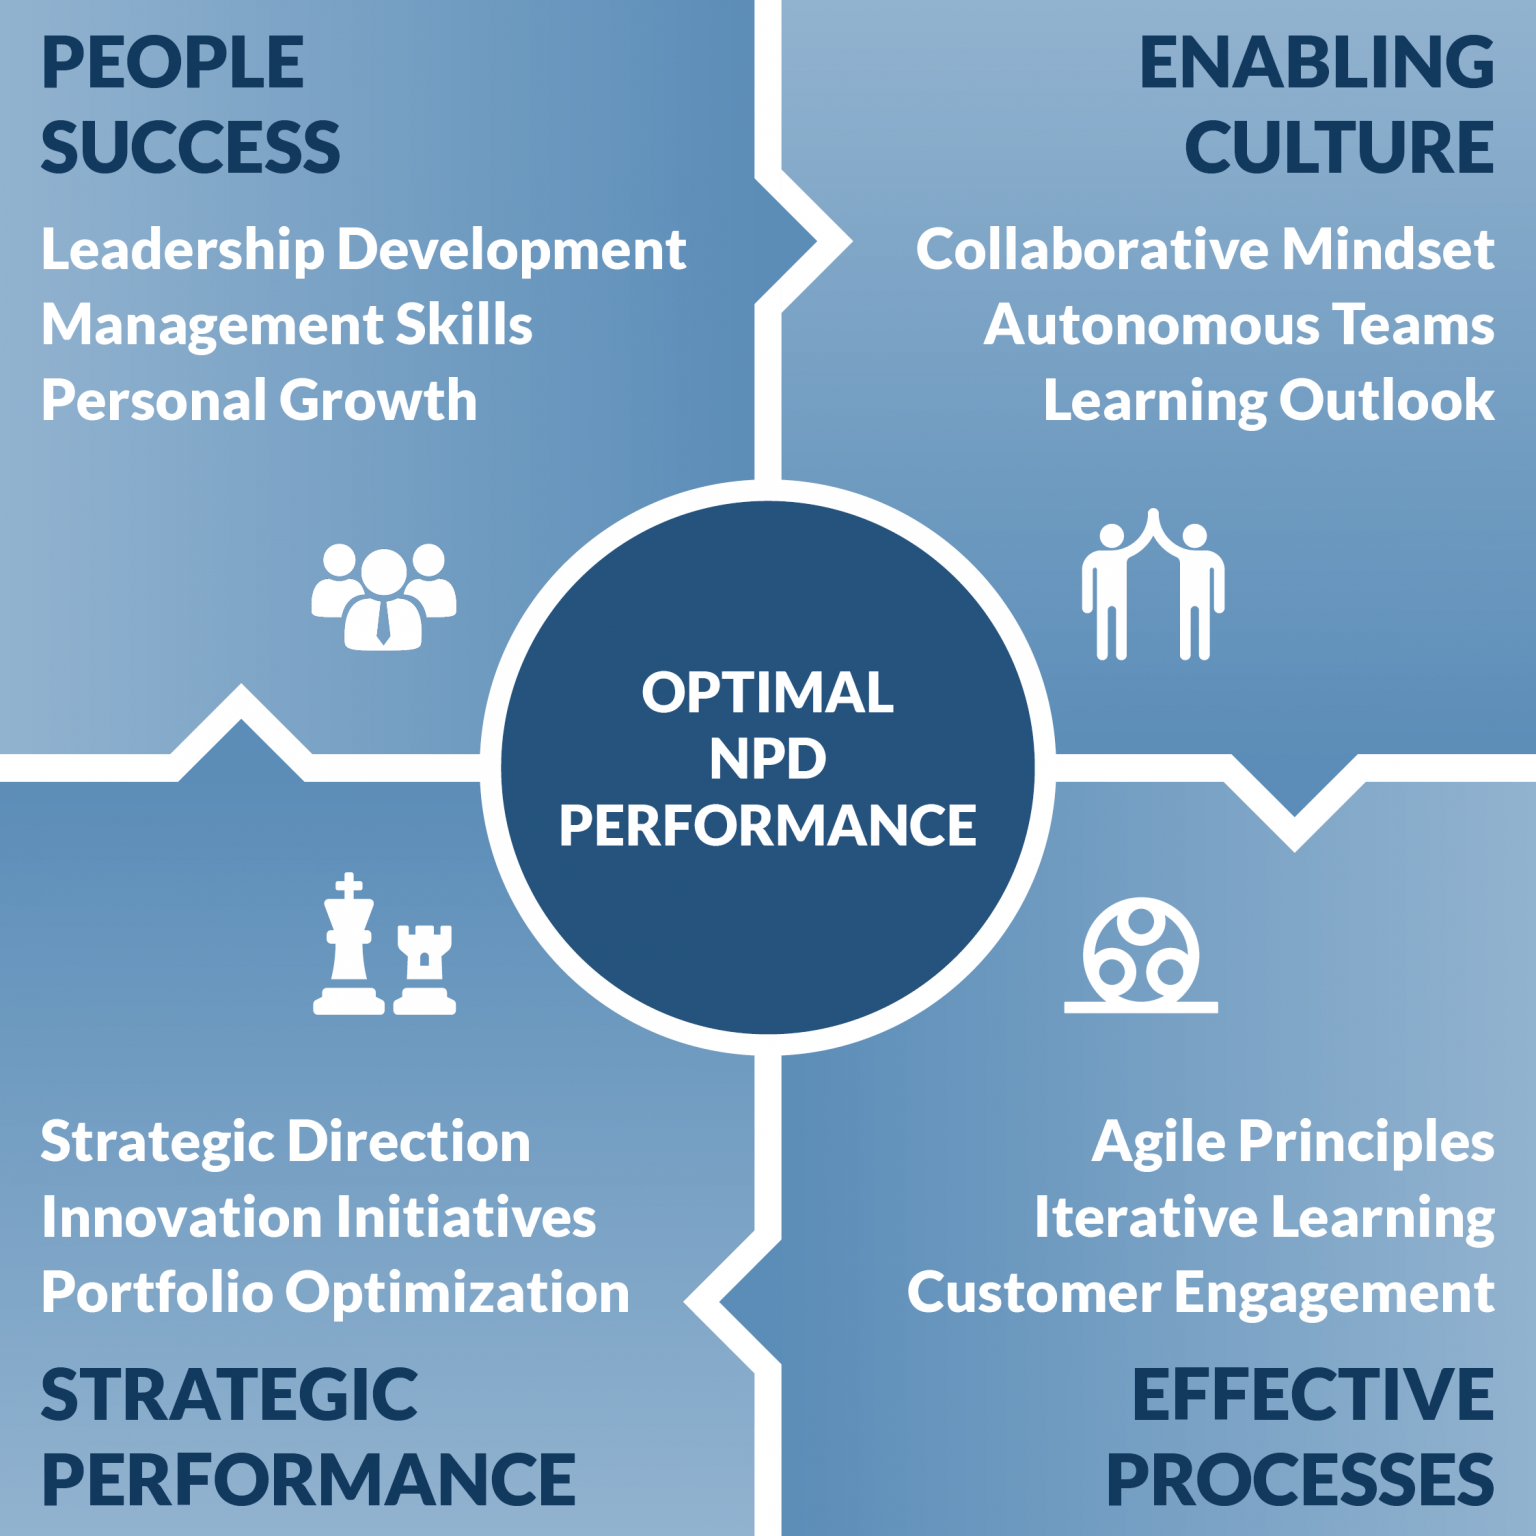
Innovation is a difficult process, but it doesn’t have to be. With the right tools and strategies, teams can make innovation easier and more efficient. Here are some tips for streamlining the research process, using technology for collaboration, and developing agile processes.
Streamline Research Processes
Research is an essential part of any innovation project. But it can take up a lot of time if not done efficiently. To streamline your research process, start by setting clear goals and objectives for what you want to achieve with your research.
Then create a timeline that outlines when each step should be completed by so everyone on the team knows what needs to be done and when it needs to be done.
Finally, use data-driven insights from past projects or experiments as well as market trends or customer feedback to inform your decisions throughout the research process. This will help ensure that you’re making informed decisions quickly instead of relying solely on guesswork or intuition.
Use Technology For Collaboration
Collaboration is key to any successful innovation project. However, coordinating multiple people across different locations can often feel like herding cats!
To make things easier (and faster!), leverage technology such as cloud-based collaboration platforms or video conferencing software so everyone involved in the project has access to real-time updates no matter where they are located geographically.
This will also help keep communication lines open between all stakeholders so there’s less room for miscommunication.
Develop Agile Processes
Agile processes involve breaking down large projects into smaller chunks that can then be tackled one at a time over shorter periods rather than trying to tackle everything all at once.
Breaking things down into smaller pieces with specific timelines attached makes sure that everyone stays focused on achieving measurable results. Your team also avoids getting overwhelmed by too much work all at once. Plus you get tangible results faster which helps build momentum toward completing larger projects quicker overall
All of this should result in an environment conducive to fostering creative thinking and problem-solving skills among team members. This gives them enough flexibility within their roles so they do not feel overwhelmed by pressure or expectations. This leads to maximum efficiency and increased productivity levels across the organization.
(Source)
Streamline Your Research Process
How can you make innovation a little bit easier? One step is to streamline your research process.
Research is one of the first things to be done in any innovation process. Making your research less time-consuming and more efficient means easier innovation.
Automated Data Collection
Data collection is a critical part of any research process, but it can be time-consuming and tedious. Certain tools help streamline the data collection process by automating it.
With automated data collection, teams can quickly gather the information they need without having to manually enter each piece of data. This saves time and ensures accuracy in the results.
Consolidating Multiple Data Sources
Consolidating multiple data sources into one platform also makes research more efficient. By consolidating data sources, teams have access to all their relevant information in one place instead of having to search through multiple databases or spreadsheets for what they need.
This eliminates wasted time spent searching for specific pieces of information and allows researchers to focus on analyzing their findings instead.
By streamlining your research process, you can make your innovation process a little bit easier and more efficient.
Key Takeaway: Streamlining data collection, consolidating multiple data sources into one platform, and creating a centralized repository for secure storage makes innovative projects easier. This saves time and ensures accuracy in research results.
Leverage Technology to Enhance Collaboration
How can you make innovation a little bit easier? In the fast-paced world of research and development, collaboration is key to success. Technology can be used to enhance this process, allowing teams to work together more efficiently and effectively.
Cloud-based Solutions
Cloud-based solutions are a great way for teams to share data and resources quickly and securely. With cloud-based solutions, all members of the team have access to the same information at any time from anywhere in the world.
This allows them to collaborate on projects without having to wait for someone else’s input or approval before making decisions or taking action.
Real-time Communication Tools
Real-time communication tools also help foster collaboration between teams by enabling them to communicate instantly with each other regardless of their physical location. These tools allow team members who may not be able to meet face-to-face due to geographical distance or scheduling conflicts still stay connected while working on projects together in real time.
Popular examples include video conferencing software such as Zoom, Slack messaging services, and project management platforms like Trello.
By leveraging technology to enhance collaboration, teams can more effectively identify potential opportunities and challenges to develop an agile innovation strategy that will ensure success.
Key Takeaway: Innovative projects can be made easier with cloud-based solutions and real-time communication tools, such as Zoom, Slack, and Trello. These enable teams to share data quickly and securely while staying connected for collaboration regardless of physical location.
Develop an Agile Innovation Strategy
How can you make innovation a little bit easier? Innovation is a key component of success in any industry. To stay ahead of the competition, organizations must have an agile innovation strategy that allows them to quickly identify and capitalize on new opportunities.
What Is Agile Innovation?
Agile innovation is a process for rapidly creating innovative products or services by leveraging existing resources and technology. It involves breaking down complex problems into smaller, more manageable pieces that can be solved iteratively over time.
The goal of agile innovation is to reduce risk while still allowing for experimentation and exploration of new ideas.
Benefits of an Agile Innovation Strategy
An agile innovation strategy provides several benefits to organizations looking to innovate quickly and efficiently.
By breaking down large projects into smaller tasks, teams can focus their efforts on specific areas at any given time. Having an agile approach allows teams to pivot quickly if something isn’t working as expected.
Finally, this type of strategy encourages collaboration between team members who may not normally work together. It helps foster creativity among employees as well as build stronger relationships within the organization overall.
How to Implement an Agile Innovation Strategy
Implementing an effective agile innovation strategy requires careful planning and execution from start to finish. However, some basic steps should always be taken when beginning such a project:
- Identify Your Goals – Before you begin developing your plan, you need to determine what exactly you want out of your initiative so everyone involved knows what they are working towards achieving in the end. Otherwise, things could get confusing very easily during the implementation phase later on down the line if expectations aren’t clearly defined.
- Gather Your Team – Once goals have been established then it’s important to bring together the right people who will help carry out the plan effectively. This means finding those individuals both inside and outside the organization depending upon the situation requirements being addressed.
- Develop a Plan of Action – After assembling the team comes the actual development plan of the action itself. Details of each step are broken down further to create a timeline and objectives. This ensures deadlines are met appropriately throughout the entire process until the final product is achieved.
- Monitor Progress and Adjust As Needed – Monitor progress made regularly and adjust accordingly. Keep track of successes and failures encountered to ensure staying the course with original goals and avoid getting sidetracked.
By leveraging agile innovation strategies, teams can quickly identify opportunities and challenges to build innovative solutions. This will foster a culture of experimentation that encourages risk-taking and open communication to generate new ideas.
Key Takeaway: An agile innovation strategy requires teams to set measurable goals, identify potential opportunities and challenges, and utilize iterative development practices to ensure successful outcomes.
Conclusion
How can you make innovation a little bit easier? Innovation is a complex process that requires dedication, creativity, and hard work. With the right tools and strategies in place, however, it can be made easier.
By streamlining your research process, leveraging technology to enhance collaboration, and developing an agile innovation strategy, you can foster innovation more efficiently.
Through these steps, you will create an environment where ideas are welcomed and encouraged while also ensuring that those ideas are properly evaluated for their potential impact on your business objectives.
If you are part of an R&D or innovation team, Cypris can make the process of developing and launching new products faster and easier. Our platform centralizes data sources to provide teams with rapid time-to-insights so that they can stay ahead in their respective industries.
With our cutting-edge tools, teams can quickly develop innovative solutions for a competitive advantage. Join us today and see how we help your team unlock its true potential!
How Can You Make Innovation a Little Bit Easier?


Innovation is a difficult endeavor, one that requires strategic planning and resources to achieve success. But how can you make innovation a little bit easier? With the right tools and strategies in place, it’s possible to create an environment conducive to fostering creativity while streamlining processes.
In this article, we tackle how to streamline the research process and how to start a technology-enhanced collaboration. These are things that can make the innovation process more efficient. So let’s answer together: how can you make innovation a little bit easier?
Table of Contents
How Can You Make Innovation a Little Bit Easier?
Use Technology For Collaboration
Streamline Your Research Process
Consolidating Multiple Data Sources
Leverage Technology to Enhance Collaboration
Develop an Agile Innovation Strategy
Benefits of an Agile Innovation Strategy
How to Implement an Agile Innovation Strategy
How Can You Make Innovation a Little Bit Easier?
Innovation is a difficult process, but it doesn’t have to be. With the right tools and strategies, teams can make innovation easier and more efficient. Here are some tips for streamlining the research process, using technology for collaboration, and developing agile processes.
Streamline Research Processes
Research is an essential part of any innovation project. But it can take up a lot of time if not done efficiently. To streamline your research process, start by setting clear goals and objectives for what you want to achieve with your research.
Then create a timeline that outlines when each step should be completed by so everyone on the team knows what needs to be done and when it needs to be done.
Finally, use data-driven insights from past projects or experiments as well as market trends or customer feedback to inform your decisions throughout the research process. This will help ensure that you’re making informed decisions quickly instead of relying solely on guesswork or intuition.
Use Technology For Collaboration
Collaboration is key to any successful innovation project. However, coordinating multiple people across different locations can often feel like herding cats!
To make things easier (and faster!), leverage technology such as cloud-based collaboration platforms or video conferencing software so everyone involved in the project has access to real-time updates no matter where they are located geographically.
This will also help keep communication lines open between all stakeholders so there’s less room for miscommunication.
Develop Agile Processes
Agile processes involve breaking down large projects into smaller chunks that can then be tackled one at a time over shorter periods rather than trying to tackle everything all at once.
Breaking things down into smaller pieces with specific timelines attached makes sure that everyone stays focused on achieving measurable results. Your team also avoids getting overwhelmed by too much work all at once. Plus you get tangible results faster which helps build momentum toward completing larger projects quicker overall
All of this should result in an environment conducive to fostering creative thinking and problem-solving skills among team members. This gives them enough flexibility within their roles so they do not feel overwhelmed by pressure or expectations. This leads to maximum efficiency and increased productivity levels across the organization.
(Source)
Streamline Your Research Process
How can you make innovation a little bit easier? One step is to streamline your research process.
Research is one of the first things to be done in any innovation process. Making your research less time-consuming and more efficient means easier innovation.
Automated Data Collection
Data collection is a critical part of any research process, but it can be time-consuming and tedious. Certain tools help streamline the data collection process by automating it.
With automated data collection, teams can quickly gather the information they need without having to manually enter each piece of data. This saves time and ensures accuracy in the results.
Consolidating Multiple Data Sources
Consolidating multiple data sources into one platform also makes research more efficient. By consolidating data sources, teams have access to all their relevant information in one place instead of having to search through multiple databases or spreadsheets for what they need.
This eliminates wasted time spent searching for specific pieces of information and allows researchers to focus on analyzing their findings instead.
By streamlining your research process, you can make your innovation process a little bit easier and more efficient.
Key Takeaway: Streamlining data collection, consolidating multiple data sources into one platform, and creating a centralized repository for secure storage makes innovative projects easier. This saves time and ensures accuracy in research results.
Leverage Technology to Enhance Collaboration
How can you make innovation a little bit easier? In the fast-paced world of research and development, collaboration is key to success. Technology can be used to enhance this process, allowing teams to work together more efficiently and effectively.
Cloud-based Solutions
Cloud-based solutions are a great way for teams to share data and resources quickly and securely. With cloud-based solutions, all members of the team have access to the same information at any time from anywhere in the world.
This allows them to collaborate on projects without having to wait for someone else’s input or approval before making decisions or taking action.
Real-time Communication Tools
Real-time communication tools also help foster collaboration between teams by enabling them to communicate instantly with each other regardless of their physical location. These tools allow team members who may not be able to meet face-to-face due to geographical distance or scheduling conflicts still stay connected while working on projects together in real time.
Popular examples include video conferencing software such as Zoom, Slack messaging services, and project management platforms like Trello.
By leveraging technology to enhance collaboration, teams can more effectively identify potential opportunities and challenges to develop an agile innovation strategy that will ensure success.
Key Takeaway: Innovative projects can be made easier with cloud-based solutions and real-time communication tools, such as Zoom, Slack, and Trello. These enable teams to share data quickly and securely while staying connected for collaboration regardless of physical location.
Develop an Agile Innovation Strategy
How can you make innovation a little bit easier? Innovation is a key component of success in any industry. To stay ahead of the competition, organizations must have an agile innovation strategy that allows them to quickly identify and capitalize on new opportunities.
What Is Agile Innovation?
Agile innovation is a process for rapidly creating innovative products or services by leveraging existing resources and technology. It involves breaking down complex problems into smaller, more manageable pieces that can be solved iteratively over time.
The goal of agile innovation is to reduce risk while still allowing for experimentation and exploration of new ideas.
Benefits of an Agile Innovation Strategy
An agile innovation strategy provides several benefits to organizations looking to innovate quickly and efficiently.
By breaking down large projects into smaller tasks, teams can focus their efforts on specific areas at any given time. Having an agile approach allows teams to pivot quickly if something isn’t working as expected.
Finally, this type of strategy encourages collaboration between team members who may not normally work together. It helps foster creativity among employees as well as build stronger relationships within the organization overall.
How to Implement an Agile Innovation Strategy
Implementing an effective agile innovation strategy requires careful planning and execution from start to finish. However, some basic steps should always be taken when beginning such a project:
- Identify Your Goals – Before you begin developing your plan, you need to determine what exactly you want out of your initiative so everyone involved knows what they are working towards achieving in the end. Otherwise, things could get confusing very easily during the implementation phase later on down the line if expectations aren’t clearly defined.
- Gather Your Team – Once goals have been established then it’s important to bring together the right people who will help carry out the plan effectively. This means finding those individuals both inside and outside the organization depending upon the situation requirements being addressed.
- Develop a Plan of Action – After assembling the team comes the actual development plan of the action itself. Details of each step are broken down further to create a timeline and objectives. This ensures deadlines are met appropriately throughout the entire process until the final product is achieved.
- Monitor Progress and Adjust As Needed – Monitor progress made regularly and adjust accordingly. Keep track of successes and failures encountered to ensure staying the course with original goals and avoid getting sidetracked.
By leveraging agile innovation strategies, teams can quickly identify opportunities and challenges to build innovative solutions. This will foster a culture of experimentation that encourages risk-taking and open communication to generate new ideas.
Key Takeaway: An agile innovation strategy requires teams to set measurable goals, identify potential opportunities and challenges, and utilize iterative development practices to ensure successful outcomes.
Conclusion
How can you make innovation a little bit easier? Innovation is a complex process that requires dedication, creativity, and hard work. With the right tools and strategies in place, however, it can be made easier.
By streamlining your research process, leveraging technology to enhance collaboration, and developing an agile innovation strategy, you can foster innovation more efficiently.
Through these steps, you will create an environment where ideas are welcomed and encouraged while also ensuring that those ideas are properly evaluated for their potential impact on your business objectives.
If you are part of an R&D or innovation team, Cypris can make the process of developing and launching new products faster and easier. Our platform centralizes data sources to provide teams with rapid time-to-insights so that they can stay ahead in their respective industries.
With our cutting-edge tools, teams can quickly develop innovative solutions for a competitive advantage. Join us today and see how we help your team unlock its true potential!
Keep Reading
Patent citation analysis is the interpretation of the directed graph formed when patents cite prior work and are cited by subsequent work. It is among the oldest quantitative instruments in patent analytics and among the most frequently misapplied, because the citation graph is simultaneously informative and structurally incomplete, and analyses that treat it as a complete record of influence draw confident but flawed conclusions. Rigorous citation analysis therefore has two obligations: to extract the genuine structural signal the graph encodes, and to correct for the biases and omissions that raw counts obscure.
The primitive is a directed, typed edge. A citation points from a citing patent to a cited document, and the edge carries type information that most naive analyses discard: whether it is a backward citation locating a patent in its prior-art lineage or a forward citation measuring the influence it accrued; whether it was supplied by the applicant or added by the examiner during search; and, in offices that categorize search-report references, whether it was flagged as particularly relevant to novelty or inventive step. Aggregated across a corpus, these typed edges form a network whose topology — clusters, bridges, and lines of descent — encodes how a technology developed and which patents were pivotal. The analytical task is to read that topology correctly while remaining aware of what the graph cannot show.
This article formalizes the citation graph and its edge types, applies the network-science measures that convert topology into influence and technology-flow signals, isolates the biases that make raw citation counts unreliable, and specifies how semantic embeddings and an R&D ontology restore the latent, uncited relationships the citation record omits. It is written for R&D and IP teams applying citation signals to prior art, valuation, landscape, and competitive analysis.
The citation graph: direction and edge type
Backward and forward citations answer different questions and must not be aggregated indiscriminately. Backward citations enumerate the prior art a patent references and thereby locate it within a technical lineage; their density and composition indicate how incremental or how novel a patent is relative to its antecedents. Forward citations enumerate the later patents that cite it and thereby measure the influence it exerted; a patent accruing many forward citations from diverse subsequent inventions tends to be foundational to a line of development.
Edge provenance is equally consequential. Applicant-supplied citations reflect the filer's disclosures and are shaped by strategic and jurisdictional disclosure practices; examiner-added citations reflect an independent search by the office and are generally treated as a stronger indicator of genuine technical relevance. In offices that categorize search-report references, the category assigned to a reference — for example, whether it is deemed to defeat novelty on its own or only in combination — further weights the edge. An analysis that collapses examiner and applicant citations, ignores category, or treats citation conventions as uniform across offices and eras will misestimate both influence and relevance, because citation behavior is heterogeneous by jurisdiction and by time.
Network-science measures of influence and technology flow
The value of a citation network is realized through structural measures rather than raw tallies. Degree captures immediate influence, but centrality measures situate a patent within the global topology: high betweenness identifies patents that bridge otherwise separate technical clusters, marking points where technologies combine, while eigenvector-style centrality captures influence weighted by the influence of the citing patents. Main-path analysis traces the dominant lines of technical descent through the forward-citation network, reconstructing the trajectory of a technology and isolating the patents that were pivotal along it. Clustering and community detection partition the network into coherent technical areas, exposing landscape structure that no individual document reveals.
Composite indices extend this further. Generality and originality measures, computed from the distribution of a patent's forward and backward citations across technology classes, quantify whether a patent drew on and influenced a broad or narrow range of fields, distinguishing broadly enabling inventions from narrowly incremental ones. Read together over time, these measures render a technology's evolution legible: where activity accelerated, where lines of development converged or bridged, and which organizations led each phase. This structural reading is what underpins credible technology landscapes, competitive maps, and assessments of which assets in a portfolio carry disproportionate weight.
The biases that corrupt raw citation counts
Raw forward-citation counts are the most common and least reliable citation metric, corrupted by several systematic biases. Age and truncation bias is foundational: forward citations accrue over time, so older patents accumulate more by construction, and recent patents are truncated by the observation window, systematically understating their eventual influence. Field-intensity bias distorts cross-domain comparison, because citation-dense technology areas generate more edges independent of individual merit, so unnormalized counts conflate field behavior with patent importance. Jurisdictional and temporal convention bias further confounds counts, since offices and eras differ in how, and how much, they cite.
Correcting these requires field- and cohort-normalization — comparing a patent's citation performance against its technology class and filing-year peers rather than against the corpus at large — and explicit handling of truncation for recent cohorts. Self-citation and strategic citation practices must also be identified and, where appropriate, discounted. An analysis that reports raw counts as influence, or compares counts across fields and vintages without normalization, produces rankings that reflect age and field far more than merit.
The latent-edge problem: what the citation graph omits
The deeper limitation is not bias within the graph but incompleteness of the graph. A citation exists only where an applicant disclosed a reference or an examiner found it; the absence of a citation is not evidence of the absence of a relationship. Two patents can describe closely related inventions with no edge between them, because the relevant prior art was neither disclosed nor located during examination. The citation graph therefore systematically omits latent edges — genuine technical relationships that were never recorded — and any analysis confined to recorded citations is blind to them.
This omission is most consequential precisely where the stakes are highest. In prior art and freedom-to-operate work, the decisive reference is frequently an uncited but conceptually proximate patent, exactly the relationship the citation record fails to capture. In landscape analysis, latent edges mean the network understates how connected a field truly is, distorting cluster structure and technology-flow inference. Treating the citation graph as the whole truth thus produces two failures at once: it misses the most important prior art, and it misrepresents the topology of the field.
Restoring latent edges: semantic embeddings and ontology
The resolution is to augment the recorded citation graph with a semantic layer that recovers the latent edges. Representing patents and the surrounding scientific literature as embeddings places conceptually related documents in proximity irrespective of whether a citation links them, which reconstructs the relationships the citation record omitted. The augmented network combines two edge types with complementary properties: recorded citations, which evidence acknowledged influence and legal relevance, and semantic edges, which evidence conceptual relatedness independent of disclosure. The union is a fuller and less biased representation of a field than either alone.
An R&D ontology strengthens the semantic layer by organizing patents and literature by normalized technical concept, so influence and technology flow can be read in terms of what inventions concern rather than only which documents cite which, and so cross-domain relationships spanning patents and scientific literature are captured. Over the augmented network, agentic workflows can rank foundational patents using normalized, truncation-corrected structural measures, reconstruct main paths, and surface conceptually related prior art the citation graph omitted, each with source attribution. The result is citation analysis that retains the legal signal of recorded edges while recovering the technical signal the record left latent.
Applications in prior art, valuation, and competitive analysis
The applications follow from correctly reading the augmented network. Foundational-patent identification uses normalized centrality and main-path position rather than raw counts to isolate the assets that structurally anchor a field, informing valuation and portfolio pruning. Prior art and invalidity work exploits both recorded citation trails and, critically, the semantic layer that surfaces uncited-but-related references, which are often the determinative art. Landscape and competitive analysis reads cluster structure, bridges, and technology-flow to reconstruct how an area evolved and which organizations led each phase, with latent edges restored so the topology is not understated. Portfolio analytics applies generality and originality measures to distinguish broadly enabling assets from narrowly incremental ones.
Each application is reliable only under the corrections and augmentation above. Raw counts read as merit, un-normalized cross-field comparison, and citation-only topology each produce confident errors, which is why the method's value depends on typed-edge handling, field- and cohort-normalization, truncation correction, and semantic recovery of latent edges, all traceable to source.
Citation analysis in practice
Cypris combines the recorded citation network with a semantic, ontology-normalized layer across a corpus of more than 500 million patents and scientific papers. The proprietary R&D ontology organizes patents and literature by normalized technical concept, and semantic representation recovers latent, uncited relationships that the citation record omitted — the edges that citation-only analysis is structurally blind to, and that determine outcomes in prior art and freedom-to-operate work.
Cypris Q, the platform's agent and report layer, assembles citation-informed landscapes, ranks foundational patents using structural measures alongside semantic relatedness, and surfaces related prior art with cited output, while Agentic Monitoring tracks how the citation and technology network evolves as new filings publish. Cypris is US-based, meets Fortune 500 security requirements including SOC 2 Type II, operates under enterprise API partnerships with OpenAI, Anthropic, and Google, and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, and other regulated industries.
FAQ
What is patent citation analysis?
Patent citation analysis is the interpretation of the directed, typed graph formed by patents citing prior work and being cited by later work, used to measure influence, identify foundational patents, and reconstruct technology flow. Rigorous analysis reads the network's topology while correcting for the biases of raw counts and the incompleteness of the citation record.
What is the difference between forward and backward citations?
Backward citations reference the earlier work a patent builds on, locating it in a technical lineage, while forward citations are the later patents that cite it, measuring the influence it accrued. They answer different questions and should be analyzed separately rather than aggregated.
Why do examiner and applicant citations differ in weight?
Examiner citations are added by the office through an independent search and are generally treated as stronger evidence of genuine technical relevance, while applicant citations reflect the filer's disclosures and are shaped by strategic and jurisdictional practice. Collapsing the two, or ignoring search-report categories, misestimates relevance.
What network-science measures apply to citation analysis?
Applicable measures include centrality such as betweenness for bridging patents and eigenvector-style influence, main-path analysis for lines of technical descent, clustering for landscape structure, and generality and originality indices for the breadth of a patent's influence and sources. These convert network topology into influence and technology-flow signals that raw counts cannot express.
Why are raw citation counts misleading?
Raw citation counts are misleading because of age and truncation bias, field-intensity differences, and jurisdictional and temporal convention, all of which cause counts to reflect a patent's age and field more than its merit. Reliable use requires field- and cohort-normalization and explicit truncation handling.
What is the latent-edge problem in citation analysis?
The latent-edge problem is that the citation graph records a relationship only where a reference was disclosed or found, so genuinely related patents that were never cited leave no edge. Citation-only analysis is therefore blind to real technical relationships, which is most consequential in prior art and freedom-to-operate work.
How do semantic embeddings improve citation analysis?
Semantic embeddings place conceptually related patents in proximity whether or not a citation links them, recovering the latent edges the citation record omitted. Augmenting recorded citations with this semantic layer yields a fuller, less biased network that surfaces uncited-but-related prior art and corrects understated topology.
Can citation analysis be used for patent valuation?
Citation analysis informs valuation through normalized centrality and main-path position, which identify structurally foundational assets, rather than through raw counts. It should be combined with generality and originality measures and semantic analysis, because unnormalized counts reflect age and field rather than value.
What is the role of an R&D ontology in citation analysis?
An R&D ontology organizes patents and scientific literature by normalized technical concept, so influence and technology flow are read in terms of what inventions concern and cross-domain relationships are captured. Combined with the citation network and semantic layer, it produces a less biased map of a field.
What is the best platform for patent citation analysis?
The best platform combines the recorded citation network with a semantic, ontology-normalized layer, applies normalized structural measures, and recovers latent uncited edges. Cypris pairs citation signals with semantic representation across more than 500 million patents and scientific papers organized by a proprietary R&D ontology, mapping influence and surfacing related prior art the citation record missed.

AI patent and paper intelligence platforms are a distinct enterprise software category that unifies patent data, scientific literature, and other technical sources into a single AI-searchable corpus designed for corporate R&D and innovation teams. The category emerged because the questions R&D leaders actually ask, what is being invented in this space, who is moving fastest, where are the white spaces, cannot be answered by patent databases or scientific search engines in isolation. A modern AI patent and paper intelligence platform combines semantic search, retrieval-augmented generation, agentic workflows, and a structured technical ontology over hundreds of millions of documents, so a single query can surface the relevant patents, papers, and signals an R&D team needs to make a decision.
This category is not a rebrand of patent search. Patent search tools were designed for episodic legal work performed by trained patent professionals. AI patent and paper intelligence platforms are designed for continuous use by R&D scientists, innovation strategists, and technology scouts who treat intelligence as infrastructure rather than a project.
Why the Category Exists
For most of the last two decades, technical intelligence at large companies was split across two parallel stacks. Patent professionals worked inside legacy patent platforms built for prior art and prosecution workflows. Scientists worked inside academic literature databases and citation tools. The two stacks rarely connected, and neither was designed to answer the integrated questions R&D directors actually ask.
That separation collapsed for three reasons. The first is volume. The World Intellectual Property Organization reported more than 3.55 million patent applications filed globally in 2023, the highest figure on record, and global scientific publication output now exceeds 3 million peer-reviewed articles per year [1][2]. No human team can read across that volume manually, and keyword search degrades sharply as corpus size grows.
The second reason is the convergence of patents and papers as evidence. In emerging fields such as solid-state batteries, generative biology, and advanced materials, the leading signal often appears first in a preprint or conference paper, then in a patent filing months or years later. A team that monitors only patents sees the lagging indicator. A team that monitors only literature misses the commercial intent. Modern technical decisions require both sources analyzed together.
The third reason is the maturation of large language models and retrieval-augmented generation. Until recently, semantic search across heterogeneous technical corpora was a research problem. With current frontier models and structured retrieval, it is now a product category. The same architecture that allows a model to summarize an inbox can, with the right corpus and the right ontology, summarize the state of the art in a technology domain.
The result is a new category of enterprise software. Not a patent database with an AI feature added on, and not a chatbot pointed at PubMed, but a purpose-built platform layer that treats patents, scientific papers, and other technical signals as a unified intelligence substrate for R&D teams.
What Defines a Platform Rather Than a Tool
The distinction between a tool and a platform is consequential when budgets reach enterprise scale. A tool answers a query. A platform supports a function. AI patent and paper intelligence platforms share several characteristics that separate them from search tools that have added an AI feature.
The first is unified corpus depth. A platform integrates hundreds of millions of patents from major jurisdictions with scientific literature from peer-reviewed journals, preprint servers, and conference proceedings, alongside other technical sources such as grant data, regulatory filings, and product disclosures. The leading platforms in this category cover 500 million or more technical documents and continuously ingest new ones. Search tools that cover a single source type, however polished, cannot answer cross-domain questions.
The second is a structured technical ontology. Raw vector search across heterogeneous technical documents produces noisy results because the same concept is described differently in patents, papers, and product literature. A purpose-built R&D ontology encodes the relationships between technical concepts, materials, mechanisms, and applications, so a semantic query for, say, sulfide solid electrolytes returns the relevant evidence regardless of whether a given document uses that exact phrase. Ontology quality is one of the most important and least visible differentiators in this category.
The third is agentic workflow support. A search box returns documents. A platform produces deliverables. Modern AI patent and paper intelligence platforms include agentic systems that can run multi-step research workflows, retrieve evidence across the corpus, synthesize findings, and produce structured reports such as landscape analyses, white space maps, and competitor profiles. These workflows are what allow a small R&D intelligence team to support a large innovation organization.
The fourth is enterprise-grade infrastructure. Corporate R&D intelligence touches sensitive competitive information, regulated industries, and confidential project context. A platform suitable for Fortune 500 deployment must offer enterprise-grade security that meets Fortune 500 requirements, role-based access controls, audit logging, and data handling guarantees that consumer or free tools do not provide.
The fifth is configurability. Different R&D programs need different views of the world. A platform allows users to configure custom corpuses of patent and non-patent literature scoped to a technology domain, a competitor set, or a strategic initiative. This corpus configuration capability is directly tied to recent research on context engineering, which has shown that focusing a language model on the relevant subset of data, rather than the entire web, materially improves the quality of generated analysis [3].
The Role of AI in the Category
The AI in AI patent and paper intelligence platforms is not a single feature. It is a layered architecture, and the quality of each layer compounds.
At the retrieval layer, semantic embedding models convert technical documents into vector representations that capture meaning rather than surface text. A well-implemented retrieval system surfaces a relevant patent about lithium polymer electrolytes even when the user query uses different terminology, because the underlying concepts are close in embedding space. Retrieval quality on technical content is highly sensitive to the embedding model used, the ontology applied on top, and the cleanliness of the underlying corpus.
At the reasoning layer, large language models perform synthesis, comparison, and extraction over retrieved evidence. The frontier models available in 2026, including the Claude 4 series, GPT-5.1, and the o-series reasoning models, have substantially improved on technical comprehension, structured output, and citation behavior compared to the models available even eighteen months ago. Platforms that have integrated official enterprise partnerships with these model providers have access to the strongest available reasoning, with the data handling and privacy guarantees enterprise buyers require.
At the agent layer, orchestrators chain retrieval and reasoning steps together to perform end-to-end workflows. An agent tasked with producing a competitive landscape on a technology domain might iterate across the corpus, identify the leading assignees, retrieve their representative patents and publications, summarize each one, build a comparison matrix, and produce a written report with citations. Recent research on agentic context compression suggests that models perform better when given concise, well-structured claims rather than dense source material, which is why high-quality ingestion and ontology work matters even more in the agent era [4].
The combination of retrieval, reasoning, and agent layers is what allows a modern platform to take a question such as what is the competitive position of company X in solid-state batteries, and return a structured answer in minutes rather than weeks of analyst time.
Use Cases That Justify the Category
The use cases that justify investment in an AI patent and paper intelligence platform are the ones where speed and breadth matter more than legal precision. These are not patent attorney workflows. They are R&D and strategy workflows.
Technology scouting is one of the clearest examples. When an innovation team needs to identify emerging approaches to a problem, the relevant evidence is spread across patent filings, recent papers, startup disclosures, and grant awards. A unified AI platform allows a scout to surface candidates across all these sources, cluster them by approach, and produce a shortlist in days rather than months.
Competitive landscape analysis is another. Understanding a competitor's technical trajectory requires reading across their patent portfolio and their scientific publications, then identifying where the two diverge from public product disclosures. Platforms with agentic synthesis can produce competitor profiles that integrate all three signals.
White space and opportunity mapping benefits especially from cross-source intelligence. The most interesting technical opportunities are often the gaps between heavy patent activity and heavy publication activity, or the spaces where academic momentum is building but commercial filings have not yet appeared. These patterns are invisible inside a single-source tool.
Freedom to operate at the R&D stage is also increasingly handled with AI patent and paper intelligence platforms, although final legal opinions still belong with patent counsel. Early-stage FTO scans performed in-house by R&D teams help engineering leaders make build versus pivot decisions before legal hours are spent.
Continuous monitoring rounds out the use case set. Once a corpus is configured for a strategic area, agents can surface new patents and papers as they appear, summarize their relevance, and route them to the right internal stakeholders. This converts patent and paper intelligence from a periodic study into an ongoing capability.
Evaluation Criteria for Enterprise R&D Buyers
R&D directors and innovation leaders evaluating platforms in this category should weigh several criteria that map to the structural definitions above.
Corpus coverage is the first. The platform should integrate patent data from all major jurisdictions, scientific literature from peer-reviewed and preprint sources, and ideally additional technical signals such as grants, clinical trials, and regulatory filings. Total document counts matter, but freshness, completeness of metadata, and coverage of non-English sources matter more.
Semantic search quality is the second. The most reliable way to evaluate this is to run real queries from the buyer's own technical domain and inspect the top results. Embedding quality and ontology quality are difficult to assess from marketing materials alone.
Agent and report quality is the third. A platform that produces a clean landscape report with proper citations and a defensible structure delivers materially more value than one that returns a chat answer. Buyers should ask vendors to run an agent task on a sample domain during evaluation.
Enterprise infrastructure is the fourth. Security posture, data handling commitments, single sign-on, audit logging, and the ability to meet Fortune 500 procurement requirements should be confirmed early. Tools that cannot pass enterprise security review will stall regardless of search quality.
Audience fit is the fifth. A platform built for patent attorneys typically defaults to legal workflows and terminology that R&D users find friction-laden. A platform built for R&D scientists and innovation strategists defaults to the language and outputs those users need. The mismatch is rarely fixable through training.
Configurability is the sixth. The ability to define custom corpuses, save them, share them across teams, and route updates from them is what turns a search platform into a research function.
Pricing structure is the final criterion. Enterprise platforms in this category are priced for sustained organizational use, not per-search consumption. Buyers should map the expected number of seats, the breadth of teams using the platform, and the report and monitoring volumes against the proposed contract.
Where the Category Is Going
The trajectory of AI patent and paper intelligence platforms over the next eighteen months follows the broader trajectory of enterprise AI. Three shifts are already visible.
The first is deeper agent integration. Platforms are moving from question-answering toward autonomous research workflows where an agent runs for minutes or hours and returns a finished deliverable. This compresses the work cycle for R&D intelligence functions and makes ambitious use cases such as cross-portfolio monitoring practical for teams that previously could not staff them.
The second is custom corpus standardization. The recognition that focusing models on the right subset of data improves output is reshaping product design. Configurable corpuses scoped to a technology, a competitor set, or a project are becoming the default rather than the exception, in line with the broader move toward context engineering in applied AI [3].
The third is enterprise model partnerships. Platforms with official enterprise API partnerships with the leading model providers, including OpenAI, Anthropic, and Google, have a structural advantage in both capability and compliance. Frontier models change frequently, and the platforms wired into the official enterprise pipelines benefit from each new release without renegotiating data handling terms.
The net effect is that AI patent and paper intelligence platforms are evolving from search experiences into research infrastructure. The buyers who treat them as the latter, rather than as a faster keyword search, will extract the most value.
A Note on Cypris
Cypris is an enterprise R&D intelligence platform built specifically for the use cases described above. The platform unifies more than 500 million patents and scientific papers into a single corpus accessible through semantic search and agentic workflows, with a proprietary R&D ontology designed to understand the relationships between technical concepts across patents and literature. Cypris holds official enterprise API partnerships with OpenAI, Anthropic, and Google, allowing the platform to deliver frontier model capabilities under enterprise data handling terms. Cypris Q, the platform's AI agent and report-generation layer, produces structured landscape analyses, competitor profiles, and white space maps that R&D teams use as primary deliverables rather than supporting research. The platform supports configurable custom corpuses of patent and non-patent literature, allowing organizations to focus their intelligence work on the technology domains, competitor sets, and strategic initiatives that matter to them. Cypris is built for R&D scientists and innovation strategists rather than IP attorneys, and is trusted by hundreds of enterprise customers and Fortune 500 R&D teams operating in regulated, security-conscious environments.
Most large R&D organizations now run some form of tech scouting. The shape varies enormously. A few companies have a dedicated technology scout sitting in the CTO's office producing quarterly horizon reports. More common is an innovation team that runs scouting sprints around specific themes when leadership asks for one. Increasingly common is some form of AI-assisted scouting workflow — a set of saved searches at the simple end, an agentic monitoring system at the more sophisticated end. The output quality across these approaches differs by an order of magnitude, and the most consequential variable separating the strong versions from the weak ones is not which AI model is underneath. It is how the scouting agent has been designed.
This guide is for innovation leaders, CTOs, R&D directors, BD and partnership teams, and corporate venture groups who want tech scouting to function as a continuous capability rather than a periodic deliverable. It explains what a tech scouting agent actually is, why agents that surface real intelligence look different from agents that produce volume, and how to design a scouting workflow that compounds value over time rather than restarting from zero every quarter.
What Tech Scouting Actually Has to Cover
Tech scouting is a forward-looking workflow. The question is not what the established competitive landscape looks like today; the question is what is emerging that the company should know about, where, and why does it matter to the strategy. That framing changes everything about how the work has to be done.
Scouting answers a small number of recurring questions. What new technologies are gaining momentum in areas adjacent to where we play? Which startups are forming around technical approaches that could disrupt our roadmap, and which could we partner with or acquire? Which research groups are producing work that will become commercially significant in three to five years, and what would it take to engage them? Which capabilities should we be building internally versus sourcing externally? Which competitors are quietly building positions in spaces we have not yet committed to? These questions do not have one-time answers. The answer this quarter and the answer next quarter are different, and the difference is precisely the signal the scouting workflow exists to capture.
The evidence base for these questions is messy and multi-source by nature. Scientific publications and preprints carry the earliest signal of where research is heading. Patent filings carry a slightly later but more strategically committed signal of where companies and inventors are placing technical bets. Startup formations, funding rounds, and corporate venture activity reveal where capital is moving and which technical theses sophisticated investors are willing to back. Government grants, program awards, and procurement filings flag where strategic priorities and non-dilutive funding are concentrating. Conference proceedings, technical talks, hiring patterns, regulatory filings, and the surrounding signal in trade press and industry analyst coverage round out the picture. Each source carries a different slice of the truth. None of them is sufficient on its own.
The implication is that a scouting agent watching one source — even a comprehensive one — produces a partial view. The signal that matters in scouting is usually cross-source. When a research group publishes three papers on a novel approach over eighteen months, when one of those authors leaves their academic position, when a small entity forms with a credible founding team and raises seed capital, when a corporate venture arm participates in the round, when an early grant award appears for the same research direction — none of those events is decisive on its own. Together, they are an emergence signal worth a senior leader's attention. An agent that sees only one source misses most of the picture. The intelligence is in the connection.
This is the workflow that older tools were not built for. Most legacy systems organize the world by source — a startup database here, a literature index there, a patent tool somewhere else, with the connections drawn by an analyst pivoting between tabs. The connection is the work. Doing that work continuously, across thousands of emergence events per week, in dozens of technology and business areas, is not a workload a team of human scouts can sustain. It is the workload tech scouting agents exist to absorb.
What a Tech Scouting Agent Actually Does
Most R&D and innovation organizations that say they have a tech scouting capability today are running a combination of saved Google Alerts, periodic searches in different databases, conference attendance, broker calls, and read-throughs of analyst reports. The work is real but episodic. Someone reads the alerts. Someone summarizes the conference. Someone reviews the analyst report. The interpretive work happens in a person's head, the institutional memory fades when they move on, and the next person to ask the same scouting question starts from a blank page.
A tech scouting agent inverts this pattern. The agent runs a defined scouting thesis continuously across the relevant evidence corpus, evaluates each new signal against the thesis using interpretive reasoning rather than keyword matching, dismisses what does not warrant attention, and escalates what does with a written rationale that explains why. The interpretive work moves from a person's head into a system that runs every day, applies consistent criteria, and produces a record the team can audit and refine.
Four functions distinguish a real scouting agent from a saved search with notifications.
It applies a strategic thesis rather than a query. Instead of matching documents against a Boolean string or a vector similarity threshold, the agent evaluates each new signal against a structured description of what the team is trying to learn and why. The thesis is interpretive, not lexical, which means the agent can recognize relevant signals even when the underlying language differs from how the team would have phrased a search.
It runs continuously, not on user-initiated demand. New papers, preprints, patent filings, funding announcements, grant awards, regulatory filings, and corporate disclosures arrive as a continuous stream. An agent designed for scouting evaluates this stream as it arrives, which eliminates the gap between when a relevant signal enters the world and when the team learns about it.
It filters for signal, not match. Most saved searches return high false-positive rates because the keywords appear in unrelated contexts, or because the technical match is real but the strategic relevance is low. An agent reads each candidate signal, evaluates it against the thesis, and discards what does not pass the relevance bar. The result is a substantially smaller and higher-quality escalation queue.
It produces a written rationale. When the agent escalates a signal, it explains why — what about the disclosure matched the thesis, how it relates to prior signals the agent has already evaluated, and what decision or downstream workflow it might inform. This rationale becomes a record the team can audit. When the agent gets it wrong, the team can see where the reasoning broke and refine the thesis. When the agent gets it right, the rationale accelerates the human follow-up because the framing is already done.
These four functions are what transform scouting from a notification system into an analytical process that compounds.
The Four Components of a Strong Scouting Thesis
The thesis is the most important input to a tech scouting agent. The quality of the thesis sets the ceiling on the quality of the output, regardless of which platform or model sits underneath. Most weak scouting output traces back to a thesis that was too short to support real work — a few sentences naming a technology area, with no specification of what would make a finding meaningful or how the team would use it.
There is a useful piece of recent prompt engineering research that bears on this directly. The discipline reorganized through 2025 around what researchers and frontier AI labs now call context engineering — the recognition that for serious knowledge work, the ceiling on output quality is set less by how a prompt is phrased and more by what information the system has been given to reason over. Andrej Karpathy described context engineering as the practice of populating the model's working context with precisely the right information for the task. Research on agentic systems published through late 2025 documented what researchers describe as brevity bias — the tendency of prompt optimization to favor concise instructions, which sounds appealing but causes the omission of domain-specific detail that actually drives output quality on knowledge-intensive tasks. The translation for tech scouting is that strong scouting theses are tight on filler but rich on domain specification. They are not short.
A well-framed scouting thesis has four components.
The strategic envelope. State why the scouting is being done and which business decisions it is meant to inform. A thesis written to support open innovation and partnership identification is different from a thesis written to support corporate venture screening, and both are different from a thesis written to support technology emergence monitoring for an executive committee or M&A target identification for corporate development. The agent can calibrate its evaluation criteria to the decision the scouting supports — but only when the decision is explicitly named. A scouting workflow without a named decision tends to escalate everything that looks interesting, which is functionally the same as escalating nothing.
The technical and market scope. Describe the technologies, capabilities, applications, and market segments of interest in specific terms. Name the methods, performance thresholds, end-use cases, and customer segments that are in scope. Name what is explicitly out of scope — the adjacent areas the team does not want the agent pulled into. List terminology variants the field uses for the same concept, particularly where industry vocabulary differs from academic vocabulary, and where new terminology has begun to displace older usage. The scope is what allows the agent to recognize relevance accurately at the edges, where most genuine emergence signals live.
The evidence priorities. State which sources of evidence matter most for this scouting question and why. For some theses, scientific publications are the leading indicator — emerging technical approaches typically appear in academic literature six to eighteen months before they reach commercial products. For other theses, startup formations and funding events are the earliest signal of where capital and talent are converging. For still others, government grant awards or regulatory filings reveal emergence first. The agent's evaluation logic depends on understanding which source carries the leading signal for the specific question, and how to weight signals from different sources when they appear together. Without this specification, the agent treats all sources as equally informative, which is rarely true.
The escalation criteria. Specify what makes a finding worth surfacing. A new initiative from a primary competitor likely warrants escalation regardless of how strong the technical match is. A scientific publication from an unknown research group likely warrants escalation only when the technical signal is strong and other independent signals point in the same direction. A startup formation likely warrants escalation only when the team behind it has a credible technical pedigree and the funding source signals strategic intent rather than seed-stage exploration. The criteria need to be explicit so the agent can apply them consistently and the team can tune them as the thesis evolves.
The discipline of writing a thesis with these four components is itself valuable. It forces the team to articulate what they are actually trying to learn, why it matters to the business, and how they would recognize a useful answer when they saw one. Teams that adopt this framing pattern tend to find that the thesis-writing exercise improves their scouting work even before any agent is run against it.
What to Watch For When Designing Scouting Agents
Three failure modes appear repeatedly in tech scouting agent deployments, and each is a design problem rather than a model problem.
The first is theses that are too broad, which produce escalation queues so large the team stops reading them. A scouting agent that escalates fifty findings a week will be functionally abandoned within a month. The remedy is rarely to make the agent more selective in isolation — it is to narrow the thesis itself, focus on the specific decisions the scouting supports, and tune the escalation criteria upward until what arrives is genuinely worth the team's time. A useful test is whether the team would feel a real loss if the scouting output stopped arriving. If the answer is no, the thesis needs to be sharper.
The second is single-source agents — scouting workflows that watch only one type of evidence, whether that is news, papers, patents, or startup data. The genuine emergence signals in tech scouting almost always show up across multiple sources, in a particular sequence, over a particular time window. An agent that sees one source can detect that something is happening but cannot evaluate whether the something is meaningful. A multi-source agent can recognize when a paper, a hire, a startup formation, and a funding round all point in the same direction, which is a fundamentally different category of intelligence than any one signal in isolation.
The third is scouting agents that are not connected to a downstream decision process. An agent that produces a weekly digest read by no one, or a digest whose findings never enter Stage-Gate reviews, partnership evaluations, M&A pipelines, or executive briefings, produces no operational value regardless of how good the underlying analysis is. The scouting workflow needs to terminate in a decision interface — a project workspace, a portfolio review, a CTO briefing, a venture screening pipeline, a corporate development tracker — where the findings can actually act on the business. A scouting agent without a downstream destination is an interesting demo, not a capability.
The Evidence Corpus Question
Here is where most tech scouting deployments hit their ceiling, often without realizing it.
A tech scouting agent's reasoning quality is bounded by what the agent is reasoning over. A general-purpose AI tool is reasoning over its training data, which is a partial and outdated slice of any specialized field. A scouting workflow built on a single-source database is reasoning over only that source. Both architectures impose ceilings on output quality that no amount of prompt refinement will fully lift.
This is the structural reason purpose-built R&D intelligence platforms produce different output than general-purpose AI tools or single-source legacy systems for scouting work. The strongest platforms maintain a unified corpus that combines scientific literature, patents, and adjacent technical and market signal in a single index, and allow scouting agents to reason across that combined corpus rather than against any one slice of it. Cross-source reasoning — recognizing that a paper, a patent, a funding event, and a hire all point in the same direction — only works when the agent has access to all of those signals in a structure that lets it connect them.
The strongest platforms go further and allow teams to configure custom corpuses focused on specific scouting theses. A custom corpus narrows the working evidence base to what is actually relevant for the question at hand, which lets the agent's reasoning operate on signal rather than fight through noise. A general index covers everything across all technology areas, and the signal that matters for a specific scouting thesis is buried in a much larger volume of irrelevant material. Even strong AI reasoning struggles to consistently find and weight the right evidence at that ratio. A focused corpus, scoped to the technical and strategic envelope of the thesis, produces meaningfully better scouting output than the same agent run against a general index.
Custom corpus configuration matters more for scouting than for most adjacent workflows. A landscape question is bounded — the scope is defined, the deliverable is a snapshot, and the corpus that supports it can be constructed once. A scouting question is open-ended — the scope evolves as the field evolves, the deliverable is continuous, and the corpus needs to evolve alongside the thesis. Platforms that treat custom corpus configuration as a first-class capability rather than an advanced feature are the ones where scouting workflows continue producing useful output six and twelve months in.
Where Cypris Fits
Cypris is an enterprise R&D intelligence platform built for this category of work. The platform unifies more than 500 million patents and scientific papers in a single corpus, applies a proprietary R&D ontology developed for the language of corporate research and innovation work, and provides agentic workflows that R&D, innovation, and corporate development teams configure to run continuous scouting against defined theses. Cypris maintains official API partnerships with OpenAI, Anthropic, and Google, which means the agentic reasoning sitting underneath the platform is built on frontier models accessed through enterprise contracts rather than scraped or rate-limited public APIs, with enterprise-grade security architecture that meets Fortune 500 requirements.
The capability that matters most for the scouting workflow described in this guide is the combination of unified corpus, custom corpus configuration, and agentic execution. A scouting team using Cypris can encode a strategic thesis, configure a focused corpus scoped to the technical and market envelope of that thesis, and run an agent against it continuously. The agent applies the team's escalation criteria, surfaces findings with written rationale, and integrates the output into the team's downstream R&D and corporate development processes. The architecture was designed from the ground up around the workflow needs of R&D scientists, innovation strategists, and corporate development teams rather than IP attorneys running discrete search engagements, which is reflected throughout the system in how scouting is structured, how findings are presented, and how the human-in-the-loop refinement of the thesis works in practice.
For an innovation team mapping a specific emerging technology space, this means the agent is reasoning over the research and technical signal actually relevant to that space, recognizing emergence patterns across sources, and surfacing findings the team would not have caught running periodic searches against a general index. For a corporate venture team screening a category of startups, the corpus can be configured around the technical area the venture thesis covers, and the agent can monitor for new entrants, technical pivots, and competitive activity continuously. For a corporate development team identifying M&A targets, the corpus can be configured around the capability gaps the strategy is trying to close, and the agent can surface companies whose technical and commercial trajectory aligns with the thesis. For a CTO running a horizon-monitoring program, the platform can support multiple parallel scouting theses, each with its own corpus, agent, and escalation logic, and integrate the combined output into the executive briefing cadence the CTO actually runs.
The combination — a unified research and technical corpus, custom corpus configuration scoped to specific theses, agentic execution against frontier reasoning models, and integration with the workflows R&D and innovation teams already run — is what separates scouting output that supports executive decisions from scouting output that summarizes what an analyst happened to read this week. Hundreds of Fortune 500 R&D and innovation organizations rely on the platform for exactly this category of work.
What Your Team Can Do This Quarter
Three things will measurably improve the tech scouting your team produces, regardless of which platform you use.
Standardize how scouting theses are written, with the four components described above — strategic envelope, technical and market scope, evidence priorities, and escalation criteria. A simple template that asks each scout to fill in these four sections before any agent runs against the thesis produces noticeably better output across the board. The discipline of writing a thesis to this standard is itself a quality lever, because it forces explicit articulation of what would otherwise stay implicit.
Establish a quality standard for what defensible scouting output looks like. The output a scouting agent produces should be grounded in specific citable signals — named entities, paper or patent identifiers, concrete dates, specific funding events — rather than vague references to activity in a space. It should distinguish between what the evidence shows and what the evidence suggests. It should calibrate its confidence by saying where the signal is thick and where it is thin. It should explicitly identify the assumptions and scope choices the conclusions depend on. Output that does not meet this standard does not get put in front of executives, regardless of which platform produced it.
Evaluate whether your current scouting toolkit supports continuous agentic execution against a unified, configurable corpus. If it does not — if the team is running periodic searches against single-source databases and synthesizing the output by hand — you are leaving substantial scouting capability on the table. Any platform evaluation you run should put unified corpus coverage, custom corpus configuration, and agentic workflow architecture near the top of the criteria list, ahead of search interface aesthetics or specific dashboard features.
The teams getting the most value from AI in tech scouting are not the teams with the most clever prompts or the highest tool budgets. They are the teams that have framed their scouting theses well, set quality standards their output has to meet, and chosen tools that let agents run continuously against the evidence base that matters for the decisions the scouting supports.
Frequently Asked Questions
What is a tech scouting agent?A tech scouting agent is an AI system that runs a defined technology scouting thesis continuously across a multi-source evidence corpus, evaluates new signals against the thesis using interpretive reasoning, and escalates findings worth human attention with a written rationale explaining why. It differs from a saved search with notifications in that it applies strategic interpretation rather than keyword matching, runs continuously rather than on user-initiated demand, filters for signal rather than lexical match, and produces auditable reasoning rather than document lists. Tech scouting agents are most valuable for R&D, innovation, corporate venture, and corporate development teams that need continuous awareness of emerging technologies, startups, research, and capabilities rather than periodic snapshots.
What kinds of decisions does a tech scouting agent support?Tech scouting agents support a recurring set of decisions: which technologies to monitor for strategic relevance, which research groups and inventors to engage for partnerships, which startups to evaluate for licensing, investment, or acquisition, which capability gaps to close internally versus source externally, and which competitive moves to track in spaces the company has not yet committed to. Each of these decisions has a different evidence priority and escalation criterion, which is why the strategic envelope of the scouting thesis matters as much as the technical scope.
What should a tech scouting thesis include?A strong tech scouting thesis has four components: the strategic envelope (why the scouting is being done and what business decisions it informs), the technical and market scope (what technologies, capabilities, and segments are in scope and what is explicitly out of scope, with terminology variants specified), the evidence priorities (which sources carry the leading signal for this question and how signals from different sources should be weighted when they appear together), and the escalation criteria (what makes a finding worth surfacing to the team). Theses missing one or more of these components tend to produce scouting output that is either too noisy to use or too narrow to capture genuine emergence.
Why does the evidence corpus matter so much for tech scouting?The corpus the scouting agent reasons over sets the ceiling on what the agent can recognize. A general-purpose AI tool reasons over its training data, which is partial and outdated for most specialized fields. A single-source database limits the agent to the signal carried in that source, missing cross-source emergence patterns. A unified, configurable corpus lets the agent reason across the full evidence base relevant to a specific thesis, which is where genuine scouting intelligence comes from. The recent shift in prompt engineering toward what researchers call context engineering reinforces this point: for serious knowledge work, the body of evidence the AI has access to matters more than the cleverness of the prompt.
What does cross-source reasoning mean in tech scouting?Cross-source reasoning is the recognition that genuine emergence signals usually appear in a particular sequence across multiple sources — papers, patents, hires, startup formations, funding events, grants, regulatory filings — rather than in any one source in isolation. A tech scouting agent capable of cross-source reasoning can identify when a research group's papers, a key author's job change, a new startup's formation, and a corporate venture investment all point in the same direction, which is a substantially stronger signal than any one of those events alone. Single-source agents cannot perform this analysis; multi-source agents can, but only when the underlying corpus is structured to support the connections.
How often should a tech scouting agent run?For most R&D, innovation, and corporate development applications, daily execution is appropriate, because new research, funding announcements, and corporate disclosures arrive continuously and the value of scouting is partly its currency. Weekly cadence is sometimes adequate for slower-moving technology domains, but the marginal cost of running an agent daily versus weekly is low, and the latency benefit is meaningful when the scouting informs time-sensitive decisions like partnership negotiations, investment rounds, or competitive responses.
What are the most common failure modes of tech scouting agents?Three failure modes appear repeatedly. The first is theses that are too broad, producing escalation queues so large the team stops reading them. The second is single-source agents that watch only one type of evidence, missing cross-source emergence patterns that constitute most genuine scouting signal. The third is scouting agents disconnected from downstream decision processes, where the output never reaches Stage-Gate reviews, partnership evaluations, M&A pipelines, or executive briefings that could act on it. Each is a design problem rather than a model problem.
Do general-purpose AI tools work for tech scouting?General-purpose AI tools can produce scouting-shaped output but rarely scouting-quality output for specialized R&D and innovation fields. The model is reasoning from whatever research, technical, and market data happened to be in its training data, which is a partial and outdated slice for most domains. The output sounds confident but the underlying evidence is often missing, generic, or wrong. For scouting workflows that inform R&D investment, partnership, corporate venture, or M&A decisions, purpose-built R&D intelligence platforms with current, comprehensive corpuses produce substantially more reliable output.
How do tech scouting agents integrate with downstream decision processes?A scouting agent's output is only valuable when it connects to a decision the organization is actually making. The integration usually takes one of three forms: routing escalated findings into project workspaces where program leads can act on them, feeding scouting output into Stage-Gate reviews, partnership evaluations, M&A pipelines, or portfolio decisions on a defined cadence, or producing structured executive briefings for technology committees and corporate venture boards. Scouting workflows that terminate in an inbox produce no operational value; scouting workflows that terminate in a decision produce compounding value over time.
What separates an enterprise R&D intelligence platform from a general AI tool for scouting work?Enterprise R&D intelligence platforms maintain unified corpuses that combine scientific literature, patents, and adjacent technical and market signal, support custom corpus configuration scoped to specific scouting theses, run agentic workflows continuously rather than on user-initiated demand, apply domain-specific ontologies trained on the language of technical research and innovation, and integrate with the downstream R&D and corporate development processes where scouting findings need to reach decisions. General AI tools provide reasoning capability but lack the corpus, the configurability, and the workflow integration that scouting at enterprise scale requires.
Citations
- Chesbrough, H. Open Innovation: The New Imperative for Creating and Profiting from Technology. Harvard Business School Press, 2003.
- Ansoff, H.I. "Managing Strategic Surprise by Response to Weak Signals." California Management Review, 1975.
- Karpathy, A. Public commentary on context engineering as the practice of populating model working context with precisely the right information for the task, 2025.
- Research on agentic context engineering and brevity bias in prompt optimization for knowledge-intensive tasks, 2025.
- Cypris platform documentation on unified research corpus, custom corpus configuration, and agentic scouting workflows.