Insights on Innovation, R&D, and IP
Perspectives on patents, scientific research, emerging technologies, and the strategies shaping modern R&D
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
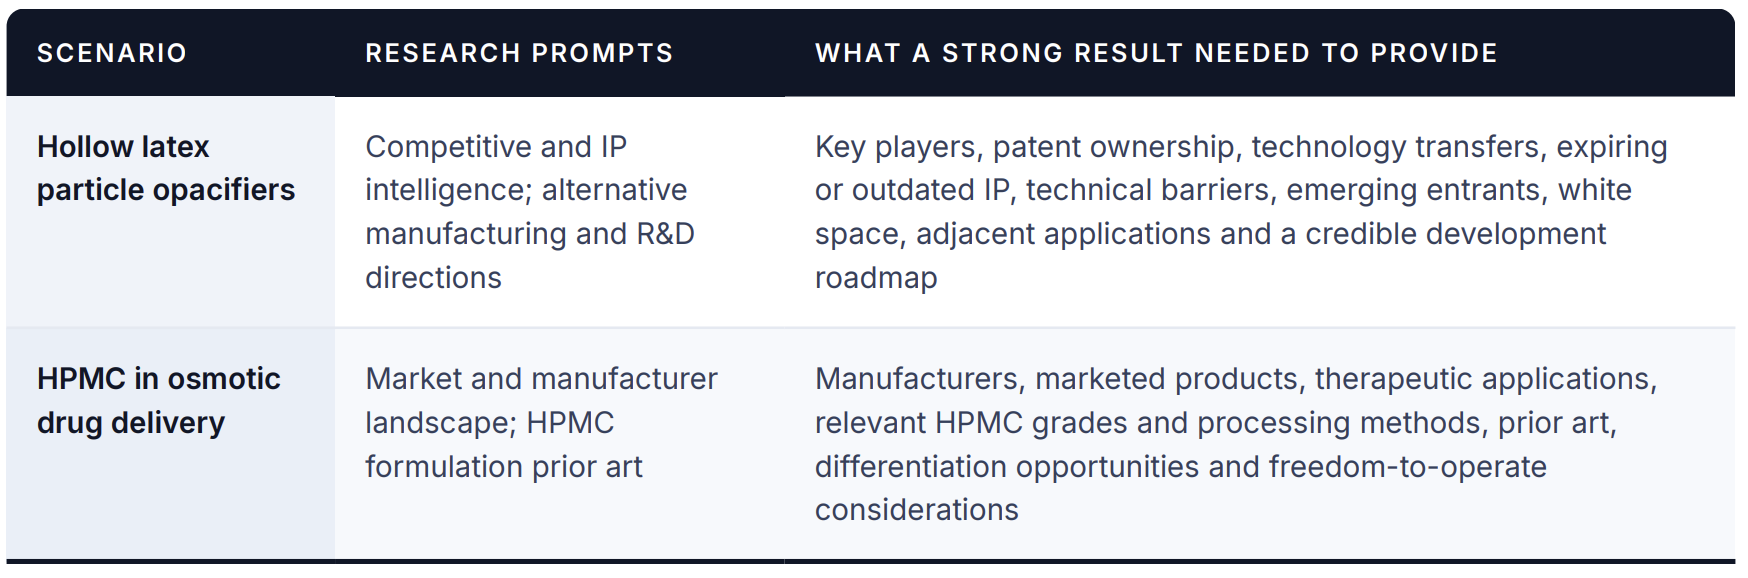
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
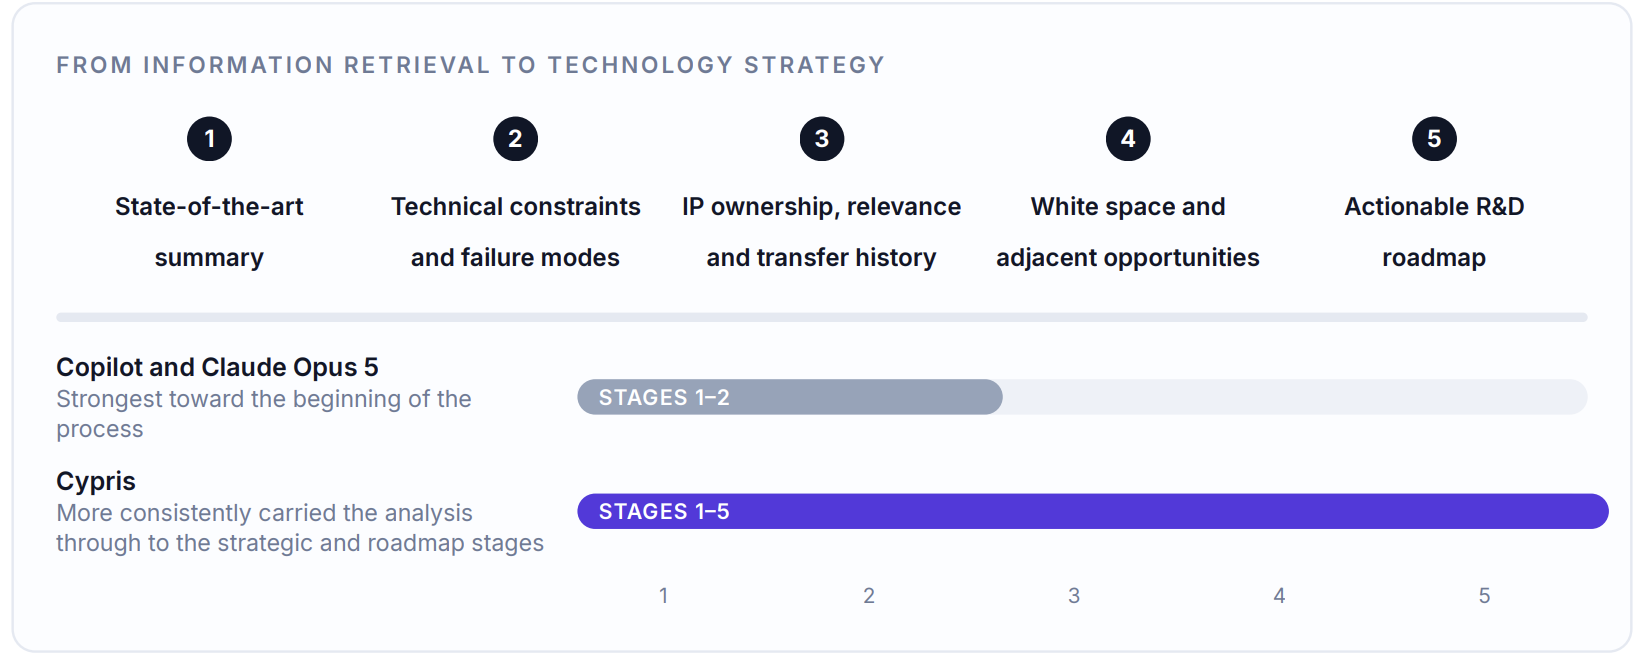
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
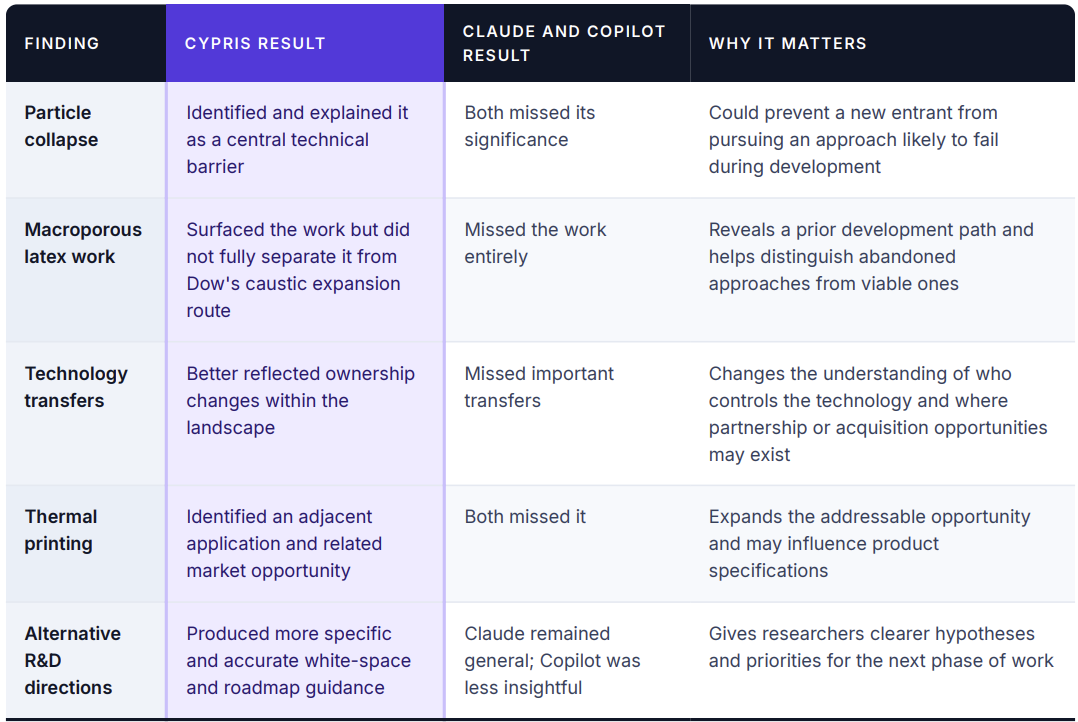
Comparative findings at a glance
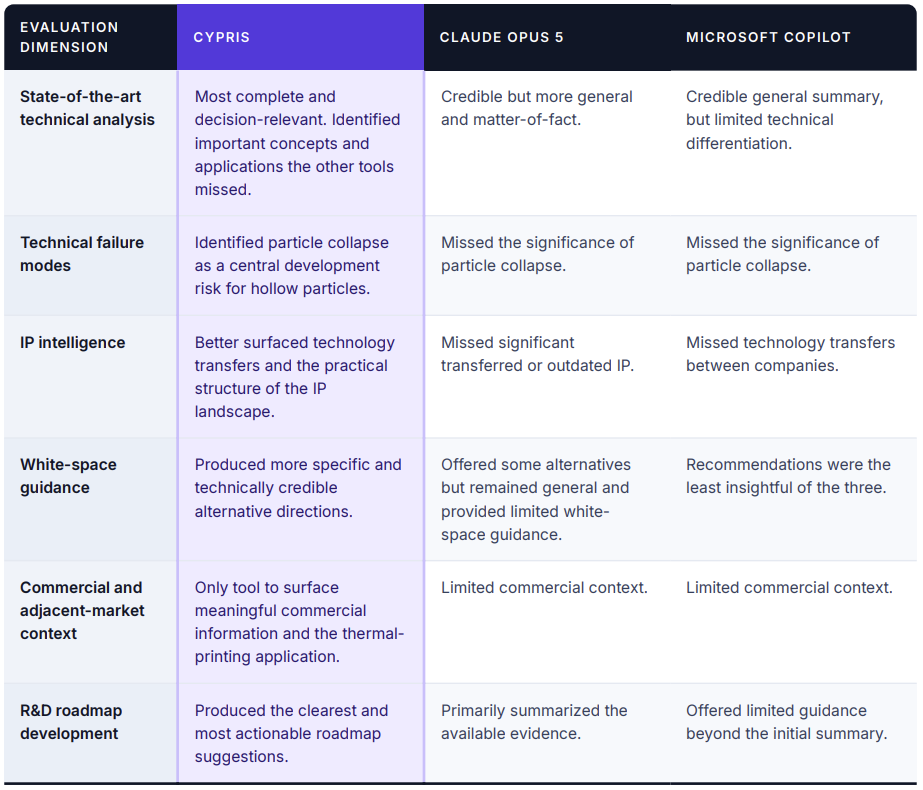
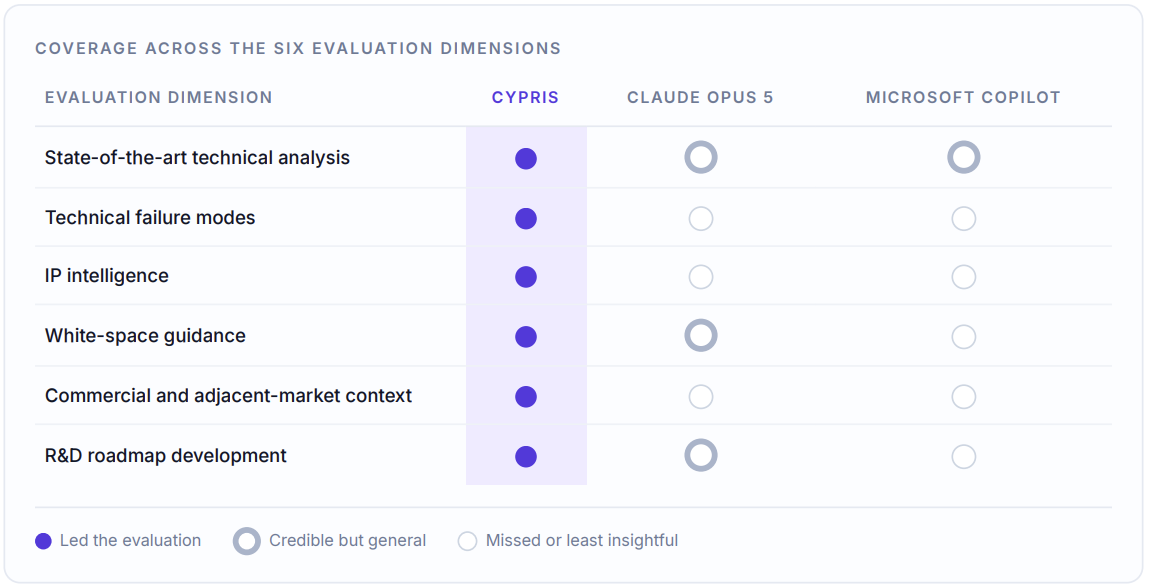
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
Former Dow Research Fellow Compares Cypris, Copilot & Claude for Chemical Intelligence
All Blogs

AI-driven patent scouting is the systematic use of artificial intelligence to monitor patents and scientific literature for early signals about where a technology field is heading. It differs from a one-time patent search. Patent scouting is continuous. It tracks new filings, emerging assignees, and shifting claim language across a technology area over months and years, and it feeds those signals into product and R&D decisions.
Patents are filed years before products reach the market, which is what makes scouting valuable. In pharmaceuticals, industry analyses indicate that composition-of-matter patents are typically filed roughly a decade before regulatory approval, with formulation and dosing patents following as a candidate moves through clinical development.1 A scouting program that reads this sequence sees a program's trajectory years before launch. Long-term product development commits budget and headcount on the same horizon, so early patent signal directly reduces the uncertainty in those bets.
This article explains what AI-driven patent scouting is, how it works, where it creates strategic value in product development, and how to run it as an ongoing process rather than a single report.
What patent scouting is
Patent scouting is the ongoing surveillance of a defined technology area to identify relevant patents, applicants, and technical trends. A scouting program defines the technology scope, monitors new patent filings and scientific publications in that scope, and reports material changes to the people making product decisions.
Patent scouting answers different questions than a freedom-to-operate (FTO) search or a prior art search. An FTO search asks whether commercializing a specific product would infringe active patent claims. A prior art search asks whether a specific invention is novel. Patent scouting asks a broader question: where is this field going, and who is moving there first. All three draw on the same underlying corpus of patents and scientific literature, but scouting is continuous and strategic rather than transactional.
Why filing activity is a leading indicator
Patent filing precedes commercial products by a measurable margin, so filing trends indicate where investment is concentrating before it reaches the market. In pharmaceuticals, the composition-to-formulation-to-dosing filing sequence maps to a candidate's progress through development, and the earliest filings appear years before a product is approved. Rising filing activity in a technology area, especially when it concentrates among established players, signals that investment is committing to an approach before the market confirms it.
A structural detail makes early scouting essential. There is a lag of roughly 18 months between when a patent is filed and when it publishes, which means disclosed research is already more than a year old when it first becomes visible. Scouting that runs continuously captures each signal as early as the publication system allows, rather than discovering it later in a periodic review.
Where patent scouting creates strategic value in product development
Direction-setting. Patent scouting shows which technical approaches are attracting investment before those approaches reach the market. A rising concentration of patents around a specific method signals that multiple organizations are committing R&D resources to it. Product teams use this to prioritize research directions with more evidence and less guesswork.
Competitive positioning. Scouting identifies which organizations are filing in a technology area and how their claim language is evolving. This reveals where competitors intend to build, which lets a product team either differentiate around protected positions or move faster in a still-open direction.
Risk reduction. Continuous scouting surfaces patents that could constrain a planned product early enough to change course cheaply. The cost asymmetry is large. Industry guides estimate that a preliminary freedom-to-operate analysis costs on the order of $10,000, rising above $100,000 for a comprehensive global one,2 while patent litigation and damages can range from several hundred thousand to hundreds of millions of dollars.3 NTP's suit against the maker of BlackBerry settled for $612.5 million in 2006 and nearly shut down the product's U.S. service.4 Discovering a blocking patent during scouting, years before launch, is far cheaper than discovering it after a design freeze or in litigation.
White space identification. Scouting maps where patents and scientific research cluster, and by extension where they do not. Sparsely patented technical territory can indicate an opening, though sparse patenting alone is not proof of a viable market. White space analysis is most reliable when patent data is read alongside scientific literature and commercial signals, not in isolation.
Portfolio and licensing strategy. Long-running scouting builds an evidence base for where to file, what to license, and which programs to sustain or retire. It connects the patent landscape to the R&D roadmap so that IP strategy and product strategy stay aligned.
How AI changes patent scouting
Traditional patent scouting relied on keyword queries and manual review. Keyword queries miss filings that describe the same concept in different terms, and manual review does not scale to the millions of patents and papers published each year.
AI-driven patent scouting changes this in three ways. First, semantic search retrieves documents by technical meaning rather than exact keyword match, so a scouting query surfaces relevant patents regardless of the specific terminology an applicant used. Second, an R&D ontology organizes patents and scientific literature into a structured map of technologies, so scouting operates on concepts and their relationships rather than on isolated search strings. Third, agentic workflows run the monitoring continuously, re-checking a defined technology area on a schedule and surfacing what changed since the last cycle. Together these let a scouting program cover a full technology field across patents and scientific research, not a keyword slice of it.
How to run AI-driven patent scouting as a process
- Define the technology scope. State the technical area in terms of the problems being solved and the approaches in use, not only keywords. A concept-level scope captures filings that use varied terminology.
- Establish a baseline. Run an initial semantic search across patents and scientific literature to map current filings, active applicants, and claim trends in scope.
- Set up continuous monitoring. Configure agentic monitoring to re-run the scouting scope on a schedule and report new filings, new entrants, and shifts in claim language since the previous cycle.
- Route signals to decisions. Deliver scouting output to the product and R&D owners who set roadmap priorities, so that new signals change decisions rather than sitting in a report.
- Review and refine scope. Update the technology scope as the field and the product strategy evolve, so scouting stays aligned with the current roadmap.
Where Cypris fits
Cypris is an AI-native R&D intelligence platform built for patent scouting and long-term technology strategy. Cypris runs semantic search across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology that maps technologies and their relationships rather than treating documents as isolated keyword hits. This lets a scouting program operate at the level of a technology field rather than a search string.
Cypris Q is the platform's agentic layer, and Agentic Monitoring runs patent scouting continuously across a defined technology area, surfacing new filings, new entrants, and shifts in claim language on an ongoing basis. Cypris holds enterprise API partnerships with OpenAI, Anthropic, and Google, and provides enterprise-grade security. It serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries where long-term product development depends on early, reliable signal from the patent and scientific literature.
FAQ
What is AI-driven patent scouting?
AI-driven patent scouting is the continuous use of artificial intelligence to monitor patents and scientific literature for early signals about where a technology field is moving. It uses semantic search and an R&D ontology to track new filings, emerging applicants, and shifting claim language across a technology area, and feeds those signals into product and R&D decisions.
How far ahead of a product are patents filed?
Patents are filed years before products reach the market. In pharmaceuticals, industry analyses indicate composition-of-matter patents are typically filed roughly a decade before regulatory approval, with formulation and dosing patents following through clinical development.1 This lead time is what makes patent scouting a leading indicator.
How is patent scouting different from a patent search?
Patent scouting is continuous and strategic, while a patent search is typically a one-time query. A patent search retrieves documents relevant to a specific question at a point in time. Patent scouting monitors a defined technology area over months and years to identify trends, new entrants, and emerging risks.
How is patent scouting different from a freedom-to-operate search?
A freedom-to-operate (FTO) search determines whether making, using, or selling a specific product would infringe active patent claims. Patent scouting asks a broader question about where a technology field is heading and who is moving there first. Scouting often surfaces the blocking patents that a later FTO search would confirm, but earlier in the development timeline.
Why is patent filing activity a leading indicator?
Patent filing activity is a leading indicator because filing precedes commercial products by years. In pharmaceuticals, the earliest composition patents are filed roughly a decade before approval. Rising filing activity concentrated among established players signals that investment is committing to an approach before it reaches the market.
What does it cost to catch a blocking patent too late?
Catching a blocking patent late is far more expensive than catching it early. Industry guides estimate a freedom-to-operate analysis costs roughly $10,000 to more than $100,000,2 while patent litigation and damages can run from several hundred thousand to hundreds of millions of dollars;3 NTP's case against the maker of BlackBerry settled for $612.5 million.4 Scouting that surfaces the risk years before launch avoids the far higher cost of a late design change or litigation.
How does AI improve patent scouting?
AI improves patent scouting through semantic search, an R&D ontology, and agentic monitoring. Semantic search retrieves patents by technical meaning rather than exact keywords, the ontology organizes patents and scientific literature into a structured technology map, and agentic monitoring runs the surveillance continuously. Together these let scouting cover a full technology field rather than a keyword sample.
Can patent scouting identify white space?
Patent scouting can help identify white space by mapping where patents and scientific research cluster and where they are sparse. Sparse patenting can indicate an opening, but it is not proof of a viable market on its own. White space analysis is most reliable when patent data is read alongside scientific literature and commercial signals.
How often should patent scouting run?
Patent scouting should run continuously rather than as a single report, because filing activity and scientific publication are ongoing and there is a roughly 18-month lag between filing and publication. Agentic monitoring re-runs a defined scouting scope on a schedule and reports what changed since the previous cycle, so product and R&D teams receive current signal rather than a one-time snapshot.
Who uses AI-driven patent scouting?
AI-driven patent scouting is used by R&D leaders, product development teams, and IP strategists in research-intensive industries such as pharmaceuticals, chemicals, advanced materials, and energy. These teams commit budget and headcount to programs years before launch, and scouting gives them early signal on where the field is moving.
References & Cited Literature
- Drug Patent Searching: The Definitive Intelligence Guide for Pharma Teams. DrugPatentWatch.
- Green Light to Launch: A Step-by-Step FTO Analysis Guide for New Drug Products. DrugPatentWatch.
- When Is a "Freedom to Operate" Opinion Cost-Effective? Finnegan.
- NTP, Inc. v. Research In Motion, Ltd. (2006). Wicely, "Freedom-to-Operate Analysis: When and How to Conduct One."
United Airlines' "Relax Row" Looks Amazing. But Who Actually Owns the IP?
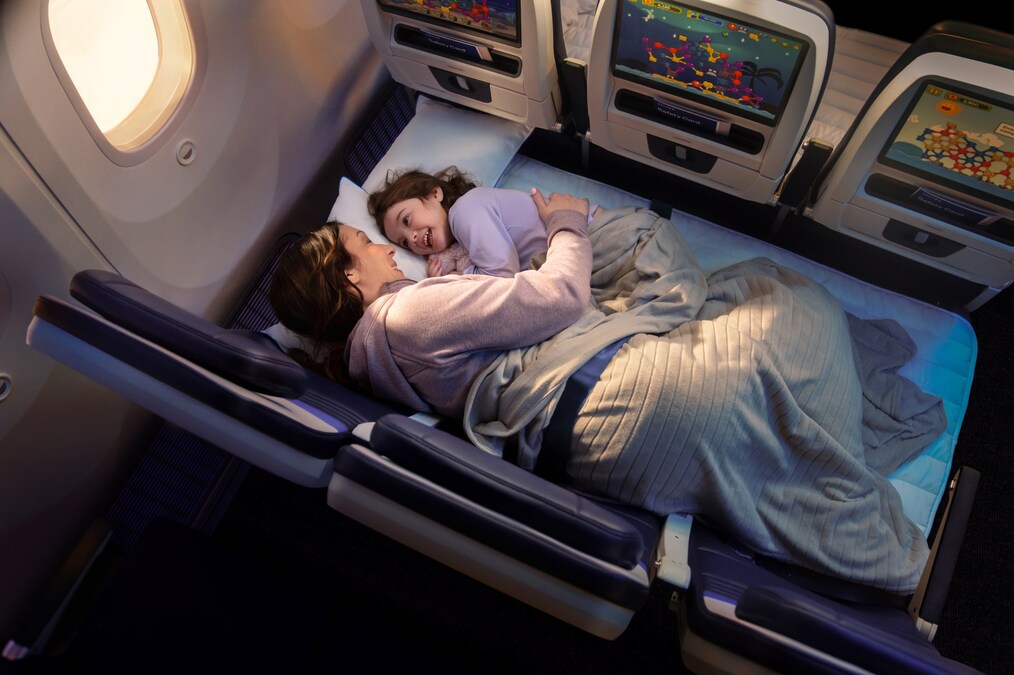
When United Airlines announced "Relax Row" — three adjacent economy seats with adjustable leg rests that raise to create a continuous lie-flat sleeping surface, complete with a mattress pad, blanket, and pillows — the aviation world took notice[1]. Slated for deployment on more than 200 of United's 787s and 777s, with up to 12 rows per aircraft, it represents one of the most ambitious economy cabin innovations ever attempted by a U.S. carrier[1].
But behind the glossy renders and enthusiastic social media rollout lies a thorny question that United hasn't publicly addressed: who actually owns the intellectual property behind this concept?
The answer, it turns out, is almost certainly not United Airlines.
The Skycouch Came First — By Over a Decade

The idea of economy seats with fold-up leg rests that create a flat sleeping surface across a row is not new. Air New Zealand pioneered this exact concept with its Economy Skycouch™, which has been in commercial service since approximately 2011[13]. The product works precisely the way United describes its Relax Row: passengers in a row of three economy seats can raise individual leg rests to seat-pan height, creating a continuous horizontal surface suitable for lying down[13].
Air New Zealand didn't just build the product — they patented it extensively. The foundational U.S. patent, US 9,132,918 B2, titled "Seating arrangement, seat unit, tray table and seating system," was granted in September 2015 and is assigned to Air New Zealand Limited[36]. The inventors — Victoria Anne Bamford, James Dominic France, Glen Wilson Porter, and Geoffrey Glen Suvalko — filed the earliest priority application in January 2009[36], giving the patent family protection extending approximately through 2029–2030.
The claims are remarkably broad. Claim 1 describes a row of adjacent seats where each seat includes a seat back, a seat pan, and a leg rest, with the leg rest moveable between a stored condition and a fully deployed condition where the seat pan and leg rest are substantially coplanar[36]. When deployed, the leg rests of adjacent seats become contiguous, and the combined surfaces cooperate to define a reconfigurable horizontal support surface that can assume T-shape, L-shape, U-shape, and I-shape configurations — allowing at least two adult passengers to recline parallel to the row direction[36].
The patent explicitly contemplates installation in an economy class section of an aircraft and in a class section that offers the lowest standard fare price per seat to customers[36]. In other words, this isn't a business class patent being stretched to cover economy — it was designed from the ground up to cover exactly what United is now proposing.
The IP Goes Deep
Air New Zealand's IP portfolio goes deeper than just the seating arrangement. A separate patent, EP 2509868, covers the specific leg rest mechanism itself — a sophisticated system using cam tracks, hydrolock pistons, synchronization cables, and detent formations that allow each leg rest to move independently between stowed, intermediate, and fully extended positions[39]. The mechanism is entirely self-supporting through the seat frame, requiring no support from the floor or the seat in front[39]. This level of mechanical detail creates additional layers of patent protection beyond the broad concept claims.
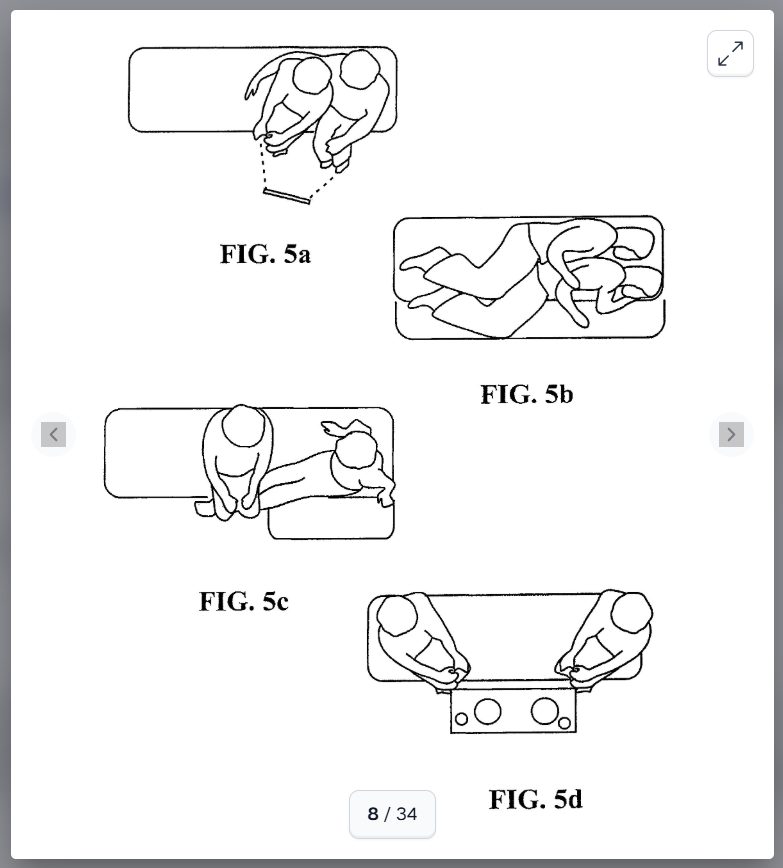
The patent family spans the globe, with filings and grants across the United States[33][34][36], Europe[35], Canada[50], Australia[48], Spain[41], France[40], Brazil[37], and other jurisdictions — a clear signal that Air New Zealand invested heavily in protecting this innovation worldwide.
Air New Zealand Has Licensed Before
Critically, Air New Zealand has not simply sat on this IP. The airline has actively licensed the Skycouch technology to other carriers. China Airlines adopted the concept for its 777-300ER fleet[23][126], and Brazilian carrier Azul licensed it for their "SkySofa" product[126]. The Skycouch represents a textbook case of patent protection leading to licensing of competitors[126].
This licensing history establishes two important facts. First, Air New Zealand treats this IP as a revenue-generating asset and actively monitors the market for potential licensees (or infringers). Second, there is a well-worn commercial path for airlines wanting to deploy this technology — they license it from Air New Zealand.
United's Silence on the IP Question
Here is where things get interesting. United's public communications about Relax Row make no mention of Air New Zealand, the Skycouch, or any licensing arrangement[1][138]. The airline's formal "Elevated" interior press release — a detailed document covering Polaris Studio suites, Premium Plus upgrades, economy screen sizes, and even red pepper flakes for onboard meals — contains zero references to economy lie-flat row technology or any third-party IP[138]. The Relax Row announcement appears to have been made separately through United's social media channels[1].
A thorough search of United Airlines' own patent portfolio reveals no filings covering the economy lie-flat row concept. United's seat-related patents focus on entirely different areas: business class herringbone seating with disabled access configurations[54][55], tray table indicators using magnetic ball mechanisms[72], and seat assignment automation systems[60]. Nothing in United's IP portfolio touches the fold-up leg rest mechanism or the convertible economy row concept.
So What's Going On?
There are several plausible explanations, and the truth likely lies in one of these scenarios.
Scenario 1: An undisclosed license. This is the most probable explanation. Licensing agreements between airlines are frequently confidential. Air New Zealand has demonstrated willingness to license the Skycouch, and United — as a sophisticated commercial entity — would almost certainly conduct freedom-to-operate analysis before committing to install this technology across 200+ widebody aircraft. A quiet licensing deal would explain both the functional similarity and the public silence.
Scenario 2: The seat manufacturer as intermediary. Airlines don't build their own seats — they purchase them from specialized manufacturers like Collins Aerospace (formerly B/E Aerospace), Safran Seats, Recaro, or others. The seat manufacturer supplying United's Relax Row hardware may hold a license or sub-license from Air New Zealand, meaning United is purchasing a licensed product rather than directly licensing the IP. This is common practice in the aircraft interiors supply chain.
Scenario 3: A design-around. While the end result looks identical to the Skycouch, the internal mechanism could differ. Air New Zealand's mechanism patent describes very specific cam-track, hydrolock, and synchronization systems[39]. A seat manufacturer could potentially engineer a leg rest that achieves the same functional result — raising to seat-pan height — using different internal mechanics. However, the broader seating arrangement patent covers the concept itself, not just the mechanism, making a pure design-around more difficult[36].
Notably, alternative approaches to economy lie-flat beds do exist. B/E Aerospace (now part of Collins Aerospace/RTX) holds recent patents describing economy seat rows convertible to beds using fundamentally different mechanisms — one where a lower portion of the backrest detaches and slides forward with the seat pan[92][95], and another where the backrest frame rotates forward to overlay the seat pan with a separate mattress placed on top[96]. These patents, filed from India in 2023 and granted in 2025, explicitly target the economy class cabin[92][96]. But from United's own images, the Relax Row appears to use fold-up leg rests — the Skycouch approach — rather than these backrest-based alternatives[1][2].
If There's No License, It Could Get Sticky

The fourth scenario — that United or its supplier is deploying this product without authorization — would create significant legal exposure. Air New Zealand's patent claims are broad, well-established, and have been maintained across multiple jurisdictions for over a decade[36][41][50]. The patent holder has demonstrated both willingness to license and awareness of the commercial value of this IP[126].
Consider the claim mapping. United describes three adjacent economy seats with adjustable leg rests that can each be raised or lowered to create a cozy lie-flat space[1]. Air New Zealand's patent claims cover a row of adjacent seats with leg rests moveable between stored and deployed conditions where the seat pan and leg rest become substantially coplanar, with adjacent leg rests becoming contiguous to form a reconfigurable horizontal support surface[36]. The visual evidence from United's announcement shows leg rests raised to seat level creating a continuous flat surface across the row[1][2] — a near-perfect overlay with the patent claims.
With the patent family not expiring until approximately 2029–2030, and United planning deployment across 200+ aircraft starting next year[1], the commercial stakes are enormous. An infringement finding could result in injunctive relief, royalty payments, or forced redesign — any of which would be extraordinarily costly and disruptive at the scale United is planning.
What to Watch For
The aviation IP community will be watching this space closely. Key indicators will include whether Air New Zealand makes any public statement acknowledging (or challenging) United's product, whether a licensing agreement surfaces in either company's financial disclosures, and whether the seat manufacturer behind Relax Row is identified — which could reveal whether the IP arrangement runs through the supply chain rather than directly between airlines.
For now, the most important takeaway is this: the concept behind United's splashy Relax Row announcement was invented, patented, and commercialized by Air New Zealand more than a decade ago. Whether United is paying for the privilege of using it, or betting that its implementation differs enough to avoid the patent claims, remains one of the more consequential unanswered questions in commercial aviation IP today.
This article was powered by Cypris Q, an AI agent that helps R&D teams instantly synthesize insights from patents, scientific literature, and market intelligence from around the globe. Discover how leading R&D teams use Cypris Q to monitor technology landscapes and identify opportunities faster - Book a demo
The information provided is for general informational purposes only and should not be construed as legal or professional advice.
Citations
[1] United Airlines Relax Row announcement (social media, March 2026)
[2] United Airlines Relax Row product images (March 2026)
[13] Air New Zealand. "Economy Skycouch – Long Haul."
[23] Executive Traveller. "Review: Air New Zealand's Skycouch seat (soon for China Airlines)."
[33] Air New Zealand Limited. Seating Arrangement, Seat Unit, Tray Table and Seating System. Patent No. US-20160031561-A1. Issued Feb 3, 2016.
[34] Air New Zealand Limited. Seating Arrangement, Seat Unit, Tray Table and Seating System. Patent No. US-20150203207-A1. Issued Jul 22, 2015.
[35] Air New Zealand Limited. Seating Arrangement, Seat Unit, Tray Table and Seating System. Patent No. EP-2391541-A1. Issued Dec 6, 2011.
[36] Air New Zealand Limited; Bamford, V.A.; France, J.D.; Porter, G.W.; Suvalko, G.G. Seating arrangement, seat unit, tray table and seating system. Patent No. US-9132918-B2. Issued Sep 14, 2015.
[37] Air New Zealand Limited. Seating arrangement, seat unit and passenger vehicle and method of setting up a passenger seat area. Patent No. BR-PI1008065-B1. Issued Jul 27, 2020.
[39] Air New Zealand Limited. A Seat and Related Leg Rest and Mechanism and Method Therefor. Patent No. EP-2509868-A1. Issued Oct 16, 2012.
[40] Air New Zealand Limited. Seating Arrangement, Seat Unit and Seating System. Patent No. FR-2941656-A3. Issued Aug 5, 2010.
[41] Air New Zealand Limited. Seating arrangement, seat unit, tray table and seating system. Patent No. ES-2742696-T3. Issued Feb 16, 2020.
[48] Air New Zealand Limited. Seating arrangement, seat unit, tray table and seating system. Patent No. AU-2010209371-B2. Issued Jan 13, 2016.
[50] Air New Zealand Limited. Seating Arrangement, Seat Unit, Tray Table and Seating System. Patent No. CA-2750767-C. Issued Apr 9, 2018.
[54] United Airlines, Inc. Passenger seating arrangement having access for disabled passengers. Patent No. US-11655037-B2. Issued May 22, 2023.
[55] United Airlines, Inc. Passenger seating arrangement having access for disabled passengers. Patent No. US-12291336-B2. Issued May 5, 2025.
[60] United Airlines, Inc. Method and system for automating passenger seat assignment procedures. Patent No. US-10185920-B2. Issued Jan 21, 2019.
[72] United Airlines, Inc. Tray table indicator. Patent No. US-12525316-B2. Issued Jan 12, 2026.
[92] B/E Aerospace, Inc. Row of passenger seats convertible to a bed. Patent No. US-12351317-B2. Issued Jul 7, 2025.
[95] B/E Aerospace, Inc. Row of Passenger Seats Convertible to a Bed. Patent No. US-20250051014-A1. Issued Feb 12, 2025.
[96] B/E Aerospace, Inc. Converting economy seat to full flat bed by dropping seat back frame. Patent No. US-12459650-B2. Issued Nov 3, 2025.
[126] Above the Law. "Coach Comfort: Myth Or The Future."
[138] United Airlines. "United Unveils the Elevated Aircraft Interior."
Innovation intelligence is the practice of combining patent analysis with commercial and market analysis to guide R&D and technology investment decisions. It treats patents, scientific literature, and commercial signals as one connected evidence base rather than separate datasets. The purpose is to answer a question that neither patent data nor market data answers alone: where should an organization invest its R&D resources, and why.
Patent activity on its own is a weak guide to commercial value. According to the World Intellectual Property Organization, global patent applications surpassed 3.5 million for the first time in 2023, a fourth consecutive year of growth.12 Volume at that scale does not indicate commercial success, because filing a patent is not the same as commercializing it. A 2025 study in Research Policy that examined roughly 3,000 patents linked to the U.S. SBIR program found only about 21.5% showed signs of commercialization.3 Filing volume and commercial outcome diverge, which is why patent analysis needs commercial context.
This article explains what innovation intelligence is, how commercial and patent analysis combine, where the combined view creates value, and how AI makes the analysis practical across a corpus of more than 500 million patents and scientific papers.
What innovation intelligence is
Innovation intelligence is the integration of technical evidence and commercial evidence into a single analysis that informs R&D strategy. The technical evidence is patents and scientific literature. The commercial evidence is competitive activity, market signals, and the commercial behavior of the organizations doing the patenting.
Innovation intelligence differs from patent analytics alone. Patent analytics measures filing volume, assignees, jurisdictions, and claim trends. Innovation intelligence uses those patent metrics as one input, then connects them to commercial context so the output is a decision about where to invest rather than a description of a patent landscape.
Innovation intelligence also differs from market intelligence alone. Market intelligence measures demand, competitors, and revenue. It does not show which technical approaches organizations are protecting or where scientific research is accelerating. Innovation intelligence adds the patent and scientific layer that market intelligence lacks.
Why patent activity alone misleads
Patent counts overstate commercial certainty in two directions.
First, a granted patent is not a commercial product. The 2025 Research Policy study of SBIR-linked patents found that only about one in five showed commercialization signs, a reminder that most filings never reach the market. Reading patent activity without commercial signals treats every filing as if it were a product, which it is not.
Second, many patents are abandoned before the end of their term. Academic analysis of patent abandonment, including work published in the NYU Journal of Intellectual Property and Entertainment Law, documents that a substantial share of patents lapse for non-payment of maintenance fees well before their 20-year term expires.4 A raw competitor patent count therefore includes protection that no longer exists. Patent analysis that does not account for lapse and abandonment overstates the strength of a portfolio.
How commercial and patent analysis combine
Commercial and patent analysis combine along three connections.
Assignee to organization. Patent assignees are organizations with commercial strategies. Linking a patent portfolio to the commercial behavior of its owner shows not only what an organization has protected, but how it intends to compete. A rising patent position from a company entering a new market is a stronger signal than a patent count in isolation.
Technology to market. A technology area maps to the products and markets it enables. Connecting patent activity in a technology area to the commercial size and growth of the markets it serves separates well-patented technologies with no market from technologies where patent activity and commercial demand are rising together.
Filing trend to commercial signal. Patent filing velocity is a proxy for R&D spend. It reads most clearly alongside other commercial signals: venture rounds, M&A, and litigation. Litigation outcomes in particular move commercial value directly, as when NTP's patent suit against the maker of BlackBerry settled for $612.5 million in 2006 after threatening to shut down U.S. service.5
Where connected commercial and patent analysis creates value
R&D investment decisions. The combined view shows which technology areas have both rising patent activity and commercial opportunity, so R&D budget is directed with evidence from both sides rather than one.
Competitive intelligence. Connecting a competitor's patent portfolio to its commercial activity reveals intent. Patents show what a competitor is building. Commercial signals show whether they are commercializing it. Together they indicate where a competitor will compete next.
Technology landscaping. A landscape that combines patents, scientific literature, and commercial context describes not only who holds patents in an area, but whether that area is commercially live. This distinguishes active technology fields from patented but dormant ones.
Licensing and partnership strategy. Identifying organizations with strong patent positions and commercial reasons to license or partner requires both the patent view and the commercial view. Neither dataset identifies these opportunities alone.
Freedom-to-operate in commercial context. A freedom-to-operate (FTO) assessment identifies patent risk. Reading that risk alongside the commercial value of a product line prioritizes which risks to clear first, based on what is commercially at stake.
How AI makes innovation intelligence work at scale
Connecting commercial and patent analysis manually does not scale. Global patent applications surpassed 3.5 million in 2023, and a structural lag of roughly 18 months between filing and publication means disclosed research is already more than a year old when it surfaces. The volume and the delay together put comprehensive manual review out of reach.
AI makes innovation intelligence practical in three ways. Semantic search retrieves patents and scientific papers by technical meaning rather than exact keyword, so a technology area is captured completely regardless of terminology. An R&D ontology organizes patents and scientific literature into a structured map of technologies and their relationships, which is what allows patent activity to be connected to technology areas and, through them, to commercial context. Agentic workflows run the analysis continuously, updating the combined view as new patents, papers, and signals appear. Together these let innovation intelligence operate across a full technology field rather than a keyword sample of it.
Where Cypris fits
Cypris is an AI-native R&D intelligence platform that connects patent analysis, scientific literature, and commercial context for innovation intelligence. Cypris runs semantic search across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology that maps technologies and their relationships. The ontology is what lets patent activity be connected to technology areas and analyzed as innovation intelligence rather than isolated patent metrics.
Cypris Q is the platform's agentic layer, and Agentic Monitoring tracks a technology area continuously, updating the combined patent and commercial view as new filings, papers, and signals appear. Cypris holds enterprise API partnerships with OpenAI, Anthropic, and Google, and provides enterprise-grade security. It serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries where R&D investment decisions depend on connecting patent evidence to commercial context.
FAQ
What is innovation intelligence?
Innovation intelligence is the practice of combining patent analysis with commercial and market analysis to guide R&D and technology investment decisions. It treats patents, scientific literature, and commercial signals as one connected evidence base, so the output is a decision about where to invest rather than a description of a patent landscape.
What is software for commercial and patent analysis?
Software for commercial and patent analysis connects patent data to commercial context in one platform, so R&D and strategy teams can evaluate both the technical and the commercial dimension of a technology area. Cypris supports this by running semantic search across more than 500 million patents and scientific papers organized through a proprietary R&D ontology that links patent activity to technology areas.
How is innovation intelligence different from patent analytics?
Innovation intelligence differs from patent analytics by adding commercial context. Patent analytics measures filing volume, assignees, and claim trends. Innovation intelligence uses those metrics as one input and connects them to commercial and market signals, so the analysis informs an investment decision rather than only describing a patent landscape.
Why is patent activity alone a poor guide to commercial value?
Patent activity alone is a poor guide because most patents are never commercialized and many are abandoned before term. A 2025 Research Policy study of SBIR-linked patents found only about 21.5% showed commercialization signs,3 and academic work on patent abandonment shows a substantial share lapse before their 20-year term ends.4 Filing volume and commercial value diverge.
How many patents are filed each year?
According to WIPO, global patent applications exceeded 3.5 million for the first time in 2023, the fourth consecutive year of growth.1 This volume, combined with a roughly 18-month filing-to-publication lag, makes comprehensive manual review impractical and is why AI-driven analysis is used for innovation intelligence.
How do commercial and patent analysis combine?
Commercial and patent analysis combine by linking patent assignees to their organizations' commercial strategies, mapping technology areas to the markets they serve, and reading patent filing trends alongside commercial signals such as venture rounds, M&A, and litigation. These connections turn patent activity into a signal about where R&D investment is concentrating and where commercial opportunity exists.
Why do R&D teams need both patent and commercial analysis?
R&D teams need both because a technology can be heavily patented but commercially stalled, or commercially attractive but legally crowded. Patent analysis shows what is protected and where research is accelerating. Commercial analysis shows where demand and competition are. Investment decisions require reading them together.
How does AI improve innovation intelligence?
AI improves innovation intelligence through semantic search, an R&D ontology, and agentic monitoring. Semantic search captures a technology area completely regardless of terminology, the ontology connects patent activity to technology areas and commercial context, and agentic monitoring keeps the combined view current. Together these make the analysis practical across a full technology field.
Who uses innovation intelligence?
Innovation intelligence is used by R&D leaders, strategy and commercial teams, and IP strategists in research-intensive industries such as pharmaceuticals, chemicals, advanced materials, and energy. These teams make technology investment decisions that require both patent evidence and commercial context.
How does innovation intelligence relate to freedom-to-operate?
Innovation intelligence relates to freedom-to-operate (FTO) by placing patent risk in commercial context. An FTO assessment identifies patent risk for a product. Reading that risk alongside the commercial value of the product line prioritizes which risks to clear first, based on what is commercially at stake.
References & Cited Literature
- World Intellectual Property Indicators 2024 — record on global patent filings (global applications surpassed 3.5 million in 2023). EU IP Helpdesk.
- WIPO reports return to growth in patents and trademarks filings in 2024. Global Legal Post.
- Raiteri, E., Bottai, C., & de Rassenfosse, G. (2025). A new approach to measuring invention commercialization: An application to the SBIR program. Research Policy.
- Does Anybody See What I See?: Abandoned Patents and Their Impacts on Technology Development. NYU Journal of Intellectual Property & Entertainment Law.
- NTP, Inc. v. Research In Motion, Ltd. — the parties settled in 2006 for $612.5 million (widely reported; matter of public record). Case discussed in: Wicely, "Freedom-to-Operate Analysis: When and How to Conduct One."
Microsoft Copilot has become the default AI assistant in many enterprise environments, and it is easy to see why. Deep integration with Word, Excel, PowerPoint, and Outlook makes it the path of least resistance for organizations already embedded in the Microsoft 365 ecosystem. But for teams doing serious scientific research, patent analysis, or technology scouting, the path of least resistance is not the same as the path to the best outcome. Copilot's intelligence is grounded in general web data and the documents inside a company's Microsoft tenant. It has no native access to patent corpora, no structured understanding of scientific literature, no concept of prior art or freedom to operate, and no ontology that maps relationships between technical domains. For R&D professionals and IP strategists, those are not nice-to-have features. They are the foundation of the work itself.
The result is a growing gap between what Copilot can do for a marketing team drafting slide decks and what it can do for an R&D scientist evaluating whether a polymer formulation infringes on a competitor's patent family. General-purpose AI assistants treat all information as interchangeable text. Domain-specific intelligence platforms treat information as structured knowledge, with provenance, citation networks, classification hierarchies, and temporal context that determine whether a finding is relevant or misleading. That distinction matters enormously when the downstream consequence of a missed reference is a nine-figure product development failure or an unexpected infringement claim.
This guide evaluates the best alternatives to Microsoft Copilot for teams working in research and development, intellectual property strategy, technology scouting, and scientific literature analysis. Each platform is assessed on three dimensions that matter most for technical and scientific use cases: the specificity and depth of its underlying dataset, the sophistication of its domain ontology or knowledge graph, and the degree to which its workflows align with the actual processes R&D and IP professionals follow every day.
Cypris
Cypris is an enterprise R&D intelligence platform purpose-built for corporate research teams, and it represents the most comprehensive alternative to Microsoft Copilot for technical and scientific use cases available in 2026. Where Copilot draws on general web data and a company's internal Microsoft documents, Cypris provides unified access to more than 500 million patents, scientific papers, grants, clinical trials, and market intelligence sources through a single interface. That dataset distinction is not incremental. It is categorical. An R&D scientist using Copilot to research a novel catalyst formulation will receive answers synthesized from web pages, blog posts, and whatever internal documents happen to be indexed in SharePoint. The same scientist using Cypris will receive answers grounded in the full global patent corpus, peer-reviewed literature spanning hundreds of journals, active grant funding data, and clinical trial records, all searchable through a single query.
What truly differentiates Cypris from both Copilot and the other alternatives on this list is its proprietary R&D ontology, a structured knowledge framework that understands the relationships between technical concepts across domains, industries, and document types. This is not a keyword index or a simple embedding model. It is a purpose-built taxonomy that maps how materials relate to processes, how processes relate to applications, and how applications relate to competitive patent positions. When a researcher queries Cypris about a specific technology area, the ontology ensures that results surface not just documents containing the right words but documents containing the right concepts, even when those concepts are described using different terminology across patents filed in different jurisdictions or papers published in different subfields.
The platform's workflow alignment with R&D processes is equally significant. Cypris supports the full spectrum of intelligence activities that corporate research teams perform, from early-stage technology landscape mapping at Gate 1 of the Stage-Gate process through prior art search, patent landscape analysis, freedom-to-operate assessment, competitive monitoring, and technology scouting. Cypris Q, the platform's AI research agent, generates structured intelligence reports that serve as direct inputs to stage-gate reviews and investment decisions, rather than requiring researchers to manually synthesize findings from multiple disconnected tools. Hundreds of enterprise teams and thousands of researchers across R&D, IP, and product development rely on Cypris as their primary technical intelligence infrastructure. Official enterprise API partnerships with OpenAI, Anthropic, and Google ensure the platform leverages frontier AI capabilities, while enterprise-grade security meets the requirements of Fortune 500 organizations handling sensitive pre-patent intellectual property. For any R&D or IP team currently using Copilot and finding that general-purpose AI falls short of their technical intelligence needs, Cypris is the most direct and complete upgrade available.
Elicit
Elicit is an AI research assistant focused specifically on scientific literature review and evidence synthesis. The platform searches approximately 138 million academic papers sourced primarily from the Semantic Scholar database and applies large language models to summarize findings, extract structured data from papers, and support systematic review workflows. For researchers conducting literature reviews, Elicit's ability to screen papers against user-defined criteria and extract specific data points into customizable tables represents a genuine productivity improvement over manual methods. Researchers using the platform report significant time savings on literature reviews, and its guided workflow for systematic reviews covers search, screening, extraction, and report generation in a structured sequence.
However, Elicit's dataset is limited to academic literature. It does not include patents, grants, clinical trial data, or market intelligence sources. This means that any R&D workflow requiring cross-referencing between published research and the patent landscape, which includes virtually every corporate technology assessment, will require supplementing Elicit with one or more additional tools. The platform also lacks a domain-specific ontology for R&D. Its search relies on semantic understanding of natural language queries matched against paper abstracts and full texts, which works well for finding relevant literature within a known domain but does not map the structural relationships between technical concepts that enable true landscape-level intelligence. Elicit is best suited for academic researchers and scientists focused on literature synthesis within a well-defined research question. For enterprise R&D teams needing to integrate patent intelligence with scientific literature analysis, the platform will need to be paired with additional patent search and analysis tools.
Consensus
Consensus takes a different approach to scientific research by functioning as an evidence-based search engine designed to answer research questions with findings drawn directly from peer-reviewed literature. The platform indexes over 200 million academic papers and uses AI to synthesize findings across multiple studies, providing concise answers with direct citations to source papers. Its signature feature is the Consensus Meter, which provides a visual representation of whether the scientific literature broadly supports or contradicts a given claim. For questions with clear empirical dimensions, such as whether a particular intervention produces a measurable effect, this feature can provide a rapid orientation to the state of the evidence that would take hours to assemble through manual review.
The dataset underlying Consensus is broad in its coverage of peer-reviewed literature but, like Elicit, excludes patents, technical standards, regulatory filings, and other document types that corporate R&D teams routinely need. The platform also lacks any R&D-specific ontological structure. Its strength lies in aggregating evidence around discrete research questions rather than mapping complex technology landscapes or identifying competitive positioning across patent portfolios. Consensus is most valuable as a rapid evidence-checking tool for scientists who need to quickly assess the state of research on a specific empirical question. It is not designed to support the broader strategic intelligence workflows, such as prior art search, competitive patent monitoring, or technology scouting, that enterprise R&D teams require.
Scite
Scite occupies a unique position in the research intelligence landscape through its focus on contextual citation analysis. The platform indexes over 250 million articles and uses machine learning to classify citation statements as supporting, contrasting, or mentioning, providing researchers with a deeper understanding of how a given paper has been received by the scientific community than simple citation counts can offer. This Smart Citations feature addresses a genuine blind spot in traditional citation analysis, where a paper cited 500 times might be cited 400 times in support and 100 times in disagreement, a distinction that raw citation counts completely obscure. Scite also offers citation dashboards, a browser extension for inline citation context, and an AI assistant for research queries grounded in its citation database.
Scite's dataset is substantial for scientific literature, and its contextual citation analysis represents a genuinely differentiated capability. However, the platform remains focused on academic citation networks and does not extend into patent data, market intelligence, or the broader range of technical document types that R&D teams analyze. Its ontological structure is oriented around citation relationships rather than technical domain taxonomies, which makes it excellent for evaluating the scientific credibility of specific claims but less useful for mapping technology landscapes or identifying white space in patent portfolios. Scite is best positioned as a supplementary tool for R&D teams that need to assess the reliability and reception of specific scientific findings, particularly during due diligence or when evaluating whether a technology direction is supported by robust evidence.
The Lens
The Lens stands out among the tools on this list because it is one of the few platforms that natively integrates patent data and scholarly literature within a single search interface. Operated by Cambia, an Australian nonprofit, The Lens provides free access to over 200 million scholarly records and patent documents from more than 100 jurisdictions, with bidirectional linking between patents and the academic papers they cite. This means a researcher can start from a patent and immediately see the scientific literature cited within it, or start from a scholarly paper and trace which patents reference that research. That bidirectional linkage is valuable for R&D teams conducting prior art searches or evaluating the relationship between published science and commercialized intellectual property.
The Lens also offers biological sequence searching through its PatSeq tools, which is particularly useful for life sciences R&D teams working in genomics, synthetic biology, or biopharmaceuticals. As a free, open-access platform, The Lens provides remarkable value for the cost. Its limitations emerge at the enterprise scale. The platform lacks AI-powered semantic search capabilities, meaning researchers must rely on Boolean queries and structured search syntax rather than natural language. It does not have a proprietary R&D ontology that maps relationships between technical concepts, and its analytics and visualization tools, while functional, are less sophisticated than those offered by dedicated enterprise intelligence platforms. The Lens is an excellent entry point for R&D teams that want patent and literature search in a single interface without a significant licensing investment, but teams requiring AI-driven landscape analysis, automated monitoring, or integration with enterprise workflows will find its capabilities insufficient as a primary intelligence platform.
Semantic Scholar
Semantic Scholar is a free AI-powered academic search engine developed by the Allen Institute for AI, indexing over 214 million papers with a strong emphasis on computer science and biomedical research. The platform's AI features go beyond basic keyword matching to include TLDR summaries that provide one-sentence overviews of paper contributions, Semantic Reader for augmented reading with contextual citation information, and Research Feeds that learn user preferences and recommend relevant new publications. Its ability to identify highly influential citations, distinguishing between perfunctory references and citations that meaningfully build on prior work, is a genuinely useful feature for researchers trying to trace the intellectual lineage of a research direction.
Semantic Scholar's greatest strength is also its most important limitation for R&D professionals: it is purely an academic literature discovery tool. It contains no patent data, no market intelligence, no clinical trial records, and no regulatory information. It also offers no enterprise features such as team collaboration, role-based access, or integration with internal knowledge management systems. The platform's knowledge graph maps relationships between papers, authors, and venues, but it does not provide the kind of R&D-specific ontological structure that connects research findings to applications, materials to processes, or scientific concepts to patent classifications. For academic researchers who need a powerful free tool for literature discovery and exploration, Semantic Scholar is among the best available. For corporate R&D teams that need their intelligence platform to span multiple document types and support enterprise-grade workflows, it serves as a useful complement to a more comprehensive platform rather than a replacement for one.
Google Patents
Google Patents provides free access to over 120 million patent documents from patent offices worldwide, with full-text search, machine translation of foreign-language patents, and prior art search functionality. The platform benefits from Google's search infrastructure, making basic patent searches fast and accessible. Google's prior art finder can identify potentially relevant prior art based on text descriptions rather than formal patent classification codes, which lowers the barrier to entry for researchers who are not trained patent searchers.
The limitations of Google Patents become apparent quickly for teams doing serious IP work. The platform offers no scientific literature integration, no landscape visualization or analytics tools, no competitive monitoring or alerting capabilities, and no structured ontology for navigating technical domains. Search results are presented as a flat list of documents with basic metadata rather than as an analyzed landscape with trends, key players, and technology clusters. Google Patents is useful as a quick reference tool for checking whether a specific patent exists or for performing a preliminary scan of a technology area, but it lacks the analytical depth, dataset breadth, and workflow support that enterprise R&D and IP teams need for substantive intelligence work.
Perplexity
Perplexity has gained significant traction as a general-purpose AI research tool that provides cited answers to questions by searching the web and synthesizing information from multiple sources. Its strength lies in its ability to produce well-structured answers with inline citations, making it useful for rapid orientation to unfamiliar topics. For R&D professionals, Perplexity can serve as a starting point for understanding a new technology area or checking recent developments before conducting deeper analysis with specialized tools.
The fundamental limitation of Perplexity for R&D and scientific use cases is the same limitation that applies to Microsoft Copilot: its dataset is the open web. Perplexity does not have direct access to patent databases, paywalled scientific journals, clinical trial registries, or proprietary technical databases. Its citations come from publicly accessible web pages, which may include summaries of research rather than the research itself. It has no ontological structure for technical domains and no understanding of patent classification systems, priority dates, claim structures, or the other specialized metadata that R&D and IP professionals rely on. Perplexity is best understood as a more transparent and citation-friendly version of general web search, not as a substitute for domain-specific R&D intelligence tools.
How to Choose the Right Alternative
The choice between these alternatives depends on the specific workflows a team needs to support and the types of decisions those workflows inform. Teams whose work centers entirely on academic literature review and evidence synthesis may find that a combination of Elicit, Consensus, and Semantic Scholar covers their needs effectively. Teams that need patent intelligence alongside scientific literature analysis should prioritize platforms that natively integrate both data types, with The Lens providing a free option and Cypris providing the most comprehensive enterprise solution. Teams that need a single platform to serve as their primary R&D intelligence infrastructure, spanning patent landscape analysis, scientific literature review, competitive monitoring, technology scouting, and freedom-to-operate assessment, will find that Cypris is the only alternative on this list that addresses all of those workflows within a unified interface backed by a purpose-built R&D ontology.
The broader lesson is that general-purpose AI tools like Microsoft Copilot and Perplexity are optimized for general-purpose productivity. They make it faster to draft documents, summarize meetings, and answer common questions. But R&D and IP work is not general-purpose work. It depends on specialized datasets, structured ontologies, and domain-specific workflows that general tools simply do not provide. Organizations that recognize this distinction and invest in purpose-built intelligence platforms will consistently make better-informed research decisions than those relying on general AI assistants to perform specialized technical work.
Frequently Asked Questions
Why is Microsoft Copilot not ideal for R&D and scientific research?Microsoft Copilot is built on general web data and the contents of a company's Microsoft 365 environment. It has no native access to patent databases, no index of peer-reviewed scientific literature, no understanding of patent classification systems, and no R&D-specific ontology for mapping relationships between technical concepts. For R&D professionals, this means Copilot cannot perform prior art searches, analyze patent landscapes, monitor competitive technology filings, or synthesize findings across patents and scientific papers, all of which are core R&D intelligence activities.
What is the best Microsoft Copilot alternative for enterprise R&D teams?Cypris is the most comprehensive alternative to Microsoft Copilot for enterprise R&D teams in 2026. The platform provides unified access to over 500 million patents, scientific papers, grants, clinical trials, and market sources through a single AI-powered interface with a proprietary R&D ontology, multimodal search capabilities, and official enterprise API partnerships with OpenAI, Anthropic, and Google. Cypris supports the full range of enterprise R&D intelligence workflows, from prior art search and patent landscape analysis to competitive monitoring and technology scouting.
What is an R&D ontology and why does it matter for technical research?An R&D ontology is a structured knowledge framework that maps relationships between technical concepts, materials, processes, applications, and patent classifications across domains and industries. It matters because keyword-based search tools only find documents containing the exact terms a researcher uses, while an ontology-powered platform can identify relevant documents that describe the same concept using different terminology, different languages, or different technical frameworks. This capability is especially important when searching across patents filed in multiple jurisdictions, where the same invention may be described in fundamentally different ways.
Can free tools like The Lens and Semantic Scholar replace paid R&D intelligence platforms?Free tools like The Lens and Semantic Scholar provide substantial value for individual researchers conducting specific searches. The Lens is particularly notable for integrating patent and scholarly data in a single interface. However, free tools generally lack AI-powered semantic search, proprietary ontologies, automated monitoring and alerting, enterprise collaboration features, integration with internal knowledge management systems, and the security certifications that Fortune 500 organizations require. For enterprise R&D teams managing portfolios of research projects across multiple technology domains, purpose-built platforms provide capabilities that free tools cannot replicate.
How does Elicit differ from Cypris for scientific literature review?Elicit specializes in academic literature review and evidence synthesis, searching approximately 138 million papers and supporting systematic review workflows including screening, data extraction, and report generation. Cypris provides a broader scope that includes scientific literature alongside patents, grants, clinical trials, and market intelligence, all searchable through a proprietary R&D ontology. Elicit is designed for researchers focused on a specific empirical question within published literature. Cypris is designed for R&D teams that need to evaluate a technology landscape across multiple data types and make strategic decisions based on the full innovation picture.
What is contextual citation analysis and why does Scite offer it?Contextual citation analysis, as implemented by Scite's Smart Citations feature, classifies how a paper is cited by subsequent publications, distinguishing between citations that support, contrast, or simply mention the original work. This matters because traditional citation counts treat all references equally, giving no indication of whether a highly cited paper is highly cited because its findings are widely confirmed or because its conclusions are widely disputed. For R&D teams evaluating whether to build on a particular scientific finding, understanding the nature of citations is as important as knowing the total count.
Does Perplexity have access to patent databases or scientific journals?No. Perplexity searches the open web and synthesizes answers from publicly accessible sources. It does not have direct access to patent databases, paywalled scientific journals, clinical trial registries, or proprietary technical databases. While it may surface summaries or secondary reports about patents and research, it cannot search the primary sources that R&D and IP professionals need to review for substantive technical intelligence work.
What types of R&D workflows require a specialized intelligence platform rather than a general AI assistant?Workflows that require specialized intelligence platforms include prior art search, patent landscape analysis, freedom-to-operate assessment, competitive technology monitoring, technology scouting, scientific literature review integrated with patent analysis, identification of white space in patent portfolios, and early-stage technology assessment at Gate 1 of the Stage-Gate process. These workflows depend on access to specialized datasets, understanding of patent classification systems, and the ability to map relationships between technical concepts across different document types, none of which general AI assistants like Copilot or Perplexity provide.
How do R&D ontologies differ from the knowledge graphs used by general AI tools?General AI tools use broad knowledge graphs derived from web data that represent millions of entities and relationships across every conceivable domain. R&D ontologies are purpose-built taxonomies that focus specifically on technical and scientific concepts, mapping how materials relate to processes, how processes relate to applications, how applications map to patent classifications, and how all of these connect across industries and jurisdictions. The specificity of an R&D ontology enables a level of precision in technical search and analysis that general knowledge graphs cannot achieve because general graphs prioritize breadth over domain depth.
What security considerations should R&D teams evaluate when choosing a Copilot alternative?R&D teams routinely work with pre-patent inventions, proprietary formulations, competitive analyses, and other highly sensitive intellectual property. Any AI platform used for R&D intelligence must meet enterprise-grade security requirements, including data isolation, encryption, access controls, and compliance certifications appropriate for the organization's industry. General-purpose AI assistants may process queries through shared infrastructure without the data governance controls that sensitive IP work demands. Enterprise R&D intelligence platforms like Cypris are designed to meet these requirements, ensuring that proprietary research queries and results remain protected.
Work, as we’ve known it, has fundamentally changed.
That statement might have sounded dramatic a year or two ago, but you would be naive to deny it today. AI is no longer just augmenting workflows. It is increasingly owning them. The initial wave focused on the obvious entry points such as drafting presentations, summarizing articles, and writing emails. But what started as assistive has quickly evolved into something far more powerful.
AI agents are now executing entire downstream workflows. Not just writing copy for a presentation, but building it. Not just drafting an email, but sending and iterating on it. These systems run asynchronously, improve over time, and are becoming easier to build and deploy by the day.
Startups and smaller organizations are already operating with them across their workflows and are seeing serious gains (including us at Cypris). Large enterprises, expectedly, lag behind, but will inevitably follow. Large enterprises are for the most part subject to their vendors, and those vendors are undergoing massive foundational shifts from traditional software apps to Agentic AI solutions.
Which raises the question:
What does this shift mean for the enterprise tech stack of the future?
The companies that answer this and position themselves correctly will not just be more efficient. They will operate at a fundamentally different pace. In a world where AI compounds progress, speed becomes the ultimate competitive advantage.
From Search to Chat
My perspective comes from the last five years building Cypris, an AI platform for R&D and IP intelligence.
We launched in 2021, before AI meant what it does today. Back then, semantic search was considered cutting edge. Our core value proposition was helping teams identify signals in massive datasets such as patents, research papers, and technical literature faster than their competitors.
The reality of that workflow looked very different than it does today.
Researchers spent the majority of their time on data curation. Entire teams were dedicated to building complex Lucene queries across fragmented datasets. The quality of insights depended heavily on how good your query was, and how effectively you could interpret thousands of results through pre-built charts, visualizations, BI tools and manual workflows.
Work that now takes minutes used to take weeks. Prior art searches, landscape analyses, and whitespace identification all required significant manual effort. Most product comparisons, and ultimately our demos, came down to a few questions:
- Does your query return better results than theirs?
- How robust are your advanced search capabilities?
- What kind of visualizations can you offer to identify meaningful signal in the results?
Then everything changed.
The Inflection Point - When AI Became Exposed to Enterprise
The launch of ChatGPT in November 2022 marked a turning point.
At first, its enterprise impact was not obvious. By early 2024, the shift became undeniable. Marketing workflows were the first to transform. Copywriting went from a differentiated skill to a commodity almost overnight. Then came coding assistants, which have rapidly evolved toward full-stack AI development.
We adapted Cypris in real time, shifting from static, pre-generated insights to dynamic, retrieval-based systems leveraging the world’s most powerful models. We recognized early that the model race was a wave we wanted to ride, so we built the infrastructure to incorporate all leading models directly into our product. What began as an enhancement quickly became the foundation of everything we do.

As the software stack progressed quickly, our customers began scrambling to make sense of it. AI committees formed. IT teams took control of purchasing decisions. Sales cycles lengthened as organizations tried to impose governance on something evolving faster than their processes could handle. We have seen this firsthand, with customers explicitly stating that all AI purchases now need to go through new evaluation and procurement processes.
But there is an underlying tension: Every piece of software is now an AI purchase.
And eventually, enterprises will need to operate that way.
What Should Be Verticalized?
At the center of this transformation and a complicated question most enterprise buyers are struggling with today is:
What can general-purpose AI handle, and where do you need specialized systems?
Most organizations do not answer this theoretically. They learn through experience, use case by use case. And the market hype does not help. There is a growing narrative that companies can “vibe code” their way into rebuilding core systems that underpin processes involving hundreds of stakeholders and millions of dollars in impact.
That is unrealistic.
Call me when a company like J&J decides to replace Salesforce with something built in their team’s free time with some prompts.
A more grounded way to think about it is through a simple principle that consistently holds true:
AI is only as good as what it is exposed to.
A model will generate answers based on the data it can access and the orchestration it is given, whether that is its training data, web content, or additional context you provide.
If you do not give it access to meaningful or proprietary data or thoughtful direction, it will default to generic knowledge.
This creates a growing divide within tech stacks that solely levergage 'commodity AI' vs. 'enterprise enhanced AI'.
Commodity AI vs. Enterprise-Enhanced AI
Commodity AI is the baseline.
It includes foundation models such as ChatGPT, Claude, and Co-Pilot, which run on top of those models, that everyone has access to.
Using them is no longer a competitive advantage. It is table stakes.
If your organization relies on the same tools trained on the same data, your outputs and decisions will begin to look the same as everyone else’s.
Enterprise-enhanced AI is where differentiation happens.
This is what you build on top of the foundation.
It includes:
- Integrating proprietary and high-value datasets
- Layering in domain-specific tools and platforms
- Designing curated workflows that tap into verticalized agents
- Building custom ontologies that interpret how your business operates
- Designing org wide system prompts tailored to existing internal processes
The goal is to amplify foundation models with context they cannot access on their own.
Additionally, enterprises that believe they can simply vibe code their own stack on top of foundation models will eventually run into the same reality that fueled the SaaS boom over the last 20 years. Your job is not to build and maintain software, and doing so will consume far more time and resources than expected. Claude is powerful, and your best vendors are already using it as a foundation. You will get significantly more leverage from it through verticalized and enhanced systems.
Where Data Foundations Especially Matter
In our eyes, nowhere is this more critical than in R&D and IP teams.
Foundation model providers are not focused on maintaining continuously updated datasets of global patents, scientific literature, company data, or chemical compounds. It is too niche and not a strategic priority for them.
But for teams making high-stakes decisions such as:
- What to build
- Where to invest
- Where to file IP
- How to differentiate
That data is essential.
If you rely on generic AI outputs without a strong data foundation, you are making decisions on incomplete information.
In technical domains, incomplete information is a strategic risk.
See our case study on real-world scenario gaps here: https://www.cypris.ai/insights/the-patent-intelligence-gap---a-comparative-analysis-of-verticalized-ai-patent-tools-vs-general-purpose-language-models-for-r-d-decision-making
The New Mandate for Enterprise Leaders
All software vendors will be AI-vendors, so figuring out your strategy, figuring out your security and IT governance, and figuring out your deployment process quickly should be a strategic priority. Focus on real-world signal and critical workflows and find vendors that can turn your commodity AI into enterprise enhanced assets before your competitors do.
We are entering a world where AI itself is no longer the differentiator.
How you implement it is.
The enterprises that recognize this early and build their stacks accordingly will not just keep up.
They will redefine the pace of their industries.
The freedom-to-operate search has always been one of the most consequential exercises in product development. Before a company commits significant capital to manufacturing, marketing, or licensing a new technology, it must determine with reasonable confidence that bringing the product to market will not infringe the valid and enforceable patent rights of a third party. That determination has never been simple, but the scale of the challenge in 2026 has grown to a point where traditional methods alone are no longer sufficient, and the rapid proliferation of general-purpose AI tools has introduced both new capabilities and new sources of confusion about what actually constitutes a defensible FTO workflow.
The Scale Problem: Why Traditional FTO Methods Are Breaking Down
The volume of global patent data is the first and most visible challenge. Innovators around the world filed 3.7 million patent applications in 2024, marking a 4.9 percent increase over 2023 and the fastest year-on-year growth since 2018 (1). Patents in force worldwide grew 6 percent in 2024 to reach an estimated 19.7 million (2). These are not evenly distributed. China's share of global patent applications jumped from 34.6 percent in 2014 to 49.1 percent in 2024, accounting for nearly half of all worldwide filings (3). For any R&D team conducting an FTO search across multiple jurisdictions, the corpus to be searched is not merely large but growing at a compounding rate, with an increasing share published in Chinese and other non-English languages that keyword searches in English will systematically miss.
The problem extends beyond sheer volume. Patent claims are written in deliberately broad and often abstract language. A single claim may describe a concept using terminology that varies dramatically from how an engineer or scientist would describe the same concept in a lab notebook or product specification. Traditional Boolean keyword searches depend on the searcher anticipating every synonym, variant, and adjacent phrasing that a patent drafter might have used. In crowded technology fields where hundreds of applicants have filed on overlapping concepts, the combinatorial explosion of possible keyword strings makes exhaustive manual search functionally impossible.
Jurisdictional complexity compounds the problem further. An FTO search is always territorial. A product that is clear in the United States may face blocking patents in Europe, Japan, or China. Each jurisdiction has its own patent database, its own classification scheme, and its own rules about claim interpretation. A thorough FTO search must account for granted patents, pending applications that may issue with claims covering the product, and patent families that span multiple national and regional offices.
General-Purpose AI vs. Verticalized LLMs: A Critical Distinction
The arrival of powerful general-purpose large language models such as GPT-4, Claude, and Gemini has created a tempting shortcut for teams looking to accelerate FTO work. These models can summarize patent documents, suggest search terms, and even draft preliminary claim comparisons. But there is a fundamental difference between a general-purpose LLM that has been exposed to some patent text during pre-training and a verticalized model that has been purpose-built for patent and technical literature analysis, and conflating the two introduces real risk into FTO workflows.
General-purpose LLMs suffer from several structural limitations in the FTO context. They do not have access to live patent databases. They cannot verify the legal status of a patent. They are prone to hallucination, meaning they may generate plausible-sounding but factually incorrect claim interpretations or invent patent numbers that do not exist. And they lack the domain-specific training that allows them to understand how patent claim language maps to technical concepts with the precision that FTO analysis demands.
Verticalized LLMs, by contrast, are models that have been fine-tuned or trained from the ground up on patent corpora, scientific literature, and technical taxonomies. These models understand the particular conventions of patent drafting: how means-plus-function claims work, how dependent claims narrow the scope of independent claims, how prosecution history estoppel affects claim interpretation, and how the same invention can be described using entirely different vocabulary across jurisdictions and technology domains. When integrated into a purpose-built search platform with access to live, structured patent data, verticalized LLMs can perform semantic retrieval at a level of precision and recall that general-purpose models cannot match.
The practical implication for FTO practitioners is straightforward: general-purpose AI is useful for background research, brainstorming search strategies, and explaining technical concepts to non-specialist stakeholders, but it should never be the primary engine of an FTO search. The search itself must be powered by domain-specific AI operating on a verified, structured, and continuously updated patent corpus.
Semantic Search: Moving Beyond Keywords to Concepts
The single most impactful AI technique for FTO searches on large datasets is semantic search. Unlike Boolean keyword search, which matches exact text strings, semantic search uses natural language processing and machine learning to understand the conceptual meaning of a query and return results that are conceptually related even when the specific terminology differs. This directly addresses the vocabulary problem that plagues patent searching: the same invention can be described using entirely different words depending on the drafter, the jurisdiction, and the era in which the patent was filed.
With semantic search, attorneys running freedom-to-operate searches no longer need to enumerate every synonym up front, and R&D teams can explore adjacent technology spaces without mastering classification schemes (4). Semantic search engines trained on patent corpora can interpret an invention disclosure or a set of product claims and retrieve conceptually similar documents from across the entire global patent landscape, surfacing references that a keyword search would have missed entirely.
The effectiveness of semantic search depends heavily on the quality of the underlying model and the data on which it was trained. This is where the distinction between general-purpose and verticalized AI becomes most consequential. A semantic search engine powered by a model trained specifically on patent text will understand that "photovoltaic energy conversion apparatus" and "solar cell" refer to the same concept, that "computing device" in one patent family may correspond to "mobile terminal" in another, and that a claim reciting a "plurality of elongated members" might cover the same structure as one describing "an array of fins." General-purpose embeddings miss these domain-specific equivalences at a rate that makes them unsuitable for production FTO work.
Automated Claim Element Mapping
Once a semantic search identifies a set of potentially relevant patents, the next step in any FTO analysis is claim mapping: comparing each element of the relevant patent claims against each feature of the product or process under review. This has traditionally been one of the most time-consuming and expertise-intensive steps in the FTO workflow, requiring a trained analyst to read each claim, decompose it into its constituent elements, and assess whether the product reads on those elements.
AI-powered claim mapping tools can now automate the initial pass of this analysis. These tools parse patent claims into individual elements, extract the corresponding features from a product description, and generate a preliminary mapping that highlights areas of potential overlap. Verticalized LLMs are particularly effective at this task because they can interpret the functional language and structural relationships embedded in patent claims with far greater accuracy than general-purpose models that lack exposure to the syntactic conventions of patent drafting. The output is not a final legal opinion, but it dramatically reduces the time required to triage a large set of potentially relevant patents down to a manageable shortlist of those that require detailed human review. For FTO searches that surface hundreds or even thousands of candidate patents from the initial semantic search, this triage step is essential to making the workflow practical.
Classification-Based Filtering and Clustering
Patent classification systems such as the Cooperative Patent Classification (CPC) and the International Patent Classification (IPC) provide a structured taxonomy that assigns each patent to one or more technology categories. While classification codes are not a substitute for full-text search, they are a powerful complement, especially for narrowing the initial scope of an FTO search to the most relevant technology areas.
AI-enhanced clustering takes this a step further. Rather than relying on the classification codes assigned by patent office examiners, machine learning algorithms can analyze the full text of search results and automatically cluster them into thematic groups based on their technical content. This allows the analyst to see at a glance which technology sub-areas are most densely populated with potentially relevant patents and to prioritize review accordingly. It also reveals patterns that might not be visible in a flat list of results, such as a concentration of filings from a particular competitor in a specific sub-technology that warrants closer scrutiny. The best clustering implementations use domain-specific ontologies rather than generic topic models, because a general-purpose topic model may group patents by surface-level keyword similarity rather than by the deeper technical relationships that matter for infringement analysis.
Citation Network Analysis
Patents do not exist in isolation. Each patent cites prior art references, and each patent is in turn cited by later filings. This web of citations creates a network that contains valuable information about the relationships between inventions, the evolution of a technology area, and the relative importance of individual patents within the landscape. AI-powered citation analysis tools can traverse this network to identify patents that are highly cited (suggesting broad influence), patents that share citation patterns with the product under review (suggesting technical proximity), and patents that have been cited in opposition or post-grant proceedings (suggesting contested validity).
Citation network analysis is particularly valuable for uncovering "hidden" prior art, meaning patents that would not surface through a keyword or semantic search because they use entirely different terminology but are technically relevant based on their position in the citation graph. For FTO searches in mature technology areas with deep citation histories, this technique can surface blocking patents that other methods would miss.
Incorporating Non-Patent Literature into FTO Workflows
One of the most significant blind spots in traditional FTO searches is the exclusive focus on patent data. A thorough clearance analysis must also consider non-patent literature (NPL), including scientific journal articles, conference proceedings, technical standards, and regulatory filings. NPL is relevant to FTO in two distinct ways. First, NPL may constitute prior art that could be used to invalidate a blocking patent, thereby eliminating the infringement risk. Second, NPL may describe the state of the art in ways that inform claim interpretation, helping the analyst understand the scope of a patent claim in the context of what was known at the time of filing.
The challenge is that non-patent literature exists in entirely separate databases from patent data, uses different terminology conventions, and is structured differently. Most traditional patent search tools do not index scientific literature at all, forcing analysts to conduct separate searches across multiple platforms and then manually correlate the results. AI-powered platforms that unify patent and scientific literature into a single searchable corpus eliminate this fragmentation and allow the analyst to see the full picture of the prior art landscape in a single workflow. This is an area where the choice of platform matters enormously: the ability to run a single semantic query across both patent and NPL data, and to have the results ranked by a verticalized model that understands both document types, is a significant structural advantage over workflows that require separate tools and manual reconciliation.
Agentic AI and Multi-Step FTO Workflows
A newer development in AI-powered FTO is the emergence of agentic AI systems that can execute multi-step research workflows autonomously. Rather than requiring the analyst to manually sequence each step of the FTO process (define search terms, run the search, filter results, cluster by technology area, map claims, check legal status), an agentic system can accept a high-level task description (such as "conduct an FTO search for this product in these jurisdictions") and autonomously plan and execute the sequence of searches, filters, and analyses needed to produce a comprehensive result.
Agentic approaches are particularly valuable for FTO searches because the process inherently involves multiple dependent steps where the output of one step determines the input to the next. A well-designed agentic FTO system can dynamically expand or narrow its search based on what it finds at each stage, pursue unexpected leads surfaced by citation analysis, and flag ambiguities for human review rather than making assumptions. This represents a meaningful step beyond static search tools, though it also demands a higher level of trust in the underlying AI and places a premium on transparency and explainability in how the system arrives at its conclusions.
Continuous Monitoring: Transforming FTO from a Snapshot to a Living Process
A traditional FTO search produces a point-in-time snapshot: a report reflecting the patent landscape as it existed on the date the search was conducted. But the patent landscape is not static. New applications are published every week. Pending applications receive grants. Legal status changes as patents are challenged, abandoned, or expire. A critical, and often overlooked, part of a modern FTO strategy is to establish a system for continuous monitoring that transforms the FTO from a static report into a living intelligence system (5).
AI-powered monitoring tools allow teams to save their search parameters and receive automated alerts whenever new patents are published in their technology area, a key competitor files a new application, or the legal status of a previously identified high-risk patent changes. This continuous approach is especially important for products with long development cycles, where the patent landscape may shift significantly between the initial FTO search and the commercial launch date.
Hybrid Intelligence: Why AI Alone Is Not Enough
For all its power, AI is not a substitute for expert human judgment in FTO analysis. The future of IP analytics lies in integrating AI-driven scalability with human interpretative depth, as highlighted at major industry conferences exploring hybrid human-machine workflows for patent searching and FTO analysis (6). AI can process millions of documents, surface the most relevant candidates, and generate preliminary claim maps. But the final determination of whether a product infringes a patent claim requires legal interpretation that accounts for claim construction doctrines, prosecution history, and jurisdiction-specific rules of infringement analysis. These are judgments that require training, experience, and an understanding of legal context that current AI systems cannot reliably provide.
The most effective FTO methodology in 2026 is a hybrid model: AI handles the high-volume discovery, filtering, and triage phases, while human experts focus their attention on the relatively small number of patents that survive the AI filter and require detailed claim-by-claim analysis. This division of labor plays to the strengths of each. AI excels at scale, speed, and consistency across large datasets. Humans excel at nuanced interpretation, contextual reasoning, and the kind of strategic thinking that determines whether a potential infringement risk warrants a design-around, a licensing negotiation, or a validity challenge.
The USPTO Is Signaling the Direction of Travel
The United States Patent and Trademark Office has itself begun integrating AI into its examination processes, and these developments have direct implications for FTO practice. The USPTO launched its Automated Search Pilot Program (ASAP!) in October 2025, using an internal AI tool to conduct pre-examination prior art searches and provide applicants with an Automated Search Results Notice listing up to 10 relevant documents ranked by relevance (7). In July 2025, the USPTO launched the DesignVision tool, enabling AI-driven image-based search of U.S. and foreign design patents to support examiners in comparing query images to global design collections (8). And in March 2026, the agency launched its Class ACT system, an AI-powered tool that automates trademark classification tasks that previously took up to five months (9).
These initiatives signal that the patent office itself views AI-assisted search as a core component of the future examination process. For FTO practitioners, this raises the bar: if the patent office is using AI to find more and better prior art during examination, then the patents that survive this enhanced scrutiny and proceed to grant may be stronger and harder to challenge. This makes thorough, AI-augmented FTO searches even more critical before making go-to-market decisions.
Platforms for AI-Powered FTO Searches: What to Look For
Not all platforms are equally suited to FTO analysis on large datasets. When evaluating tools for this purpose, R&D and IP teams should prioritize several capabilities.
The first is data coverage. A platform is only as useful as the corpus it can search. The best FTO tools provide access to patent data from all major patent-issuing authorities worldwide, including full-text documents, legal status information, patent family linkages, and prosecution history. Equally important is coverage of non-patent literature, including peer-reviewed scientific journals and conference proceedings, which can be essential both for identifying prior art and for understanding claim scope.
The second is AI model quality. The platform's AI should be built on verticalized models trained specifically on patent and technical text, not repurposed general-purpose LLMs. It should support natural language queries, full-document input, and iterative refinement of search results based on user feedback.
The third is workflow integration. FTO analysis is not a single search query but a multi-step process that includes search, filtering, clustering, claim mapping, validity assessment, and reporting. The best platforms support this entire workflow in a unified environment rather than requiring the analyst to export data and switch between tools at each stage.
The fourth is monitoring and alerting. As discussed above, FTO is not a one-time event. The platform should support saved searches, automated alerts, and ongoing landscape tracking so that the initial FTO assessment remains current throughout the product development cycle.
With these criteria in mind, several platforms merit consideration for enterprise FTO workflows in 2026.
Cypris takes a structurally different approach from most patent intelligence tools by unifying patent data, scientific literature, and competitive intelligence into a single enterprise R&D intelligence platform. Cypris indexes over 500 million patents and scientific papers and applies a proprietary R&D ontology that maps relationships across data types, enabling searches that span the full spectrum of technical prior art in a single query. For FTO analysis specifically, this means an analyst can conduct the patent search, cross-reference the results against relevant scientific literature, and monitor the landscape for changes, all without leaving a single platform or reconciling outputs from multiple tools. Cypris maintains enterprise API partnerships with OpenAI, Anthropic, and Google, which positions it to integrate the latest advances in large language model technology directly into its search and analysis workflows as verticalized AI capabilities rather than generic chat interfaces bolted onto legacy data. It is trusted by hundreds of enterprise teams and thousands of researchers across R&D, IP, and product development functions. For organizations whose FTO needs extend beyond patent-only analysis into the broader question of what the full body of technical prior art looks like across both patent and non-patent sources, Cypris provides a unified foundation that eliminates the fragmentation inherent in multi-tool approaches (10).
Derwent Innovation from Clarivate is one of the longest-established platforms in the patent intelligence space. It provides access to a large global patent collection with strong coverage of the Derwent World Patents Index (DWPI), which includes human-written abstracts that standardize patent terminology across jurisdictions. Derwent Innovation is widely used by IP attorneys and patent professionals, and its strength lies in the depth of its curated data and its classification-enhanced search capabilities. However, Derwent Innovation is primarily a patent-focused tool. Its scientific literature integration is handled through a separate Clarivate product (Web of Science), which requires a distinct subscription and a separate search interface. For teams that need to search patents and scientific literature in a unified workflow, this two-product structure can add friction and increase the risk of gaps between the two datasets (11).
Google Patents is a free, publicly accessible patent search tool that covers patents from major jurisdictions worldwide. It has added basic semantic search capabilities in recent years and provides a useful starting point for initial FTO screening, particularly for teams with limited budgets. However, Google Patents has significant limitations for enterprise FTO work. It does not provide legal status tracking, patent family visualization, automated monitoring, or claim mapping tools. It does not index scientific literature. And it does not offer API access for integration into automated workflows. Google Patents is best understood as a supplementary resource rather than a primary FTO platform (12).
The Lens is an open-access platform that provides a unified search across patents, scholarly articles, and biological sequences. It is operated by Cambia, a nonprofit organization, and its commitment to open data access makes it a valuable resource for teams that want to cross-reference patent and literature data without separate subscriptions. The Lens offers structured metadata, patent family linkages, and basic visualization tools. Its limitations for enterprise FTO work center on the absence of advanced AI search capabilities, automated claim mapping, and the kind of continuous monitoring infrastructure that large R&D organizations require (13).
PQAI (Patent Quality AI) is an open-source project that applies machine learning to patent prior art search. It offers semantic similarity search trained on patent text and allows users to input invention disclosures as natural language queries. PQAI is a useful tool for technology scouting and initial prior art screening, but it is primarily focused on prior art discovery rather than full FTO analysis, and it lacks the enterprise features (monitoring, claim mapping, legal status tracking, team collaboration) required for production FTO workflows (14).
Scite takes a different approach, focusing on scientific literature rather than patents. Scite's AI analyzes citation contexts to determine whether a citing paper supports, contradicts, or simply mentions a cited claim. For FTO workflows that require deep analysis of the non-patent literature, particularly in life sciences and pharmaceuticals where journal publications play a critical role in establishing the state of the art, Scite provides a layer of intelligence that patent-focused tools do not offer (15).
Building an Effective FTO Workflow for Large Datasets in the Age of AI
The platforms discussed above are tools, not solutions in themselves. An effective FTO workflow on large datasets requires a structured methodology that sequences the right techniques in the right order, and an understanding of where general-purpose AI, verticalized AI, and human expertise each contribute the most value.
The first phase is scoping. Before any search begins, the team must define the product or process features to be cleared, the jurisdictions of interest, and the relevant time window (typically patents filed within the last 20 years, adjusted for patent term extensions). General-purpose LLMs can be useful at this stage for brainstorming potential claim interpretations, generating alternative descriptions of the product's features, and identifying adjacent technology areas that might harbor relevant patents. Clear scoping prevents the search from expanding into irrelevant technology areas and ensures that the results are actionable.
The second phase is broad discovery. This is where verticalized AI delivers the most value. The analyst inputs the product description or claim set into a platform powered by domain-specific models and runs a broad semantic search across the full patent corpus, supplemented by classification-based filtering and citation network analysis. The goal is to cast a wide net and capture every potentially relevant reference. Using a general-purpose chatbot for this step is inadequate because it cannot search live patent databases, verify legal status, or rank results using patent-trained embeddings.
The third phase is AI-assisted triage. The results of the broad discovery phase will typically number in the hundreds or thousands. AI clustering and preliminary claim mapping tools reduce this set to a manageable shortlist of patents that warrant detailed human review. Documents that are clearly irrelevant, expired, or directed to a different technology are filtered out automatically. Agentic AI systems can further accelerate this phase by autonomously pursuing follow-up searches on the most promising clusters and flagging ambiguities for human attention.
The fourth phase is expert analysis. The shortlisted patents are reviewed in detail by a qualified patent professional who constructs claim charts, assesses infringement risk under the applicable legal standards, and evaluates the validity of any blocking patents. This is the step where human judgment is indispensable. No AI system, however sophisticated, should be the sole basis for a go/no-go commercialization decision.
The fifth phase is continuous monitoring. The search parameters from the initial analysis are saved and configured to generate automated alerts. The FTO assessment becomes a living document that is updated as the patent landscape evolves.
The Cost of Getting FTO Wrong
The consequences of an inadequate FTO search are not abstract. Patent infringement lawsuits named 1,889 defendants in a recent reporting period, a 21.6 percent increase over the prior year (8). Even a single overlooked patent can delay a product launch, trigger costly litigation, or force an expensive redesign after manufacturing has already begun. The investment in AI-augmented FTO tools and methodologies is small relative to the risk it mitigates.
For R&D organizations operating in technology areas with dense patent landscapes, such as semiconductors, pharmaceuticals, telecommunications, and advanced materials, the question is no longer whether to adopt AI-powered FTO methods but how quickly the transition from manual-only workflows can be completed. The data volumes, jurisdictional complexities, and competitive stakes of 2026 demand it. And the distinction between using a general-purpose chatbot to "ask about patents" and deploying a verticalized AI platform purpose-built for patent intelligence is the difference between a defensible FTO process and an expensive false sense of security.
Citations
(1) WIPO, "World Intellectual Property Indicators 2025: Patents Highlights," November 2025. https://www.wipo.int/web-publications/world-intellectual-property-indicators-2025-highlights/en/patents-highlights.html
(2) WIPO, "IP Facts and Figures 2025," 2025. https://www.wipo.int/edocs/pubdocs/en/wipo-pub-943-2025-en-wipo-ip-facts-and-figures-2025.pdf
(3) WIPO, "IP Facts and Figures 2025: Patents and Utility Models," 2025. https://www.wipo.int/web-publications/ip-facts-and-figures-2025/en/patents-and-utility-models.html
(4) IPWatchdog, "Agentic AI Meets Patent Search: A New Paradigm for Innovation," October 2025. https://ipwatchdog.com/2025/10/30/agentic-ai-meets-patent-search-new-paradigm-innovation/
(5) DrugPatentWatch, "Conducting a Biopharmaceutical Freedom-to-Operate (FTO) Analysis," 2025. https://www.drugpatentwatch.com/blog/conducting-a-biopharmaceutical-freedom-to-operate-fto-analysis-strategies-for-efficient-and-robust-results/
(6) ScienceDirect, "AI, Hybrid Intelligence, and the Future of Patent Analytics: Key Takeaways from the CEPIUG 17th Anniversary Conference," February 2026. https://www.sciencedirect.com/science/article/abs/pii/S017221902600013X
(7) Morgan Lewis, "USPTO Announces Automated Search Pilot Program," October 2025. https://www.morganlewis.com/pubs/2025/10/uspto-announces-automated-search-pilot-program
(8) Lumenci, "AI-Powered Freedom to Operate: Streamlining Patent Risk Analysis," November 2025. https://lumenci.com/blogs/ai-assisted-fto-search/
(9) Sterne Kessler, "USPTO Launches AI Examination Tools: What This Means for Trademark Applicants," March 2026. https://www.sternekessler.com/news-insights/insights/uspto-launches-ai-examination-tools-what-this-means-for-trademark-applicants/
(10) Cypris. https://cypris.ai
(11) Clarivate, Derwent Innovation. https://clarivate.com/products/ip-intelligence/patent-intelligence/derwent-innovation/
(12) Google Patents. https://patents.google.com
(13) The Lens, Cambia. https://www.lens.org
(14) PQAI (Patent Quality AI). https://projectpq.ai
(15) Scite. https://scite.ai
FAQ
What is a freedom-to-operate search?A freedom-to-operate search, also called an FTO search or patent clearance search, is an investigation of existing and pending patents to determine whether a product, process, or technology can be commercialized in a specific jurisdiction without infringing the valid intellectual property rights of a third party. It is distinct from a patentability search, which evaluates whether an invention is novel enough to receive its own patent. FTO analysis focuses specifically on infringement risk and is typically conducted before major investment decisions such as product launch, manufacturing scale-up, or market entry.
Why are large datasets a challenge for FTO searches?Global patent filings reached 3.7 million applications in 2024, and an estimated 19.7 million patents are currently in force worldwide. This corpus spans hundreds of patent-issuing authorities, multiple languages, and decades of filing history. Traditional keyword searches require the analyst to anticipate every possible phrasing a patent drafter might have used, which becomes impractical at this scale. AI-powered semantic search addresses this by understanding conceptual meaning rather than matching exact text strings, enabling the analyst to surface relevant references even when the terminology differs from the search query.
Can I use ChatGPT or another general-purpose LLM for FTO searches?General-purpose LLMs like ChatGPT, Claude, or Gemini can be helpful for background research, brainstorming search strategies, and explaining technical concepts to non-specialist stakeholders. However, they are not suitable as the primary engine of an FTO search. They do not have access to live patent databases, cannot verify legal status, are prone to hallucination, and lack the domain-specific training needed to interpret patent claim language with the precision FTO analysis demands. Verticalized AI models trained specifically on patent and scientific text, and integrated into platforms with access to structured patent data, are required for defensible FTO work.
What is a verticalized LLM and why does it matter for FTO?A verticalized LLM is a large language model that has been fine-tuned or trained specifically on domain-specific data, in this case patent documents, scientific literature, and technical taxonomies. These models understand the conventions of patent drafting, including how claim language maps to technical concepts, how dependent claims narrow independent claims, and how the same invention can be described using different vocabulary across jurisdictions. When integrated into a purpose-built patent search platform, verticalized LLMs perform semantic retrieval, claim decomposition, and relevance ranking at a level of precision that general-purpose models cannot match.
How does AI improve FTO search accuracy?AI improves FTO search accuracy in several ways. Semantic search identifies conceptually related patents that keyword searches miss. Automated claim mapping generates preliminary comparisons between patent claims and product features, speeding up the triage process. Citation network analysis uncovers patents that are technically relevant based on their position in the citation graph rather than their text alone. Classification-based clustering reveals patterns in the patent landscape that help the analyst prioritize review. And agentic AI systems can autonomously execute multi-step search workflows, dynamically adjusting their approach based on intermediate results. Together, these techniques reduce the risk of missing a blocking patent while also reducing the time and cost of the analysis.
Can AI replace human experts in FTO analysis?No. AI is a powerful tool for the discovery, filtering, and triage phases of FTO analysis, but the final determination of infringement risk requires legal judgment that accounts for claim construction, prosecution history, and jurisdiction-specific rules. The most effective FTO methodology combines AI-driven discovery with expert human analysis in a hybrid model. AI processes the volume; humans apply the judgment.
When should an FTO search be conducted?FTO searches should be conducted early in the product development process, ideally before significant investments in design, tooling, or manufacturing. Conducting FTO analysis at the ideation or early development stage allows the team to identify potential patent obstacles while there is still time and flexibility to design around them, seek licenses, or challenge the validity of blocking patents. FTO analysis should also be refreshed at major development milestones and before commercial launch, as the patent landscape may have changed since the initial search.
What is the difference between semantic search and keyword search for patents?Keyword search matches exact text strings in patent documents. If a patent uses the term "optical waveguide" but the search query uses "fiber optic channel," a keyword search will not find the match. Semantic search uses natural language processing to understand the conceptual meaning of both the query and the documents, enabling it to recognize that these two phrases describe the same concept. For FTO searches across large, multilingual patent datasets, semantic search provides significantly broader coverage than keyword-only approaches.
How does non-patent literature factor into FTO analysis?Non-patent literature, including scientific journal articles, conference proceedings, and technical standards, is relevant to FTO in two ways. First, it may constitute prior art that can be used to invalidate a blocking patent, eliminating the infringement risk. Second, it provides context about the state of the art at the time a patent was filed, which can inform claim interpretation and scope analysis. Platforms that unify patent and scientific literature in a single search interface eliminate the need to conduct separate searches across different databases and reduce the risk of gaps.
What is continuous FTO monitoring and why does it matter?Continuous FTO monitoring means saving the search parameters from an initial FTO analysis and configuring automated alerts for changes in the patent landscape. These alerts can notify the team when new patents are published in the relevant technology area, when a competitor files a new application, or when the legal status of a previously identified patent changes. This transforms the FTO assessment from a one-time snapshot into a living intelligence system that keeps pace with the evolving patent landscape throughout the product development cycle.
How many jurisdictions should an FTO search cover?An FTO search should cover every jurisdiction where the product will be manufactured, sold, imported, or used. At a minimum, this typically includes the United States, Europe (via the European Patent Office), China, Japan, and South Korea for technology products with global distribution. PCT applications should also be monitored, as an international filing may enter the national phase in any member country. The specific jurisdictional scope depends on the company's commercialization plans and supply chain geography.
What should I look for in an AI-powered FTO platform?The most important capabilities for an enterprise FTO platform are comprehensive global patent data coverage, high-quality semantic search powered by verticalized models trained on patent text, non-patent literature integration, automated claim mapping and clustering tools, legal status tracking, patent family visualization, continuous monitoring and alerting, API access for workflow automation, and enterprise-grade security. Platforms that unify patent and scientific literature search in a single interface and leverage domain-specific AI rather than generic general-purpose models provide the strongest foundation for defensible FTO analysis at scale.

Clarivate is not a single product. It is a portfolio of acquired tools assembled over decades, and the two platforms that enterprise R&D teams use most frequently — Derwent Innovation for patent intelligence and Web of Science for scientific literature — were designed for entirely different audiences with entirely different workflows. Derwent was built for IP attorneys conducting freedom-to-operate searches. Web of Science was built for academic librarians and university researchers. Neither was built for the R&D scientist trying to answer a strategic question about a technology landscape, a competitive portfolio, or an emerging technical risk.
The gap between what Clarivate's R&D-adjacent tools were designed to do and what modern innovation teams actually need is the primary reason organizations are evaluating alternatives. This guide examines six of the strongest alternatives to Clarivate for enterprise R&D and IP teams, explains what distinguishes each platform, and provides a framework for matching your team's specific requirements to the right solution.
Why R&D Teams Are Reevaluating Clarivate
Clarivate's position in the market is the product of consolidation, not native product design. The company was spun out of Thomson Reuters' IP and Science division in 2016 and has since assembled its portfolio through a series of acquisitions — Derwent, Web of Science, ProQuest, Cortellis, and others — without fully integrating the underlying data architectures. For R&D teams, the practical consequence is that patent intelligence and scientific literature intelligence live in separate platforms with separate subscriptions, separate interfaces, and separate learning curves.
This fragmentation has real costs. An R&D scientist conducting a technology scouting exercise needs to understand what has been patented, what has been published in the scientific literature, and how those two bodies of knowledge relate to each other. Performing that analysis through Derwent and Web of Science requires toggling between platforms, manually reconciling results, and building synthesis layers that neither tool provides natively. The time investment alone is a meaningful barrier, and the cognitive load of maintaining fluency in two complex legacy interfaces reduces the frequency with which R&D teams can turn to patent and literature intelligence for decision support.
Pricing is a compounding factor. Clarivate's enterprise contracts for combined Derwent and Web of Science access can run into six figures annually, and the terms typically require institutional commitment rather than flexible per-seat or usage-based arrangements. For Fortune 500 R&D organizations that have historically lived with the cost because no integrated alternative existed, the rapid maturation of AI-native intelligence platforms over the past three years has changed the evaluation calculus significantly.
There is also a structural concern specific to Derwent. Clarivate's Derwent World Patents Index is maintained by a team of over 800 patent editors who manually write abstracts for each invention family — a curation model that represents both the platform's greatest strength and its most significant vulnerability. The value of Derwent has always rested on human expertise applied at scale. As AI-native platforms develop increasingly sophisticated capabilities for patent comprehension and synthesis, the competitive differentiation of hand-written abstracts is narrowing, and the cost premium associated with that curation model becomes harder to justify for teams whose primary need is strategic intelligence rather than legal-quality prior art analysis.
What to Look for in a Clarivate Alternative
Before evaluating specific platforms, it is worth being precise about what Clarivate's R&D-adjacent products actually do, because the alternatives that best address those functions are not necessarily the platforms that appear most often in head-to-head comparison articles.
Derwent Innovation provides access to the Derwent World Patents Index, a curated database covering over 130 million patents, along with tools for patent search, analytics, portfolio management, and competitive landscaping. Its primary design center is the patent professional: the interface and workflows are optimized for freedom-to-operate analyses, patentability assessments, and portfolio strategy decisions that require high-confidence data quality.
Web of Science provides access to a peer-reviewed scientific literature database covering approximately 20,000 journals, along with citation analytics, research performance metrics, and discovery tools. Its primary design center is the academic researcher and institutional library administrator.
An effective Clarivate alternative for an enterprise R&D team needs to cover both functions, ideally within a unified architecture, and needs to provide the kind of strategic synthesis and workflow integration that neither Derwent nor Web of Science was designed to deliver. The evaluation criteria that matter most are unified data architecture, native AI capabilities, scientific literature depth alongside patent coverage, enterprise security posture, and whether the platform was designed for R&D scientists and innovation strategists or for IP attorneys and academic administrators.
The Best Clarivate Alternatives for Enterprise R&D Teams
Cypris — Best Unified Platform for Enterprise R&D Intelligence
Cypris takes a fundamentally different approach to R&D intelligence than Clarivate's two-platform model. Rather than providing a patent database and a literature database as separate tools, Cypris unifies over 500 million patents and scientific papers within a single platform, structured through a proprietary R&D ontology that understands the relationships between technical concepts across both corpora. The result is that searches and analyses performed in Cypris return integrated results from patents and scientific literature simultaneously, without requiring the researcher to reconcile findings from separate systems.
The distinction is not merely a user experience improvement. When patent data and scientific literature are indexed through a shared ontology rather than maintained in separate silos, the analytical possibilities expand substantially. A technology scouting exercise can reveal not just what has been patented in a domain but what the concurrent scientific literature suggests about the direction of technical development, where the patent portfolio is leading versus lagging the research frontier, and which organizations are accumulating both IP and publication activity in emerging areas. These cross-signal insights are structurally unavailable in a Derwent-plus-Web-of-Science architecture because the data models do not share a common semantic layer.
Cypris is trusted by hundreds of enterprise teams and thousands of researchers across R&D, IP, and product development functions, including organizations in the Fortune 500. The platform's AI architecture is built on official enterprise API partnerships with OpenAI, Anthropic, and Google — partnerships that distinguish it from platforms that have layered general-purpose AI onto legacy data infrastructure without formal integration agreements. Enterprise security meets Fortune 500 requirements, addressing the compliance and data governance requirements that govern platform adoption decisions at large corporations.
For organizations that have historically maintained separate Derwent and Web of Science subscriptions, Cypris offers the possibility of consolidating that intelligence infrastructure into a single platform while simultaneously gaining access to AI capabilities that neither legacy tool provides. The platform's Research Brief service extends beyond self-service search to provide bespoke analysis by Cypris research analysts, which addresses the capacity constraint that limits how frequently in-house teams can conduct deep landscape analyses.
Google Patents — Best Free Option for Preliminary Research
Google Patents provides free access to patent documents from major patent offices worldwide, with an interface that will be immediately familiar to anyone comfortable with Google's search products. The platform indexes over 87 million patents and offers some integration with Google Scholar to bring non-patent literature into search results.
For preliminary research, competitive screening, and exploratory work, Google Patents offers genuine utility. The familiar search interface eliminates the training investment required by Derwent and Orbit, and the zero-cost access model makes it available to anyone in an R&D organization without procurement friction. Translation capabilities allow English-language searches to surface relevant patents from non-English-language jurisdictions, which addresses one of the more significant practical limitations of manual prior art searching.
The gap between Google Patents and enterprise-grade intelligence platforms is most visible in the analytics layer. Google Patents is a document retrieval tool. It does not offer patent landscaping, portfolio analytics, competitive benchmarking, or AI-powered synthesis — the capabilities that allow R&D teams to extract strategic insights from patent data rather than simply locating relevant documents. For organizations that have been paying Clarivate prices, the step down to Google Patents represents a significant reduction in capability even as it eliminates license costs entirely. It functions well as a complement to an enterprise platform for quick searches, but not as a replacement for the strategic intelligence that Derwent and Web of Science provide in combination.
The Lens — Best Free Platform for Combined Patent and Literature Access
The Lens is the most capable free alternative for organizations that need both patent and scientific literature access without a commercial subscription. The platform provides open access to over 300 million patent records and more than 200 million scientific documents, making it the most comprehensive free resource available for the combined research task that Derwent and Web of Science together currently serve
What distinguishes The Lens from other free tools is its integration philosophy. Patent records and scholarly works are available within the same interface, and The Lens supports citation analysis linking patents to the scientific literature they cite and vice versa. This cross-domain citation capability partially replicates one of the most valuable analytical functions in a combined Derwent and Web of Science environment — understanding how patent filings and published research co-evolve in a technology area.
The Lens operates under an open-access mission and is supported by charitable foundations rather than commercial subscription revenue, which means its development roadmap and feature investment are less predictable than those of commercial platforms. The analytical tools are more limited than those available in Orbit or enterprise platforms, and there is no AI-powered synthesis capability comparable to what modern commercial platforms provide. For budget-constrained teams or organizations beginning to build a patent and literature intelligence practice before committing to enterprise platform investments, The Lens represents a meaningful option. It is not a direct substitute for the combined capability of Clarivate's R&D suite, but it provides a more complete free alternative than any other single platform.
PQAI — Best Open-Source AI Patent Search
PQAI is an open-source patent search platform built on an AI-first philosophy that removes the requirement for Boolean search expertise. Researchers can submit queries in natural language and receive relevant patent results without building complex search strings or learning classification system syntax. The platform includes a prior art search API that allows R&D and legal teams to embed patent intelligence directly into their workflows rather than requiring researchers to visit a separate interface.
For organizations where the primary limitation of Derwent and other legacy platforms has been the training barrier — the reality that effective use requires significant investment in Boolean search and classification system expertise — PQAI offers a genuinely different user experience. Its accessibility makes patent intelligence available to R&D scientists who would not typically engage with Derwent's professional-grade interface.
PQAI's scope is narrower than Clarivate's R&D suite. It does not include scientific literature, and its analytical capabilities are more limited than those of commercial platforms. It is most appropriately used as a prior art search and patent discovery tool rather than as a strategic intelligence platform. PQAI fits best in organizations where patent accessibility is the primary unmet need and where the R&D intelligence use case is being built incrementally rather than addressed through a comprehensive platform investment.
Scite — Best for Citation Intelligence
Scite addresses the scientific literature dimension of the Clarivate suite more directly than any other alternative on this list. The platform provides access to over 1.2 billion citation statements from the scientific literature, with AI-powered analysis of whether each citation supports, contrasts, or simply mentions the cited work. This distinction between supporting and contrasting citations transforms citation analysis from a quantitative measure of research influence into a qualitative map of scientific consensus and controversy — a capability that Web of Science's citation analytics does not provide.
For R&D teams whose primary use of Web of Science is tracking the scientific literature in their technology domains, understanding where expert consensus is solidifying versus where debates remain open, and identifying emerging research directions before they appear in patent filings, Scite's citation intelligence capability offers something meaningfully different from what Web of Science delivers. It is a tool oriented around scientific understanding rather than research performance metrics.
Scite does not address the patent dimension of the Clarivate use case, and its data coverage, while extensive, is focused on the scholarly literature rather than the full breadth of technical documentation that platforms like Cypris access. Organizations replacing a combined Derwent and Web of Science subscription will need to address the patent intelligence requirement separately if they select Scite for the literature component. It is most appropriately positioned as a supplement to an enterprise intelligence platform or as a specialized tool for scientific literature analysis within a broader technology monitoring program.
Choosing the Right Alternative
The right Clarivate alternative depends on which parts of the R&D intelligence workflow the current Clarivate subscription is actually serving and what the primary failure modes of the existing setup are.
For organizations that use Derwent and Web of Science as integrated inputs into technology scouting, competitive landscape analysis, and R&D investment decisions, the most important criterion is unified data architecture. Platforms that treat patents and scientific literature as separate databases with separate interfaces recreate the fragmentation that makes Clarivate's two-platform model difficult to use efficiently. The relevant question is not which alternative is best at patents and which is best at literature, but which alternative treats them as components of a single intelligence layer.
For organizations that use Clarivate primarily for patent prosecution support, freedom-to-operate analysis, and legal-quality prior art searching, the relevant alternatives are different. The data quality and curation precision of Derwent's human-written abstracts matter significantly for legal applications in ways they do not for strategic R&D applications, and the evaluation should weight Orbit Intelligence's capabilities more heavily.
For organizations with constrained budgets exploring their options before committing to enterprise platform investments, the combination of The Lens for free patent and literature access and Scite for citation intelligence provides a meaningful foundation. Neither platform alone replicates Clarivate's combined capability, but together they address the core discovery and analysis functions at no cost.
The broader pattern in how enterprise R&D teams are evaluating this market is a shift toward platforms that were designed for scientists and innovation strategists rather than platforms originally designed for attorneys and academic administrators. Clarivate's core products are genuinely excellent at what they were built to do. The question organizations are asking is whether what they were built to do maps onto what modern enterprise R&D functions actually need — and increasingly, the answer is that the fit is incomplete.
Frequently Asked Questions
What is Clarivate used for in enterprise R&D?
In enterprise R&D contexts, Clarivate is most commonly used through two products: Derwent Innovation for patent search and analytics, and Web of Science for scientific literature access and citation analysis. R&D teams use these tools for technology scouting, competitive landscape analysis, prior art research, and tracking the scientific literature in their technology domains. Because these products are sold as separate subscriptions with separate interfaces, organizations often maintain both to cover the full range of patent and literature intelligence tasks, which creates workflow fragmentation and a combined cost that enterprise R&D teams are increasingly questioning as AI-native unified platforms have matured.
How does Derwent Innovation compare to other patent platforms?
Derwent Innovation's primary differentiator is the Derwent World Patents Index, a curated database in which human patent editors write standardized abstracts for each invention family. These hand-written abstracts improve search precision and patent comprehension, particularly in complex technical domains. The platform covers over 130 million patents and is used by more than 40 national patent offices. Its limitations relative to modern alternatives include a traditional interface designed for IP attorneys rather than R&D scientists, the absence of native scientific literature integration, and a cost structure that reflects its premium data curation model. AI-native platforms increasingly challenge its differentiation by offering sophisticated natural language search and synthesis capabilities that reduce the practical advantage of manually curated abstracts for strategic R&D applications.
Is there a free alternative to Clarivate for R&D research?
The Lens provides the most comprehensive free alternative for the combined patent and scientific literature access that Derwent and Web of Science together currently serve. It covers over 300 million patent records and more than 200 million scholarly documents within a single interface and supports citation analysis linking patents to the scientific literature they cite. PQAI is a capable free option specifically for prior art patent search using natural language queries. Google Patents remains useful for preliminary patent research. None of these free options replicates the analytical capabilities and AI-powered synthesis available in enterprise platforms, but they provide meaningful starting points for organizations building their R&D intelligence practice.
Why are R&D teams replacing Clarivate with AI-native platforms?
The primary reasons R&D teams are evaluating AI-native alternatives to Clarivate center on three limitations of the current platform architecture. First, Derwent and Web of Science are separate products that do not share a unified data model, which requires manual synthesis when both patent and literature intelligence are needed for the same analysis. Second, both platforms were designed for IP attorneys and academic researchers respectively, and their interfaces and analytical tools reflect those use cases rather than the workflow of an R&D scientist or innovation strategist. Third, AI-native platforms have developed sufficient capability in natural language patent search, landscape synthesis, and cross-domain analysis to reduce the competitive advantage of Derwent's manual curation model for strategic R&D applications, while offering workflow integration and AI synthesis capabilities that Clarivate's tools do not provide.
What should enterprise teams prioritize when evaluating Clarivate alternatives?
Enterprise teams should prioritize unified data architecture above other criteria when evaluating Clarivate alternatives. Platforms that treat patents and scientific literature as separate data sources with separate interfaces recreate the fragmentation problem that is the primary operational limitation of the Clarivate suite. After data architecture, the relevant evaluation criteria are native AI capabilities and the quality of synthesis they enable, enterprise security posture and compliance certifications, scientific literature depth alongside patent coverage, and whether the platform's design orientation matches the actual users — R&D scientists and innovation strategists rather than IP attorneys. Cost structure and contract flexibility are also significant considerations given the high annual cost of Clarivate enterprise subscriptions.
Chemical R&D, drug discovery, and advanced materials teams face a search problem that most software fail to solve in one place: the chemistry that matters is spread across patents, scientific papers, and chemical structure databases at once. A single relevant compound may be claimed in a recent patent, described in a preprint or journal article, and registered in a structure database under a different name. Answering a real research question, whether a compound is novel, whether a route is protected, whether a class of molecules is crowded, requires connecting all three sources. Software that searches only patents, or only scientific literature, or only chemical structures leaves the team to run separate searches and reconcile the results by hand.
The core requirement is therefore not a better single-source search but a unified one. Software that searches patents, scientific papers, and chemical structures together has to treat them as one connected corpus rather than three silos: chemical structure and substructure search on one side, semantic search across patents and scientific literature on the other, and an R&D ontology underneath that understands how a compound, its uses, and its surrounding technology relate. That is what turns a structure query into an entry point into the patents and papers where the chemistry actually appears, instead of a lookup against a single isolated database.
This article explains how combined patent, scientific paper, and chemical structure search works, why the tools most teams use cover only part of it, and how an AI R&D intelligence approach unifies the three. It is written for chemical R&D and IP teams evaluating how to search chemistry across patents and literature without stitching tools together manually.
Why patents, papers, and chemical structures live in separate tools
The fragmentation is historical, not deliberate. Patent chemical structure search, scientific literature search, and compound databases grew up as separate resources, each excellent at its own slice. The free landscape shows the pattern clearly. SureChEMBL, maintained by the European Bioinformatics Institute, extracts chemical structures from patent documents and makes them searchable by structure, substructure, or structure combined with keywords, holding roughly 17 million compounds drawn from around 14 million patent documents. WIPO PATENTSCOPE offers a free chemical compound structure search across its international patent collection for registered users. PubChem, from the US National Institutes of Health, supports structure search across both patent and non-patent documents and adds biological activity data. The Lens links patents to the scholarly literature behind them.
Each of these is genuinely useful, and each covers one part of the problem. None unifies chemical structure search, patent search, and scientific-paper search into a single connected workflow. A team relying on them runs a structure search in one tool, a patent search in another, and a literature search in a third, then reconciles the overlaps manually, which is slow and prone to missed connections precisely where chemical naming differs across sources. The gap is not any single tool's coverage; it is the seam between them.
How chemical structure search works, and why it beats name search
Chemical structure search matches molecules by their structure rather than by name, which matters because a single compound is referred to inconsistently across patents and papers, by systematic name, trivial name, trade name, or registry number. A structure or substructure query sidesteps that variance. An exact-structure search finds a specific molecule; a substructure or scaffold search finds every molecule containing a defined core, which is how a team identifies a whole congeneric series rather than one compound at a time. For patent chemistry specifically, structure search is the reliable way to find where a compound is claimed or exemplified, because the same molecule may never be named the same way twice across a body of filings.
Structure search has a known limitation that any serious workflow must account for: when compounds are extracted from patent text and images automatically, the extraction can introduce errors, so a structure hit should be confirmed against the underlying patent before it is relied upon. This is a reason to connect structure search directly to the source patents and papers rather than treat a compound database as a standalone answer, and it is one of the advantages of software that unifies structures with the documents they came from.
Why semantic search and an R&D ontology are the connective layer
Structure search finds the compound; it does not find the surrounding knowledge. A compound identified in a patent is only useful in context: the scientific papers describing its synthesis and properties, the other patents claiming related molecules, the technology area it belongs to. Connecting a structure to that context requires searching patents and scientific literature by meaning, not by exact keyword, because chemical terminology is inconsistent and a keyword search misses relevant documents that describe the same chemistry in different words. Semantic search retrieves by meaning, which is what makes the link from a structure to its literature and patent context reliable.
An R&D ontology is the second half of the connective layer. An ontology encodes how compounds, uses, methods, and technologies relate, so a search returns a connected picture of a chemistry area rather than a flat list of documents that happen to share a term. Together, chemical structure search, semantic search, and an R&D ontology are what let one query span structures, patents, and scientific papers and return a unified result. Without semantic search and an ontology, combining the three sources remains a manual reconciliation task no matter how many databases a team has access to.
From structure search to prior art, FTO, and white space analysis
A combined patent, paper, and chemical structure search is rarely the end goal; it is the input to an IP or strategy decision. Once a structure search identifies where a compound or scaffold appears across patents and literature, the natural next steps are prior art search, freedom-to-operate (FTO) analysis, and white space analysis. Prior art asks whether the chemistry is novel. FTO asks whether commercializing it would infringe active patent claims. White space analysis asks whether a region of chemical and technology space is genuinely open, which for chemistry means checking scientific literature and commercial signals, not patents alone.
When structure search, patent search, and literature search sit in separate tools, each of these downstream steps requires re-exporting and re-searching, and the analysis fractures across platforms. When they sit in one environment, a structure-driven question flows directly into prior art, FTO, and white space analysis on the same connected corpus. That continuity is the practical payoff of unifying patents, papers, and chemical structures: the search and the decision it feeds happen in the same place.
Where Cypris fits
Cypris is an AI R&D intelligence platform built for exactly this unification. It ingests chemical structure data alongside a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology, so a chemical structure search becomes an entry point into the patents and scientific literature where that chemistry appears rather than a lookup against an isolated compound set. Semantic search across patents and scientific literature connects a structure to its context by meaning, even when terminology differs across assignees, authors, and jurisdictions.
Because the three sources sit in one environment, a structure-driven question moves directly into prior art, FTO, and white space analysis without leaving the platform. The agentic layer, Cypris Q, lets teams run multi-step search and analysis workflows in natural language across the combined corpus, and Agentic Monitoring keeps a compound class or technology area under continuous watch across patent offices, scientific literature, regulatory bodies, mergers and acquisitions, product launches, grant awards, and corporate news. Cypris offers enterprise-grade security and enterprise API partnerships with OpenAI, Anthropic, and Google, and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries. For chemical R&D and drug discovery teams whose questions span structure, patent, and literature at once, that unification removes the reconciliation step entirely.
Each compound page in our directory shows a slice of these connections: who is patenting, which classifications cluster, which research groups are active. You can browse it freely here.
FAQ
Is there software that searches patents, scientific papers, and chemical structures together? Yes. AI R&D intelligence platforms search patents, scientific papers, and chemical structures in one environment. Cypris ingests chemical structure data alongside a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, so a structure search connects directly to the patents and literature where that chemistry appears. Free tools such as SureChEMBL, WIPO PATENTSCOPE, PubChem, and The Lens each cover part of the problem but require manual reconciliation across them.
What software searches both patents and chemical structures? Software that searches patents and chemical structures together ranges from free resources to AI R&D intelligence platforms. SureChEMBL and WIPO PATENTSCOPE offer free chemical structure search over patents, and PubChem adds structure search across patent and non-patent literature. Cypris unifies chemical structure search with patent search and scientific-literature search in one platform, connecting a structure query to the patents and papers where the chemistry appears through a proprietary R&D ontology.
Can I search chemical structures in patents for free? Yes. SureChEMBL offers free chemical structure and substructure search across compounds extracted from patents, with roughly 17 million compounds from around 14 million patent documents. WIPO PATENTSCOPE provides free chemical compound structure search for registered users across its patent collection, and PubChem supports free structure search across patent and non-patent documents. These free tools are strong for structure search but do not unify patents, papers, and structures into one connected platform.
Which platform searches both scientific papers and chemical structures? Platforms that search both scientific papers and chemical structures connect chemistry data to scientific literature. Cypris does this by ingesting chemical structure data alongside a corpus of more than 500 million patents and scientific papers, so a compound query reaches the papers describing it. PubChem also links chemical structures to non-patent literature, and The Lens links patents to scholarly papers, though combining structure search and paper search across those free tools requires manual work.
Why do chemical R&D teams need patents, papers, and structures in one place? Chemical R&D, drug discovery, and materials teams need patents, papers, and chemical structures in one place because the relevant chemistry is spread across all three: a compound may be claimed in a patent, described in a paper, and registered in a structure database under a different name. Searching them separately forces manual reconciliation and risks missing connections where naming differs. A unified platform with structure search, literature search, and patent search under one R&D ontology removes that gap.
How does chemical structure search work? Chemical structure search matches molecules by their structure rather than by name. An exact-structure search finds a specific compound, while a substructure or scaffold search finds every molecule containing a defined core, which surfaces a whole series of related compounds. Structure search is more reliable than name search for patent chemistry because a single compound is named inconsistently across filings and papers. Automatically extracted structures should be verified against the source document before they are relied upon.
Does chemical structure search need semantic search too? Chemical structure search benefits greatly from semantic search over the surrounding patents and scientific literature, because chemical naming and terminology are inconsistent across patents, papers, and jurisdictions. Structure search finds the compound; semantic search finds the relevant documents describing it even when the wording differs. Cypris combines chemical structure search with semantic search across patents and scientific papers under a proprietary R&D ontology so results are connected by meaning.
How does chemical structure search connect to FTO and prior art? Chemical structure search identifies where a compound or scaffold appears in the patent and scientific record, which is the starting point for prior art and freedom-to-operate (FTO) analysis. A complete workflow moves from structure search to identifying the patents claiming the compound to assessing FTO risk against active claims. Cypris connects chemical structure search, prior art, FTO, and white space analysis in one R&D intelligence environment through its agentic layer, Cypris Q.
Are free chemical structure databases good enough for enterprise use? Free chemical structure databases such as SureChEMBL, WIPO PATENTSCOPE, and PubChem are valuable and widely used, and many teams rely on them for structure search. For enterprise use, however, they cover only parts of the problem and require manual reconciliation across structure, patent, and literature search, and they lack an R&D ontology, agentic workflows, continuous monitoring, and enterprise-grade security. Enterprise teams typically use them as inputs alongside a purpose-built platform.
How much data does Cypris search across patents, papers, and chemical structures? Cypris ingests chemical structure data alongside a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology so the platform understands how compounds, uses, and technologies relate. This lets Cypris connect a chemical structure search directly to the patents and scientific literature where that chemistry appears, and to prior art, FTO, and white space analysis, in a single environment.
Executive Summary
In 2024, US patent infringement jury verdicts totaled $4.19 billion across 72 cases. Twelve individual verdicts exceeded $100million. The largest single award—$857 million in General Access Solutions v.Cellco Partnership (Verizon)—exceeded the annual R&D budget of many mid-market technology companies. In the first half of 2025 alone, total damages reached an additional $1.91 billion.
The consequences of incomplete patent intelligence are not abstract. In what has become one of the most instructive IP disputes in recent history, Masimo’s pulse oximetry patents triggered a US import ban on certain Apple Watch models, forcing Apple to disable its blood oxygen feature across an entire product line, halt domestic sales of affected models, invest in a hardware redesign, and ultimately face a $634 million jury verdict in November 2025. Apple—a company with one of the most sophisticated intellectual property organizations on earth—spent years in litigation over technology it might have designed around during development.
For organizations with fewer resources than Apple, the risk calculus is starker. A mid-size materials company, a university spinout, or a defense contractor developing next-generation battery technology cannot absorb a nine-figure verdict or a multi-year injunction. For these organizations, the patent landscape analysis conducted during the development phase is the primary risk mitigation mechanism. The quality of that analysis is not a matter of convenience. It is a matter of survival.
And yet, a growing number of R&D and IP teams are conducting that analysis using general-purpose AI tools—ChatGPT, Claude, Microsoft Co-Pilot—that were never designed for patent intelligence and are structurally incapable of delivering it.
This report presents the findings of a controlled comparison study in which identical patent landscape queries were submitted to four AI-powered tools: Cypris (a purpose-built R&D intelligence platform),ChatGPT (OpenAI), Claude (Anthropic), and Microsoft Co-Pilot. Two technology domains were tested: solid-state lithium-sulfur battery electrolytes using garnet-type LLZO ceramic materials (freedom-to-operate analysis), and bio-based polyamide synthesis from castor oil derivatives (competitive intelligence).
The results reveal a significant and structurally persistent gap. In Test 1, Cypris identified over 40 active US patents and published applications with granular FTO risk assessments. Claude identified 12. ChatGPT identified 7, several with fabricated attribution. Co-Pilot identified 4. Among the patents surfaced exclusively by Cypris were filings rated as “Very High” FTO risk that directly claim the technology architecture described in the query. In Test 2, Cypris cited over 100 individual patent filings with full attribution to substantiate its competitive landscape rankings. No general-purpose model cited a single patent number.
The most active sectors for patent enforcement—semiconductors, AI, biopharma, and advanced materials—are the same sectors where R&D teams are most likely to adopt AI tools for intelligence workflows. The findings of this report have direct implications for any organization using general-purpose AI to inform patent strategy, competitive intelligence, or R&D investment decisions.

1. Methodology
A controlled comparative evaluation was conducted on March 27, 2026. An identical patent landscape query was submitted verbatim to each platform under standardized testing conditions. No follow-up prompts, clarifications, or iterative refinements were permitted, ensuring that each platform was evaluated based solely on its initial response.
The outputs were preserved in their original form and evaluated against predefined criteria using publicly verifiable patent records.
1.1 Query
Identify all active US patents and published applications filed in the last 5 years related to solid-state lithium-sulfur battery electrolytes using garnet-type ceramic materials. For each, provide the assignee, filing date, key claims, and current legal status. Highlight any patents that could pose freedom-to-operate risks for a company developing a Li₇La₃Zr₂O₁₂(LLZO)-based composite electrolyte with a polymer interlayer.
1.2 Tools Evaluated

1.3 Evaluation Criteria
Each response was evaluated using a consistent six-part scoring framework: patent coverage, assignee accuracy, filing metadata completeness, depth of claim analysis, quality of FTO risk stratification, and the presence of actionable strategic guidance.
Patent numbers, assignees, filing information, and legal status were independently checked against publicly available USPTO and WIPO records. The evaluation focused on the completeness, accuracy, and practical utility of each platform’s output rather than writing quality or presentation.
2. Findings
2.1 Coverage Gap
The most significant finding is the scale of the coverage differential. Cypris identified over 40 active US patents and published applications spanning LLZO-polymer composite electrolytes, garnet interface modification, polymer interlayer architectures, lithium-sulfur specific filings, and adjacent ceramic composite patents. The results were organized by technology category with per-patent FTO risk ratings.
Claude identified 12 patents organized in a four-tier risk framework. Its analysis was structurally sound and correctly flagged the two highest-risk filings (Solid Energies US 11,967,678 and the LLZO nanofiber multilayer US 11,923,501). It also identified the University ofMaryland/ Wachsman portfolio as a concentration risk and noted the NASA SABERS portfolio as a licensing opportunity. However, it missed the majority of the landscape, including the entire Corning portfolio, GM's interlayer patents, theKorea Institute of Energy Research three-layer architecture, and the HonHai/SolidEdge lithium-sulfur specific filing.
ChatGPT identified 7 patents, but the quality of attribution was inconsistent. It listed assignees as "Likely DOE /national lab ecosystem" and "Likely startup / defense contractor cluster" for two filings—language that indicates the model was inferring rather than retrieving assignee data. In a freedom-to-operate context, an unverified assignee attribution is functionally equivalent to no attribution, as it cannot support a licensing inquiry or risk assessment.
Co-Pilot identified 4 US patents. Its output was the most limited in scope, missing the Solid Energies portfolio entirely, theUMD/ Wachsman portfolio, Gelion/ Johnson Matthey, NASA SABERS, and all Li-S specific LLZO filings.
2.2 Critical Patents Missed by Public Models
The following table presents patents identified exclusively by Cypris that were rated as High or Very High FTO risk for the proposed technology architecture. None were surfaced by any general-purpose model.
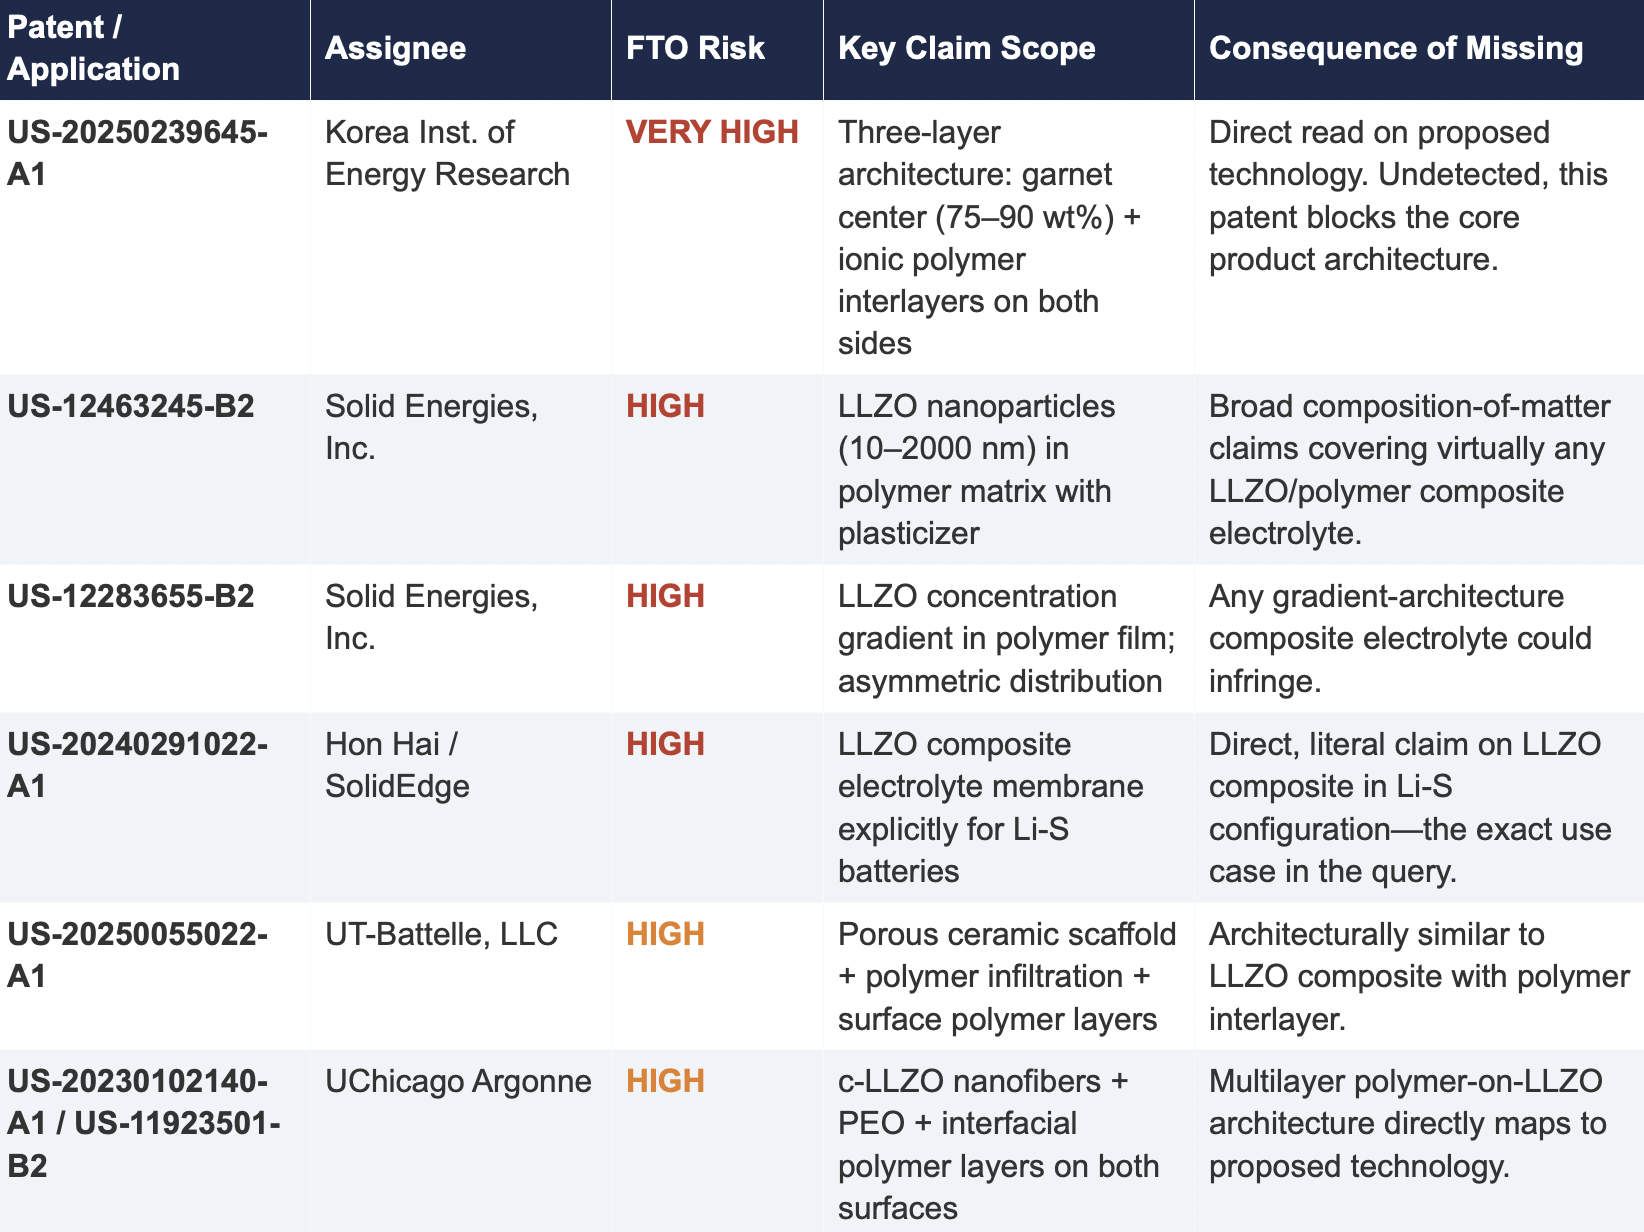
2.3 Patent Fencing: The Solid Energies Portfolio
Cypris identified a coordinated patent fencing strategy by Solid Energies, Inc. that no general-purpose model detected at scale. Solid Energies holds at least four granted US patents and one published application covering LLZO-polymer composite electrolytes across compositions(US-12463245-B2), gradient architectures (US-12283655-B2), electrode integration (US-12463249-B2), and manufacturing processes (US-20230035720-A1). Claude identified one Solid Energies patent (US 11,967,678) and correctly rated it as the highest-priority FTO concern but did not surface the broader portfolio. ChatGPT and Co-Pilot identified zero Solid Energies filings.
The practical significance is that a company relying on any individual patent hit would underestimate the scope of Solid Energies' IP position. The fencing strategy—covering the composition, the architecture, the electrode integration, and the manufacturing method—means that identifying a single design-around for one patent does not resolve the FTO exposure from the portfolio as a whole. This is the kind of strategic insight that requires seeing the full picture, which no general-purpose model delivered
2.4 Assignee Attribution Quality
ChatGPT's response included at least two instances of fabricated or unverifiable assignee attributions. For US 11,367,895 B1, the listed assignee was "Likely startup / defense contractor cluster." For US 2021/0202983 A1, the assignee was described as "Likely DOE / national lab ecosystem." In both cases, the model appears to have inferred the assignee from contextual patterns in its training data rather than retrieving the information from patent records.
In any operational IP workflow, assignee identity is foundational. It determines licensing strategy, litigation risk, and competitive positioning. A fabricated assignee is more dangerous than a missing one because it creates an illusion of completeness that discourages further investigation. An R&D team receiving this output might reasonably conclude that the landscape analysis is finished when it is not.
3. Structural Limitations of General-Purpose Models for Patent Intelligence
3.1 Training Data Is Not Patent Data
Large language models are trained on web-scraped text. Their knowledge of the patent record is derived from whatever fragments appeared in their training corpus: blog posts mentioning filings, news articles about litigation, snippets of Google Patents pages that were crawlable at the time of data collection. They do not have systematic, structured access to the USPTO database. They cannot query patent classification codes, parse claim language against a specific technology architecture, or verify whether a patent has been assigned, abandoned, or subjected to terminal disclaimer since their training data was collected.
This is not a limitation that improves with scale. A larger training corpus does not produce systematic patent coverage; it produces a larger but still arbitrary sampling of the patent record. The result is that general-purpose models will consistently surface well-known patents from heavily discussed assignees (QuantumScape, for example, appeared in most responses) while missing commercially significant filings from less publicly visible entities (Solid Energies, Korea Institute of EnergyResearch, Shenzhen Solid Advanced Materials).
3.2 The Web Is Closing to Model Scrapers
The data access problem is structural and worsening. As of mid-2025, Cloudflare reported that among the top 10,000 web domains, the majority now fully disallow AI crawlers such as GPTBot andClaudeBot via robots.txt. The trend has accelerated from partial restrictions to outright blocks, and the crawl-to-referral ratios reveal the underlying tension: OpenAI's crawlers access approximately1,700 pages for every referral they return to publishers; Anthropic's ratio exceeds 73,000 to 1.
Patent databases, scientific publishers, and IP analytics platforms are among the most restrictive content categories. A Duke University study in 2025 found that several categories of AI-related crawlers never request robots.txt files at all. The practical consequence is that the knowledge gap between what a general-purpose model "knows" about the patent landscape and what actually exists in the patent record is widening with each training cycle. A landscape query that a general-purpose model partially answered in 2023 may return less useful information in 2026.
3.3 General-Purpose Models Lack Ontological Frameworks for Patent Analysis
A freedom-to-operate analysis is not a summarization task. It requires understanding claim scope, prosecution history, continuation and divisional chains, assignee normalization (a single company may appear under multiple entity names across patent records), priority dates versus filing dates versus publication dates, and the relationship between dependent and independent claims. It requires mapping the specific technical features of a proposed product against independent claim language—not keyword matching.
General-purpose models do not have these frameworks. They pattern-match against training data and produce outputs that adopt the format and tone of patent analysis without the underlying data infrastructure. The format is correct. The confidence is high. The coverage is incomplete in ways that are not visible to the user.
4. Comparative Output Quality
The following table summarizes the qualitative characteristics of each tool's response across the dimensions most relevant to an operational IP workflow.
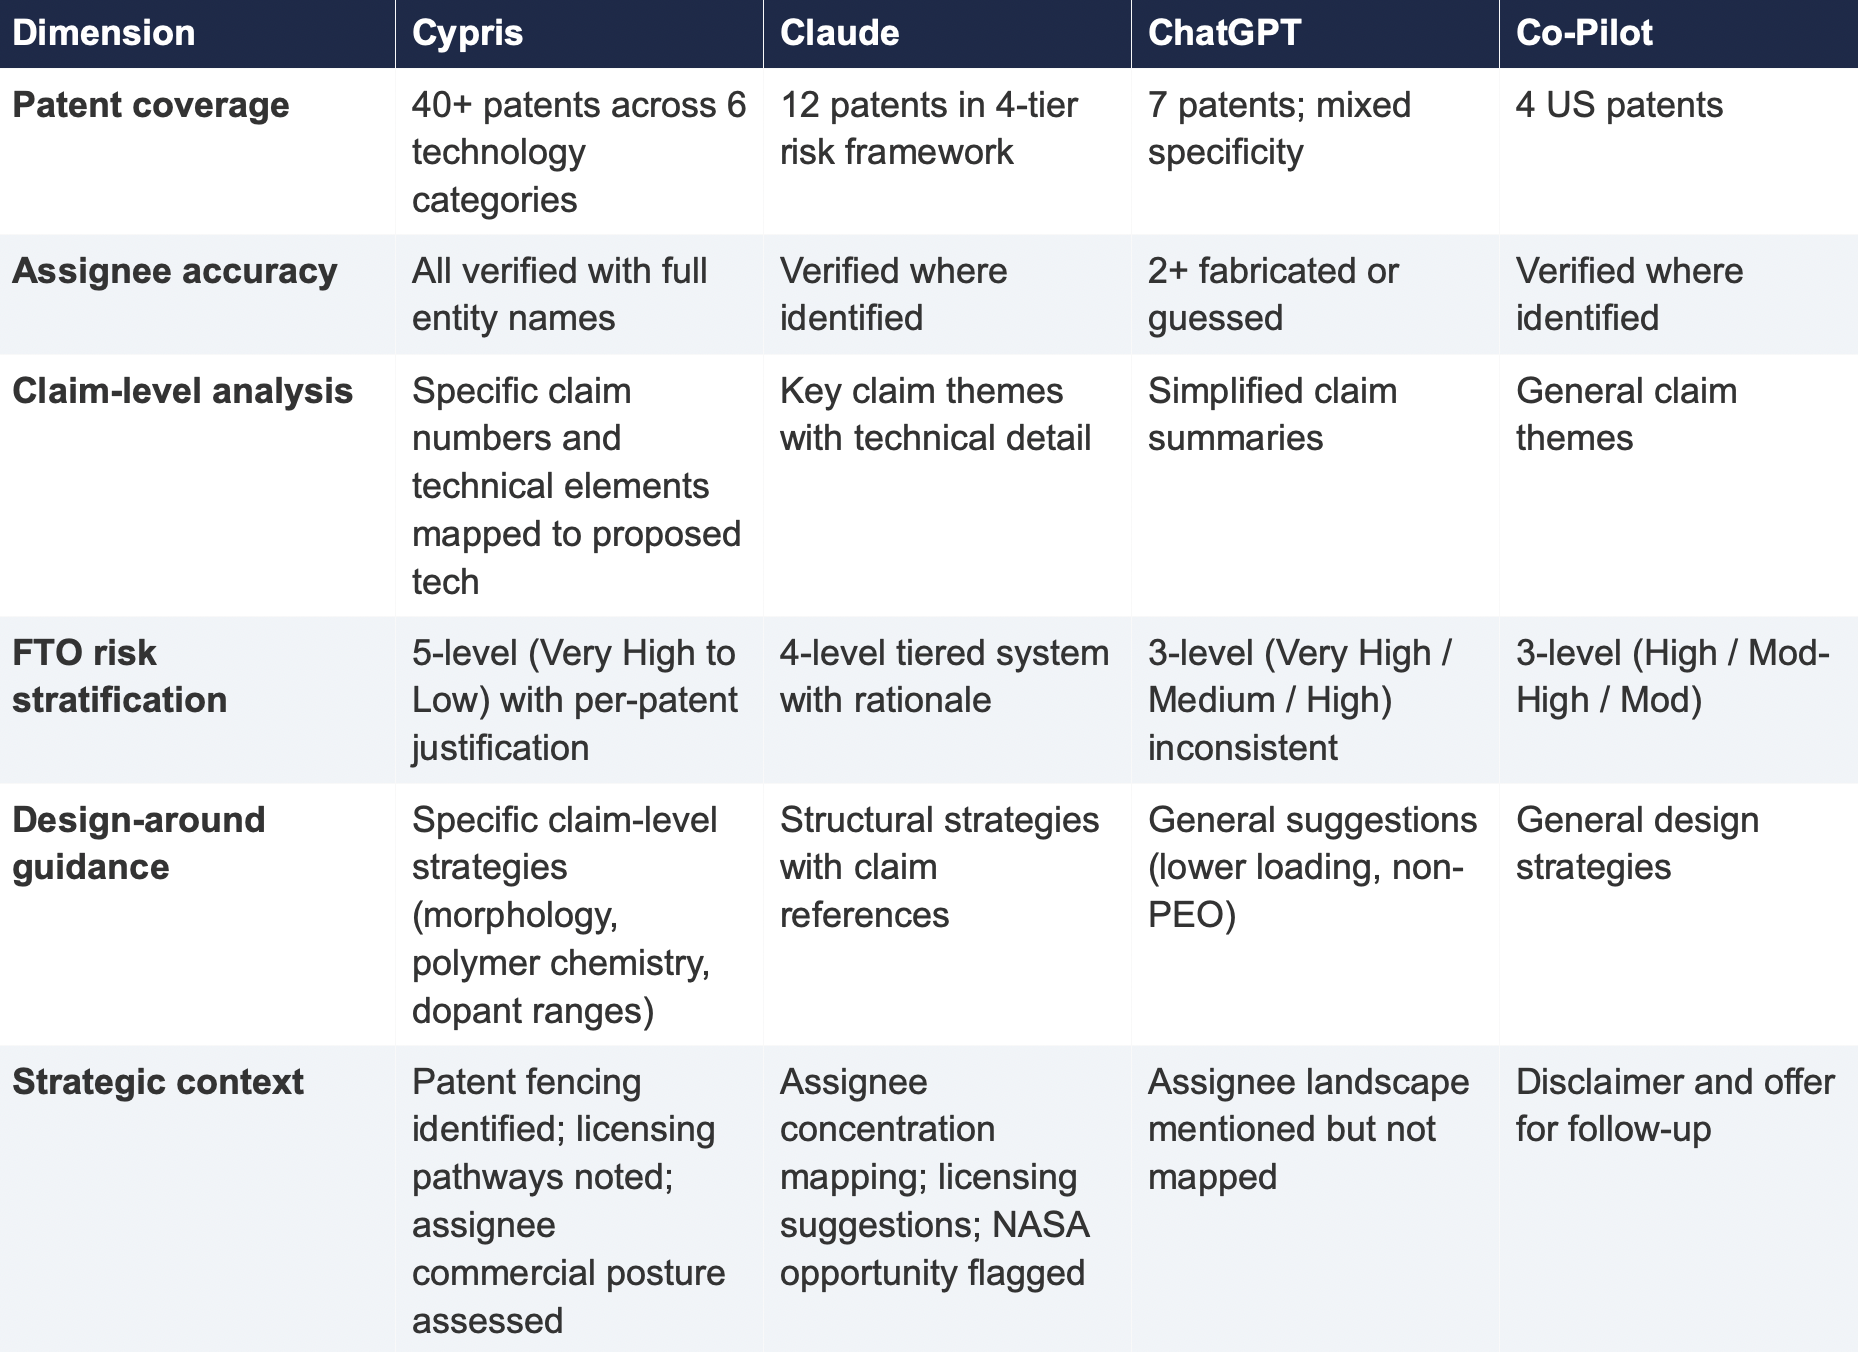
5. Implications for R&D and IP Organizations
5.1 The Confidence Problem
The central risk identified by this study is not that general-purpose models produce bad outputs—it is that they produce incomplete outputs with high confidence. Each model delivered its results in a professional format with structured analysis, risk ratings, and strategic recommendations. At no point did any model indicate the boundaries of its knowledge or flag that its results represented a fraction of the available patent record. A practitioner receiving one of these outputs would have no signal that the analysis was incomplete unless they independently validated it against a comprehensive datasource.
This creates an asymmetric risk profile: the better the format and tone of the output, the less likely the user is to question its completeness. In a corporate environment where AI outputs are increasingly treated as first-pass analysis, this dynamic incentivizes under-investigation at precisely the moment when thoroughness is most critical.
5.2 The Diversification Illusion
It might be assumed that running the same query through multiple general-purpose models provides validation through diversity of sources. This study suggests otherwise. While the four tools returned different subsets of patents, all operated under the same structural constraints: training data rather than live patent databases, web-scraped content rather than structured IP records, and general-purpose reasoning rather than patent-specific ontological frameworks. Running the same query through three constrained tools does not produce triangulation; it produces three partial views of the same incomplete picture.
5.3 The Appropriate Use Boundary
General-purpose language models are effective tools for a wide range of tasks: drafting communications, summarizing documents, generating code, and exploratory research. The finding of this study is not that these tools lack value but that their value boundary does not extend to decisions that carry existential commercial risk.
Patent landscape analysis, freedom-to-operate assessment, and competitive intelligence that informs R&D investment decisions fall outside that boundary. These are workflows where the completeness and verifiability of the underlying data are not merely desirable but are the primary determinant of whether the analysis has value. A patent landscape that captures 10% of the relevant filings, regardless of how well-formatted or confidently presented, is a liability rather than an asset.
6. Test 2: Competitive Intelligence — Bio-Based Polyamide Patent Landscape
To assess whether the findings from Test 1 were specific to a single technology domain or reflected a broader structural pattern, a second query was submitted to all four tools. This query shifted from freedom-to-operate analysis to competitive intelligence, asking each tool to identify the top 10organizations by patent filing volume in bio-based polyamide synthesis from castor oil derivatives over the past three years, with summaries of technical approach, co-assignee relationships, and portfolio trajectory.
6.1 Query

6.2 Summary of Results
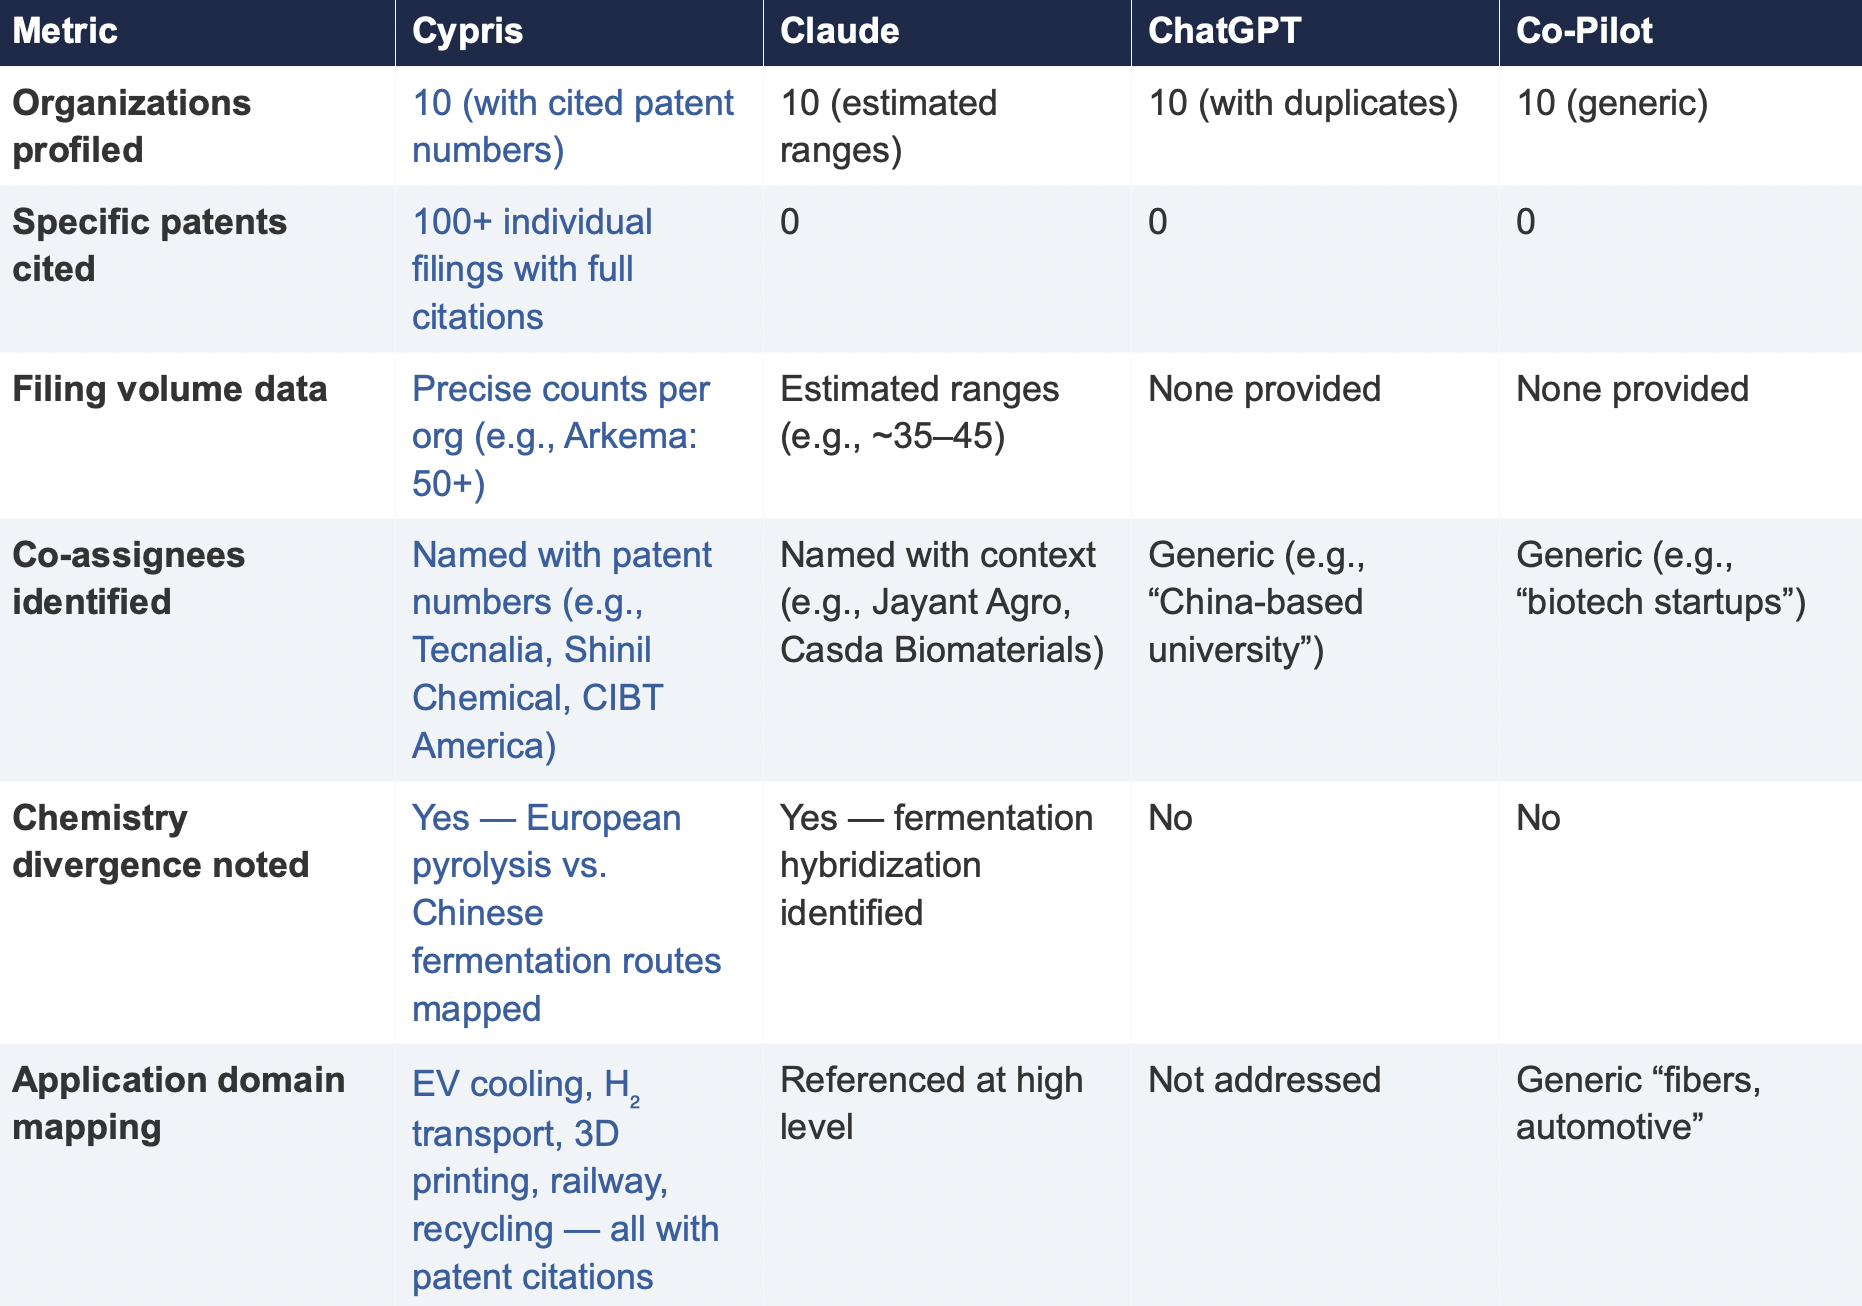
6.3 Key Differentiators
Verifiability
The most consequential difference in Test 2 was the presence or absence of verifiable evidence. Cypris cited over 100 individual patent filings with full patent numbers, assignee names, and publication dates. Every claim about an organization’s technical focus, co-assignee relationships, and filing trajectory was anchored to specific documents that a practitioner could independently verify in USPTO, Espacenet, or WIPO PATENT SCOPE. No general-purpose model cited a single patent number. Claude produced the most structured and analytically useful output among the public models, with estimated filing ranges, product names, and strategic observations that were directionally plausible. However, without underlying patent citations, every claim in the response requires independent verification before it can inform a business decision. ChatGPT and Co-Pilot offered thinner profiles with no filing counts and no patent-level specificity.
Data Integrity
ChatGPT’s response contained a structural error that would mislead a practitioner: it listed CathayBiotech as organization #5 and then listed “Cathay Affiliate Cluster” as a separate organization at #9, effectively double-counting a single entity. It repeated this pattern with Toray at #4 and “Toray(Additional Programs)” at #10. In a competitive intelligence context where the ranking itself is the deliverable, this kind of error distorts the landscape and could lead to misallocation of competitive monitoring resources.
Organizations Missed
Cypris identified Kingfa Sci. & Tech. (8–10 filings with a differentiated furan diacid-based polyamide platform) and Zhejiang NHU (4–6 filings focused on continuous polymerization process technology)as emerging players that no general-purpose model surfaced. Both represent potential competitive threats or partnership opportunities that would be invisible to a team relying on public AI tools.Conversely, ChatGPT included organizations such as ANTA and Jiangsu Taiji that appear to be downstream users rather than significant patent filers in synthesis, suggesting the model was conflating commercial activity with IP activity.
Strategic Depth
Cypris’s cross-cutting observations identified a fundamental chemistry divergence in the landscape:European incumbents (Arkema, Evonik, EMS) rely on traditional castor oil pyrolysis to 11-aminoundecanoic acid or sebacic acid, while Chinese entrants (Cathay Biotech, Kingfa) are developing alternative bio-based routes through fermentation and furandicarboxylic acid chemistry.This represents a potential long-term disruption to the castor oil supply chain dependency thatWestern players have built their IP strategies around. Claude identified a similar theme at a higher level of abstraction. Neither ChatGPT nor Co-Pilot noted the divergence.
6.4 Test 2 Conclusion
Test 2 confirms that the coverage and verifiability gaps observed in Test 1 are not domain-specific.In a competitive intelligence context—where the deliverable is a ranked landscape of organizationalIP activity—the same structural limitations apply. General-purpose models can produce plausible-looking top-10 lists with reasonable organizational names, but they cannot anchor those lists to verifiable patent data, they cannot provide precise filing volumes, and they cannot identify emerging players whose patent activity is visible in structured databases but absent from the web-scraped content that general-purpose models rely on.
7. Conclusion
This comparative analysis, spanning two distinct technology domains and two distinct analytical workflows—freedom-to-operate assessment and competitive intelligence—demonstrates that the gap between purpose-built R&D intelligence platforms and general-purpose language models is not marginal, not domain-specific, and not transient. It is structural and consequential.
In Test 1 (LLZO garnet electrolytes for Li-S batteries), the purpose-built platform identified more than three times as many patents as the best-performing general-purpose model and ten times as many as the lowest-performing one. Among the patents identified exclusively by the purpose-built platform were filings rated as Very High FTO risk that directly claim the proposed technology architecture. InTest 2 (bio-based polyamide competitive landscape), the purpose-built platform cited over 100individual patent filings to substantiate its organizational rankings; no general-purpose model cited as ingle patent number.
The structural drivers of this gap—reliance on training data rather than live patent feeds, the accelerating closure of web content to AI scrapers, and the absence of patent-specific analytical frameworks—are not transient. They are inherent to the architecture of general-purpose models and will persist regardless of increases in model capability or training data volume.
For R&D and IP leaders, the practical implication is clear: general-purpose AI tools should be used for general-purpose tasks. Patent intelligence, competitive landscaping, and freedom-to-operate analysis require purpose-built systems with direct access to structured patent data, domain-specific analytical frameworks, and the ability to surface what a general-purpose model cannot—not because it chooses not to, but because it structurally cannot access the data.
The question for every organization making R&D investment decisions today is whether the tools informing those decisions have access to the evidence base those decisions require. This study suggests that for the majority of general-purpose AI tools currently in use, the answer is no.
Study Disclosure
This comparative evaluation was commissioned and published by Cypris. The testing methodology, prompts, evaluation criteria, and underlying outputs have been documented to support independent review and replication.
All platform outputs were preserved in their original form. Patent data and material factual claims were cross-checked against USPTO Patent Center and WIPO PATENTSCOPE records as of March 27, 2026. Cypris was one of the platforms evaluated and therefore has a commercial interest in the findings.