Insights on Innovation, R&D, and IP
Perspectives on patents, scientific research, emerging technologies, and the strategies shaping modern R&D
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
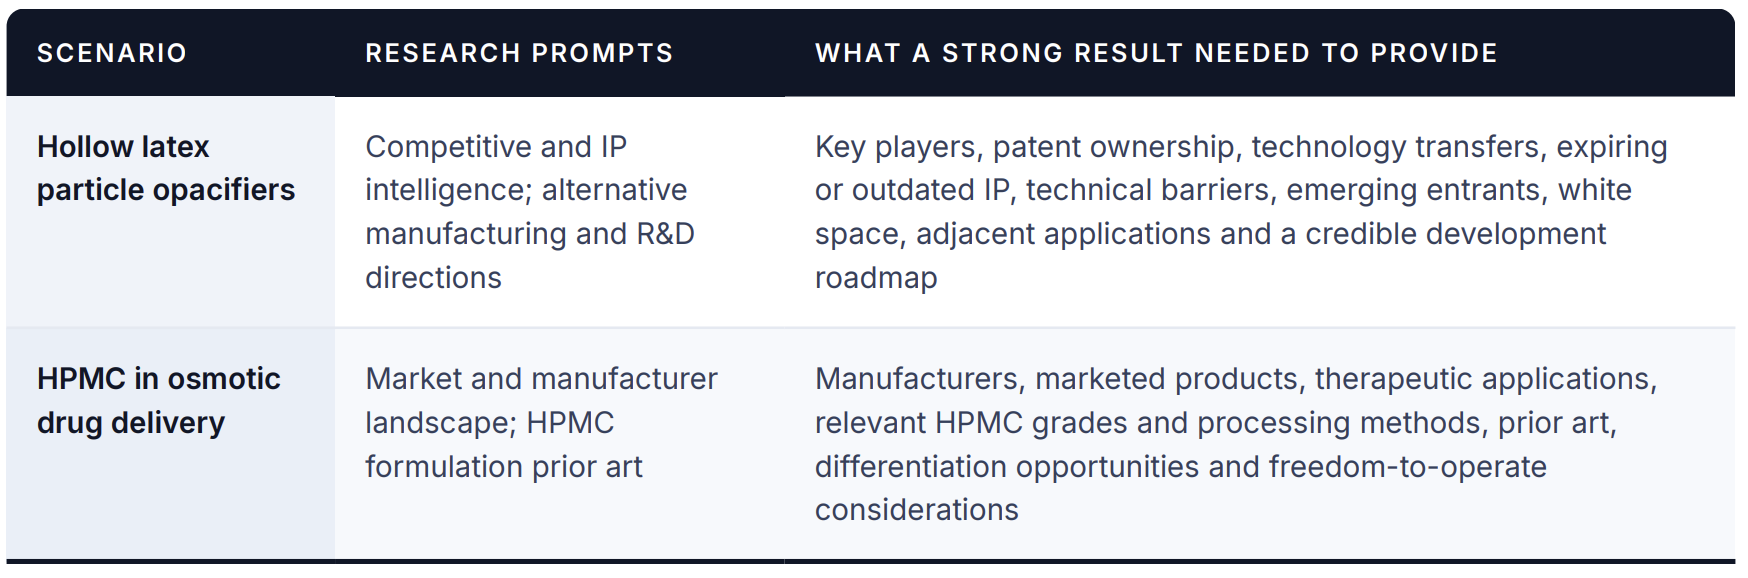
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
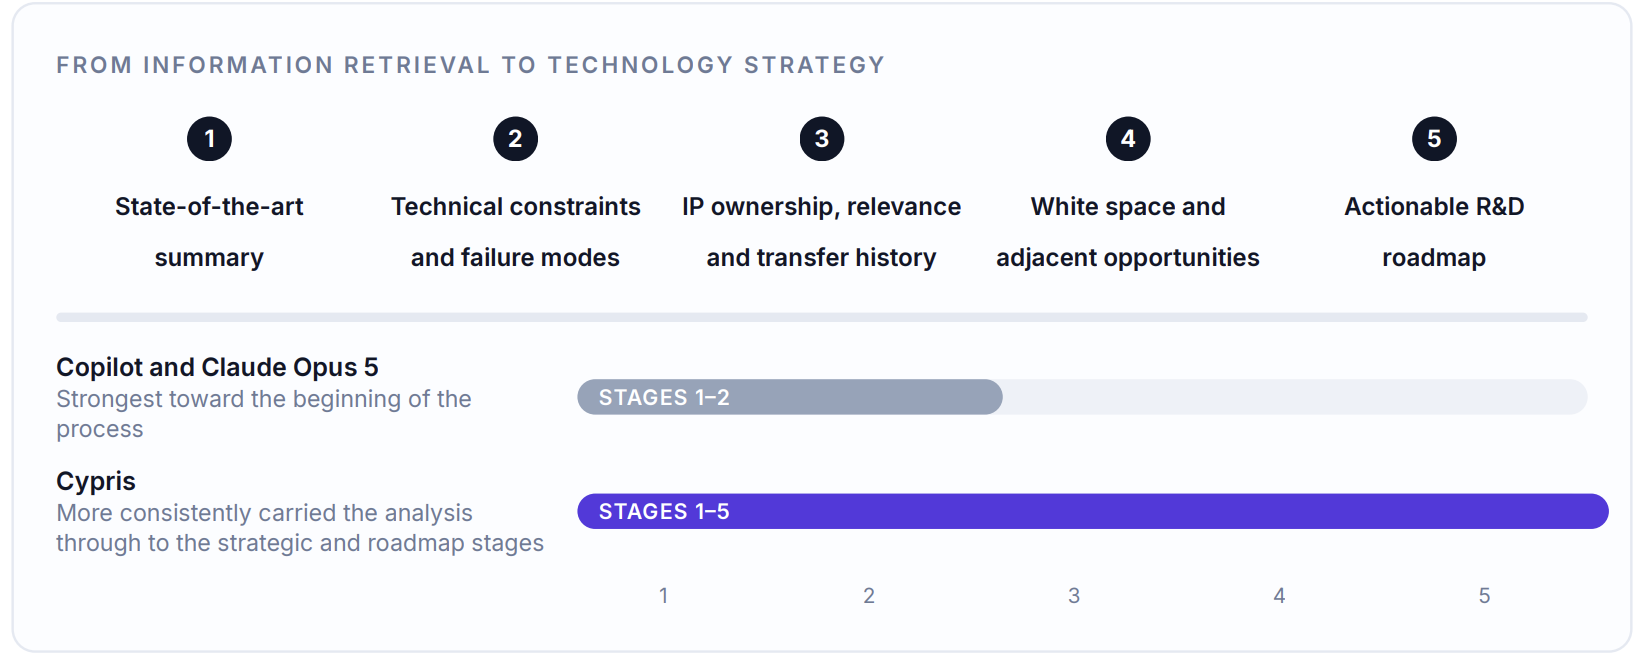
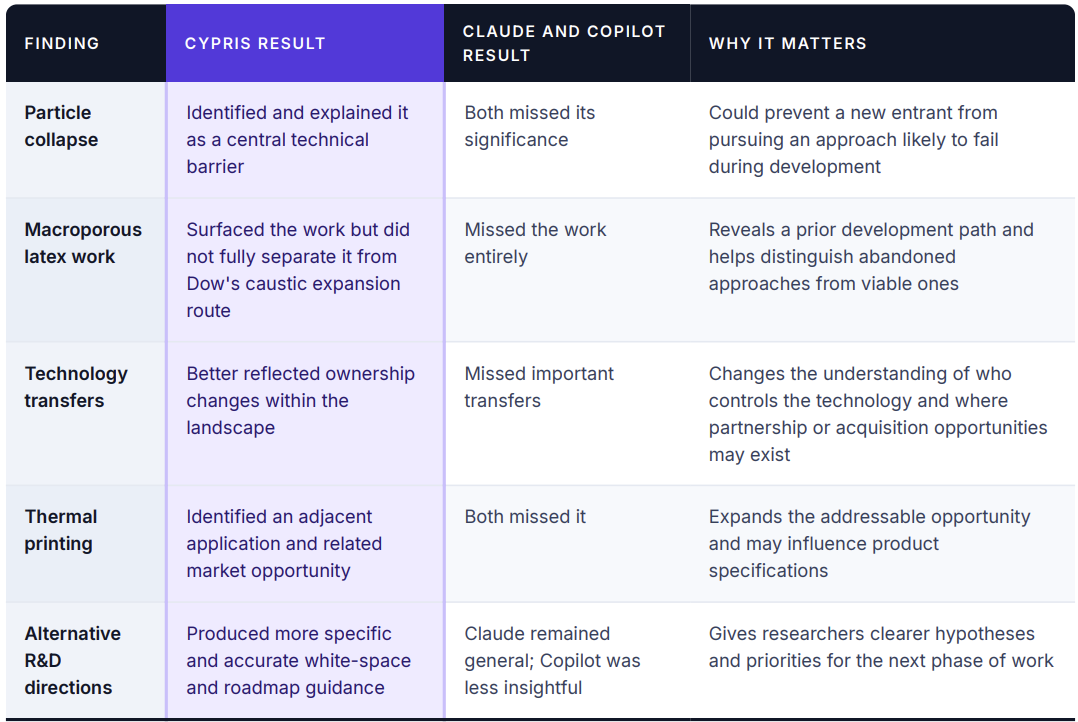
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
Comparative findings at a glance
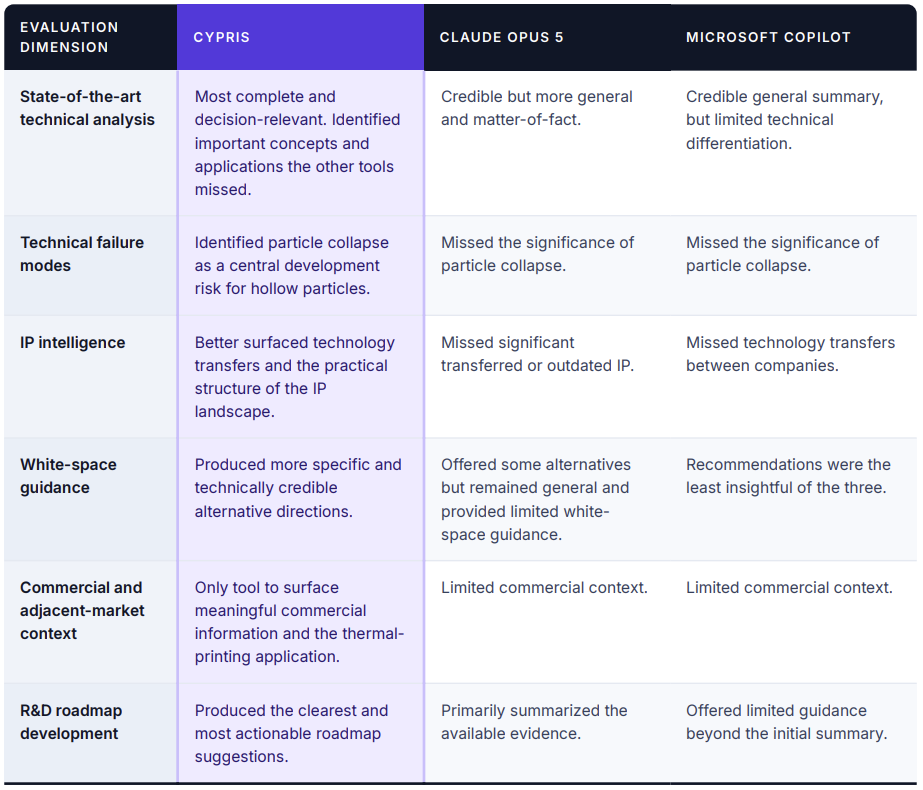
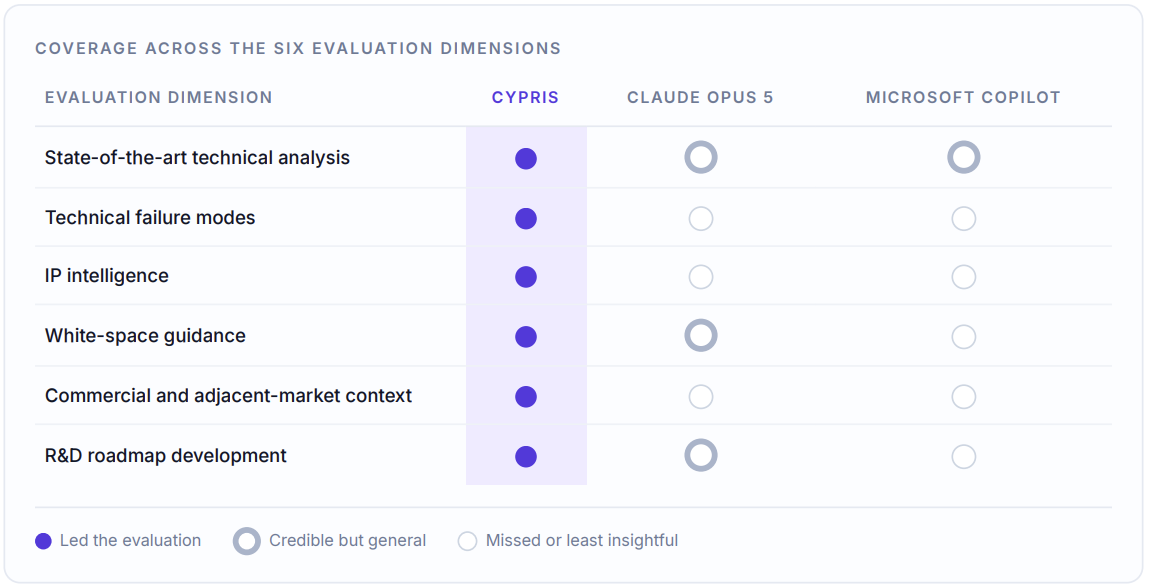
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
Former Dow Research Fellow Compares Cypris, Copilot & Claude for Chemical Intelligence
All Blogs
Keyword search matches exact terms. Semantic search matches meaning. For patent search, that distinction determines whether a strategically critical filing is found or missed.
Patent search has relied on Boolean keyword queries and classification codes for decades. The method works when the searcher already knows the exact language an invention will use. It fails when a competitor describes the same mechanism with different words, files under a different classification, or uses terminology that did not exist when the query was written. In fast-moving fields, that failure is routine.
In 2026, R&D and IP teams are moving to AI-native semantic patent search because the volume and linguistic variety of global filings have outpaced keyword methods. This article defines semantic search, contrasts it with keyword search, and explains what the shift changes for patent search, patent analytics, prior art, and freedom-to-operate work.
How keyword patent search works and where it breaks
Keyword search retrieves documents that contain the specific terms in a query, usually combined with Boolean operators and classification filters. It is precise when the vocabulary is known and stable, and it remains useful for targeted lookups.
It breaks on vocabulary mismatch. Two teams working on the same problem often use entirely different terminology, and patent drafters frequently choose broad or unusual language deliberately. A keyword query built around expected terms will not retrieve a filing that describes the same invention differently. The result is silent gaps: the searcher sees results and assumes coverage, without knowing what was missed.
Volume magnifies the problem. Global patent filings and scientific publications continue to rise, and the World Intellectual Property Organization reported scientific output above two million articles in 2025. Expanding keyword queries to chase this volume produces either too much noise or too little signal.
How semantic search works
Semantic search represents the meaning of text as mathematical vectors, so that conceptually similar passages sit close together regardless of exact wording. A query for a mechanism retrieves filings that describe that mechanism, even when the words differ. This directly addresses the vocabulary-mismatch problem that keyword search cannot solve.
For patents, the strongest implementations apply semantic search at the claim level and across both patents and scientific literature. Claim-level retrieval matters because the legal risk in a patent lives in its claims, not its abstract. Searching patents and scientific papers together matters because early technical disclosure often appears in the literature before it reaches granted claims.
An R&D ontology strengthens semantic search further. An ontology is a structured map of technical concepts and their relationships. When semantic retrieval is organized through an ontology, the system interprets a query in the context of a technology domain rather than as isolated words, which improves both recall and precision.
What the shift changes for R&D and IP teams
Semantic search changes prior art and FTO work most directly. In prior art search, semantic retrieval surfaces conceptually relevant disclosures that keyword queries overlook, which strengthens both patentability assessments and invalidity arguments. In freedom-to-operate search, it surfaces active claims a product may read on even when those claims use unexpected language, reducing unquantified legal risk.
It also changes patent analytics. Once retrieval understands meaning, analytics can group filings by technical concept rather than by literal text, producing cleaner technology landscapes, competitor maps, and white space analysis. Agentic workflows build on this by chaining retrieval and reasoning steps to assemble landscapes, comparison matrices, and monitored positions automatically.
Where Cypris fits
Cypris is an AI-native R&D intelligence platform built on semantic search across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology lets Cypris interpret technical meaning and retrieve conceptually related patents and literature at the claim level, rather than matching keywords.
Cypris Q, the platform's agentic layer, chains semantic retrieval and reasoning into end-to-end workflows such as landscape analysis, prior art review, and FTO assessment. Agentic Monitoring keeps those positions current by evaluating new filings as they publish. Cypris operates under enterprise API partnerships with OpenAI, Anthropic, and Google, with enterprise-grade security, and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, and other regulated industries.
FAQ
What is semantic search for patents?
Semantic search for patents retrieves filings by meaning rather than by exact keywords, representing text as vectors so that conceptually similar patents sit close together. This surfaces relevant patents that use different terminology than a query expects, which keyword search cannot do.
What is the difference between semantic search and keyword search?
Semantic search matches the meaning of text, while keyword search matches exact terms combined with Boolean operators. Keyword search misses filings that describe the same invention in different words, whereas semantic search retrieves them because it operates on concepts rather than literal strings.
Why are R&D teams moving to AI-native patent search?
R&D teams are moving to AI-native patent search because the volume and linguistic variety of global filings have outpaced keyword methods, causing silent gaps in coverage. Semantic search retrieves conceptually related filings across patents and scientific literature, reducing the risk that critical disclosures are missed.
Is semantic search better than keyword search for prior art?
Semantic search is generally stronger for prior art because it surfaces conceptually relevant disclosures that keyword queries overlook due to vocabulary mismatch. Keyword search remains useful for targeted lookups when the exact terminology is known, so many workflows combine both.
What is an R&D ontology in patent search?
An R&D ontology is a structured map of technical concepts and their relationships that organizes a search corpus by meaning. In patent search, an ontology lets a system interpret a query in the context of a technology domain rather than as isolated words, improving both recall and precision.
Does semantic search work across patents and scientific papers?
Semantic search works across both patents and scientific papers when the corpus unifies them, which matters because early technical disclosure often appears in the literature before it reaches granted patent claims. Searching both together produces a more complete technical and competitive picture.
How does semantic search improve patent analytics?
Semantic search improves patent analytics by grouping filings by technical concept rather than literal text, which produces cleaner technology landscapes, competitor maps, and white space analysis. Analytics built on meaning are more reliable than analytics built on keyword matches alone.
Can semantic patent search be automated with agents?
Semantic patent search can be automated with agentic workflows that chain retrieval and reasoning steps to assemble landscapes, comparison matrices, and monitored positions. Agents keep the analysis current by re-running semantic retrieval against new filings as they publish.
Does semantic search replace Boolean patent search entirely?
Semantic search does not fully replace Boolean patent search, because targeted keyword queries remain useful when exact terminology is known. The strongest workflows combine semantic retrieval for recall with keyword precision for confirmation.
What data coverage does effective semantic patent search require?
Effective semantic patent search requires broad coverage across patents and scientific literature, so that conceptually related disclosures in any vocabulary can be retrieved. A corpus of more than 500 million patents and scientific papers organized through an R&D ontology supports this breadth.

Patenting in artificial intelligence is growing faster than almost any other technology area, and generative AI is the sharpest example. According to the World Intellectual Property Organization, generative AI patent families grew from 733 in 2014 to more than 14,000 in 2023, an increase of over 800 percent, while related scientific publications rose even faster, from 116 to more than 34,000 over the same period.¹ WIPO's subsequent analysis shows the acceleration continuing: newly published generative AI patent families reached roughly 37,800 in 2025, and more were published in 2024 and 2025 combined than in the entire preceding decade.² This makes AI, and generative AI within it, one of the most active and fastest-moving areas of the global patent record.
Two structural features shape how the AI patent landscape must be read. The first is the gap between research and patents. Scientific publication in AI runs ahead of patenting and at higher volume, so the research literature is the leading edge of the landscape and patents are a lagging, commercial-commitment signal.¹ The second is publication lag: applications publish roughly eighteen months after filing, so the most recent windows of the landscape are systematically under-represented, and apparent slowdowns in the latest year are usually artifacts rather than real declines.² Any analysis that reads the latest patent counts without accounting for lag will misjudge the current state of a field moving this quickly.
The landscape is also highly concentrated, which matters for competitive positioning. Between 2014 and 2023, generative AI patenting was dominated by a small number of countries: inventors in China accounted for 38,210 patent families, followed by the United States with 6,276, South Korea with 4,155, Japan with 3,409, and India with 1,350, so the top four locations represented roughly 94 percent of all generative AI patenting.¹ The leading individual applicants over that period were Tencent with 2,074 families, Ping An with 1,564, and Baidu with 1,234, followed by the Chinese Academy of Sciences, IBM, Alibaba, Samsung, Alphabet, ByteDance, and Microsoft, and generative AI still represented only about 6 percent of all AI patent families, indicating substantial room for growth.¹ The broader picture is consistent: AI patents granted worldwide rose from 3,833 in 2010 to 122,511 in 2023, with China accounting for roughly 70 percent of grants, the United States about 14 percent, and Europe under 3 percent.⁵ WIPO's more recent analysis shows the concentration intensifying, with China publishing more than 43,000 generative AI families in 2024 and 2025 combined, exceeding its entire cumulative output from 2014 to 2023, and new entrants such as Nvidia rising into the top ranks.² WIPO further notes that most generative AI inventions are protected primarily in their domestic markets rather than through large international patent families, and it expects the fastest future growth in multimodal systems and AI agents, and in the integration of generative AI into sectors such as healthcare, finance, and energy.² This aligns with the broader enterprise shift to agentic AI: the Model Context Protocol has become the standard through which AI agents connect to external data,⁴ and Gartner projects that 40 percent of enterprise applications will include task-specific AI agents by the end of 2026.³ For organizations building or adopting AI, the practical implication is that the areas of heaviest future activity, including agentic AI, are identifiable now from the research and early-filing signal.
What the AI patent landscape shows
Rapid, accelerating growth. Generative AI patent families grew from 733 in 2014 to more than 14,000 in 2023 and to roughly 37,800 in 2025, with more published in 2024 and 2025 combined than in the preceding decade.¹,²
Research ahead of patents. Scientific publication in AI runs ahead of patenting and at higher volume, so the research literature is the leading edge and patents are a commercial-commitment signal.¹
Concentration. Activity is concentrated in a small number of organizations and geographies: China accounted for 38,210 generative AI families from 2014 to 2023, and the top four locations for roughly 94 percent of the total, led by applicants such as Tencent, Ping An, and Baidu.¹
By application. Among generative AI families from 2014 to 2023, image and video (about 18,000), text (about 13,500), and speech or music (about 13,500) dominate, while molecule, gene, and protein applications, though smaller at about 1,500, grew fastest at roughly 78 percent per year.¹
Granted patents worldwide. AI patents granted worldwide rose from 3,833 in 2010 to 122,511 in 2023, with China accounting for roughly 70 percent of grants, the United States about 14 percent, and Europe under 3 percent.⁵
Domestic protection. Most generative AI inventions are protected primarily in domestic markets rather than through large international families, which affects where freedom-to-operate risk sits.²
Emerging direction. The fastest future growth is expected in multimodal systems and AI agents, and in the integration of generative AI into healthcare, finance, and energy.²
How to analyze a fast-moving AI patent landscape
Scope the technology space with classification codes and concept-based search, since AI terminology evolves quickly and keyword-only boundaries miss relevant work.
Aggregate to the patent-family level, so a single invention filed across jurisdictions is counted once and international coverage is not conflated with volume.
Read scientific literature as the leading edge, because AI research precedes and exceeds patenting, so the earliest signal of a new direction is in publications.¹
Correct for publication lag, discounting the most recent windows, because applications publish about eighteen months after filing and the latest year is under-represented.²
Map concentration and white space, identifying which organizations and areas are crowded and which sub-areas, such as specific agentic or multimodal applications, remain open.
Monitor continuously, tracking the landscape over time so new filings and research are surfaced as they publish in a field that is changing rapidly.
Where Cypris fits
Cypris runs patent landscape and white space analysis for fast-moving fields such as artificial intelligence across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters AI activity by concept across rapidly evolving terminology and normalizes organizations to canonical entities, so a team can resolve which areas and players are crowded and which sub-areas remain open as white space. Semantic search across patents and scientific literature reads the research leading edge, which is essential in AI because publication precedes and exceeds patenting, and connects it to early filings. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the scoping, clustering, attribution, and gap analysis. Agentic Monitoring tracks a defined AI area over time and flags new patents and papers as they publish, which is essential where recent activity is under-represented by publication lag. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
How fast is AI patenting growing? AI patenting is growing faster than almost any other technology area, and generative AI is the sharpest example. WIPO data show generative AI patent families grew from 733 in 2014 to more than 14,000 in 2023, an increase of over 800 percent, and to roughly 37,800 in 2025. More generative AI families were published in 2024 and 2025 combined than in the entire preceding decade.
What is the AI patent landscape? The AI patent landscape is the map of where artificial intelligence is being patented, which organizations are active, and where activity is concentrated or sparse. Because AI research runs ahead of patenting, the landscape is best read across both patents and scientific literature. It is one of the fastest-moving areas of the global patent record.
Why does AI patent analysis rely on scientific literature? AI patent analysis relies on scientific literature because research in AI precedes patenting and occurs at higher volume, so the literature is the leading edge of the field. Patents are a lagging, commercial-commitment signal. WIPO data show scientific publications in generative AI grew even faster than patents over the past decade.
Why does publication lag matter in the AI patent landscape? Publication lag matters because applications publish roughly eighteen months after filing, so the most recent windows of the AI patent landscape are systematically under-represented. In a field moving this quickly, apparent slowdowns in the latest year are usually artifacts of lag rather than real declines. Longer-window trends and continuous monitoring are more reliable.
Where is AI patenting concentrated? AI patenting is concentrated in a small number of organizations and geographies. WIPO's analysis shows organizations based in China prominent among the top generative AI filers, with generative AI still representing a modest share of the broader AI patent total. Most generative AI inventions are protected primarily in domestic markets rather than through large international families.
Where is AI innovation heading next? AI innovation is expected to grow fastest in multimodal systems and AI agents, and in the integration of generative AI into sectors such as healthcare, finance, and energy, according to WIPO. Because research precedes patenting, these directions are already visible in the publication and early-filing signal. Analyzing the landscape now identifies where future activity will concentrate.
Why aggregate AI patents into families? Aggregating AI patents into families avoids double-counting, because a single invention is often filed across multiple jurisdictions. Counting documents overstates activity and conflates international coverage with genuine volume. The patent family is the correct unit for measuring how much distinct AI invention is occurring.
How do you find white space in the AI patent landscape? Finding white space in the AI patent landscape means mapping patents and scientific literature across AI sub-areas, clustering activity by concept, and identifying the sparse sub-areas where few patents exist. Because AI terminology evolves quickly, semantic and concept-based analysis is essential. The sparse areas, such as specific agentic or multimodal applications, indicate where a defensible position remains available.
How do you keep an AI patent landscape current? Keeping an AI patent landscape current requires continuous monitoring, because AI moves quickly, new research and filings publish constantly, and publication lag hides the most recent activity. A one-time landscape ages within months. Cypris uses Agentic Monitoring to track a defined AI area and flag new patents and papers as they publish.
Who uses AI patent landscape analysis? AI patent landscape analysis is used by R&D, innovation, IP, and strategy teams at technology companies, and by organizations across sectors adopting AI, to understand where the technology is heading and where competitors are active. It is also used to identify white space for new AI inventions. Cypris serves hundreds of enterprise customers across research-intensive and regulated industries.
Endnotes
- World Intellectual Property Organization (2024). Patent Landscape Report: Generative Artificial Intelligence. Geneva: WIPO. https://doi.org/10.34667/tind.49740
- World Intellectual Property Organization (2026). Generative AI patent landscape update, WIPO Patent Analytics. https://www.wipo.int/en/web/patent-analytics/generative-ai
- Gartner (2025). Gartner Predicts 40% of Enterprise Apps Will Feature Task-Specific AI Agents by 2026. https://www.gartner.com/en/newsroom/press-releases/2025-08-26-gartner-predicts-40-percent-of-enterprise-apps-will-feature-task-specific-ai-agents-by-2026-up-from-less-than-5-percent-in-2025
- Anthropic (2025). Donating the Model Context Protocol and establishing the Agentic AI Foundation. https://www.anthropic.com/news/donating-the-model-context-protocol-and-establishing-of-the-agentic-ai-foundation
- Stanford Institute for Human-Centered Artificial Intelligence (2025). Artificial Intelligence Index Report 2025, Chapter 1. arXiv:2504.07139. https://doi.org/10.48550/arxiv.2504.07139
Patent search built for text doesn't work well for chemistry. A compound can be described with different names, different notation, or a Markush structure covering a whole class of molecules, all referring to the same underlying chemical entity. A keyword-based patent search treats these as unrelated results, even when the compounds are structurally identical or close enough to raise real FTO or novelty concerns. For R&D and IP teams in pharmaceuticals, chemicals, and advanced materials, this is a genuine gap: the patent search tool and the chemical structure search tool are usually separate products, and neither one alone gives a complete picture.
This matters at every stage of the R&D and IP workflow. A white space analysis that only checks patent text can miss a structurally overlapping compound published under an unfamiliar name. An FTO search that doesn't account for structural similarity can clear a compound that a structure-based comparison would have flagged. And prior art review that treats chemical literature and patents as separate searches duplicates effort while still leaving gaps between the two.
Why chemical structure search needs to be part of patent search
Naming doesn't map to structure. The same molecule can appear under IUPAC nomenclature, a trade name, a CAS registry number, or an informal lab designation across different patents and papers. Text-based patent search treats these as different entities unless someone manually reconciles them.
Markush claims cover more than they name. Patent claims in chemistry frequently use Markush structures to cover a genus of related compounds rather than naming each one individually. Assessing FTO or novelty against a Markush claim requires structural comparison, not keyword matching, since the specific compound in question may never appear by name in the claim text.
Scientific literature moves faster than patent filings in chemistry. A compound can appear in scientific research well before it's the subject of a patent application. Patent search that excludes scientific literature can miss the earliest indication that a structurally relevant compound is already being studied.
Structural similarity, not just exact matches, matters for FTO. Freedom-to-operate risk isn't limited to identical compounds — a structurally similar compound falling within a broad claim can carry the same infringement risk as an exact match, which text search has no way to detect.
How Cypris connects chemical structure search to patent analytics
Cypris runs patent search, patent analytics, FTO, and white space analysis on a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. That ontology is what lets a query connect a compound's structure to the concept it represents, rather than relying only on the vocabulary a specific patent or paper happens to use.
Because Cypris runs semantic search across patents and scientific literature together, a chemistry-focused query surfaces both patent claims and related scientific research on the same underlying compound or reaction class, rather than requiring two separate searches. The platform's agentic layer, Cypris Q, lets R&D and IP teams run multi-step queries — checking a compound against patent claims, related literature, and Markush coverage as a single agentic workflow rather than a manual, multi-tool process. Agentic Monitoring then keeps tracking a technology or compound area on an ongoing basis, surfacing new patents or papers that affect a cleared position as they publish.
Cypris also supports MCP (Model Context Protocol), so chemistry and IP teams can connect this corpus directly into their own AI agents and internal tools, rather than working through a standalone search interface. With enterprise API partnerships with OpenAI, Anthropic, and Google and enterprise-grade security, this supports AI implementation inside regulated R&D functions where compound data needs to stay protected.
Commercial research, ontological search, and agent systems in practice
Chemical structure search isn't only a legal or IP exercise — it's also a commercial research problem. Business development and licensing teams need to know who else is working on a structurally related compound before pursuing a partnership, and technology scouting for M&A due diligence depends on finding relevant chemistry regardless of how a target company has described it internally. Patent search and patent analytics that only serve the IP function miss this commercial research use case, even though it draws on the same underlying corpus of patents and scientific literature.
Ontological search is what makes both the IP and commercial research use cases work from a single system. Rather than matching text, ontological search organizes patents, scientific papers, and compound data around the technical concepts and structural relationships that connect them, so a query for a specific chemistry returns everything relevant to that concept — a competing patent claim, an academic paper describing the same reaction pathway, or a company's public disclosure of related research — regardless of the vocabulary each source uses. This is the same ontology-driven structure that supports FTO and white space analysis, applied to commercial and licensing questions instead of legal clearance.
Agent systems are what turn ontological search into an ongoing capability rather than a single query. Cypris Q operates as an agent system that can run a multi-step chemical structure and patent search — checking a compound against claims, literature, and commercial activity in one pass — while Agentic Monitoring keeps that same agent system watching a technology or compound area afterward, so a licensing team or IP function is notified when new patents, papers, or public research change the picture. Because these agent systems are accessible through MCP, both R&D and business development teams can query the same underlying chemical structure and patent data from within their own AI tools, rather than maintaining separate systems for IP work and commercial research.
Where Cypris fits
Cypris is built to close the gap between patent search, scientific literature search, and chemistry-specific analysis. Its corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology, connects claim language and scientific research to the underlying technical and chemical concepts they describe. Cypris Q and Agentic Monitoring turn a one-time chemistry-related patent search into an ongoing, agentic workflow, and MCP support lets that corpus plug directly into a team's own AI agents. With enterprise API partnerships with OpenAI, Anthropic, and Google and enterprise-grade security, Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries where patent search, patent analytics, FTO, and white space analysis depend on getting chemistry right.
Each compound page in our directory shows a slice of these connections: who is patenting, which classifications cluster, which research groups are active. You can browse it freely here.
FAQ
Is there a platform that searches patents and chemical structures together? Yes — platforms built for chemistry-focused R&D, such as Cypris, connect patent search to the underlying chemical concept rather than treating structure search and patent search as separate tools, using an ontology that maps compounds and claims to the same technical concept regardless of naming differences.
Why isn't keyword-based patent search enough for chemistry? Keyword-based patent search misses compounds described under different names, notations, or Markush structures, so it can overlook patents or papers that are structurally relevant even when the text doesn't match.
What is a Markush structure, and why does it matter for patent search? A Markush structure is a patent claim format that covers a broad genus of related chemical compounds rather than naming each one individually, which means assessing FTO or novelty against it requires structural comparison rather than keyword matching.
Does scientific literature matter for chemical patent search? Yes. Compounds and reactions often appear in scientific literature before they are the subject of a granted patent, so searching patents and scientific literature together surfaces relevant chemistry earlier than a patents-only search.
How does structural similarity affect freedom-to-operate (FTO) risk? FTO risk isn't limited to exact compound matches — a structurally similar compound that falls within a broad existing claim can carry meaningful infringement risk, which text-based patent search has no way to detect.
What role does AI play in chemical structure and patent search? AI enables semantic search and ontology-driven concept mapping, so a chemical structure query can be connected to relevant patent claims and scientific literature regardless of the specific naming convention used in each document.
What is agentic monitoring for chemistry-focused patent search? Agentic monitoring is the ongoing, automated tracking of a compound or technology area after the initial search, surfacing new patents or scientific papers relevant to that chemistry as they are published.
How does MCP (Model Context Protocol) apply to chemistry and patent research? MCP lets R&D and IP teams connect a patent, scientific literature, and chemical structure corpus directly into their own AI agents, rather than working through a separate, standalone search tool.
Which industries need combined patent and chemical structure search? Pharmaceuticals, chemicals, and advanced materials R&D teams rely most heavily on combined patent and chemical structure search, since compound novelty and FTO risk in these industries depend on structural comparison, not just text matching.
Is Cypris only useful for chemistry-focused teams? No — Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries, supporting patent search, patent analytics, FTO, and white space analysis broadly, with chemical structure context available where relevant.
Is chemical structure search only useful for IP and legal teams? No. Commercial research use cases like licensing scouting, partnership evaluation, and M&A due diligence rely on the same chemical structure and patent search capability as FTO and prior art work, since both depend on finding structurally relevant compounds regardless of how they are named or described.
What is ontological search in the context of chemical structure and patent search? Ontological search organizes patents, scientific papers, and compound data around the technical concepts and structural relationships connecting them, so a query returns everything relevant to a chemistry regardless of the specific vocabulary or naming convention each source uses.
What are agent systems, and how do they apply to chemical patent search? Agent systems are AI-driven layers, like Cypris Q, that run multi-step chemical structure and patent search as a single ongoing process rather than a one-time query, and that continue monitoring a compound or technology area afterward through agentic monitoring.
Patent research increasingly starts with an AI prompt. Attorneys, IP analysts, and R&D teams ask a general-purpose LLM to summarize a technology area, draft a freedom-to-operate (FTO) opinion, or point them toward relevant prior art. The problem is structural, not a matter of prompting technique: a general LLM answers from whatever it was trained on and whatever it can retrieve through web search, not from a live, complete corpus of patents and scientific research. For patent search, patent analytics, and FTO work, that gap is the difference between a plausible-sounding answer and a defensible one.
This matters more as AI implementation spreads through R&D and legal functions. A chatbot that has never indexed the patent it should be citing, or that treats a five-year-old filing as current, isn't performing patent search — it's guessing in the shape of an answer. The sections below walk through exactly where general LLMs fall short for patent research, and what a purpose-built alternative needs to do differently.
Why general LLMs are insufficient for patent research
No live connection to the full patent and scientific literature landscape. A general LLM's knowledge is bounded by its training data and, at best, supplemented by web search. Neither is built to search the patent corpus at the claim level or track scientific literature systematically, which is the baseline requirement for patent search, prior art review, and white space analysis.
No concept-level understanding of patent claims. Patent language is written to be legally precise, not to match how R&D teams describe their own technology. A general model can summarize a patent's claims in plain English, but it has no ontology connecting that claim to the broader scientific research or adjacent patent filings addressing the same underlying concept — which is exactly what patent analytics requires.
No ontological search. A general LLM retrieves by matching text patterns, not by reasoning across a structured map of technical concepts. It has no ontology to tell it that two patents using different vocabulary are describing the same underlying mechanism, or that a scientific paper and a patent claim are addressing the same technical concept from different angles. Ontological search resolves this by organizing patents and scientific literature around the concepts themselves rather than the words used to express them, so a query returns everything relevant to a technology regardless of how each document happens to phrase it. Without that structure, a general LLM's patent search is limited to whatever keyword or semantic similarity it can infer in the moment, which misses adjacent filings and related research that don't share obvious vocabulary.
No persistence or monitoring. A chat with a general LLM ends when the conversation ends. It cannot maintain an ongoing watch over a technology area or a cleared FTO position, and a white space finding from one conversation isn't automatically checked against new filings next month.
Hallucination risk on citations. Because general LLMs generate text probabilistically rather than retrieving from a verified patent and paper index, they can produce citations to patents or papers that don't exist or misstate a real filing's claims — a serious risk in FTO and prior art work, where the underlying documents need to be real and correctly represented.
What to use instead: a purpose-built patent intelligence platform
An AI-native platform such as Cypris addresses each of these gaps directly by pairing AI with a dedicated patent and scientific research infrastructure, rather than a general model working from training data alone.
A real, current corpus. Cypris draws on more than 500 million patents and scientific papers, giving patent search and patent analytics a live dataset to work from instead of a static training cutoff.
Concept-level structure, not just text. That corpus is organized through a proprietary R&D ontology, which connects patent claims to the scientific research behind them. This is what makes real white space analysis and FTO review possible — semantic search across patents and scientific literature that matches concepts, not just keywords.
An agentic layer built for the workflow, not general conversation. Cypris Q is Cypris's agentic layer, purpose-built to run multi-step patent search, patent analytics, and FTO queries as agentic workflows rather than a single-turn chatbot exchange. Agentic Monitoring extends this into an ongoing process: once a technology area or cleared position is established, it continues to be tracked, and new patents or papers that affect it are surfaced automatically.
Direct integration through MCP. Cypris supports MCP (Model Context Protocol), so IP and R&D teams can connect its patent and scientific literature corpus directly into their own AI agents and internal tools. This is the practical version of AI implementation for patent research: instead of asking a general chatbot to guess at patent data, teams query a real corpus through the agents they already use.
Where Cypris fits
Cypris exists specifically to close the gaps that show up when general LLMs are used for patent research. Its corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology, supports patent search, patent analytics, FTO, and white space analysis on real, current data rather than a model's training memory. Cypris Q and Agentic Monitoring turn one-off queries into ongoing, agentic workflows, and MCP support lets that corpus plug directly into a team's own AI agents. With enterprise API partnerships with OpenAI, Anthropic, and Google and enterprise-grade security, Cypris is built to sit alongside general AI tools rather than compete with their conversational use cases — it is the layer that supplies verified patent and scientific research data underneath them. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
Why are general LLMs insufficient for patent research? General LLMs are insufficient for patent research because they aren't connected to a live, complete corpus of patents and scientific literature, so they can't reliably perform patent search, verify citations, or run FTO and white space analysis the way a purpose-built patent intelligence platform can.
What is the risk of using a general LLM for freedom-to-operate (FTO) analysis? The main risk is hallucinated or outdated citations. A general LLM can describe a patent's claims inaccurately or reference filings that don't exist, which is dangerous in FTO work where the underlying documents must be verified and current.
What makes a patent research tool "AI-native" versus a general LLM with search added on? An AI-native patent platform is built around a dedicated corpus and ontology, like Cypris's 500M+ patents and scientific papers organized through a proprietary R&D ontology, rather than treating patent data as one more thing a general model can look up on the web.
Can AI agents be connected directly to patent data? Yes. Platforms that support MCP (Model Context Protocol), such as Cypris, let R&D and IP teams connect their own AI agents directly to a patent and scientific literature corpus rather than relying on a general model's training data.
What is agentic monitoring, and why does it matter for patent research? Agentic monitoring is the ongoing, automated tracking of a technology area or FTO position after the initial analysis, so new patents or scientific papers that affect it are surfaced continuously instead of requiring a fresh manual search each time.
Does semantic search matter for patent research? Yes. Patent claims are written in legal language that rarely matches how R&D teams describe the same technology, so semantic search across patents and scientific literature is necessary to find relevant prior art or white space that keyword search alone would miss.
Is a general LLM ever useful for patent-related work? General LLMs can be useful for summarizing or explaining a patent in plain language once it has been retrieved, but they should not be relied on as the primary patent search, patent analytics, or FTO tool, since they lack a verified, current corpus to search against.
What industries use AI-native patent intelligence platforms like Cypris? Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries that rely on accurate patent search, patent analytics, FTO, and white space analysis.
How does Cypris handle security for enterprise R&D and IP data? Cypris is built with enterprise-grade security and maintains enterprise API partnerships with OpenAI, Anthropic, and Google, supporting AI implementation for regulated R&D and IP functions without exposing sensitive competitive intelligence.
What is Cypris Q? Cypris Q is the agentic layer of the Cypris platform, allowing R&D and IP teams to run conversational, multi-step patent search and patent analytics workflows across the platform's corpus of patents and scientific literature.
White space analysis identifies where a technology area is uncontested: gaps in the patent landscape where a company can file, build, or acquire without walking into a crowded field of existing claims. Done well, it turns a patent landscape from a defensive document into an offensive one, pointing R&D toward directions competitors have not claimed rather than only flagging directions they have.
The stakes behind this are larger than the term suggests. R&D failure rates are persistently high, and a recurring, underexamined cause is validating technical opportunity through patent analysis while leaving commercial opportunity unvalidated. A program clears the patent landscape, looks open, and proceeds, only to discover the space was empty for reasons the patent record never showed. When a landscape analysis is steering investment direction, the cost of an incomplete map is not a missed filing. It is a misallocated research budget and a multi-year bet placed in the wrong direction.
The core problem is that an empty region of the patent map can mean two very different things, and most white space tools cannot tell them apart. A gap can be open because there is no market demand, because the underlying science does not work yet, or because the unit economics never close. Or the gap can be a trap: a region where competitors are active but moving through channels that never touch the patent system, such as trade secrets, defensive publications, or fast commercial execution that outruns the filing timeline. In both cases the patent map looks identical. Only data drawn from outside the patent system can tell you which kind of empty you are actually looking at, and software that only reads patents cannot make that distinction.
What effective white space analysis software actually needs to do
The single biggest differentiator among white space tools is data breadth, not visualization quality. A platform that maps gaps using patent filings alone can only ever answer half the question: where filings are sparse. It cannot tell you whether that sparseness reflects a genuinely open opportunity or an area where research has not yet reached the filing stage, because that distinction requires reading scientific literature, funding activity, and other forward-looking signal alongside the patent record.
A second differentiator is whether the software treats technology relationships as a structured problem or a keyword-matching one. Identifying uncontested territory requires understanding how technologies relate to each other conceptually, since the same underlying idea is often described with different terminology across different filings. A tool built on literal keyword or classification-code matching will systematically miss adjacent white space that uses different vocabulary for the same concept.
A third differentiator is whether white space findings stay current. A technology landscape shifts as new patents are filed and new research publishes, so a white space finding is only accurate at the moment it is generated unless the platform continues to track that area afterward. Software that treats white space as a one-time report rather than a monitored position will quietly go stale.
How to run a real white space analysis
A useful white space process moves through several linked steps rather than a single search. It starts by defining the technology scope precisely enough to bound the analysis, including the terminology variants the field uses for the same underlying concept. From there, the analysis needs to pull both patent filings and non-patent signal, such as scientific literature and funding activity, across that scope, so that gaps in the patent record can be checked against whether the underlying science or commercial activity is actually present. Genuine white space is where both are also sparse, or where literature and funding are building while patent filings have not yet caught up. A crowded patent area is not automatically a closed door either: some of the most commercially urgent positions are in contested spaces where an organization holds a real technical advantage but has under-filed relative to competitors, so the analysis needs to flag those cases rather than treating density alone as a stop sign. Once a gap is identified, it should feed directly into prior art and freedom-to-operate review on the same technology, and then stay under ongoing monitoring so a position that looks open today is still open by the time a program reaches a launch decision.
Where Cypris fits
Cypris runs on a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, so a white space query returns a map of technology relationships rather than a list of documents matching a keyword. Because the ontology drives semantic search rather than literal keyword matching, adjacent white space described in different terminology across filings is surfaced rather than missed. Cypris Q, the platform's agentic layer, runs white space analysis in natural language and lets a team move from a gap identified in the landscape directly into prior art review or freedom-to-operate assessment on the same technology, in the same environment. Because Cypris Q is agentic, that hand-off between stages runs as a connected workflow rather than a set of separate manual searches. Cypris connects white space findings to Agentic Monitoring, so a technology area flagged as open territory today continues to be tracked as new filings, papers, and competitive activity enter it. Cypris is also reachable through MCP (the Model Context Protocol), so this analysis can run inside the AI clients an R&D team already uses. Cypris meets enterprise-grade security requirements and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, and other regulated industries.
How to choose white space analysis software
The deciding question is whether white space analysis needs to happen as a one-time, query-driven project or as a continuously updated view of a technology landscape. Legacy patent analytics platforms, built primarily for IP attorneys running structured, deliberate analyses, are capable for a defined, one-time white space project scoped to the patent record. A platform built for continuous R&D decision-making, such as Cypris, is the better fit when white space findings need to connect directly into prior art, freedom-to-operate, and ongoing monitoring, across patents and the broader scientific and market signal that determines whether a gap is actually worth pursuing.
FAQ
**What is white space analysis in patents?**
White space analysis identifies gaps in a patent landscape: technology areas where few or no existing filings claim the territory. It shows where a company can file, build, or acquire with lower risk of running into existing patent claims. It is used alongside prior art and freedom-to-operate searches to guide R&D investment decisions, not only to assess risk on a specific product.
**What software is best for white space analysis?** The strongest white space software connects patent data with scientific literature and other forward-looking signal, rather than mapping gaps from patents alone. Cypris runs on a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, mapping technology relationships instead of returning keyword matches, and connects findings to ongoing monitoring so a gap identified today stays current.
**How is white space analysis different from a prior art search?**
A prior art search looks for existing disclosures that might affect the novelty of a specific invention. White space analysis looks across a broader technology area to identify where filings are sparse or absent. It informs where to direct R&D rather than assessing a single idea against existing documents.
**Can white space analysis include non-patent data?** Yes, and this improves accuracy. A gap in the patent record can reflect genuinely open territory, or it can reflect an area where research has not yet reached the filing stage. Platforms that connect patent data with scientific literature can distinguish between these two cases. Patent-only tools cannot.
**Does white space analysis replace freedom-to-operate assessment?**
No. White space analysis identifies where to direct R&D investment based on gaps in the landscape. Freedom-to-operate assessment evaluates whether a specific, already-defined product or process risks infringing existing claims. Teams typically run white space analysis earlier in a program and freedom-to-operate assessment closer to a launch decision.
**How often should white space analysis be updated?** Technology landscapes shift as new patents are filed and new research publishes. A white space finding is only accurate at the moment it is generated unless it is monitored afterward. Cypris connects white space findings to ongoing monitoring, so a gap identified today continues to be tracked as new activity enters that technology area.
**Is free patent search software sufficient for white space analysis?**
Free patent search tools are a useful starting point for spot-checking specific technical ideas, but they offer no clustering, visualization, or systematic methodology for identifying gaps across a technology landscape. Enterprise white space analysis requires a platform built for landscape mapping, not document-by-document search.
**Why does a crowded patent area sometimes still represent an opportunity?** Patent density measures competitive intensity, not the absence of opportunity. Some of the most commercially urgent positions a company can take are in crowded spaces where the organization holds a real technical advantage but has under-filed relative to competitors. Treating a crowded map as a closed door can forfeit exactly the positions most worth pursuing.
A freedom-to-operate search answers a specific question: can a company make, use, or sell a product without infringing someone else's active patent claims. This differs from a novelty or prior art search, which asks whether an invention is new. FTO asks whether launching it is safe, and getting the answer wrong carries direct commercial risk, not just a delayed filing.
The consequences of an incomplete FTO analysis are not abstract. Patent infringement verdicts routinely reach into the hundreds of millions of dollars, and a single missed blocking patent can force a hardware redesign, a halted product line, or years of litigation over technology that could have been designed around during development. For a mid-size company, a university spinout, or any organization without a large in-house IP function, a nine-figure verdict or a multi-year injunction is not a survivable event. The FTO analysis conducted during development is often the only real risk mitigation mechanism a program has.
A growing share of that analysis is now being run with general-purpose AI tools that were never built for it. These tools reason from training data rather than a live patent record, so their outputs adopt the format and tone of an FTO report without the underlying data infrastructure to support it. The result is a specific and dangerous failure mode: an incomplete analysis delivered with high confidence, with no signal to the reader that the coverage is partial. A team that treats that output as a finished FTO clearance is taking on risk it cannot see.
How to run an AI-powered FTO report
A rigorous AI-powered FTO analysis moves through several linked steps, and the quality of the output depends on how carefully each one is done, not just on which model is generating the summary. The most reliable version of this process runs as an agentic workflow: rather than a single prompt, a sequence of connected steps that search, verify, and stratify against a live patent record, ideally over a structured R&D ontology and connected to the patent data through a protocol such as MCP (the Model Context Protocol).
The first step is defining the product or process precisely enough to search against. A vague description produces a vague search. The scope should specify the technical architecture, the materials or methods involved, and the specific claims of function the product makes, since claim-level FTO risk is assessed against exactly this level of detail, not a general category description.
The second step is running that scope against the patent corpus at the level of the claims themselves, not a keyword index. Claim language is technical and often uses different terminology across different filings for the same underlying concept, so a search that only matches literal keywords will miss patents that a human examiner would immediately recognize as relevant. A capable AI-powered search reads claim text semantically and against the scope's technical features, rather than pattern-matching surface language.
The third step is verifying every result against a real, current legal record: assignee, filing date, publication status, and whether a patent is active, abandoned, or subject to a terminal disclaimer. This is the step where general-purpose AI tools fail most visibly. A model reasoning from training data will sometimes infer an assignee rather than retrieve it, producing plausible-looking attributions that are not actually verifiable. In an FTO context, an unverified assignee is functionally equivalent to no assignee, since it cannot support a licensing inquiry or a risk assessment.
The fourth step is risk stratification, not a flat list of matches. A useful FTO report groups results by risk level, distinguishing patents whose claims directly read on the proposed product from patents that are only tangentially related. It should also surface portfolio-level patterns, since a single company sometimes files a coordinated set of patents covering a composition, an architecture, and a manufacturing method for the same underlying technology. Clearing one patent in that set does not resolve exposure to the portfolio as a whole, and a report that only lists individual hits without connecting them will understate real risk.
The fifth step is monitoring the result afterward, not treating it as a one-time report. An FTO position reflects the patent landscape at the moment the search was run, and new filings can change that picture before a product actually launches, particularly on programs with long development timelines. A cleared position from eighteen months ago is not the same as a cleared position today.
Where Cypris fits
Cypris treats freedom-to-operate as one stage in a connected R&D decision process rather than an isolated search task. It runs on a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, so an FTO query surfaces claim-level risk across a full technology landscape rather than a list of patents that happen to share keywords with a product description. Because the ontology drives semantic search, a blocking patent that describes the same underlying claim in different terminology is surfaced rather than missed. Cypris Q, the platform's agentic layer, runs FTO agents that flag blocking risk directly and connect that assessment to the prior art and white space work that typically precedes an FTO decision, so a team moves through the full stage-gate process in one environment as an agentic workflow rather than a set of disconnected searches. Cypris pairs FTO assessment with Agentic Monitoring, so a cleared freedom-to-operate position continues to be tracked as new filings enter the space rather than going stale the moment the initial report is delivered. Cypris is reachable through MCP (the Model Context Protocol), so FTO analysis can run inside the AI clients an R&D or IP team already uses. Cypris meets enterprise-grade security requirements and serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, and other regulated industries.
How to choose FTO patent search software
The deciding question is whether the assessment needs to stand alone or connect to the rest of an R&D decision. Legacy, patent-centric analytics platforms provide credible FTO analysis for a defined product or process, built primarily for IP professionals running structured, deliberate searches. A platform built for continuous R&D decision-making, such as Cypris, is the better fit for teams that want FTO risk assessed as part of the same workflow as prior art and white space analysis, with the resulting position monitored afterward rather than treated as a one-time report. Given that a mistaken or incomplete FTO assessment carries direct commercial risk, the completeness and currency of the underlying data should weigh more heavily than convenience or price alone.
FAQ
**What is a freedom-to-operate (FTO) search?**
A freedom-to-operate search determines whether making, using, or selling a specific product or process would infringe another party's active patent claims in a given jurisdiction. It differs from a novelty or prior art search, which asks whether an invention is new. FTO asks whether commercializing it is legally safe.
**How do I run an AI-powered FTO report?** Define the product or process precisely, including its technical architecture and specific claims of function. Search that scope against the patent corpus at the claim level using semantic rather than keyword matching. Verify every result against a current legal record, including assignee, filing date, and legal status. Stratify results by risk level rather than listing flat matches, and check for coordinated patent filings covering the same technology from a single source. Monitor the cleared position afterward, since new filings can change the picture before launch.
**What is the best FTO patent search software?**
The strongest FTO software connects claim-level analysis to the rest of an R&D decision process rather than treating FTO as an isolated search. Cypris runs FTO assessment on a corpus of more than 500 million patents and scientific papers organized through a proprietary R&D ontology, surfacing claim-level risk and monitoring it afterward rather than delivering a one-time report.
**How is an FTO search different from a patentability search?** A patentability search asks whether an invention is novel enough to be granted a patent. An FTO search asks whether commercializing that invention would infringe someone else's existing patent, regardless of whether the invention itself is novel. An invention can be patentable and still infringe another company's active claims.
**Why is a freedom-to-operate search necessary before a product launch?**
Launching a product that infringes an active patent can result in injunctions, damages, and forced redesigns after significant investment has already been made. An FTO search conducted during development identifies blocking claims early enough to design around them, license them, or reconsider the approach before launch costs are sunk.
**Can AI tools identify all blocking patents automatically?** No FTO process guarantees complete automatic identification, and general-purpose AI tools carry a specific risk: they can produce a confident, well-formatted report while missing most of the relevant landscape, with no signal to the reader that the analysis is incomplete. Claim scope, prosecution history, and continuation chains require careful interpretation, and platforms with claim-level analysis grounded in a live patent corpus reduce that risk far more than tools reasoning from training data alone.
**Is free patent search software sufficient for an FTO clearance?**
Free patent search tools are useful for an initial, informal scan, but they provide no claim-scope analysis, risk stratification, or systematic FTO methodology. A genuine FTO clearance intended to support a product launch decision should rely on a platform or process built specifically for FTO.
**How does FTO search relate to white space and prior art analysis?** The three are linked but distinct. White space analysis identifies where a technology area is open for investment. Prior art search evaluates whether a specific invention is novel. FTO search evaluates whether commercializing a specific, already-defined product risks infringing existing claims. Teams typically move through white space, then prior art, then FTO as a program advances toward launch.
**Can AI agents run a freedom-to-operate analysis?**
AI agents can run much of an FTO analysis when they are grounded in a live patent record rather than training data. An agentic workflow can define the scope, run semantic search over a structured R&D ontology, verify results against the legal record, and stratify risk as connected steps rather than a single prompt. Connecting those agents to patent data through a protocol such as MCP (the Model Context Protocol) lets the analysis run inside an existing AI client, though high-stakes launches still benefit from expert review.
**Should FTO risk be monitored after the initial assessment?** Yes. A freedom-to-operate position reflects the patent landscape at the time of the search, and new filings can change that picture before a product actually launches, particularly for programs with long development timelines. Platforms that pair FTO assessment with ongoing monitoring keep a cleared position current rather than treating it as a one-time report.
What an MCP server is, how the Model Context Protocol connectsAI assistants to patent and scientific literature databases, and how Cyprisuses MCP to deliver R&D intelligence.
AnAI assistant cannot reach live patent data on its own. Every patent searchquestion requires manual work first: pull the patent family from a database,copy the claims into the chat, ask the question, copy the answer elsewhere. TheModel Context Protocol, or MCP, removes that manual step. MCP lets an AIassistant connect directly to external data sources during a conversation.
What MCP is
MCPis an open standard for connecting AI assistants to external data sources andtools. Anthropic introduced MCP in November 2024. A data source, such as apatent database or a scientific literature index, exposes itself through an MCPserver. Any MCP-compatible AI client, including Claude Desktop and ChatGPTDesktop, can connect to that server and use it directly.
BeforeMCP, connecting an AI assistant to a specific database required a customintegration for each assistant and each data source. MCP standardizes thatconnection. One server, built once, works with any MCP-compatible client.
AnMCP server exposes three things to a connected AI client: tools it can call,such as a patent search function; resources it can read, such as patent recordsor paper abstracts; and prompts that template common tasks. A connected AIassistant can call a tool mid-conversation, retrieve current data, and answerbased on that data. It does not have to rely only on what it learned duringtraining.
Why MCP matters for patent search
Patentand scientific literature data changes constantly. A patent landscape shiftswith every new filing. A freedom-to-operate risk can appear the week before aproduct launch. A relevant paper can publish while a literature review isunderway. An AI assistant reasoning only from training data cannot know aboutany of this. It also cannot flag that its answer might be incomplete.
Patentdata is structured and authoritative. Assignee, filing date, legal status, andclaim language are facts recorded in a system of record: USPTO, EPO, WIPO.These facts do not benefit from being paraphrased from a webpage that oncementioned them. MCP lets an AI assistant query the system of record directly.It can cite exactly what it found, inside the same conversation where theanalysis is happening.
How MCP is used in patent search and R&D workflows
Aresearcher using an MCP-connected AI client can describe an invention in plainlanguage. The assistant searches live patent and literature sources directly.No query translation step is required. An IP analyst can ask about a specificassignee's recent filing activity and get an answer sourced from a current APIcall, not from training data. A scientist reviewing a technology area can pullrecent papers, patents, and citation relationships into the same conversationwhere a landscape summary is being drafted.
TheAI assistant stops operating next to the data. It starts operating on the datadirectly. Output quality depends on what data the assistant can reach throughits connected MCP server.
Where open-source MCP servers are useful, and where they stop beingenough
Open-sourceMCP servers connect AI clients to major patent and literature sources: USPTOsearch and litigation APIs, EPO's Open Patent Services for European patentdata, Google Patents, and academic sources including arXiv, PubMed, andSemantic Scholar. For a team that needs one specific data source from onespecific AI client, these are frequently the right choice. Several are activelymaintained.
Theseconnectors answer one question against one source. They do not carry contextacross a decision. A prior art search, a white space analysis, afreedom-to-operate assessment, and a regulatory check are linked stages of thesame decision: whether an R&D program is worth pursuing. The result of onestage should inform how the next is read. A single-source MCP server accuratelyreturns what its database contains. It has no framework for connecting a priorart result to a freedom-to-operate risk rating, because it answers one kind ofquery, not a workflow.
How Cypris uses MCP
Cyprisis an R&D intelligence platform, reachable through MCP, built on a corpusof more than 500 million patents and scientific papers organized through aproprietary R&D ontology. A connected AI client using Cypris through MCPworks with structured domain context, not raw results from a single searchendpoint.
Theagents available through Cypris's MCP server map to the stage-gate decisions anR&D or IP team makes: prior art review, white space identification,freedom-to-operate risk assessment, and regulatory tracking. Cypris Q, theplatform's agentic layer, and enterprise API partnerships with OpenAI,Anthropic, and Google make Cypris accessible inside the AI environmentsenterprise R&D and IP teams already use. Cypris meets enterprise-gradesecurity requirements and serves hundreds of enterprise customers acrosspharmaceuticals, chemicals, advanced materials, energy, and other regulated,security-conscious industries.
Asingle-source, open MCP server is the right tool for retrieval from one patentoffice or literature source inside one AI client. Cypris is built for adifferent need: an AI assistant that carries domain context across prior art,white space, freedom-to-operate, and regulatory decisions in the same workflow.
Setting up an MCP connection
Connectingan MCP-compatible AI client to a data source is a configuration step. Point theclient at the server. Authenticate if the source requires it. Its tools becomeavailable in conversation. Cypris is accessed through enterprise APIpartnerships rather than a self-hosted connection. This is what allows Cypristo meet enterprise security requirements while functioning as an MCP serverinside a team's existing AI client.
FAQ
**What is MCP?** MCP, theModel Context Protocol, is an open standard that lets an AI assistant connectdirectly to external data sources and tools during a conversation. Anthropicintroduced MCP in November 2024. MCP replaces custom, one-off integrations witha single protocol that works across MCP-compatible AI clients and MCP servers.
**Whatis an MCP server?** An MCP server is a connector, built on the Model ContextProtocol, that exposes a data source or tool to an MCP-compatible AI client.For patent search and R&D intelligence, an MCP server can expose patentdatabases, scientific literature indexes, or a broader intelligence platformlike Cypris to an AI assistant such as Claude Desktop or ChatGPT Desktop.
**How is MCP different froma standard API integration?** A standard integration is built once for oneapplication to connect to one data source. MCP standardizes the connection. AnyMCP-compatible AI client can use any MCP server without a new integration foreach pairing.
**Whydoes MCP matter for patent search?** Patent and scientific literature datachanges continuously. It is only useful when current and verifiable against asystem of record. An AI assistant reasoning from training data alone cannotreflect a recent filing. MCP lets the assistant query authoritative sourcesdirectly and answer based on what it retrieves.
**Does connecting to an MCPserver guarantee accurate patent search results?** No. MCP determines whetheran AI assistant can reach a data source in real time. It does not determine howcomplete that source is. A single-source MCP server accurately returns whatthat one source contains. That is not the same as complete patent landscapecoverage.
**Whatis the difference between an MCP connector and an R&D intelligence platformlike Cypris?** A connector answers one query against one data source. Cyprissupports a decision process where prior art, white space, freedom-to-operate,and regulatory findings inform each other. Cypris runs on a corpus of more than500 million patents and scientific papers organized through a proprietaryR&D ontology, delivered through an MCP server and enterprise APIpartnerships with OpenAI, Anthropic, and Google.
**Can Cypris be usedtogether with open-source MCP servers?** Yes. Teams often use open-source,single-source MCP connectors for specific databases alongside Cypris forworkflows that require reasoning across multiple linked patent and R&Ddecisions.
**Do I need to be a developer to use Cypris throughMCP?** No. Once Cypris is connected inside a compatible AI client, using it isa natural-language conversation. Cypris is accessed through enterprise APIpartnerships built to remove setup
Green ammonia has become a priority for industrial decarbonization, and its patent landscape is distinctive because low-carbon ammonia is being pursued through several competing routes, each with its own chemistry and process engineering. Ammonia is one of the highest-volume chemicals made, the foundation of nitrogen fertilizer, and a candidate hydrogen carrier and fuel, and its conventional production, reforming fossil methane for hydrogen and combining it with nitrogen in the high-temperature, high-pressure Haber-Bosch process, is carbon-intensive: the International Energy Agency attributes to ammonia production roughly 1.3 percent of energy-system carbon dioxide emissions and about 2 percent of total final energy consumption, with direct carbon dioxide emissions on the order of 450 million tonnes a year.¹ Decarbonizing it is therefore a climate priority, and the routes divide into distinct regions of patenting: renewable-powered Haber-Bosch, which replaces fossil hydrogen with hydrogen from water electrolysis and feeds a modified synthesis loop;⁴ direct electrochemical nitrogen reduction, which converts nitrogen to ammonia electrochemically under mild conditions;²,⁵ plasma-electrocatalysis; nitrogen-oxide reduction; and solid-oxide electrochemical cells. Cutting across the routes are the catalysts, the electrode and cell designs, and the process control that adapts synthesis to variable renewable power. Because a competitive process depends on several of these, freedom-to-operate and white space analysis must span the routes and the layers together.
The landscape is being pulled forward by decarbonization and by the sheer scale of demand, so even incremental efficiency and emission gains are valuable. The routes sit at very different stages: renewable-powered Haber-Bosch is the most commercially mature and holds the largest share of patent activity, with established engineering firms filing on integrating intermittent hydrogen supply, buffer storage, and dynamic synthesis-loop control, while direct electrochemical, plasma, and solid-oxide routes are earlier, advancing rapidly in catalyst design and device operation but still facing fundamental efficiency and selectivity limits. Theoretical analysis places the maximum energy efficiency of the leading lithium-mediated electrochemical process at roughly 28 percent, and scaling relations among reaction intermediates constrain how selective nitrogen-to-ammonia catalysts can be, which is why catalyst design is the central research problem for these routes.³,⁷ This shows in the record: across the Cypris corpus of more than 500 million patents and scientific papers, the green and electrochemical ammonia set holds on the order of 3,613 families and grew from about 155 in 2020 to roughly 523 in 2024, with the most active assignees led by established ammonia-technology licensors such as Topsoe and Casale alongside energy majors, and China well ahead of the United States and Denmark on geography; 2025 and 2026 counts are partial because of the publication lag.
The strategic question is which route and layer to back, and the white space sits where the chemistry is hardest. In renewable-powered Haber-Bosch, the open ground is in dynamic operation and process integration that let a plant follow variable renewable power. In the electrochemical routes, catalysts that raise ammonia yield and suppress the competing hydrogen-evolution reaction are the central problem, and they are comparatively open and high-value.²,⁵ Plasma-electrocatalysis and solid-oxide cells are earlier, less-crowded routes, and modular, decentralized designs are strategically important where distributed fertilizer and fuel production matter.⁶ Reading the landscape by route, catalyst, and process, and tracking both the patents and the underlying catalysis research, is what separates a crowded region from an open one.
Where the green-ammonia white space is
Nitrogen-reduction catalysts. Catalysts that raise ammonia yield and suppress the competing hydrogen-evolution reaction are the central problem for the electrochemical route and a comparatively open, high-value layer.²,⁵
Dynamic, flexible Haber-Bosch. Process control and loop designs that let a synthesis plant follow variable renewable power are a large, active layer in the most mature route.⁴
Plasma-electrocatalysis and solid-oxide cells. These earlier routes, including intermediate-temperature solid-oxide electrochemical cells, are less crowded and offer differentiated positions.
Nitrogen-oxide-mediated routes. Pathways that route through nitrogen-oxide intermediates are an emerging, distinct area of chemistry.
Modular, decentralized systems. Small-scale, modular ammonia production near renewable resources and demand is a strategically important system layer.⁶
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans several synthesis routes, each with its own catalysts and process, requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by route, catalyst, and process across varied terminology, attribution that normalizes engineering-firm, startup, and academic filers to canonical entities, and continuous monitoring that keeps pace with a decarbonization-driven surge. Because ammonia-synthesis advances appear in scientific and catalysis literature before they are patented, reading both patents and literature gives the earliest signal of where scalable routes are emerging.
Where Cypris fits
Cypris runs patent landscape and white space analysis for multi-route chemical fields such as green ammonia across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by route, renewable Haber-Bosch, electrochemical nitrogen reduction, plasma, nitrogen-oxide, and solid-oxide, and by layer, catalyst, cell and electrode, and process control, and normalizes engineering-firm, startup, and academic filers to canonical entities, so a team can resolve which routes and layers are crowded and which remain open as white space, and can track new entrants as the field scales. Semantic search across patents and scientific literature connects filings to the underlying catalysis research, which is where green-ammonia advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined route over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is the green ammonia patent landscape? The green ammonia patent landscape is the set of patents covering low-carbon ammonia production. It divides across competing routes, renewable-powered Haber-Bosch, direct electrochemical nitrogen reduction, plasma-electrocatalysis, nitrogen-oxide reduction, and solid-oxide electrochemical cells, each with distinct catalysts and process IP. Each route is a distinct region of patenting.
Why is green ammonia a decarbonization priority? Green ammonia is a decarbonization priority because ammonia is one of the largest-volume chemicals, the backbone of fertilizer, and a candidate fuel and hydrogen carrier, while its conventional production is fossil-fuel-based. The International Energy Agency attributes to it roughly 1.3 percent of energy-system carbon dioxide emissions and about 2 percent of final energy use. Decarbonizing it addresses both food and energy systems.
What routes does the green-ammonia landscape cover? The landscape covers renewable-powered Haber-Bosch, direct electrochemical nitrogen reduction, plasma-electrocatalysis, nitrogen-oxide reduction, and solid-oxide electrochemical cells. Each uses different chemistry and sits at a different maturity, with renewable Haber-Bosch the most commercially advanced. Freedom-to-operate and white space analysis must treat them separately.
Where is the white space in green ammonia? The white space includes nitrogen-reduction catalysts, dynamic and flexible Haber-Bosch operation, plasma-electrocatalysis and solid-oxide cells, nitrogen-oxide-mediated routes, and modular decentralized systems. Renewable Haber-Bosch is comparatively mature and holds the most patents. The most open, high-value opportunities are in electrochemical catalysts and the earlier routes.
Why are nitrogen-reduction catalysts so important? Nitrogen-reduction catalysts are important because the direct electrochemical route's viability depends on raising ammonia yield while suppressing the competing hydrogen-evolution reaction, which otherwise dominates, and because scaling relations among intermediates limit selectivity. Solving this is the central technical problem for that route. The catalyst compositions and cell designs that achieve it are foundational and defensible.
Why does green-ammonia analysis need scientific literature? Green-ammonia analysis needs scientific literature because catalyst and cell advances appear in chemistry research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the green ammonia patent landscape? Software for the green-ammonia landscape should cluster activity by route and process layer, resolve engineering-firm, startup, and academic filers to canonical owners, search patents and scientific literature semantically, and monitor a decarbonization-driven field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use green ammonia patent landscape analysis? Green ammonia patent landscape analysis is used by R&D, innovation, IP, and strategy teams at chemical, fertilizer, energy, and engineering companies, catalysis developers, and their partners, as well as investors and policymakers. It informs which route to back, where to file, and where competitors are concentrated. Cypris serves hundreds of enterprise customers across chemicals, energy, advanced materials, and other regulated industries.
Endnotes
- International Energy Agency (2021). Ammonia Technology Roadmap. https://www.iea.org/reports/ammonia-technology-roadmap
- Li, S., et al. (2021). Electrochemical ammonia synthesis: mechanistic understanding and catalyst design. Chem, 7(12). https://doi.org/10.1016/j.chempr.2021.01.009
- Fu, X., Zhou, Y., Nørskov, J. K., & Chorkendorff, I. (2024). Electrochemical ammonia synthesis: the energy efficiency challenge. ACS Energy Letters, 9(12). https://doi.org/10.1021/acsenergylett.4c02954
- Gu, Y., et al. (2024). Ambient electrochemical ammonia synthesis: from theoretical guidance to catalyst design. Advanced Science, 11. https://doi.org/10.1002/advs.202308979
- Sankannavar, A., & Shetty, A. (2024). Exploring nitrogen reduction reaction mechanisms in electrochemical ammonia synthesis: a comprehensive review. Journal of Energy Chemistry, 92. https://doi.org/10.1016/j.jechem.2024.01.024
- Chebrolu, V. T., et al. (2023). Overview of emerging catalytic materials for electrochemical green ammonia synthesis. Carbon Energy, 5. https://doi.org/10.1002/cey2.361
- Tsai, C., Vojvodić, A., Montoya, J., & Nørskov, J. K. (2015). The challenge of electrochemical ammonia synthesis: nitrogen scaling relations. ChemSusChem, 8(13). https://doi.org/10.1002/cssc.201500322
The solid-state battery race is being decided at the electrolyte, and the patent landscape divides along three chemistries: sulfide, oxide, and polymer. A solid-state battery replaces the liquid electrolyte of a conventional lithium-ion cell with a solid one, which can improve safety and enable higher-energy electrode pairings. The central engineering problem is that no single solid electrolyte class simultaneously optimizes the three properties that matter, room-temperature ionic conductivity, stability at the electrode interfaces, and manufacturability, so each class represents a different set of trade-offs and a different region of the patent landscape. Understanding where filing activity concentrates by class, and where it does not, is how R&D and IP teams locate defensible positions in one of the fastest-moving areas of energy patenting.
The scale of that activity is documented in primary data. A joint analysis by the European Patent Office and the International Energy Agency found that international patent families in electricity storage grew from 1,029 in 2000 to more than 7,000 in 2018, at an average of 14 percent per year between 2005 and 2018, roughly four times the economy-wide average.¹ Within that, solid-state lithium-ion filings grew faster still, at around 25 percent per year since 2010, reaching 211 international patent families in 2018, with Japan the dominant country of origin, and solid-state electrolyte activity rose several-fold over the decade.¹ More recent analysis reports that energy storage now accounts for roughly 40 percent of all energy-related patenting, confirming that the field has continued to accelerate.² Because applications publish about eighteen months after filing, the most recent activity is under-represented, so these figures understate the current state.
The three electrolyte classes occupy distinct positions defined by their physics. Sulfide electrolytes reach the highest room-temperature ionic conductivities, on the order of 10 to the minus two siemens per centimeter, comparable to or exceeding liquid electrolytes, but they are chemically and electrochemically unstable at the electrode interfaces and sensitive to moisture, so the dominant patenting and research effort targets interfacial stabilization and dry-processing manufacture.³,⁴ Oxide electrolytes, principally garnet-type structures, offer good stability and a wide electrochemical window with intermediate conductivity, typically in the 10 to the minus four to 10 to the minus three siemens per centimeter range, but they are hard and brittle, which makes achieving low-resistance interfaces and scalable, thin, dense layers the central challenge.⁵ Polymer electrolytes are the most manufacturable, compatible with existing roll-to-roll processing, but historically suffered from low room-temperature conductivity, on the order of 10 to the minus seven siemens per centimeter for early systems, though engineered solid polymer electrolytes have since reached the milli-siemens-per-centimeter range, which is why manufacturability arguments increasingly favor them despite the historical conductivity gap.⁶
What the three classes trade off
Sulfide. Highest ionic conductivity, comparable to liquid electrolytes, but poor interfacial and moisture stability; patenting concentrates on interface engineering and dry manufacturing.³
Oxide. Good stability and a wide electrochemical window with intermediate conductivity, but brittleness and interfacial resistance dominate the technical and patenting effort.⁵
Polymer. Best manufacturability and compatibility with existing processes, historically limited by low room-temperature conductivity that engineered systems are now closing.⁶
Emerging classes. Halide and composite electrolytes are an active newer area that combines properties across classes, and the interfacial-engineering literature increasingly treats all classes together.⁷
How to analyze the electrolyte landscape and find white space
Scope the analysis by electrolyte class and by the property being improved, since sulfide, oxide, and polymer activity concentrate on different problems and should be assessed separately.
Aggregate to the patent-family level and attribute to organizations, so international coverage is not double-counted and activity is correctly assigned by country and assignee.
Map patents against the underlying materials research, because solid-electrolyte advances appear in scientific literature before they are patented, so literature coverage gives the earliest signal.
Identify dense and sparse regions within each class, distinguishing crowded problems, such as sulfide interface stabilization, from open white space, such as specific composite or processing approaches.
Correct for publication lag and monitor continuously, since the most recent activity is under-represented and the field moves quickly.
Where Cypris fits
Cypris runs patent landscape and white space analysis for fast-moving fields such as solid-state batteries across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by electrolyte class and by the property being improved, and normalizes organizations to canonical entities, so a team can resolve which classes and problems are crowded and which remain open as white space. Semantic search across patents and scientific literature connects filings to the underlying materials research, which matters in solid-state batteries because advances appear in the literature before they are patented. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the class-level scoping, attribution, and gap analysis, and Agentic Monitoring tracks a defined chemistry over time and flags new patents and papers as they publish, which is essential where recent activity is under-represented by publication lag. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What are the three main solid-state battery electrolyte classes?
The three main solid-state battery electrolyte classes are sulfide, oxide, and polymer. They trade off room-temperature ionic conductivity, stability at the electrode interfaces, and manufacturability, and no single class optimizes all three. Each occupies a distinct region of the patent landscape, with halide and composite electrolytes an emerging fourth area.
How do sulfide, oxide, and polymer electrolytes compare?
Sulfide electrolytes have the highest ionic conductivity, around 10 to the minus two siemens per centimeter, but poor interfacial and moisture stability. Oxide garnets offer good stability with intermediate conductivity but are brittle. Polymers are the most manufacturable but historically had low conductivity, which engineered systems are now improving.
How fast is solid-state battery patenting growing?
Solid-state battery patenting is growing quickly. Electricity-storage international patent families grew about 14 percent per year from 2005 to 2018, four times the economy-wide average, and solid-state lithium-ion filings grew around 25 percent per year since 2010. Energy storage now accounts for roughly 40 percent of all energy-related patenting.
Why does ionic conductivity differ so much between electrolyte classes?
Ionic conductivity differs between electrolyte classes because it is governed by the material's structure and ion-transport mechanism. Sulfides allow fast ion movement and reach conductivities comparable to liquids, oxides are intermediate, and polymers historically conducted far more slowly at room temperature. Engineering has narrowed the polymer gap substantially.
Which electrolyte class is winning?
No electrolyte class has decisively won, because each optimizes different properties. Sulfides lead on conductivity, oxides on stability, and polymers on manufacturability, and patenting concentrates on each class's specific weakness. The manufacturability advantage of polymers and the conductivity of sulfides are both driving heavy activity, with the outcome still open.
How do you find white space in the solid-state electrolyte landscape?
Finding white space in the solid-state electrolyte landscape means scoping by class and by the property being improved, mapping patents and scientific literature, and identifying the sparse regions within each class. Because advances appear in research first, literature coverage gives early signal. The white space is where a specific composition or processing approach is viable but few patents yet exist.
Why does solid-state battery analysis need scientific literature?
Solid-state battery analysis needs scientific literature because electrolyte and interface advances appear in materials research before they are patented, so the literature gives the earliest signal of a viable approach. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
Why does publication lag matter in the battery patent landscape?
Publication lag matters because applications publish about eighteen months after filing, so the most recent solid-state activity is under-represented in current data. In a field growing this quickly, the latest figures understate the true state. Longer-window trends and continuous monitoring are more reliable.
Who uses solid-state battery patent landscape analysis?
Solid-state battery patent landscape analysis is used by R&D, innovation, IP, and strategy teams at battery makers, automotive and energy companies, materials developers, and their partners. It informs which electrolyte class to pursue, where to file, and where competitors are concentrated. Cypris serves hundreds of enterprise customers across energy, advanced materials, chemicals, and other regulated industries.
Endnotes
- International Energy Agency & European Patent Office (2020). Innovation in Batteries and Electricity Storage: A Global Analysis Based on Patent Data. https://www.iea.org/reports/innovation-in-batteries-and-electricity-storage
- International Energy Agency (2026). The State of Energy Innovation 2026. https://www.iea.org/reports/the-state-of-energy-innovation-2026
- Richter, F. H. et al. (2020). Interfacial challenges for all-solid-state batteries based on sulfide solid electrolytes. Journal of Materiomics. https://doi.org/10.1016/j.jmat.2020.09.003
- Gamo, H., Nagai, A. & Matsuda, A. (2023). Toward Scalable Liquid-Phase Synthesis of Sulfide Solid Electrolytes for All-Solid-State Batteries. Batteries. https://doi.org/10.3390/batteries9070355
- Wei, Z. et al. (2024). Oxide Solid Electrolytes in Solid-State Batteries. Batteries & Supercaps. https://doi.org/10.1002/batt.202400667
- Wei, Z., Guo, R., Li, C. & Peng, H. (2025). Why Will Polymers Win the Race for Solid-State Batteries? Advanced Science. https://doi.org/10.1002/advs.202510481
- Chae, S. et al. (2026). Interfacial Engineering for Layered Oxide Cathodes in All-Solid-State Batteries. Batteries & Supercaps. https://doi.org/10.1002/batt.70366