Insights on Innovation, R&D, and IP
Perspectives on patents, scientific research, emerging technologies, and the strategies shaping modern R&D
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
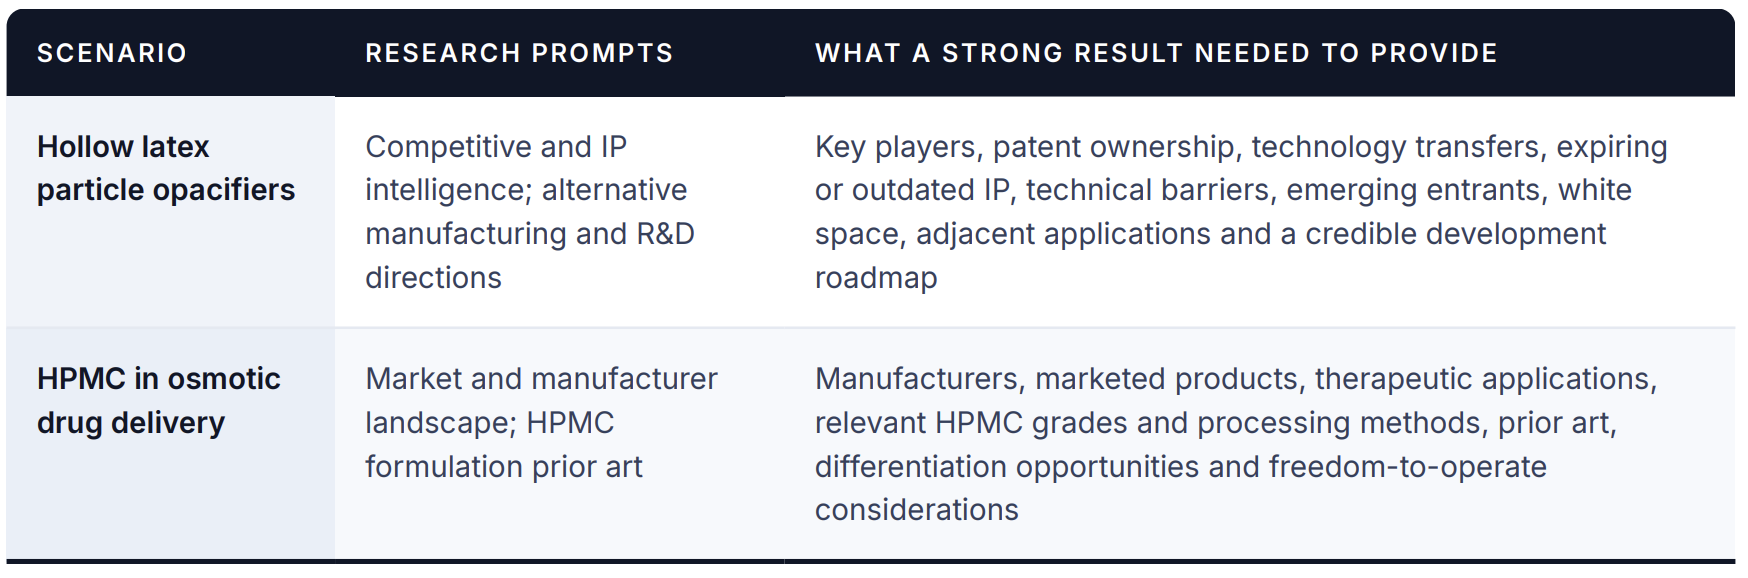
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
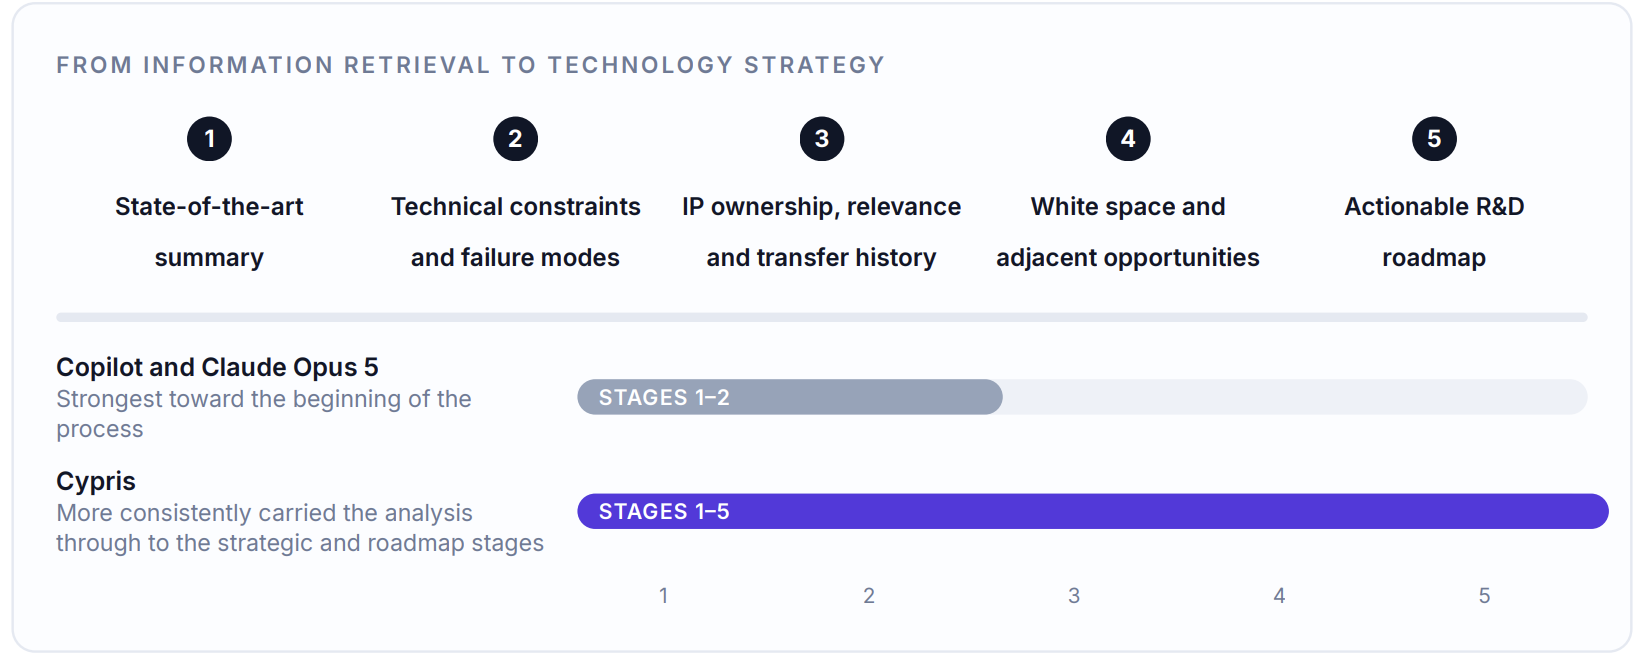
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
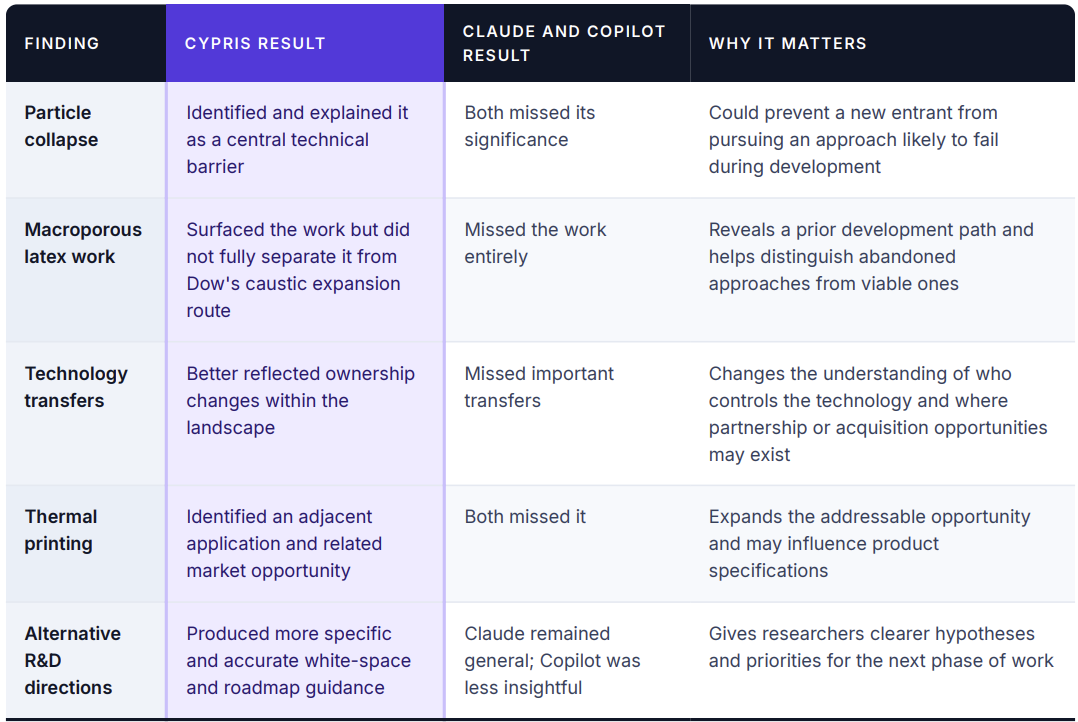
Comparative findings at a glance
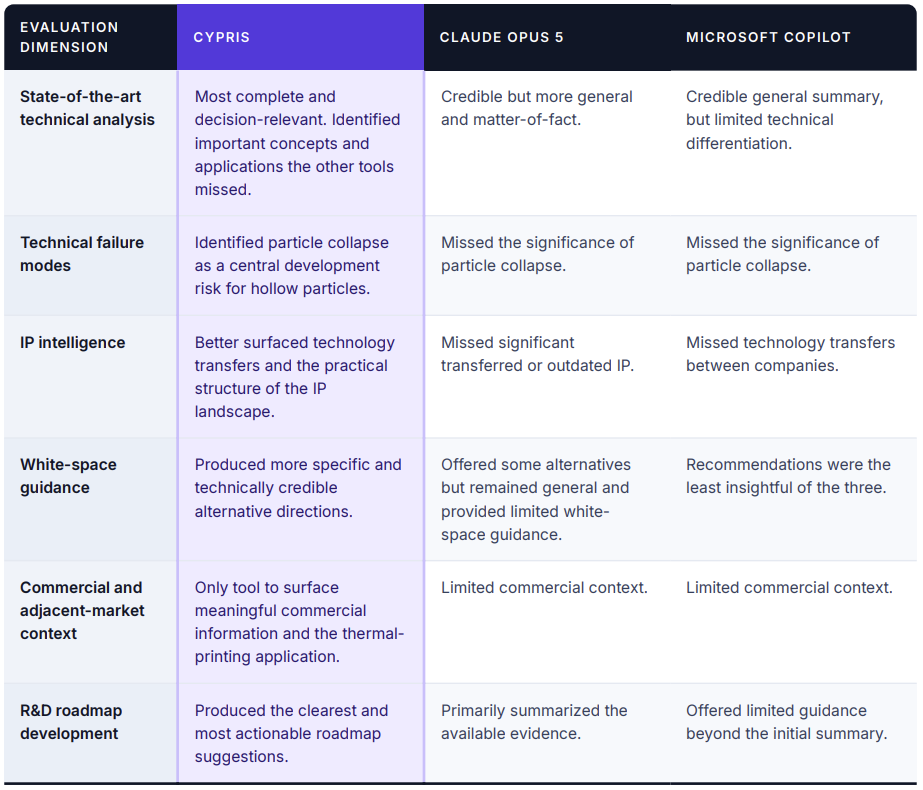
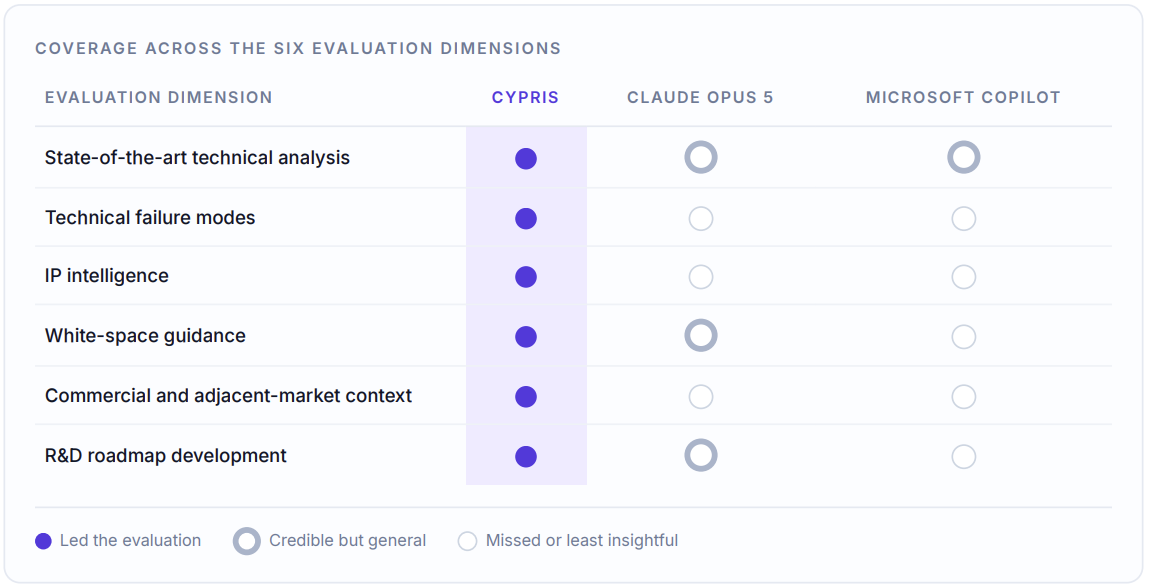
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
Former Dow Research Fellow Compares Cypris, Copilot & Claude for Chemical Intelligence
All Blogs
Direct lithium extraction has become central to scaling lithium supply, and its patent landscape is distinctive because DLE is not a single technology but a set of competing route families, each with its own materials and mechanism. Conventional brine production concentrates lithium in solar evaporation ponds over many months to years, which is slow, land-intensive, and limited to favorable climates; DLE instead recovers lithium selectively from brine using engineered materials, which is faster, has a smaller footprint, and can tap lower-grade and unconventional brines. National-laboratory work classifies the field into five route families, each a distinct region of patenting: adsorption, which captures lithium on aluminum-based or other sorbents; ion exchange, which uses manganese- or titanium-based ion-sieve sorbents and can work on lower-grade brines; solvent extraction; membrane separation; and electrochemical methods.¹,²,³,⁴,⁷ Cutting across the routes are the sorbent and membrane materials, the brine pretreatment that removes hardness and competing ions such as magnesium, the regeneration chemistry, and the conversion of recovered lithium into battery-grade hydroxide or carbonate. Because a commercial process depends on several of these layers, freedom-to-operate and white space analysis must span the routes and the supporting steps together.
The landscape is being pulled forward by demand and by resource economics. Lithium sits at the center of battery supply chains: world reserves are on the order of 30 million tonnes, identified resources are far larger, world mine production reached roughly 240,000 tonnes in 2024, up about eighteen percent on the prior year, and batteries account for the large majority of end use.⁸ Brine resources are a major share of the total and are distributed across countries including those of the lithium triangle, so technologies that unlock them efficiently carry strategic value, and interest has extended from classic salar brines to geothermal and oilfield brines that pair lithium recovery with existing fluid infrastructure.² The route families sit at different stages: adsorption is the most commercially proven, operating at scale in several regions; ion exchange is advancing with developers targeting lower-grade brines;³ and solvent extraction, membrane, and electrochemical routes are earlier, at pilot and demonstration scale, though recent work has shown electrochemical recovery from dilute and high-impurity brines.⁵,⁶ Because applications publish about eighteen months after filing, the most recent sorbent and electrochemical filings are under-represented (2025 and 2026 counts are partial), so the current frontier is more active than granted-patent counts suggest.
The strategic question is which route and layer to back, and the white space sits where selectivity, durability, and cost are hardest. Sorbent and membrane materials with high lithium selectivity, long cycle life, and low regeneration cost are the central materials problem, so composition and process innovation carry high, defensible value.²,³ The earlier routes, membrane and electrochemical, are less crowded and offer room for differentiated positions,⁵,⁶ and technologies that handle lower-grade and unconventional brines, that cut water and energy use, and that integrate recovery with conversion to battery-grade chemicals are all strategically important. Across the Cypris corpus, DLE families number on the order of 1,679 and step up sharply from 2023, with the most active assignees concentrated in China, led by battery-materials and salt-lake specialists alongside oilfield-services filers, and China well ahead of the United States and Canada on geography; these are Cypris-corpus figures, with 2025 and 2026 partial. Reading the landscape by route, material, and step, and tracking both the patents and the underlying separations research, is what separates a crowded region from an open one.
Where the DLE white space is
High-selectivity, durable sorbents. Sorbent and ion-sieve materials with high lithium selectivity, long cycle life, and low-cost regeneration are the central materials problem and a high-value layer.²,³
Membrane and electrochemical routes. The earlier membrane and electrochemical route families are less crowded and offer room for differentiated positions.⁵,⁶
Lower-grade and unconventional brines. Technologies that recover lithium from geothermal and oilfield brines and from low-concentration resources broaden where DLE can be deployed.⁶
Water and energy reduction. Processes that cut the water and energy needed for extraction and regeneration are a differentiating capability under environmental scrutiny.
Integrated conversion to battery-grade chemicals. Recovering lithium and converting it directly to high-purity hydroxide or carbonate is where product value and economics are decided.
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans five route families and several supporting steps requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by route, material, and step across varied terminology, attribution that normalizes developer, resource-company, and academic filers to canonical entities, and continuous monitoring that keeps pace with a demand-driven surge. Because DLE advances appear in scientific and separations literature before they are patented, reading both patents and literature gives the earliest signal of where viable, low-cost routes are emerging.
Where Cypris fits
Cypris runs patent landscape and white space analysis for multi-route materials fields such as direct lithium extraction across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by route family, adsorption, ion exchange, solvent extraction, membrane, and electrochemical, and by layer, sorbent and membrane materials, pretreatment, regeneration, and conversion, and normalizes developer, resource-company, and academic filers to canonical entities, so a team can resolve which routes and layers are crowded and which remain open as white space, and can track new entrants as the field scales. Semantic search across patents and scientific literature connects filings to the underlying separations and materials research, which is where DLE advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined route over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is direct lithium extraction? Direct lithium extraction is a set of technologies that recover lithium selectively from brine using engineered materials, rather than concentrating it in solar evaporation ponds over months to years. It is faster, has a smaller footprint, and can tap lower-grade and unconventional brines. It is central to scaling lithium supply for batteries.
What route families does the DLE landscape cover? The landscape covers five route families: adsorption, ion exchange, solvent extraction, membrane separation, and electrochemical methods. Each uses different materials and mechanisms and sits at a different maturity, with adsorption the most commercially proven. Freedom-to-operate and white space analysis must treat them separately.
Why is DLE strategically important? DLE is strategically important because brine resources hold a large share of global lithium and unlocking them efficiently expands supply for batteries, which account for the large majority of lithium end use. DLE also enables recovery from geothermal and oilfield brines that pair with existing infrastructure. That makes the enabling materials and processes valuable.
Where is the white space in DLE? The white space includes high-selectivity, durable sorbents, the earlier membrane and electrochemical routes, lower-grade and unconventional brines, water and energy reduction, and integrated conversion to battery-grade chemicals. Adsorption is comparatively crowded and proven. The most open, high-value opportunities are in advanced materials and the earlier routes.
Why are sorbent materials the key layer? Sorbent materials are the key layer because the selectivity, cycle life, and regeneration cost of the sorbent largely determine whether a DLE process is efficient and economical. Improving these properties is the central materials problem across adsorption and ion-exchange routes. The composition and process methods that achieve it are foundational and defensible.
Why does DLE analysis need scientific literature? DLE analysis needs scientific literature because sorbent, membrane, and separations advances appear in research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the direct lithium extraction patent landscape? Software for the DLE landscape should cluster activity by route family and process layer, resolve developer, resource-company, and academic filers to canonical owners, search patents and scientific literature semantically, and monitor a demand-driven field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use DLE patent landscape analysis? DLE patent landscape analysis is used by R&D, innovation, IP, and strategy teams at lithium producers, materials and chemicals companies, energy and resource firms, and their partners, as well as investors and policymakers. It informs which route to back, where to file, and where competitors are concentrated. Cypris serves hundreds of enterprise customers across advanced materials, chemicals, energy, and other regulated industries.
Endnotes
- Stringfellow, W. T., & Dobson, P. F. (2021). Technology for the recovery of lithium from geothermal brines. Energies, 14(20), 6805. https://doi.org/10.3390/en14206805
- Kolb, T., et al. (2022). Lithium extraction techniques and the application potential of different sorbents for lithium recovery from brines. Mineral Processing and Extractive Metallurgy Review. https://doi.org/10.1080/08827508.2022.2047041
- Chen, L., et al. (2024). Advanced lithium ion-sieves for sustainable lithium recovery from brines. Sustainability Horizons. https://doi.org/10.1016/j.horiz.2024.100093
- Razmjou, A., et al. (2024). Lithium recovery from brines. Nature Sustainability, 7. https://doi.org/10.1038/s41893-024-01451-2
- Leones, R. (2024). Membraneless electrochemical extraction of lithium from brines. Nature Chemical Engineering, 1. https://doi.org/10.1038/s44286-024-00155-w
- Zhou, X., et al. (2024). Lithium extraction from low-quality brines. Nature, 634. https://doi.org/10.1038/s41586-024-08117-1
- Hu, J., et al. (2019). Recovery of lithium from salt-lake brines using solvent extraction with TBP and FeCl3. Hydrometallurgy, 189. https://doi.org/10.1016/j.hydromet.2019.105244
- U.S. Geological Survey (2025). Lithium. In Mineral Commodity Summaries 2025. https://doi.org/10.3133/mcs2025
Perception is the part of an autonomous vehicle that turns raw sensor data into an understanding of the road, and its patent landscape is distinctive because value is distributed across a deep stack of sensing, calibration, fusion, and learning technologies. An autonomous vehicle carries an array of sensors, lidar, radar, cameras, and ultrasonics, and perception is the layer that combines them into a coherent, real-time model of the surroundings: detecting and classifying vehicles, pedestrians, and obstacles, tracking their motion, and locating the vehicle on a map. Large-scale multi-sensor benchmarks such as the Waymo Open Dataset have become the reference standard for training and evaluating this layer<sup>1</sup>. The intellectual property divides across several regions, each a distinct area of patenting: the sensors themselves, including lidar hardware; the calibration that aligns the sensors' coordinate frames, without which fusion outputs are biased; the sensor-fusion algorithms that combine the streams at different stages, whether early, feature-level, or late fusion<sup>3,4</sup>; the perception models that perform detection, tracking, and segmentation — an approach with roots in foundational architectures such as MV3D, which fused LiDAR and RGB views for 3D object detection<sup>7</sup>; the mapping and localization systems, including high-definition maps; and, increasingly, the end-to-end learning models that fold several of these steps into a single trained system. Because a working stack depends on several of these layers, freedom-to-operate and white space analysis must span them together.
The landscape is deep, concentrated among leaders, and geographically broad. A small number of established developers hold very large portfolios covering their full self-driving stacks, from sensing and mapping to on-vehicle compute; in Cypris's corpus, China and the United States are roughly neck-and-neck as the two largest filing jurisdictions, with automakers, technology companies, autonomous-driving startups, and universities all active, followed by strong filing in other major markets as foreign developers protect their positions there (see the landscape figures below). A defining technical debate now runs through the landscape: conventional modular pipelines, which separate perception, prediction, and planning into interpretable stages, versus end-to-end learning systems, which train a single model from sensor input to driving action and handle rare situations more flexibly but are harder to interpret and certify. Each approach generates its own IP. Because applications publish about eighteen months after filing, the most recent fusion and end-to-end-model filings are under-represented, so the current frontier is more active than granted-patent counts suggest.
The strategic question is which layer to own, and the white space sits where reliability is hardest. Sensor fusion that stays robust when sensors disagree or degrade, and calibration that holds during operation, are foundational and heavily worked but still advancing — the case for fusion in the first place rests on the fact that no single sensor modality is reliable across all conditions<sup>5</sup>, and combining complementary modalities such as 4D radar and LiDAR is one active response<sup>6</sup>. End-to-end learning models are the fastest-moving frontier, where much of the newest activity concentrates. Perception in adverse conditions, approaches that reduce dependence on high-definition maps, collaborative and vehicle-to-everything perception, and the simulation and validation methods needed to certify safety are all distinct, contested layers. Reading the landscape by layer and by owner, and tracking both the patents and the underlying computer-vision and machine-learning research, is what separates a crowded region from an open one.
Where the autonomous perception white space is
Robust sensor fusion. Fusion that stays accurate when sensors disagree, degrade, or are attacked is a foundational layer where reliability gains carry high value, spanning early, feature-level, and late fusion architectures<sup>3,4</sup>.
End-to-end learning models. Models that map sensor input to driving action in a single trained system are the fastest-moving frontier and the most active recent layer.
Adverse-condition and map-light perception. Perception in rain, fog, and low light, and approaches that reduce dependence on high-definition maps, are distinct, high-value layers, building on the case for multi-modal complementarity established in the fusion literature<sup>5,6</sup>.
Collaborative and vehicle-to-everything perception. Sharing perception between vehicles and infrastructure to see beyond line of sight is an emerging, less-crowded area.
Simulation and validation. Methods to test and certify perception safety, including for rare long-tail scenarios, are where deployment and regulatory approval are decided, and large real-world benchmarks such as the Waymo Open Dataset support this work<sup>1</sup>.
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans sensing, calibration, fusion, perception models, mapping, and end-to-end learning requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by layer and approach across varied terminology, attribution that normalizes automaker, technology-company, startup, and university filers to canonical entities across jurisdictions, and continuous monitoring that keeps pace with a fast-moving field. Because perception advances appear in computer-vision and machine-learning literature before they are patented, reading both patents and literature gives the earliest signal of where the frontier and the white space are moving.
The competitive landscape by the numbers
Cypris's corpus puts the autonomous-driving-perception patent family set at roughly 36,227 families (Cypris corpus, indicative; 2025–26 partial). Filing has accelerated from 285 new families in 2015 to 1,249 in 2018 and 4,354 in 2024, with 2025 (6,749) and 2026 (6,012, partial) continuing that climb (Cypris corpus, indicative; 2025–26 partial). Jurisdiction distribution shows China (11,593 families, 612 assignees) and the United States (10,837 families, 354 assignees) essentially neck-and-neck at the top, followed by Germany (2,331), South Korea (953), Japan (722), Sweden (431), and Israel (267) (Cypris corpus, indicative; 2025–26 partial). Assignee concentration is led by Waymo (1,101 families), Aurora (1,000), Bosch (787), General Motors (685), Ford (637), Baidu (604), Nvidia (570), GM Cruise (470), and Zoox (444) (Cypris corpus, indicative; 2025–26 partial) — figures drawn from the Cypris corpus rather than any company's own disclosed portfolio size, since issuer-reported totals were not independently available for this set. These per-company totals should be treated as lower bounds: assignee names are not fully canonicalized in the underlying index (for example, GM Global Technology Operations filings sit apart from GM Cruise, and Baidu USA filings sit apart from Baidu's Beijing entity), so known name variants should be summed before publishing a definitive ranking.
Where Cypris fits
Cypris runs patent landscape and white space analysis for fast-moving, cross-disciplinary fields such as autonomous driving perception across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by layer, sensing, calibration, fusion, perception models, mapping, and end-to-end learning, and normalizes automaker, technology-company, startup, and university filers to canonical entities across jurisdictions, so a team can resolve which layers are crowded and which remain open as white space. Semantic search across patents and scientific literature connects filings to the underlying computer-vision and machine-learning research, which is where perception advances appear first, often well ahead of the patent record. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined layer over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is autonomous driving perception? Autonomous driving perception is the layer that turns data from lidar, radar, cameras, and other sensors into a real-time model of the vehicle's surroundings, detecting and tracking objects and localizing the vehicle. It sits between raw sensing and the prediction and planning that decide how the vehicle moves. It is central to the safety and capability of a self-driving system.
What layers does the perception patent landscape cover? The landscape covers the sensors themselves, calibration, sensor fusion, perception models for detection and tracking, mapping and localization, and end-to-end learning models<sup>3,4,7</sup>. Each is a distinct region of patenting with different owners. Freedom-to-operate and white space analysis must span them together.
Who holds the IP in autonomous perception? A small number of established developers hold very large portfolios covering their full self-driving stacks. In Cypris's corpus, Waymo, Aurora, and Bosch lead the assignee ranking, and China and the United States are roughly neck-and-neck as the two largest filing jurisdictions, with automakers, technology companies, startups, and universities all active (Cypris corpus, indicative; 2025–26 partial). Foreign developers also file heavily in other major markets to protect their positions.
What is the modular-versus-end-to-end debate? The modular-versus-end-to-end debate is the architectural choice between separating perception, prediction, and planning into distinct, interpretable stages, and training a single model that maps sensor input directly to driving action. Modular systems are easier to interpret and certify; end-to-end systems handle rare situations more flexibly but are harder to interpret. Each approach generates its own IP.
Why is sensor fusion necessary in the first place? Sensor fusion is necessary because no single sensor modality — lidar, radar, or camera — is reliable across all conditions on its own, so combining complementary modalities, such as 4D radar with LiDAR, improves robustness where any one sensor would fail<sup>5,6</sup>. This is why fusion architecture, spanning early, feature-level, and late fusion, is a foundational and heavily worked layer<sup>3,4</sup>. It remains an active area even though it is comparatively mature.
Where is the white space in autonomous perception? The white space includes robust sensor fusion, end-to-end learning models, adverse-condition and map-light perception, collaborative and vehicle-to-everything perception, and simulation and validation. The core sensing and fusion layers are heavily worked. The fastest-moving and most open opportunities are in end-to-end learning and in reliability under difficult conditions.
Why does perception analysis need scientific literature? Perception analysis needs scientific literature because computer-vision and machine-learning advances appear in research and conference proceedings before they are patented, so the literature gives the earliest signal in a fast-moving field. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the autonomous driving perception patent landscape? Software for the perception landscape should cluster activity by layer and approach, resolve automaker, technology-company, startup, and university filers to canonical owners across jurisdictions, search patents and scientific literature semantically, and monitor a fast-moving field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use autonomous perception patent landscape analysis? Autonomous perception patent landscape analysis is used by R&D, IP, and strategy teams at automakers, autonomous-driving and sensor companies, and technology firms, as well as investors assessing the sector. Because the landscape is deep, concentrated, and moving fast, structured analysis is essential. Cypris serves hundreds of enterprise customers across research-intensive and regulated industries.
Endnotes
- Sun P, Kretzschmar H, Vasudevan V, et al. (Google/Waymo). Scalability in perception for autonomous driving: Waymo Open Dataset. CVPR. 2020. DOI: 10.1109/cvpr42600.2020.00252.
- Mao Q, Zhang Y, et al. Multi-modal 3D object detection in autonomous driving: a survey. International Journal of Computer Vision. 2023. DOI: 10.1007/s11263-023-01784-z.
- Bi J, Wang L, et al. Multi-modal 3D object detection in autonomous driving: a survey and taxonomy. IEEE Transactions on Intelligent Vehicles. 2023. DOI: 10.1109/tiv.2023.3264658.
- Chehri A, et al. Multi-sensor fusion technology for 3D object detection in autonomous driving: a review. IEEE Transactions on Intelligent Transportation Systems. 2023. DOI: 10.1109/tits.2023.3317372.
- Tang Y, et al. Multi-modality 3D object detection in autonomous driving: a review. Neurocomputing. 2023. DOI: 10.1016/j.neucom.2023.126587.
- Wang L, et al. Multi-modal and multi-scale fusion 3D object detection of 4D radar and LiDAR. IEEE Transactions on Vehicular Technology. 2022. DOI: 10.1109/tvt.2022.3230265.
- Chen X, Ma H, et al. Multi-view 3D object detection network for autonomous driving (MV3D). CVPR. 2017. DOI: 10.1109/cvpr.2017.691.
- Cypris platform corpus analysis, autonomous-driving-perception patent families. Indicative figures; 2025–2026 partial.
Enhanced geothermal systems have moved from research pilots to commercial deployment, and their patent landscape is being staked out as the field adapts oil-and-gas technology to a new purpose. Conventional geothermal power is limited to the few places where hot rock, natural permeability, and fluid coincide; enhanced geothermal systems remove that limitation by engineering a reservoir in hot dry rock, drilling injection and production wells, stimulating a network of fractures — through hydraulic, chemical, or thermal means — to create permeability, and circulating a working fluid to carry heat to the surface<sup>1</sup>. This promises round-the-clock, carbon-free baseload power in far more locations, and it is being built largely by transferring horizontal drilling, hydraulic fracturing, and downhole sensing from the shale industry, including multistage-fractured horizontal well pairs that improve heat extraction relative to single-fracture designs<sup>2</sup>. Field-scale designs illustrate the resource depths involved: a two-horizontal-well EGS project at the Zhacang field reached a bottom-hole temperature of 214°C at 4,700 meters<sup>3</sup>. The intellectual property divides across several regions, each a distinct area of patenting: open-loop reservoir stimulation, including well-pair architecture, horizontal wells, and fracture creation; closed-loop systems that circulate fluid through sealed wellbores without fracturing; advanced and non-mechanical drilling, including energy-based methods; downhole sensing and monitoring, such as distributed fiber-optic measurement; the working fluids themselves, from water to supercritical carbon dioxide; and integration with thermal energy storage for dispatchable output. Because a commercial project depends on several of these layers, freedom-to-operate and white space analysis must span the approaches and the enabling layers together.
The landscape has shifted decisively into a deployment era. A first-of-its-kind, roughly 500-megawatt commercial EGS project — Fervo Energy's Cape Station in Utah — is under construction, and the U.S. Department of Energy's and NREL's 2025 U.S. Geothermal Market Report documents materially improved drilling rates across Utah FORGE and Fervo's own drilling campaigns as shale techniques have been imported into geothermal<sup>7</sup>. The build is a phased, multi-year process rather than a single completed plant: a utility power-purchase agreement tied to one phase of Cape Station was amended in January 2025, with an expected commercial operation date of January 1, 2031, according to the California Public Utilities Commission record<sup>9</sup>, and financing and offtake structure are disclosed in Fervo's own SEC registration and periodic filings<sup>8</sup>. The competitive picture spans dedicated developers pursuing open-loop, horizontal well-pair designs; closed-loop specialists; the major oilfield-services companies bringing drilling, measurement, and sensing IP; and a set of drilling startups pursuing non-mechanical methods such as millimeter-wave, plasma, and laser rock removal to reach deeper, hotter resources. Because applications publish about eighteen months after filing, the most recent drilling, stimulation, and sensing filings are under-represented, so the current frontier is more active than granted-patent counts suggest.
The strategic question is which enabling layer to own, and the white space sits where cost and depth are the barriers. Drilling is the single largest cost in an EGS project — a cost-methodology lineage that traces back to early national-laboratory work on hot-dry-rock electricity economics<sup>6</sup> — so advanced and non-mechanical drilling methods that cut time and reach deeper, hotter rock are a high-value, fast-moving layer. Closed-loop architectures that avoid fracturing, working fluids such as supercritical carbon dioxide, superhot-rock and superdeep resources, downhole sensing that improves reservoir control, induced-seismicity mitigation — a risk that fracture-network modeling work is increasingly used to manage<sup>4</sup> — and integration with thermal storage for dispatchable power are all distinct, contested areas. Reading the landscape by approach, enabling layer, and owner, and tracking both the patents and the underlying geoscience and drilling research, is what separates a crowded region from an open one.
Where the enhanced geothermal white space is
Advanced and non-mechanical drilling. Energy-based drilling methods that cut drilling time and reach deeper, hotter rock address the single largest cost in an EGS project<sup>6,7</sup>.
Closed-loop architectures. Sealed-wellbore designs that circulate fluid without fracturing are a distinct approach that avoids some reservoir and seismicity risks.
Working fluids and superhot rock. Supercritical carbon dioxide and other working fluids, and access to superhot and superdeep resources, are high-value, less-crowded layers.
Downhole sensing and reservoir control. Distributed fiber-optic sensing and real-time reservoir characterization improve performance and reduce risk, including around induced seismicity<sup>4</sup>.
Seismicity mitigation and thermal-storage integration. Induced-seismicity management and integration with thermal energy storage for dispatchable output are distinct, strategically important layers.
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans stimulation, drilling, sensing, and integration, built by transferring technology from oil and gas, requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by approach and enabling layer across varied terminology, attribution that normalizes developer, oilfield-services, and startup filers to canonical entities, and continuous monitoring that keeps pace with a fast-deploying field. Because geothermal advances appear in scientific and engineering literature before they are patented, reading both patents and literature gives the earliest signal of where cost and depth barriers are falling.
The competitive landscape by the numbers
Cypris's corpus puts the enhanced geothermal / hot-dry-rock / reservoir-stimulation patent family set at roughly 1,157 families (Cypris corpus, indicative; 2025–26 partial). Filing rose from single digits per year before 2010 to a plateau of roughly 68–142 new families per year between 2017 and 2024, peaking around 142 in 2022, with 2025 (86) and 2026 (59, partial) continuing (Cypris corpus, indicative; 2025–26 partial). China (781 families) and the United States (171) dominate, with Canada (25) and smaller tails in Europe and Australia (Cypris corpus, indicative; 2025–26 partial). The assignee ranking reflects the oil-and-gas technology-transfer story described above: Sinopec (40 families) and its Sinopec Petroleum Engineering unit (21) lead, alongside China University of Mining and Technology-Beijing (23), the University of Minnesota (15), Halliburton (12), Johns Hopkins University (11), and UT-Battelle/Oak Ridge National Laboratory (6) (Cypris corpus, indicative; 2025–26 partial) — a mix of oilfield-services majors, universities, and national labs that mirrors the field's drilling and stimulation lineage.
Where Cypris fits
Cypris runs patent landscape and white space analysis for fast-deploying energy fields such as enhanced geothermal systems across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by approach, open-loop stimulation, closed-loop, and advanced drilling, and by enabling layer, drilling, sensing, working fluids, and integration, and normalizes developer, oilfield-services, and startup filers to canonical entities, so a team can resolve which approaches and layers are crowded and which remain open as white space. Semantic search across patents and scientific literature connects filings to the underlying geoscience and drilling research, which is where EGS advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined layer over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What are enhanced geothermal systems? Enhanced geothermal systems create geothermal reservoirs where natural permeability is insufficient, by drilling well pairs into hot dry rock, stimulating a fracture network, and circulating a working fluid to carry heat to the surface<sup>1</sup>. This makes round-the-clock, carbon-free geothermal power possible in far more locations. The technology adapts drilling and stimulation from the oil-and-gas sector<sup>2</sup>.
Why is EGS a patenting hotspot now? EGS is a patenting hotspot now because the field has moved from pilots to commercial-scale projects such as Fervo Energy's Cape Station, developers have documented improved drilling times by importing shale techniques<sup>7</sup>, and technology firms have signed power deals for data centers backed by disclosed financing and offtake structures<sup>8,9</sup>. That deployment shift is driving filings across drilling, stimulation, and sensing.
What layers does the EGS landscape cover? The landscape covers open-loop reservoir stimulation, closed-loop well architectures, advanced and non-mechanical drilling, downhole sensing, working fluids, and thermal-storage integration. Each is a distinct region of patenting with different owners. Freedom-to-operate and white space analysis must span them together.
Where is the white space in enhanced geothermal systems? The white space includes advanced and non-mechanical drilling, closed-loop architectures, working fluids and superhot-rock access, downhole sensing and reservoir control, and seismicity mitigation and thermal-storage integration. Drilling is the largest cost, so drilling innovation is especially high-value. The most open opportunities are in cutting cost and reaching deeper, hotter rock.
Why is drilling the key cost in EGS? Drilling is the key cost because reaching hot rock deep underground and creating well pairs is capital-intensive, tracing back to cost-methodology work first developed for hot-dry-rock electricity at the national-laboratory level<sup>6</sup>, so reducing drilling time and reaching deeper, hotter resources directly determines project economics<sup>7</sup>. That is why advanced and non-mechanical drilling methods are such an active, high-value layer.
Is Cape Station a completed 500-megawatt plant today? Not yet — Cape Station is best described as a first-of-its-kind, roughly 500-megawatt commercial EGS project that is being built in phases<sup>7</sup>. A utility power-purchase agreement tied to one phase carries an expected commercial operation date of January 1, 2031, per the California Public Utilities Commission record<sup>9</sup>, so current statements should describe it as under construction with forward delivery dates rather than as fully operational.
Why does EGS analysis need scientific literature? EGS analysis needs scientific literature because drilling, stimulation, and sensing advances appear in geoscience and engineering research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the enhanced geothermal patent landscape? Software for the EGS landscape should cluster activity by approach and enabling layer, resolve developer, oilfield-services, and startup filers to canonical owners, search patents and scientific literature semantically, and monitor a fast-deploying field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use enhanced geothermal patent landscape analysis? Enhanced geothermal patent landscape analysis is used by R&D, IP, and strategy teams at geothermal developers, oilfield-services and drilling companies, utilities, and technology buyers, as well as investors assessing the sector. Because the field is deploying fast and spans several enabling layers, structured analysis is essential. Cypris serves hundreds of enterprise customers across energy and other research-intensive industries.
Endnotes
- Niemi A, Tsang C-F, et al. Hydraulic stimulation strategies in enhanced geothermal systems (EGS): a review. Geomechanics and Geophysics for Geo-Energy and Geo-Resources. 2022. DOI: 10.1007/s40948-022-00516-w.
- Qu Z, et al. Evaluation of geothermal energy extraction in EGS with multiple fracturing horizontal wells. Renewable Energy. 2019. DOI: 10.1016/j.renene.2019.11.134.
- Lei Z, et al. Reservoir stimulation design and heat exploitation of a two-horizontal-well EGS, Zhacang field. Renewable Energy. 2021. DOI: 10.1016/j.renene.2021.10.101.
- Xu T, et al. Discrete element modeling for multistage hydraulic stimulation of a horizontal well in hot dry rock. Computers and Geotechnics. 2023. DOI: 10.1016/j.compgeo.2023.105274.
- Wang G, et al. Heat extraction mechanism in hot dry rock based on horizontal wells with multi-stage fracturing. Energy. 2026. DOI: 10.1016/j.energy.2026.140217.
- Pierce K, Livesay BJ (Sandia National Laboratories). An estimate of the cost of electricity production from hot-dry rock. 1993. DOE/OSTI.
- U.S. Department of Energy / National Renewable Energy Laboratory. U.S. Geothermal Market Report. 2025.
- Fervo Energy. SEC registration and periodic filings — Form S-1; Form 424(b)(4); Form 10-Q for the period ended June 30, 2026. sec.gov.
- California Public Utilities Commission. Power-purchase agreement filing tied to Cape Station, amended January 9, 2025. docs.cpuc.ca.gov.
- Cypris platform corpus analysis, enhanced geothermal / hot-dry-rock / reservoir-stimulation patent families. Indicative figures; 2025–2026 partial.
Green steel has become one of the most closely watched areas of industrial decarbonization, and its patent landscape is distinctive because low-carbon steelmaking is not a single technology but a set of competing routes, each with its own chemistry and process engineering. Conventional steelmaking reduces iron ore with coal-derived coke in a blast furnace, and ironmaking generates roughly 7 percent of global CO2 emissions across an industry producing about 1.85 billion tonnes of steel a year<sup>2</sup>. The leading low-carbon routes replace that chemistry in different ways, and each is a distinct region of patenting: hydrogen-based direct reduction uses green hydrogen instead of coke to turn iron ore into sponge iron, which is then melted in an electric arc furnace<sup>3</sup>; molten oxide electrolysis passes electricity through molten iron ore, producing liquid metal and oxygen at the anode with no process CO2 given a clean electricity input<sup>4</sup>; and low-temperature electrochemical routes produce iron from ore or low-grade feedstocks by electrowinning, though the aqueous chemistry still faces a hydrogen-evolution-reaction efficiency bottleneck that limits faradaic efficiency<sup>7</sup>. Because each route relies on different core steps, anode and electrolyte materials, hydrogen integration, ore handling, and furnace design, freedom-to-operate and white space analysis must treat green steel as several landscapes at once.
The field is moving from pilots to first industrial-scale plants. A hydrogen direct-reduction plant designed for a developer-reported emissions reduction of up to roughly 95 percent versus blast-furnace production — a figure consistent with, though not itself drawn from, peer-reviewed techno-economic modeling of the H2-DRI/EAF route<sup>1</sup> — is being built at industrial scale and is on track to begin production, and electrolysis-based developers are scaling reactors toward commercial output. The intellectual property reflects the maturity gap between the routes: hydrogen direct reduction builds on established direct-reduced-iron practice and concentrates IP in hydrogen integration, reduction control, and furnace operation, with break-even hydrogen pricing as a central techno-economic question in the peer-reviewed literature<sup>1</sup>, while the electrolysis routes concentrate foundational IP in the inert-anode and electrolyte materials and cell designs that make emission-free iron production work<sup>4,5</sup>, much of it traceable to a small number of academic and company lineages. Because applications publish about eighteen months after filing, the most recent electrolysis and process filings are under-represented, so the current frontier is more active than granted-patent counts suggest.
The strategic question is which route and layer to back, and the white space sits where cost, materials, and feedstock constraints are hardest. In hydrogen direct reduction, the open ground is in reducing hydrogen consumption and cost, tolerating lower-grade ore, and integrating variable hydrogen supply<sup>1</sup>. In molten oxide electrolysis, durable inert-anode materials that survive the process are the central, high-value problem<sup>4</sup>. In low-temperature electrowinning, the opportunity is in efficient electrochemistry and the use of low-grade ores and mining waste, with comparative techno-economic analysis showing how the three electrolysis-adjacent routes trade off against hydrogen reduction<sup>6,7</sup>. Across all routes, ore flexibility is strategically important because some routes require scarce high-grade ore. Reading the landscape by route, core step, and owner, and tracking both the patents and the underlying process research, is what separates a crowded region from an open one.
Where the green-steel white space is
Inert-anode and electrolyte materials. Durable anode and electrolyte materials that survive molten oxide electrolysis are the central, high-value problem for the electrolysis route<sup>4,5</sup>.
Low-grade ore tolerance. Processes that use lower-grade ore or mining waste ease the feedstock constraint that limits some routes and broaden where plants can be sited.
Hydrogen integration and reduction control. Reducing hydrogen consumption and cost and integrating variable green-hydrogen supply in direct reduction is a large, active layer, with break-even hydrogen price as the key economic lever<sup>1</sup>.
Low-temperature electrochemical iron production. Efficient aqueous-phase electrowinning of iron is an earlier, less-crowded route with distinct chemistry, currently constrained by hydrogen-evolution-reaction efficiency losses<sup>7</sup>.
Furnace and process integration. Integrating direct-reduced iron with electric arc furnaces and optimizing continuous operation is where cost and quality are decided<sup>3</sup>.
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans several production routes, each with its own chemistry and process, requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by route, core step, and material across varied terminology, attribution that normalizes filers to canonical entities and tracks new entrants, and continuous monitoring that keeps pace with a fast-commercializing field. Because green-steel advances appear in scientific and process-engineering literature before they are patented, reading both patents and literature gives the earliest signal of where scalable routes are emerging.
The competitive landscape by the numbers
Cypris's corpus puts the low-carbon steelmaking patent family set — spanning hydrogen-DRI, electrolysis/molten oxide electrolysis, electrowinning, and general "green steel" filings — at roughly 27,049 families (Cypris corpus, indicative; 2025–26 partial). Filing has run at roughly 900–1,900 new families per year across 2016–2024, with 2025 (2,210) and 2026 (1,750, partial) continuing the trend (Cypris corpus, indicative; 2025–26 partial). The assignee ranking spans both steel majors and petrochemical/catalysis houses: Sinopec (431 families), Nippon Steel (229), ArcelorMittal (215), JFE (98), and Northeastern University (111) lead the count (Cypris corpus, indicative; 2025–26 partial) — worth flagging, since several of the top filers are catalysis and process-engineering companies rather than primary steelmakers, so the set is broader than steel production alone. Geographically, China dominates with 14,065 families, followed by the United States (1,233), Germany (636), Japan (329), Luxembourg (271, reflecting ArcelorMittal's filings), and Sweden (151) (Cypris corpus, indicative; 2025–26 partial).
Where Cypris fits
Cypris runs patent landscape and white space analysis for multi-route industrial fields such as green steel across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by route, hydrogen direct reduction, molten oxide electrolysis, and electrowinning, and by layer, anode and electrolyte, hydrogen integration, ore handling, and furnace design, and normalizes filers to canonical entities, so a team can resolve which routes and layers are crowded and which remain open as white space, and can track new entrants as the field scales. Semantic search across patents and scientific literature connects filings to the underlying process and materials research, which is where green-steel advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined route over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is the green steel patent landscape? The green steel patent landscape is the set of patents covering low-carbon steelmaking. It divides across competing routes, hydrogen-based direct reduction feeding an electric arc furnace, molten oxide electrolysis, and low-temperature electrowinning, each with distinct chemistry and process IP<sup>1,4,7</sup>. Each route is a distinct region of patenting.
Why is steelmaking a decarbonization priority? Steelmaking is a decarbonization priority because ironmaking generates roughly 7 percent of global CO2 emissions across an industry producing about 1.85 billion tonnes of steel a year<sup>2</sup>. Low-carbon routes replace coke-based reduction with hydrogen or electricity. The first industrial-scale plants are now being built.
What routes does the green-steel landscape cover? The landscape covers hydrogen-based direct reduced iron, which uses green hydrogen instead of coke<sup>3</sup>; molten oxide electrolysis, which splits molten iron ore with electricity to yield liquid metal and oxygen<sup>4</sup>; and low-temperature electrochemical iron production by electrowinning<sup>6,7</sup>. Each relies on different core steps and materials. Freedom-to-operate and white space analysis must treat them separately.
Where is the white space in green steel? The white space includes inert-anode and electrolyte materials for electrolysis, low-grade ore tolerance, hydrogen integration and reduction control, low-temperature electrochemical iron production, and furnace and process integration. The routes sit at different maturity levels. The most open, high-value opportunities are in the electrolysis materials and in ore and hydrogen flexibility.
Why are inert-anode materials so important? Inert-anode materials are important because molten oxide electrolysis depends on an anode that can survive extreme temperatures and produce oxygen rather than carbon dioxide, and finding durable, affordable anode and electrolyte materials is the central technical problem for that route<sup>4,5</sup>. Solving it is what makes emission-free electrolytic iron viable. Much of the route's defensible IP concentrates there.
Is molten oxide electrolysis actually "zero-carbon"? Molten oxide electrolysis is more precisely described as producing oxygen and liquid metal with no process CO2, provided the electricity input is clean — the process itself does not emit carbon during reduction, but the claim depends on the power source<sup>4</sup>. Unqualified "zero-carbon" framing overstates this without specifying the electricity mix. That distinction matters for both technical and disclosure purposes.
Who is filing green-steel patents, and where? In Cypris's corpus of roughly 27,049 low-carbon steelmaking patent families, China dominates filing activity, followed by the United States, Germany, Japan, and Luxembourg, and the assignee ranking includes both steel majors (Nippon Steel, ArcelorMittal, JFE) and petrochemical/catalysis filers (Sinopec) (Cypris corpus, indicative; 2025–26 partial).
Why does green-steel analysis need scientific literature? Green-steel analysis needs scientific literature because reduction, electrolysis, and materials advances appear in process research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the green steel patent landscape? Software for the green-steel landscape should cluster activity by route and process layer, resolve filers to canonical owners, search patents and scientific literature semantically, and monitor a fast-commercializing field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use green steel patent landscape analysis? Green steel patent landscape analysis is used by R&D, innovation, IP, and strategy teams at steelmakers, mining and materials companies, electrolysis and hydrogen developers, and their partners, as well as investors and policymakers. It informs which route to back, where to file, and where competitors are concentrated. Cypris serves hundreds of enterprise customers across advanced materials, energy, chemicals, and other regulated industries.
Endnotes
- Papadias DD, Brooks K, Yoro KO, Autrey T, et al. (Argonne National Laboratory, Lawrence Berkeley National Laboratory, Pacific Northwest National Laboratory; DOE-funded). Green steel: design and cost analysis of hydrogen-based direct iron reduction. Energy & Environmental Science. 2023. DOI: 10.1039/d3ee01077e.
- Bae JW, Raabe D, et al. Reducing iron oxide with ammonia: a sustainable path to green steel. Advanced Science. 2023. DOI: 10.1002/advs.202300111.
- Boretti A. The perspective of hydrogen direct reduction of iron. Journal of Cleaner Production. 2023. DOI: 10.1016/j.jclepro.2023.139585.
- Paramore JD, Kim H, Allanore A, Sadoway DR (MIT). Stability of iridium anode in molten oxide electrolysis for ironmaking. ECS Transactions. 2010. DOI: 10.1149/1.3484779.
- Azimi G, Allanore A, Judge WD, Sadoway DR. E-logpO2 diagrams for ironmaking by molten oxide electrolysis. Electrochimica Acta. 2017. DOI: 10.1016/j.electacta.2017.07.059.
- Rhamdhani MA, et al. (CSIRO, Swinburne University). Economics of electrowinning iron from ore for green steel production. Journal of Sustainable Metallurgy. 2024. DOI: 10.1007/s40831-024-00878-3.
- Viswanathan V, Kavalsky L. Electrowinning for room-temperature ironmaking: mapping the electrochemical aqueous iron interface. Journal of Physical Chemistry C. 2024. DOI: 10.1021/acs.jpcc.4c01867.
- Cypris platform corpus analysis, low-carbon steelmaking patent families. Indicative figures; 2025–2026 partial.
Targeted protein degradation has become one of the most closely watched modalities in drug discovery, and its patent landscape is distinctive because a degrader is a modular molecule whose parts are patented separately. Rather than blocking a protein's active site the way a conventional inhibitor does, a degrader recruits the cell's ubiquitin-proteasome system to destroy the target protein outright, which makes it possible to address targets that lack a druggable pocket.¹ The two most advanced approaches are proteolysis-targeting chimeras, or PROTACs, which are heterobifunctional molecules built from a ligand that binds the target protein, a linker, and a ligand that binds an E3 ubiquitin ligase, and molecular glues, which are smaller, single-piece molecules that induce proximity between the target and an E3 ligase by reprogramming the ligase's surface to recruit a neosubstrate.²,³ A growing set of related modalities, including lysosome-targeting and autophagy-targeting chimeras and degrader-antibody conjugates, extends the field further, and the chemical space of molecular glues in particular is only beginning to be mapped.⁴ Because the E3-ligase binder, the target ligand, the linker, and the whole composite molecule can each be claimed independently and are often held by different owners, freedom-to-operate for a degrader is a multi-layer, multi-owner analysis rather than a single clearance.
The field has moved from concept to the market, which has raised the stakes across every layer. In May 2026 vepdegestrant (VEPPANU), an oral PROTAC estrogen-receptor degrader developed by Arvinas and Pfizer, received US Food and Drug Administration approval, becoming the first approved PROTAC therapy, and the partners had earlier moved to out-license its commercialization.⁸,⁹ A steady stream of degrader deals has followed, including a second Monte Rosa–Novartis molecular-glue collaboration announced in September 2025 with a $120 million upfront payment and total potential value up to $5.7 billion.¹⁰ Foundational intellectual property traces to the academic origins of the PROTAC concept and to the E3-ligase-binder chemistries: the large majority of clinical-stage degraders recruit the cereblon ligase, with von Hippel-Lindau the other principal handle, even as the field works to expand to the other canonical E3 ligases and beyond.³,⁵ Patent activity around the von Hippel-Lindau layer alone is now substantial enough to sustain dedicated patent reviews.⁷ This concentration is visible in the record: across the Cypris corpus of more than 500 million patents and scientific papers, the degrader set holds on the order of 4,292 families and grew from roughly 134 in 2020 to about 814 in 2024, with the most active assignees including Dana-Farber, C4 Therapeutics, and Arvinas, and China (about 1,492 families) modestly ahead of the United States (about 1,205); 2025 and 2026 counts are partial because of the publication lag.
The strategic picture turns on where defensible, hard-to-design-around IP sits. The human genome encodes more than six hundred E3 ligases, but only a handful have been harnessed for degradation, so novel E3-ligase binders are a high-value, comparatively open layer, and the molecular-glue field, where rational design is still early, is another.¹,⁶ Because a degrader assembled from a known target ligand and a known E3 binder may face freedom-to-operate exposure on either component plus the linker, the durable value increasingly lies in new E3 chemistries, glue scaffolds, tissue- or ligase-selective designs, orally bioavailable degraders, and expansion beyond oncology into immunology and neuroscience.² Reading the landscape by layer and by owner, and tracking both the patents and the underlying chemistry and cell-biology research, is what separates a workable position from a blocked one.
What creates FTO risk in targeted protein degradation
E3-ligase-binder claims. These cover the chemistries that recruit an E3 ligase, such as cereblon and von Hippel-Lindau binders and newer ligases, a foundational and heavily contested layer.³,⁷
Target-ligand claims. These cover the warhead that binds the protein of interest, which can carry its own separate IP from inhibitor programs.
Linker claims. These cover the chemistry connecting the two ligands in a PROTAC, a distinct layer that materially affects degradation and is independently patentable.
Composite-molecule and molecular-glue claims. These cover the specific bifunctional degrader or single-piece glue, the layer most directly tied to a clinical candidate.²
Mechanism, formulation, and modality claims. These cover degradation mechanisms, formulations, and emerging modalities such as lysosome-targeting chimeras and degrader-antibody conjugates.
How AI-powered landscape and FTO analysis helps
A modular, multi-owner, fast-moving landscape is beyond manual clearance. AI-powered analysis addresses this with semantic search that retrieves relevant E3-binder, target-ligand, linker, and composite-molecule claims regardless of terminology, attribution that resolves academic and commercial owners and the license chains to canonical entities, claim-level analysis that separates the layers, and continuous monitoring that tracks new filings and deals. Because degrader advances appear in scientific literature before they are patented, reading both patents and literature gives earlier warning of where the field is heading.
Where Cypris fits
Cypris runs patent landscape and freedom-to-operate analysis for modular, contested fields such as targeted protein degradation across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters the landscape by layer, E3-ligase binder, target ligand, linker, and composite molecule, and normalizes academic and commercial owners to canonical entities, so a team sees how rights are distributed across the many parties rather than a flat list. Semantic search across patents and scientific literature surfaces relevant claims regardless of terminology and connects filings to the underlying research, which is where new E3 chemistries and glue scaffolds emerge first. Cypris Q, the platform's agentic layer, lets teams run landscape and FTO analysis conversationally and chain the attribution, clustering, and claim-level analysis across layers, and Agentic Monitoring tracks the landscape over time and flags new filings and developments as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is targeted protein degradation? Targeted protein degradation is a modality that eliminates a disease-causing protein by recruiting the cell's ubiquitin-proteasome system, rather than inhibiting the protein's activity. The leading approaches are PROTACs, which are bifunctional molecules, and molecular glues, which are single-piece molecules. It can address targets that lack a druggable pocket.
Why is freedom-to-operate hard for degraders? Freedom-to-operate is hard for degraders because a PROTAC is built from an E3-ligase binder, a target ligand, and a linker, each independently patentable and often held by different owners, and the composite molecule is a further layer. Molecular glues add their own scaffold IP. FTO must therefore be assessed layer by layer across multiple estates.
What claim types create FTO risk in TPD? Five claim types create FTO risk? E3-ligase-binder claims, target-ligand claims, linker claims, composite-molecule and molecular-glue claims, and mechanism, formulation, and modality claims. Each covers a distinct layer and can be held by a different owner. The E3-binder and composite-molecule layers are especially decisive.
Has any PROTAC been approved? Yes. In May 2026, vepdegestrant, an oral PROTAC estrogen-receptor degrader developed by Arvinas and Pfizer, received US FDA approval, becoming the first approved PROTAC therapy. Its approval marks the transition of targeted protein degradation from clinical development toward the market. Many other degraders remain in trials.
Why are novel E3 ligases important? Novel E3 ligases are important because the genome encodes more than six hundred E3 ligases but only a few have been harnessed for degradation, so binders for new ligases open a high-value, comparatively uncrowded layer. They can enable tissue- or context-selective degradation and help design around crowded cereblon and von Hippel-Lindau chemistries. Much of the field's future white space lies here.
Where is the white space in targeted protein degradation? The white space includes novel E3-ligase binders, molecular-glue scaffolds and rational glue design, tissue- and ligase-selective degraders, orally bioavailable degraders, and expansion beyond oncology into immunology and neuroscience. The cereblon and von Hippel-Lindau chemistries are comparatively crowded. The durable, defensible value is in new E3 chemistries and glues.
Why does TPD analysis need scientific literature? TPD analysis needs scientific literature because new E3 binders, glue scaffolds, and degradation mechanisms appear in research before they are patented, so the literature gives the earliest signal. Analyzing patents alone gives a lagging view. Cypris analyzes both across more than 500 million patents and scientific papers.
What software helps analyze the targeted protein degradation patent landscape? Software for the TPD landscape should resolve academic and commercial owners and license chains to canonical entities, cluster the E3-binder, target-ligand, linker, and composite-molecule layers, search patents and scientific literature semantically, and monitor deals and new filings continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Endnotes
- Cowan, A. D., & Ciulli, A. (2022). Driving E3 ligase substrate specificity for targeted protein degradation: lessons from nature and the laboratory. Annual Review of Biochemistry, 91. https://doi.org/10.1146/annurev-biochem-032620-104421
- Fasching, B., Gaínza, P., Oleinikovas, V., Thomä, N. H., et al. (2023). From thalidomide to rational molecular glue design for targeted protein degradation. Annual Review of Pharmacology and Toxicology, 63. https://doi.org/10.1146/annurev-pharmtox-022123-104147
- Ishida, T., & Ciulli, A. (2020). E3 ligase ligands for PROTACs: how they were found and how to discover new ones. SLAS Discovery, 26(4). https://doi.org/10.1177/2472555220965528
- Poongavanam, V., et al. (2024). Molecular glue chemical space and design. Drug Discovery Today. https://doi.org/10.1016/j.drudis.2024.104205
- Zhang, X., et al. (2025). The expanding E3 ligase-ligand landscape for PROTAC technology. Targets, 3(4). https://doi.org/10.3390/targets3040030
- Belcher, B. P., Ward, C. C., & Nomura, D. K. (2021). Ligandability of E3 ligases for targeted protein degradation applications. Biochemistry, 62(3). https://doi.org/10.1021/acs.biochem.1c00464
- Urbina, F., Robertson, N., Hallatt, A. J., & Ciulli, A. (2025). A patent review of von Hippel-Lindau (VHL)-recruiting chemical matter (2019–present). Expert Opinion on Therapeutic Patents, 35(3). https://doi.org/10.1080/13543776.2024.2446232
- Arvinas, Inc. (2026, May 1). Arvinas announces FDA approval of VEPPANU (vepdegestrant) for the treatment of ESR1m, ER+/HER2- advanced breast cancer. https://ir.arvinas.com/news-releases/news-release-details/arvinas-announces-fda-approval-veppanu-vepdegestrant-treatment
- Arvinas, Inc. (2025, September 17). Arvinas provides update on collaboration with Pfizer and announces further actions to support value creation. https://ir.arvinas.com/news-releases/news-release-details/arvinas-provides-update-collaboration-pfizer-and-announces
- Monte Rosa Therapeutics, Inc. (2025, September 15). Monte Rosa Therapeutics announces collaboration with Novartis for degraders to treat immune-mediated diseases. https://ir.monterosatx.com/news-releases/news-release-details/monte-rosa-therapeutics-announces-collaboration-novartis

Semantic search for patents retrieves documents by modeled meaning rather than by lexical overlap. A Boolean or keyword query matches on the surface form of a string: it returns patents whose text contains the specified tokens, combined through operators and often expanded with truncation, proximity, and classification filters. A semantic query matches on representation: each document and the query are encoded as high-dimensional vectors, and retrieval ranks documents by vector similarity, so patents whose claims and disclosures are conceptually related are returned even when they share no keywords with the query. This distinction is decisive in patent work because equivalent subject matter is routinely described in divergent vocabulary, and applicants draft claims with deliberately broad, idiosyncratic, or coined terminology to widen scope. When relevant patents use language the searcher did not anticipate, lexical retrieval fails to surface them, and those recall failures are the primary source of risk in prior art and freedom-to-operate analysis.
The stakes are set by scale. The World Intellectual Property Organization reported roughly 3.5 million patent applications filed worldwide in 2023,¹ and scientific literature has grown at approximately 8 to 9 percent per year across recent decades,² so the candidate space a searcher must cover exceeds what manually constructed Boolean queries can reliably span. Lexical retrieval trades recall for precision: it returns documents matching the exact terms and omits everything phrased differently. Evaluations in the patent-retrieval literature have found that keyword and Boolean logic disregard the syntax and semantics of technical language, which makes patent retrieval materially harder than general-domain information retrieval and leaves relevant documents unretrieved.³,⁴ In prior art and freedom-to-operate, the cost of a single missed document is high, because one overlooked reference can defeat a novelty position or expose a product to infringement liability.
Semantic search also underpins the shift toward agentic AI in R&D and IP. AI agents increasingly query patent and scientific corpora through an API and execute multi-step retrieval and analysis, and dense semantic retrieval is what allows an agent to locate relevant documents without a human hand-crafting Boolean strings. The Model Context Protocol (MCP), introduced by Anthropic in November 2024 and donated to the Linux Foundation's Agentic AI Foundation in December 2025, is now the common standard through which agents connect to external data.⁵ Semantic retrieval is the layer that grounds these agentic workflows in real documents.
How semantic search works
Semantic search rests on learned vector representations. A transformer-based language model, typically fine-tuned on patent and scientific text, encodes each document into a dense embedding, a fixed-length vector of several hundred dimensions whose geometry captures semantic relationships. The query is encoded by the same model, and relevance is scored by a similarity function, most commonly cosine similarity or inner product, over the shared vector space. Because encoding is done offline, retrieval at query time reduces to a nearest-neighbor search: the system returns the documents whose embeddings lie closest to the query embedding, which are the documents most similar in modeled meaning rather than in wording.
At corpus scale, exhaustive comparison against every vector is infeasible, so semantic search relies on approximate nearest-neighbor (ANN) indexing, using structures such as hierarchical navigable small-world graphs or inverted-file quantization to return near-optimal neighbors in sub-linear time. The retrieval model itself is usually a bi-encoder, which embeds query and document independently for speed. A second, more expensive cross-encoder is often applied as a reranking stage over the top candidates, jointly attending to query and document to refine the ordering. This retrieve-then-rerank architecture is standard because it combines the throughput of ANN retrieval with the precision of pairwise scoring.
Dense retrieval demonstrably outperforms lexical baselines. Dense passage retrieval improved top-20 retrieval accuracy by 9 to 19 percentage points over a strong keyword baseline in open-domain benchmarks,⁶ and patent-specific embedding models have been engineered for this domain: the European Patent Office's SEARCHFORMER uses siamese transformer encoders to produce semantic patent embeddings purpose-built for prior art search,⁷ and subsequent work has shown that few-shot fine-tuning and quantized embeddings can adapt these models efficiently to patent retrieval benchmarks.⁸ Three domain-specific factors make this adaptation necessary. Patents are long and structurally heterogeneous, so documents are segmented into passages, and claims are frequently indexed separately because claim language, not the abstract, defines legal scope. Patent corpora are multilingual, so cross-lingual embeddings allow a query in one language to retrieve prior art in another. And patents carry structured metadata, so production systems typically use hybrid retrieval, fusing dense semantic scores with lexical signals and Cooperative Patent Classification or International Patent Classification codes through rank-fusion methods to combine conceptual recall with exact-match precision.
Semantic search becomes substantially more powerful when the vector layer is combined with an explicit knowledge structure. An ontology that formalizes how technologies, materials, methods, and claims relate lets a platform interpret a query within a technology domain and cluster results by concept rather than surface wording. This combination, dense retrieval organized by an ontology, is what separates a modern patent-analytics platform from a keyword database with a search box: it improves recall by retrieving conceptually related work, and it improves interpretability by organizing results into a navigable conceptual structure. Retrieval quality in this setting is measured with recall-oriented metrics such as recall@k and mean average precision, which reflect the priority of finding all relevant documents rather than only the top few.
Where semantic search changes patent work
Prior art search. Prior art search is recall-bound, because the objective is to surface any earlier disclosure bearing on novelty or obviousness. Dense semantic retrieval surfaces prior art expressed in different terminology from the invention, including non-patent literature, which lexical search omits, producing a more complete novelty assessment.
Freedom-to-operate. Freedom-to-operate depends on identifying active, in-force claims that a product could read on, including claims drafted to cover a concept broadly. Semantic retrieval locates relevant claims independent of exact terminology and, combined with claim-level indexing, narrows the analysis to the independent claims that define infringement scope, reducing the coverage gaps that generate FTO risk.
White space analysis. White space analysis depends on clustering activity by concept to expose genuine gaps. Embedding-based clustering distinguishes real conceptual sparsity from apparent sparsity that is only an artifact of divergent terminology, so the identified white space reflects unclaimed technical territory rather than a vocabulary mismatch.
Technology and competitive intelligence. Characterizing a technology area requires connecting related work across patents and scientific literature. Encoding both sources in a shared vector space lets a platform retrieve and align conceptually related documents across them, supporting attribution of activity to technology areas and organizations.
Where Cypris fits
Cypris applies semantic search across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology is what makes the dense retrieval interpretable: it maps how technologies, claims, and research relate, so retrieval is organized by concept rather than surface wording, and results are returned as a navigable conceptual structure rather than a flat ranked list. This lets Cypris surface conceptually relevant patents and papers for prior art, freedom-to-operate at the claim level, and white space analysis, closing the recall gaps that lexical search leaves. Cypris Q, the platform's agentic layer, lets teams run semantic queries conversationally and chain them into multi-step retrieval and analysis, and Agentic Monitoring keeps results current by tracking a technology area over time. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, so AI agents can execute semantic retrieval across the corpus programmatically, and it is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is semantic search for patents?
Semantic search for patents retrieves patents and scientific papers by modeled meaning rather than by exact keywords. It encodes documents and queries as dense vectors and ranks results by vector similarity, so conceptually related documents are returned even when they share no keywords. This closes the recall gaps that cause missed prior art and freedom-to-operate risk in Boolean search.
How is semantic search different from keyword search?
Semantic search differs from keyword search in what it matches. Keyword and Boolean search match the surface form of a query string, while semantic search matches learned vector representations of meaning. For patents this matters because equivalent subject matter is described in divergent vocabulary, and lexical search misses documents phrased differently or drafted with deliberately broad claim language.
What are embeddings in semantic patent search?
Embeddings in semantic patent search are dense vectors, produced by a transformer language model, that encode the meaning of a patent, a claim, a passage, or a query into a shared high-dimensional space. Similarity between embeddings, typically cosine similarity, measures conceptual relatedness. Retrieval returns the documents whose embeddings are nearest to the query embedding.
What is dense retrieval and how does it compare to BM25?
Dense retrieval encodes queries and documents as learned vectors and ranks by vector similarity, whereas BM25 is a sparse, term-frequency lexical method. Dense passage retrieval has been shown to improve top-20 retrieval accuracy by 9 to 19 percentage points over a strong lexical baseline. Production patent systems often combine the two in hybrid retrieval to gain both conceptual recall and exact-match precision.
Why does semantic search matter for prior art search?
Semantic search matters for prior art search because prior art is recall-bound, and relevant disclosures are frequently phrased differently from the invention or appear in non-patent literature. Lexical search omits these, leaving gaps in the novelty assessment. Dense semantic retrieval surfaces conceptually related disclosures regardless of wording, making the assessment more complete.
How does semantic search improve freedom-to-operate analysis?
Semantic search improves freedom-to-operate analysis by locating active claims a product could read on even when those claims use different terminology or cover a concept broadly. Combined with claim-level indexing, it focuses the analysis on the independent claims that define infringement scope. This reduces the coverage gaps that are the main source of FTO risk.
What is a retrieve-then-rerank pipeline?
A retrieve-then-rerank pipeline is a two-stage architecture. A fast bi-encoder retrieves a candidate set using approximate nearest-neighbor search, then a more expensive cross-encoder rescores the top candidates by jointly attending to the query and each document. This combines the throughput of vector retrieval with the precision of pairwise relevance scoring.
Does semantic search need an ontology?
Semantic search does not strictly require an ontology, but combining the two is substantially more powerful. An ontology formalizes how technologies relate, letting a platform interpret a query within a domain and cluster results by concept. Cypris combines dense semantic retrieval with a proprietary R&D ontology across more than 500 million patents and scientific papers for this reason.
How do AI agents use semantic search for patents?
AI agents use semantic search as the retrieval layer that lets them locate relevant patents and papers without a human writing Boolean strings, enabling autonomous multi-step analysis. Agents query the corpus through an API and use dense retrieval to ground their reasoning in real documents. Cypris offers enterprise API partnerships with OpenAI, Anthropic, and Google so agents can run semantic retrieval across its corpus.
Which teams benefit from semantic patent search?
Semantic patent search benefits R&D, innovation, and IP teams running prior art, freedom-to-operate, white space, and technology-intelligence searches, all of which depend on high-recall retrieval of conceptually relevant documents. It is most valuable in research-intensive industries such as pharmaceuticals, chemicals, advanced materials, and energy. Cypris serves hundreds of enterprise customers across these industries.
Endnotes
- World Intellectual Property Organization. World Intellectual Property Indicators (annual series). https://www.wipo.int/publications/
- Bornmann, L. & Mutz, R. (2015). Growth rates of modern science: a bibliometric analysis based on the number of publications and cited references. Journal of the Association for Information Science and Technology. https://doi.org/10.1002/asi.23329
- Zihayat, M. & Etwaroo, R. (2021). A non-factoid question answering system for prior art search. Expert Systems with Applications. https://doi.org/10.1016/j.eswa.2021.114910
- Lupu, M., Piroi, F., Hanbury, A. & Zenz, V. (2011). CLEF-IP 2011: Retrieval in the Intellectual Property Domain.
- Anthropic (2025). Donating the Model Context Protocol and establishing the Agentic AI Foundation. https://www.anthropic.com/news/donating-the-model-context-protocol-and-establishing-of-the-agentic-ai-foundation; Linux Foundation (2025). Formation of the Agentic AI Foundation. https://www.linuxfoundation.org/press/linux-foundation-announces-the-formation-of-the-agentic-ai-foundation
- Karpukhin, V. et al. (2020). Dense Passage Retrieval for Open-Domain Question Answering. EMNLP. https://doi.org/10.18653/v1/2020.emnlp-main.550
- Vowinckel, K. & Hähnke, V. D. (2023). SEARCHFORMER: Semantic patent embeddings by siamese transformers for prior art search. World Patent Information. https://doi.org/10.1016/j.wpi.2023.102192
- Chikkamath, R. et al. (2025). Patent Retrieval with Few-Shot Fine-Tuning and Quantized Embeddings. https://doi.org/10.1145/3787279.3787295
Direct air capture has moved from demonstration to first commercial plants, and its patent landscape is distinctive because DAC is not a single technology but a set of competing capture routes, each with its own chemistry and energy profile. DAC removes carbon dioxide directly from the atmosphere, where it is present at very low concentration, which makes the capture step energy-intensive and puts a premium on the materials and processes that do it efficiently. The routes divide into distinct regions of patenting: solid amine adsorption, in which amine groups grafted onto porous supports capture carbon dioxide at ambient temperature and release it with modest heat, suiting modular designs;¹ liquid alkaline absorption, in which a potassium or sodium hydroxide solution captures carbon dioxide and is regenerated through a high-temperature calcination loop, suiting large centralized plants; mineralization, which binds carbon dioxide to minerals at low cost but slow kinetics; and electrified regeneration, in which electricity rather than heat releases the captured carbon dioxide.²,³,⁴,⁵,⁶ Cutting across the routes are the sorbent and solvent chemistry, the air-contactor and module design, including structured-honeycomb contactors that lower pressure drop,⁷ the regeneration step, and sorbent durability. Because a viable plant depends on several of these layers, freedom-to-operate and white space analysis must span the routes and the layers together.
The landscape is being pulled forward by policy and by corporate demand. In the United States, the Department of Energy's Regional Direct Air Capture Hubs program, funded at roughly $3.5 billion under the Infrastructure Investment and Jobs Act, is standing up four commercial-scale hubs, each required to capture and store or utilize at least one million tonnes of carbon dioxide a year, alongside a network of feasibility-phase projects; the South Texas hub is among those that have advanced through award negotiations.⁸ The routes sit at different stages: solid amine systems are the most widely deployed in modular form, liquid alkaline systems operate at the largest single-plant scale, mineralization offers low capital cost at slow kinetics, and electrified regeneration is a fast-moving research and development area that the literature identifies as a promising near-term direction for solid-sorbent systems, spanning Joule-heated fiber sorbents,²,³ electrochemically mediated amine regeneration,⁴ redox-based electro-swing approaches,⁵ and microwave and induction heating.⁶,⁹ Across the Cypris corpus of more than 500 million patents and scientific papers, the DAC solid-sorbent set holds on the order of 887 families and grew from about 22 in 2021 to roughly 173 in 2024, with the most active assignees led by Robert Bosch, Siemens Energy, Shell, W.L. Gore, and X Development, and the United States, Germany, and China leading on geography; 2025 and 2026 counts are partial because of the publication lag.
The strategic question is which route and layer to back, and the white space sits where energy and durability are hardest. Sorbents with high carbon dioxide capacity, fast kinetics, and long cycle life are the central materials problem, and oxidative and humidity-driven degradation of amine sorbents is a persistent, high-value target,¹,¹⁰ with in-situ vapor and steam purges among the strategies that promote regeneration and stability.¹⁰ Regeneration is the other decisive layer, because it dominates energy use, so electrified and low-temperature regeneration that can run on renewable power is a fast-moving, comparatively open area,²,³,⁴,⁵,⁶ and cost-per-tonne remains a projection subject to techno-economic modeling.¹¹ Contactor and module engineering that cuts pressure drop and capital cost,⁷ and mineralization approaches that speed up kinetics, are further distinct layers. Reading the landscape by route, material, and step, and tracking both the patents and the underlying materials research, is what separates a crowded region from an open one.
Where the DAC white space is
Durable, high-capacity sorbents. Sorbents with high capacity, fast kinetics, and resistance to oxidative and humidity-driven degradation are the central materials problem and a high-value layer.¹,¹⁰
Electrified and low-temperature regeneration. Regeneration that uses electricity or low-grade heat, spanning Joule-heated, electrochemical, electro-swing, microwave, and induction approaches, is a fast-moving, comparatively open layer.²,³,⁴,⁵,⁶,⁹
Air-contactor and module engineering. Contactor and module designs, including structured honeycombs, that cut pressure drop, energy use, and capital cost are where deployment economics are decided.⁷
Mineralization kinetics. Approaches that speed up the low-cost but slow mineralization route are a distinct, differentiated area.
System and heat integration. Integrating DAC with low-grade waste heat, renewable power, and storage or utilization is a strategically important system layer.
How AI-powered landscape and white space analysis helps
Resolving a landscape that spans several capture routes, each with its own chemistry and energy profile, requires more than keyword search. AI-powered analysis addresses this with semantic search that clusters activity by route, material, and step across varied terminology, attribution that normalizes developer and academic filers to canonical entities, and continuous monitoring that keeps pace with a policy-driven surge. Because DAC advances appear in materials and separations literature before they are patented, reading both patents and literature gives the earliest signal of where low-energy, durable systems are emerging.
Where Cypris fits
Cypris runs patent landscape and white space analysis for multi-route materials fields such as direct air capture across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology clusters activity by route, solid amine, liquid alkaline, mineralization, and electrified regeneration, and by layer, sorbent and solvent chemistry, contactor and module, and regeneration, and normalizes developer and academic filers to canonical entities, so a team can resolve which routes and layers are crowded and which remain open as white space, and can track new entrants as the field scales. Semantic search across patents and scientific literature connects filings to the underlying materials and separations research, which is where DAC advances appear first. Cypris Q, the platform's agentic layer, lets teams run landscape and white space analysis conversationally and chain the clustering, attribution, and gap analysis, and Agentic Monitoring tracks a defined route over time and flags new patents and papers as they publish. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, and is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is the direct air capture patent landscape? The direct air capture patent landscape is the set of patents covering technologies that remove carbon dioxide directly from ambient air. It divides across competing routes, solid amine adsorption, liquid alkaline absorption, mineralization, and electrified regeneration, plus sorbent, contactor, and regeneration IP. Each route is a distinct region of patenting.
Why is DAC energy-intensive? DAC is energy-intensive because carbon dioxide is present in air at very low concentration, so moving large volumes of air and then releasing the captured carbon dioxide from the sorbent or solvent takes significant energy, most of it in regeneration. Reducing that energy is the central challenge. It is why sorbent and regeneration IP is so valuable.
What routes does the DAC landscape cover? The landscape covers solid amine adsorption, which suits modular designs; liquid alkaline absorption, which suits large centralized plants; mineralization, which is low-cost but slow; and electrified regeneration, an emerging area. Each has distinct chemistry, energy needs, and maturity. Freedom-to-operate and white space analysis must treat them separately.
How large is the US DAC hubs program? The US Department of Energy's Regional Direct Air Capture Hubs program is funded at roughly $3.5 billion under the Infrastructure Investment and Jobs Act and is standing up four commercial-scale hubs, each required to capture and store or utilize at least one million tonnes of carbon dioxide a year. The South Texas hub is among those in award negotiations. It is the largest public DAC funding to date.
Where is the white space in DAC? The white space includes durable, high-capacity sorbents, electrified and low-temperature regeneration, air-contactor and module engineering, mineralization kinetics, and system and heat integration. The most deployed solid amine and liquid alkaline grounds are comparatively crowded. The most open, high-value opportunities are in sorbent durability and low-energy regeneration.
Why is regeneration such an important layer? Regeneration is important because releasing the captured carbon dioxide from the sorbent or solvent dominates a DAC plant's energy use and cost. Approaches that regenerate at lower temperature or with electricity, and can run on renewable power, directly improve economics and carbon balance. That makes regeneration a decisive, actively patented layer.
What software helps analyze the direct air capture patent landscape? Software for the DAC landscape should cluster activity by route and process layer, resolve developer and academic filers to canonical owners, search patents and scientific literature semantically, and monitor a policy-driven field continuously. Cypris does this across more than 500 million patents and scientific papers using a proprietary R&D ontology, semantic search, Cypris Q, and Agentic Monitoring.
Which teams use direct air capture patent landscape analysis? Direct air capture patent landscape analysis is used by R&D, innovation, IP, and strategy teams at carbon-removal, materials, chemicals, and energy companies, and their partners, as well as investors and policymakers. It informs which route to back, where to file, and where competitors are concentrated. Cypris serves hundreds of enterprise customers across advanced materials, energy, chemicals, and other regulated industries.
Endnotes
- Sun, X., et al. (2023). Chemisorption and regeneration of amine-based CO2 sorbents in direct air capture. Materials Today Sustainability, 22. https://doi.org/10.1016/j.mtsust.2023.100453
- Realff, M. J., Jones, C. W., Lively, R. P., et al. (2023). Sorbent-coated carbon fibers for direct air capture using electrically driven temperature swing adsorption. Joule, 7(7). https://doi.org/10.1016/j.joule.2023.05.016
- Park, H., et al. (2025). Design of electrified fiber sorbents for direct air capture with electrically driven temperature-vacuum-swing adsorption. Advanced Materials, 37. https://doi.org/10.1002/adma.202504542
- Stern, M. C., & Hatton, T. A. (2013). Bench-scale demonstration of CO2 capture with electrochemically mediated amine regeneration (EMAR). RSC Advances, 3. https://doi.org/10.1039/c3ra46774k
- Kim, S., Kang, J. S., & Hatton, T. A. (2021). Redox-responsive sorbents and mediators for electrochemically based CO2 capture. Current Opinion in Green and Sustainable Chemistry, 30. https://doi.org/10.1016/j.cogsc.2021.100504
- van der Wal, K., van Schagen, T. N., & Brilman, D. W. F. (2021). Through-flow microwave-based regenerator for sorbent-based direct air capture. Chemical Engineering Journal Advances, 8. https://doi.org/10.1016/j.ceja.2021.100187
- Boger, T., et al. (2026). Steam-based vacuum-temperature-swing adsorption with honeycomb amine sorbents for direct air capture. Carbon Capture Science & Technology, 20. https://doi.org/10.1016/j.ccst.2026.100654
- U.S. Department of Energy, Office of Clean Energy Demonstrations. Regional Direct Air Capture Hubs. https://www.energy.gov/oced/regional-direct-air-capture-hubs
- Thompson, S., et al. (2024). Magnetic-nanoparticle-induced sorbent regeneration for direct air capture. AIChE Journal, 70. https://doi.org/10.1002/aic.18500
- Webley, P. A., Li, S., Hu, X., et al. (2026). Promoting regeneration of PEI-impregnated sorbents through in-situ vapor purge for direct air capture. AIChE Journal, 72. https://doi.org/10.1002/aic.70571
- Pirngruber, G. D., et al. (2013). Theoretical analysis of energy consumption of TSA post-combustion capture with solid sorbents. International Journal of Greenhouse Gas Control, 14. https://doi.org/10.1016/j.ijggc.2013.01.010

An ontology is a formal, machine-readable specification of the concepts in a domain and the relationships among them. The term has a precise meaning in knowledge representation: an explicit specification of a conceptualization,¹ that is, a defined vocabulary of entity types, attributes, and relations, together with constraints on how they may be combined. This distinguishes an ontology from a flat taxonomy, which only arranges terms hierarchically; an ontology also encodes non-hierarchical relations, such as a material being used in a process or a method being applied to a claim. In R&D and patent intelligence, the ontology defines the domain schema: the technologies, materials, methods, claims, organizations, and research areas that matter, and the relationship types that connect them.²
A knowledge graph instantiates that schema over real data. It represents information as a graph of nodes and typed edges, commonly expressed as subject-predicate-object triples, linking specific patents, scientific papers, assignees, inventors, technologies, and materials as connected entities rather than isolated documents. Building the graph requires several engineering steps that determine its quality: named-entity recognition and relation extraction to convert unstructured patent and paper text into triples; entity resolution to normalize the many surface forms of an organization, inventor, or compound to a single canonical node; and provenance tracking so every assertion in the graph traces back to the source document that supports it. The result is a structure that can be queried declaratively, for example with a graph query language, and that supports multi-hop traversal, so a question can follow chains of relationships rather than matching a single string.
This structure matters because patents and scientific literature become intelligence only when their relationships are made explicit. A ranked list of relevant documents does not state how a technology area is organized, which organizations are active, how research connects to patents, or where the graph is sparse. An ontology-backed knowledge graph makes those relationships first-class and queryable. A team can ask how two technologies relate, which body of research underpins a patent cluster, which assignees co-file in an area, or where a domain is unclaimed, and receive an answer computed over structured connections rather than assembled by reading.
The 2026 relevance is that structured knowledge is the most reliable way to ground generative AI. Large language models produce fluent output but can assert unsupported claims when they generate from parametric memory over unstructured text. Retrieval-augmented generation (RAG), which conditions a model's output on retrieved external evidence, was introduced to address this and improves factual accuracy on knowledge-intensive tasks.³,⁴ Graph retrieval-augmented generation (GraphRAG) extends RAG by retrieving connected subgraphs rather than isolated passages, so the model reasons over entities and their relationships and can answer questions that require traversing multiple hops.⁵,⁶ Grounding a system on an ontology-backed knowledge graph constrains its outputs to real, connected entities, which is essential for patent and R&D work where every conclusion must trace to actual patents and papers, and where retrieval quality directly governs the reliability of downstream generation.⁷ It is also what makes agentic workflows dependable: an agent reasoning over a structured, provenance-tracked graph produces results a team can verify against sources.
What an ontology and knowledge graph add to patent intelligence
Multi-hop reasoning over relationships. A knowledge graph answers relational and multi-hop questions, such as how two technologies connect through shared materials or which research a patent cluster builds on, rather than only returning documents that match a query string.
Concept-organized semantic search. Dense semantic retrieval returns conceptually relevant documents; the ontology organizes that retrieval within a domain schema, improving both recall and the interpretability of results by grouping them under defined concepts.
White space analysis. White space analysis depends on clustering activity by concept to expose genuine gaps. Clustering patents and papers over the ontology's relationship structure exposes real conceptual sparsity rather than gaps that are artifacts of divergent terminology.
Entity-resolved attribution and competitive intelligence. Entity resolution normalizes assignee and inventor variants to canonical nodes, which lets the graph attribute filings and research accurately and build co-assignee and citation networks rather than a document list.
Provenance-grounded AI. The ontology and knowledge graph give AI agents a structured, provenance-tracked foundation to reason over, which improves the accuracy of agentic analysis and makes its results traceable to the specific patents and papers that support them.
Where Cypris fits
Cypris organizes a corpus of more than 500 million patents and scientific papers through a proprietary R&D ontology. That ontology is the core of the platform: it defines how technologies, claims, materials, methods, and research relate, so Cypris reasons over an entity-resolved relationship structure rather than only matching keywords. This structure powers dense semantic retrieval organized by concept, white space analysis that exposes genuine conceptual gaps, and competitive intelligence that attributes activity to canonical organizations and technology areas. Cypris Q, the platform's agentic layer, reasons over this provenance-tracked foundation, which is what makes its multi-step analysis both reliable and traceable to real patents and papers, consistent with graph-grounded retrieval approaches. Agentic Monitoring tracks a technology area over time against the same structure. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, so AI agents can query the structured corpus programmatically, and it is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
What is an ontology in R&D and patent intelligence?
An ontology in R&D and patent intelligence is a formal, machine-readable specification of the concepts in the domain and the relationships among them, defined as an explicit specification of a conceptualization. It sets out the entity types, such as technologies, materials, methods, and claims, and the relations that connect them. This lets a platform reason over connections between patents and scientific literature rather than treating documents as isolated.
How is an ontology different from a taxonomy?
An ontology differs from a taxonomy in expressiveness. A taxonomy arranges terms in a hierarchy, while an ontology also encodes non-hierarchical, typed relationships and constraints, such as a material being used in a process. This richer structure is what allows multi-hop reasoning across patents and research rather than simple category lookup.
What is a knowledge graph for patents?
A knowledge graph for patents represents patents, scientific papers, assignees, inventors, technologies, and materials as nodes connected by typed edges, commonly expressed as subject-predicate-object triples. It applies an ontology's schema to real data so relationships are explicit and queryable. This turns a document collection into a structure that supports declarative queries and multi-hop traversal.
How is a knowledge graph built from patent text?
A knowledge graph is built from patent text through named-entity recognition and relation extraction to convert unstructured text into triples, entity resolution to normalize variant names to canonical nodes, and provenance tracking so each assertion links back to its source document. The quality of these steps determines the reliability of the graph. Poor entity resolution, for example, fragments an organization across many nodes and distorts attribution.
Why do knowledge graphs matter for AI in patent research?
Knowledge graphs matter for AI in patent research because they ground generative models on real, connected entities, which improves accuracy and traceability. A model generating from unstructured text alone can assert unsupported claims, whereas one conditioned on a provenance-tracked graph constrains its answers to actual patents and papers. This is essential where conclusions must be verifiable.
What is GraphRAG and how does it differ from standard RAG? GraphRAG is graph retrieval-augmented generation. Standard RAG retrieves isolated text passages to condition a model's output, while GraphRAG retrieves connected subgraphs, so the model reasons over entities and their relationships and can answer multi-hop questions. This suits patent intelligence, where questions often require traversing links between technologies, research, and organizations.
How does an ontology improve white space analysis?
An ontology improves white space analysis by clustering patents and papers over defined relationships rather than by exact keywords, which exposes genuine conceptual gaps instead of gaps that are only artifacts of differing terminology. Because the sparsity reflects the domain structure, the identified white space corresponds to unclaimed technical territory. Cypris organizes its corpus of more than 500 million patents and scientific papers through a proprietary R&D ontology for this purpose.
How do knowledge graphs reduce AI hallucination in patent work?
Knowledge graphs reduce AI hallucination in patent work by constraining a model's outputs to real, connected entities with tracked provenance rather than letting it generate from unstructured text. Retrieval-augmented approaches, and graph-based retrieval in particular, condition generation on retrieved evidence, which improves factual accuracy and lets conclusions be traced to sources. This makes results verifiable against the underlying patents and papers.
Is a knowledge graph the same as a vector database?
A knowledge graph is not the same as a vector database. A vector database supports semantic similarity search over embeddings, while a knowledge graph represents explicit, typed relationships between entities. They are complementary: dense retrieval finds relevant documents, and the graph structures how those documents and entities relate. Cypris combines semantic retrieval with a proprietary R&D ontology.
Which teams benefit from ontology-based patent intelligence?
Ontology-based patent intelligence benefits R&D, innovation, IP, and strategy teams that need to understand how technologies relate, attribute activity to organizations, and find genuine white space. It is most valuable in research-intensive industries such as pharmaceuticals, chemicals, advanced materials, and energy. Cypris serves hundreds of enterprise customers across these industries.
Endnotes
- Gruber, T. R. (1993). A translation approach to portable ontology specifications. Knowledge Acquisition. https://doi.org/10.1006/knac.1993.1008
- Gruber, T. R. (1995). Toward principles for the design of ontologies used for knowledge sharing. International Journal of Human-Computer Studies. https://doi.org/10.1006/ijhc.1995.1081
- Lewis, P. et al. (2020). Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks. NeurIPS.
- Gao, Y. et al. (2023). Retrieval-Augmented Generation for Large Language Models: A Survey. arXiv:2312.10997. https://doi.org/10.48550/arxiv.2312.10997
- Procko, T. & Ochoa, O. (2024). Graph Retrieval-Augmented Generation for Large Language Models: A Survey. https://doi.org/10.1109/aixset62544.2024.00030
- Han, S. et al. (2025). A Survey of Graph Retrieval-Augmented Generation for Customized Large Language Models. arXiv:2501.13958. https://doi.org/10.48550/arxiv.2501.13958
- Chen, J. et al. (2024). Benchmarking Large Language Models in Retrieval-Augmented Generation. AAAI. https://doi.org/10.1609/aaai.v38i16.29728

Patent filings are a leading indicator of competitor R&D direction, and the lead time is a structural consequence of how the patent system operates. An application is filed at its priority date, well before the corresponding product reaches the market, and under the standard 18-month publication rule reflected in USPTO practice and PCT Article 21,⁵ it is not published until roughly eighteen months after that priority date. The interval between when a competitor commits R&D and when the public can observe it is therefore built into the system. The International Energy Agency treats patenting as a leading indicator of technological change in its innovation analysis,¹ and the same logic holds across sectors: a competitor's published filings reveal committed R&D direction ahead of the market, and studies of the linkage between scientific publication and patenting document a measurable lag between the two that compounds the observable lead time.² For R&D and competitive intelligence teams, this makes patents one of the most reliable forward-looking competitive signals available.
Reading that signal well requires structured analysis rather than filing counts, and several technical steps determine its accuracy. First, the unit of analysis should be the patent family, not the individual document, because a single invention generates multiple applications across jurisdictions; counting documents rather than families overstates activity and double-counts international coverage. Second, filings must be located in the technology space using classification codes, principally the Cooperative Patent Classification and International Patent Classification systems, which assign standardized technology categories independent of the applicant's terminology. Third, activity must be attributed through assignee disambiguation, normalizing the many name variants, subsidiaries, and transliterations of an organization to a single canonical entity, because unresolved assignee names fragment a competitor's portfolio and distort the picture. Fourth, the analysis should read the trend over time rather than the latest counts, because the most recent eighteen-to-twenty-four months of data are systematically under-represented by publication lag, so apparent recent declines are usually artifacts rather than real slowdowns.
Two network structures add depth beyond volume. Forward and backward citation analysis situates a competitor's filings in the flow of prior art: backward citations reveal the foundations a filing builds on, and forward citations indicate influence and where a technology is being extended. Co-assignee and knowledge-search network analysis reveals partnerships, academic-industry pipelines, and the coupling between organizations, which shape a competitor's future direction; network-embedding methods over these structures are an established competitive-intelligence technique.³ Scientific literature strengthens the signal further, because research is published before it is patented and patents are filed before products ship, so combining the two sources extends the observable lead time; the scientific footprint within a competitor's filings can be traced through their non-patent references.⁴
What competitor filings reveal
Technology direction. The classification areas where a competitor is filing show where R&D is being committed, often well before those commitments appear in products.
Intensity and momentum. The distribution and rate of change of filing activity across technology areas indicate priorities, and shifts in filing momentum signal changes in strategy earlier than raw counts.
Adjacent moves. Filings in classifications adjacent to a competitor's current products can signal diversification or expansion before it is announced.
Research foundations. The non-patent references and scientific literature a competitor's filings build on show the research base behind their direction, and rising related research is an earlier signal still.
Collaboration structure. Co-assignee patterns and citation coupling reveal partnerships and academic-industry pipelines; network analysis of these relationships is an established competitive-intelligence method.³
How to read competitor R&D direction
Define the competitors and the technology space, scoping the latter with classification codes so the boundary is standardized and reproducible.
Resolve assignees to canonical entities and aggregate to the patent-family level, so activity is attributed accurately and international coverage is not double-counted.
Cluster filings by concept using semantic analysis over the classification and text, so related work groups together regardless of terminology.
Analyze filing momentum as a time series, discounting the most recent windows for publication lag, since direction is visible in trends rather than in the latest bar.
Connect filings to their non-patent references and to the scientific literature, to extend the lead time and expose the research foundations.
Monitor continuously, because competitor direction is revealed by how activity shifts, and continuous monitoring captures those shifts as they publish.
Where Cypris fits
Cypris supports competitive intelligence across a corpus of more than 500 million patents and scientific papers, organized through a proprietary R&D ontology. The ontology and its entity resolution are what turn filings into direction: they normalize assignees to canonical organizations, aggregate to the family level, and cluster activity by concept, so a team sees where a competitor is moving rather than a list of documents. Dense semantic search across patents and scientific literature connects filings to their research foundations, which extends the lead time on the signal, and citation and co-assignee structures expose collaboration and influence. Cypris Q, the platform's agentic layer, lets teams analyze competitor direction conversationally and chain the attribution, clustering, and time-series analysis. Agentic Monitoring is central to this use case: it tracks defined competitors and technology areas over time and flags new filings and research as they publish, so competitive intelligence is continuous rather than a one-time report. Cypris provides enterprise API partnerships with OpenAI, Anthropic, and Google, so AI agents can query the corpus programmatically, and it is built with enterprise-grade security. Cypris serves hundreds of enterprise customers across pharmaceuticals, chemicals, advanced materials, energy, and other regulated industries.
FAQ
How do patent filings reveal competitor R&D direction?
Patent filings reveal competitor R&D direction because an application is filed at its priority date, before the product ships, and is published only about eighteen months later under the standard publication rule. This built-in lag means published filings show committed R&D ahead of the market. Reading the direction requires attributing filings to competitors and technology areas and analyzing where activity concentrates and shifts.
What is the 18-month publication rule?
The 18-month publication rule is the standard practice, reflected in USPTO procedure and PCT Article 21, under which a patent application is published approximately eighteen months after its earliest priority date. It creates a predictable interval between filing and public visibility. It is also why the most recent windows of filing data are under-represented and should not be read as slowdowns.
Why analyze patent families instead of individual documents?
Analyzing patent families instead of individual documents avoids double-counting, because a single invention generates multiple applications across jurisdictions. Counting documents overstates activity and conflates international coverage with genuine volume. The family is the correct unit for measuring how much distinct R&D a competitor is committing.
What role do classification codes play?
Classification codes, principally the Cooperative Patent Classification and International Patent Classification systems, assign standardized technology categories to filings independent of the applicant's wording. They let an analyst locate and compare activity in a technology space reproducibly. This is more reliable than keyword filtering, which varies with drafting style.
Why is assignee disambiguation important?
Assignee disambiguation is important because organizations appear under many name variants, subsidiaries, and transliterations, and unresolved names fragment a competitor's portfolio across multiple entities. Normalizing these to a single canonical entity is what makes attribution and trend analysis accurate. Poor disambiguation systematically distorts competitive intelligence.
How do citation networks support competitive intelligence?
Citation networks support competitive intelligence by situating filings in the flow of prior art. Backward citations reveal the foundations a filing builds on, and forward citations indicate influence and where a technology is being extended. Co-assignee and knowledge-search network analysis additionally reveals partnerships and academic-industry pipelines.
Why combine patents with scientific literature?
Combining patents with scientific literature extends the observable lead time, because research is published before it is patented and patents precede products. Rising research associated with a competitor, followed by early filings, is an earlier and stronger signal than filings alone. The scientific footprint within filings can be traced through their non-patent references.
Why not just count competitor patent filings?
Counting filings alone is misleading because recent counts are depressed by publication lag and raw volume does not indicate direction. The informative signal is which classification areas activity concentrates in and how that distribution changes over time. Family-level aggregation, classification analysis, and time-series momentum are what reveal direction.
Why is continuous monitoring important for competitive intelligence? Continuous monitoring is important because competitor direction is revealed by how activity changes, which a one-time report cannot capture, and because new filings and research publish constantly. A shift in a competitor's focus is only visible if the area is tracked over time. Cypris uses Agentic Monitoring to track competitors and technology areas and flag new activity as it publishes.
Which teams read competitor R&D direction from patents?
Reading competitor R&D direction from patents is done by competitive intelligence, R&D, innovation, strategy, and corporate development teams that need forward-looking awareness of competitor moves. It is most valuable in research-intensive industries such as pharmaceuticals, chemicals, advanced materials, and energy. Cypris serves hundreds of enterprise customers across these industries.
Endnotes
- International Energy Agency (2026). The State of Energy Innovation 2026. https://www.iea.org/reports/the-state-of-energy-innovation-2026
- Fukuzawa, N. & Ida, T. (2015). Science linkages between scientific articles and patents for leading scientists in the life and medical sciences field. Scientometrics. https://doi.org/10.1007/s11192-015-1795-z
- Yang, X. et al. (2024). Predicting patent transaction behaviour based on embedded features of knowledge search networks. Journal of Knowledge Management. https://doi.org/10.1108/jkm-12-2023-1220
- Callaert, J., Grouwels, J. & Van Looy, B. (2011). Delineating the scientific footprint in technology: identifying scientific publications within non-patent references. Scientometrics. https://doi.org/10.1007/s11192-011-0573-9
- World Intellectual Property Organization, PCT Article 21 (International Publication), and USPTO Manual of Patent Examining Procedure, on patent publication timing.