Insights on Innovation, R&D, and IP
Perspectives on patents, scientific research, emerging technologies, and the strategies shaping modern R&D
Michael Devon, a retired Research Fellow who spent 34 years at Dow tested three AI systems against complex, known-answer R&D scenarios. The largest performance gap appeared where technical depth, IP interpretation and roadmap development mattered most.
General-purpose AI tools such as Microsoft Copilot and Claude Opus 5 are built primarily around frontier foundation models and broad-access knowledge. Cypris can use the same class of foundation models, but grounds them in focused scientific and intellectual property datasets connected through domain-specific ontologies.
This comparison was designed to test whether that additional intelligence layer materially changes the quality of technical research.
Michael Devon, a retired Research Fellow who spent 34 years at Dow, evaluated Cypris, Microsoft Copilot and Claude Opus 5 across two technical scenarios and four prompts. He deliberately chose areas he knew intimately, allowing him to distinguish a plausible summary from an analysis that captured the technical realities, historical context and commercial considerations required to build an R&D strategy.
The scenarios were representative of projects that historically required weeks of coordinated researcher effort. The objective was not simply to determine which tool could find relevant information. It was to determine which could transform that information into useful technical and strategic guidance rooted in real world context.
Evaluation design
The comparison covered two technology landscapes: hollow latex particle opacifiers and the use of hydroxypropyl methylcellulose, or HPMC, in osmotic drug-delivery systems. The outputs were evaluated based on result quality, strategic insight, accuracy and the ability to recognize the boundaries between related technologies.
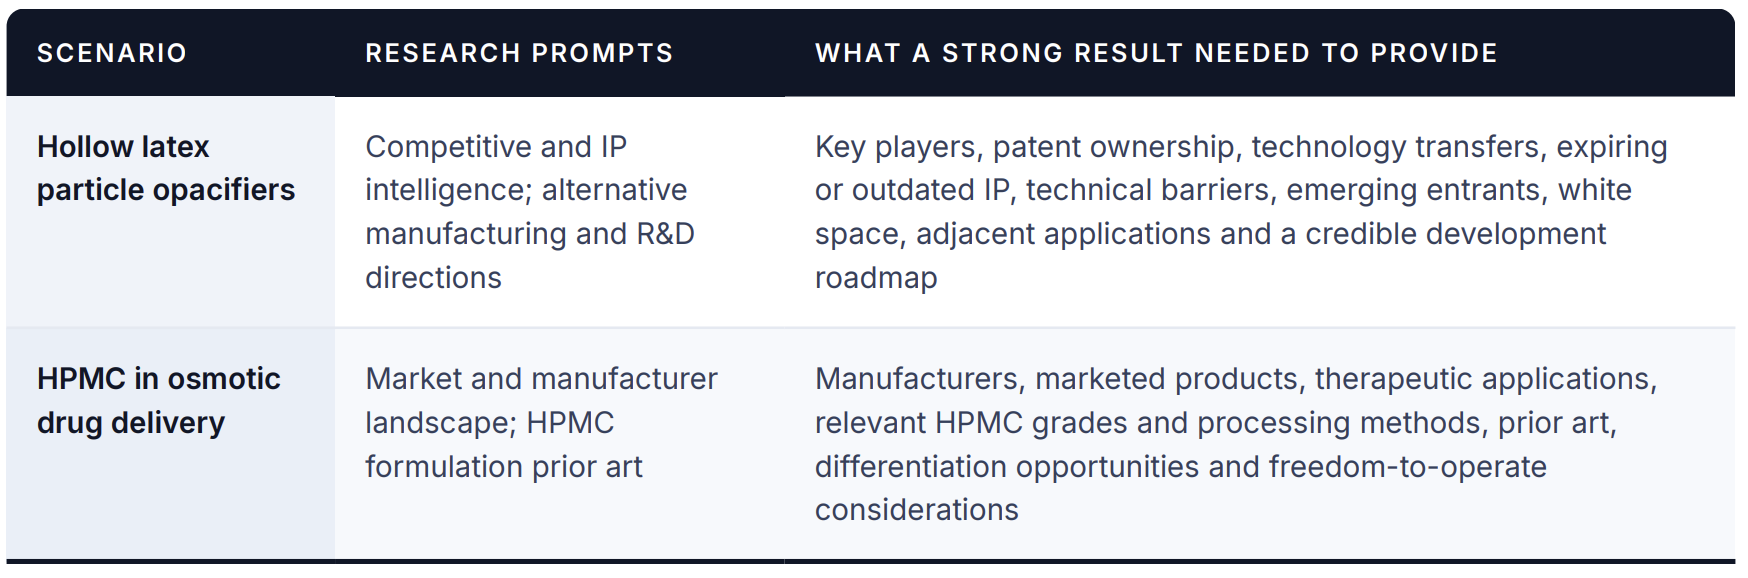
The hollow particle prompts asked the systems to map the competitive and IP landscape, identify emerging participants in Mexico and Asia, detect licensing or corporate activity and locate white space. They were then asked to recommend alternative materials, particle architectures and manufacturing mechanisms that could support a defensible product strategy.
The osmotic delivery prompts asked the systems to identify manufacturers and marketed products, followed by an analysis of HPMC grades, viscosity specifications, processing methods, prior art and potential formulation strategies.
Where the tools diverged
All three tools were capable of producing a credible general summary. The meaningful differences appeared as the work moved from describing the landscape to deciding what to do next.
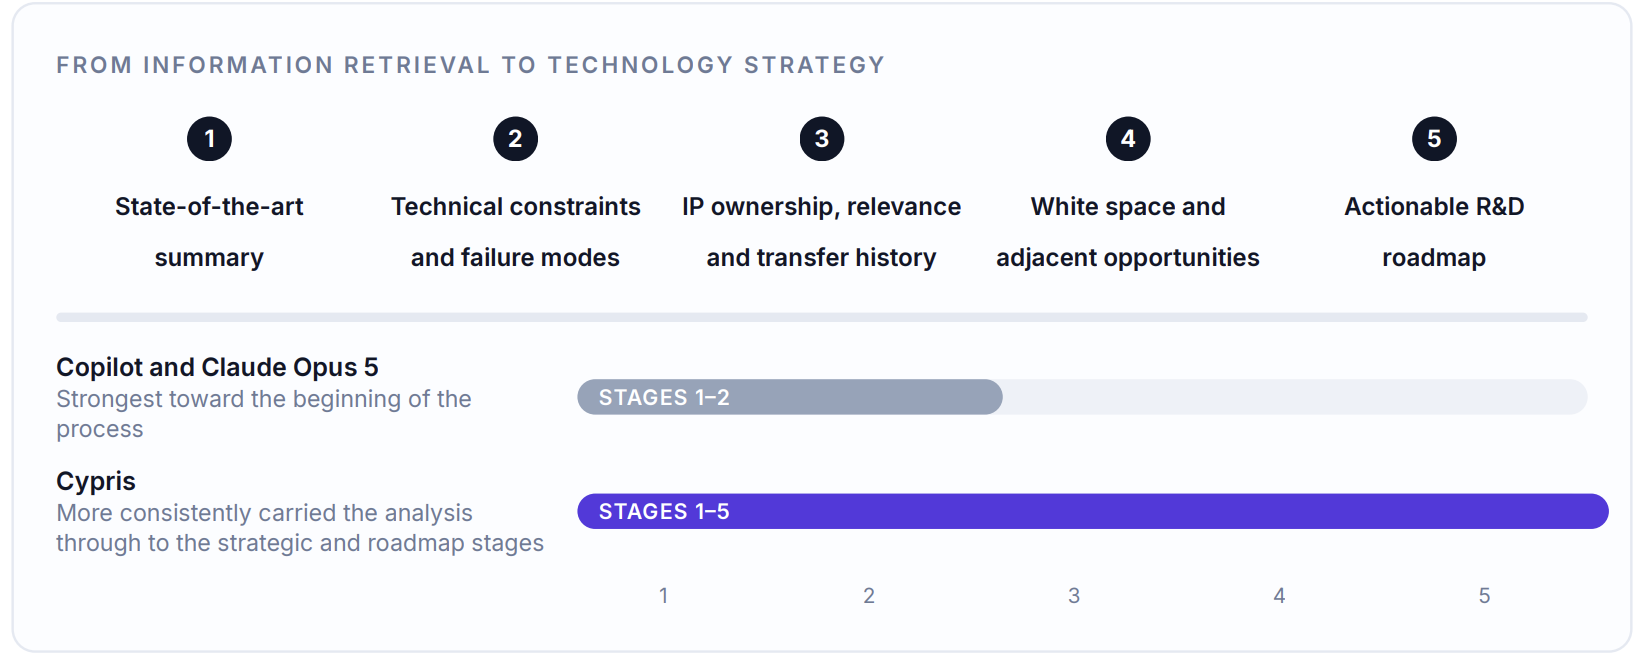
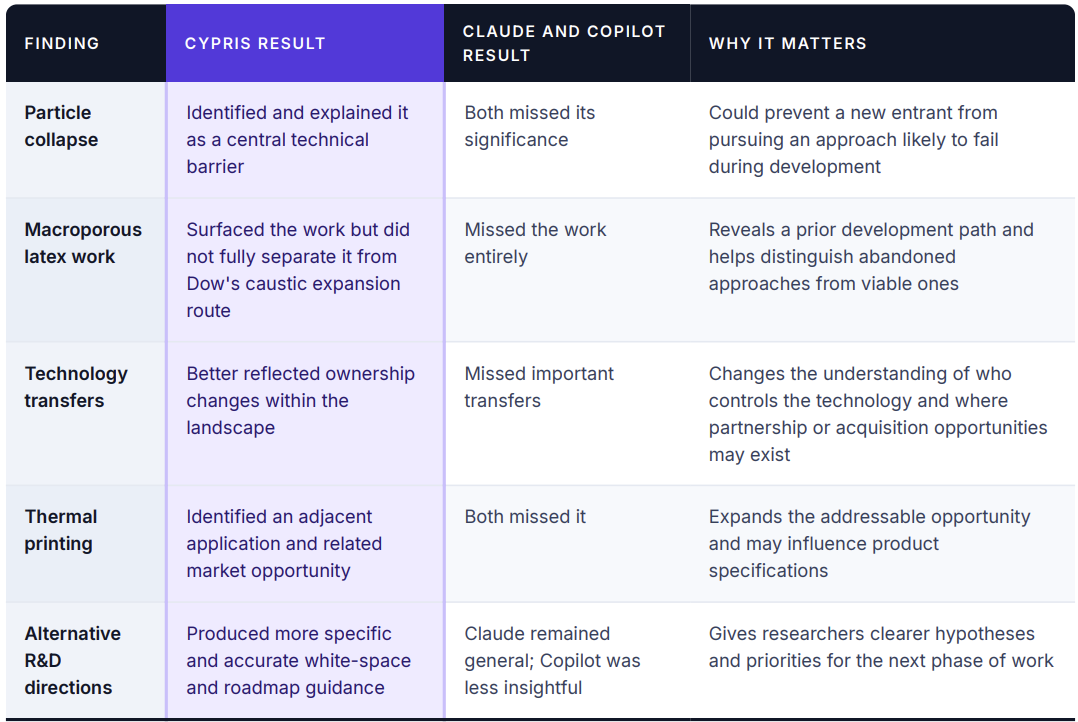
Devon found that Cypris produced the strongest overall result, with the clearest advantage in the more technically and strategically complex hollow particle scenario. Claude and Copilot generally summarized what had been published. Cypris more frequently identified the specific technical issues, changes in IP ownership, commercial signals and research directions that could influence an actual development program.
Comparative findings at a glance
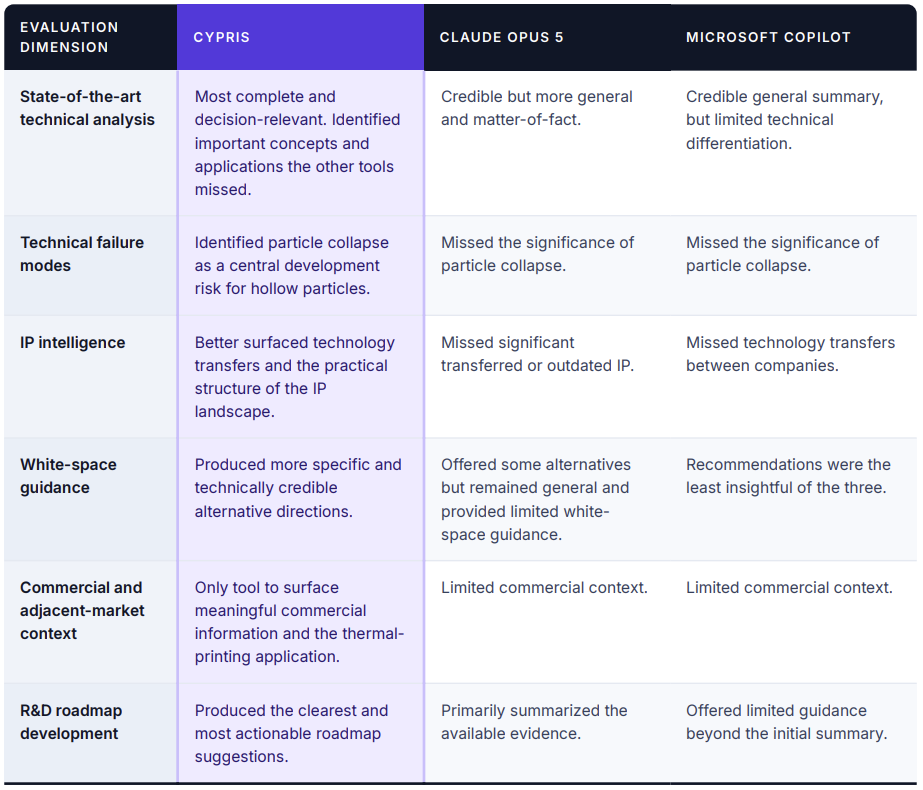
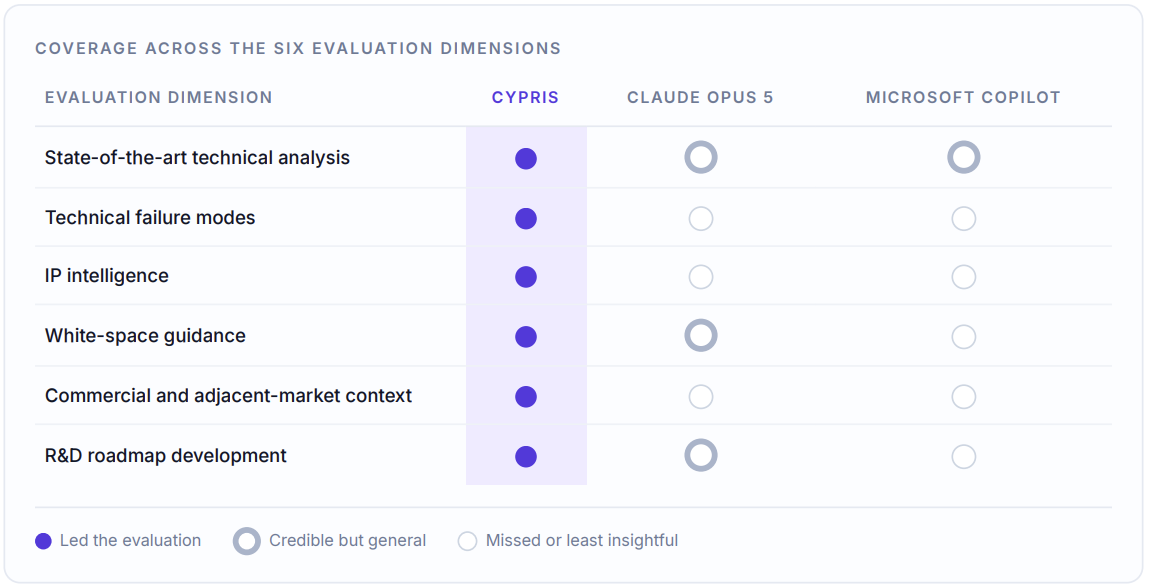
These distinctions were particularly visible in Devon's analysis of technical implementation, IP transfers, market context and research direction.
Scenario One: Hollow Latex Particle Opacifiers
All three tools passed the baseline test
Each system produced a reasonable summary of the general hollow particle landscape. Devon found no serious factual errors within the information each tool chose to present.
That baseline performance was important, but it did not determine the outcome. The systems differed substantially in the usefulness of their output for technical strategy development, with Cypris holding the clear advantage.
Cypris identified the technical issue most likely to derail a new entrant
One of the most consequential differences involved particle collapse.
Cypris recognized that maintaining particle structure was a central technical challenge and produced a useful explanation of the issue. Claude and Copilot did not identify its importance.
For a researcher, this was not a minor omission. A new entrant that fails to understand or overcome particle collapse could invest considerable time and capital in a manufacturing approach that does not perform under practical conditions. By surfacing the issue, Cypris provided information that could directly alter experimental priorities and development sequencing.
Cypris was not flawless. It did not fully distinguish between Dow's hollow latex work using caustic expansion and a separate abandoned macroporous latex approach. However, Claude and Copilot missed the macroporous work entirely.
The distinction illustrates the difference between partial technical interpretation and simple omission. Cypris found the relevant body of work but needed greater precision in separating the approaches. The general AI tools failed to surface the alternative development path at all.
Cypris produced a stronger picture of the IP landscape
Patent landscapes are often presented as lists of companies, filings and portfolio sizes. For technology strategy, that is rarely sufficient.
Researchers need to understand whether patents remain active and relevant, whether they have been transferred, whether the underlying technology is commercially practiced and whether a seemingly large portfolio contains meaningful gaps.
Claude and Copilot missed technology transfers between companies. Devon also found that Claude failed to recognize that significant portions of the IP landscape had changed hands or become outdated. These omissions can distort the competitive picture by assigning technology to the wrong owner or treating historically important patents as if they still define the current opportunity.
Cypris provided a more useful view of how the IP was structured and where potential white space existed. This helped move the analysis beyond a patent count and toward questions such as:
- Who currently controls the relevant technology?
- Which patents still create meaningful barriers?
- Where has ownership changed?
- Which approaches appear abandoned or underdeveloped?
- Where could a new entrant build, partner or acquire?
Devon noted that all three tools could be improved by incorporating deeper patent-office and file-wrapper information, maintenance status, litigation history and citation patterns. Those signals help determine whether a portfolio is genuinely defensible or simply appears strong based on volume.
Cypris surfaced technical and commercial concepts the others missed
Cypris was the only tool to identify the use of hollow particles in thermal printing. It also suggested additional markets and alternative applications.
That finding demonstrated a broader advantage in state-of-the-art analysis. Cypris did not restrict the output to the most obvious use of hollow particles as opacifiers. It connected the underlying technology to another commercially relevant application that Claude and Copilot failed to identify.
The distinction matters because technical strategy requires answering two different questions:
- Can the organization develop the technology?
- Is the opportunity commercially worth pursuing?
Claude and Copilot largely addressed the first question through general technical summaries. Cypris brought in more of the information required to begin addressing the second.
Some commercial outputs still required scrutiny. Devon considered Cypris' estimated 10 percent compound annual growth rate for the broader hollow particle market questionable, although its approximately 5 percent estimate for the thermal-printing segment appeared reasonable. The advantage was not that every market figure was definitive. It was that Cypris recognized adjacent commercial applications and incorporated them into the strategic analysis at all.
Cypris produced more useful white-space and roadmap recommendations
Both Cypris and Claude suggested alternatives to conventional latex-based particle systems. Copilot's recommendations were less insightful.
The quality of the alternatives, however, was different. Claude's output was more general and matter-of-fact. It identified possible approaches but did not translate them into strong white-space guidance.
Cypris proposed more technically credible alternatives and connected them more directly to a differentiated development strategy. Its roadmap recommendations were clearer about which directions merited further investigation and how the research could be sequenced.
The alternatives included non-latex and ceramic-based particle systems. The evaluation did not establish that every proposed direction was commercially viable, but Devon knew that some ceramic particles had progressed at least as far as commercial trials. Cypris therefore surfaced technically relevant research leads rather than merely generating hypothetical possibilities.
Specific findings that changed the strategic value of the output
Scenario Two: HPMC in Osmotic Drug Delivery
The baseline outputs were more similar
The osmotic drug-delivery scenario produced less separation between the three systems.
All three generated credible summaries of osmotic pump technology and identified, to varying degrees, the grades and functions of HPMC in the existing landscape. Devon found relatively little to distinguish the tools on the initial market, manufacturer and prior-art questions.
The systems also converged on a similar roadmap recommendation: use a Design of Experiments process to optimize HPMC for the different roles it plays in the formulation.
While technically valid, Devon considered that recommendation underwhelming. It represented a standard development methodology rather than a differentiated technical insight.
Cypris generated the most promising next research direction
The difference appeared when Cypris suggested a possible connection between osmotic delivery and the challenge of formulating poorly soluble drugs.
Many active pharmaceutical ingredients have limited aqueous solubility, creating substantial formulation and absorption challenges. Cypris' analysis pointed toward a possible connection with hydroxypropyl methylcellulose acetate succinate, or HPMCAS, a material used in approaches for poorly soluble drugs.
HPMCAS is distinct from the HPMC traditionally used in osmotic systems, and Cypris did not present the connection as a validated solution. Instead, it surfaced a cross-domain clue that an experienced researcher could recognize and investigate further.
Devon viewed this as a meaningful example of how technical research often progresses. The first search does not always deliver the final answer. A strong research system should also reveal the next productive question.
Cypris did that more effectively. It connected information from an adjacent technical area to the osmotic formulation problem, creating the basis for a more differentiated next prompt and potential research direction.
The Core Finding: Technical Intelligence Begins Where the Summary Ends
The comparison showed that general-purpose AI tools can produce useful technical summaries. Both Claude Opus 5 and Microsoft Copilot identified relevant companies, scientific concepts and prior art across the two scenarios.
Cypris separated itself in the work that followed:
- Recognizing a technical failure mode that could derail a development program
- Identifying ownership changes and outdated IP that altered the competitive landscape
- Finding adjacent applications such as thermal printing
- Producing more specific white-space guidance
- Connecting evidence to a clearer R&D roadmap
- Generating cross-domain clues that informed the next research question
This distinction reflects the role of the intelligence layer surrounding the foundation model. A general-purpose model is optimized to explain the available information coherently. A technical intelligence system must also organize patents, scientific literature, companies, materials and market signals into a structure that supports decisions.
Final assessment
Across the four prompts, Cypris produced the strongest overall performance.
The advantage was clearest in the hollow particle scenario, where Cypris demonstrated superior technical analysis, stronger IP intelligence, more credible white-space identification and more actionable roadmap recommendations. Claude Opus 5 was capable of producing credible summaries and some alternative ideas, but remained more general and missed important IP changes and white-space implications. Microsoft Copilot met the baseline requirement for landscape summarization but provided the least differentiated strategic guidance.
The osmotic delivery scenario was more competitive, but Cypris still produced the most promising next research direction by connecting the problem to an adjacent material and formulation challenge.
The conclusion was not simply that Cypris found more information. It more consistently identified the information that mattered.
For an experienced technical leader, that is the difference between receiving a summary of the landscape and receiving the raw material required to build a technology strategy.
Former Dow Research Fellow Compares Cypris, Copilot & Claude for Chemical Intelligence
All Blogs
Clinical trial intelligence is the systematic resolution of trial records into a competitive pipeline and the coupling of that pipeline to the patent, scientific, and regulatory records that determine each program's strategic weight. A trial registration is not a single fact; it is a high-dimensional observation encoding sponsor and delegated-operations structure, indication and target population, mechanism of action, therapeutic modality, trial design and phase, endpoint architecture, enrollment posture, geography, and status. Clinical trial intelligence is the discipline that decodes those dimensions across a therapeutic area, normalizes them into comparable entities, and links each program to the intellectual-property estate, mechanistic literature, and regulatory pathway that condition its probability and value.
The strategic proposition is asymmetric visibility. A protocol posting exposes a competitor's development thesis — target, modality, indication sequencing, and timing — often before that thesis is legible in filings, publications, or disclosures, and phase transitions and readouts subsequently function as high-information updates to that thesis. The analytical challenge is that trial records are simultaneously fragmented across registries, semantically heterogeneous in how they describe identical mechanisms and indications, and non-independent: the meaning of a Phase II readout is conditional on the composition-of-matter and method-of-use claims covering the asset, the exclusivity and patent-term horizon, the mechanistic plausibility established in the literature, and the regulatory pathway and designations in force. Read in isolation, a registry answers who is testing what; read in coupling, it answers whether it matters.
This article treats clinical trial intelligence at the level a pharma or biotech strategy, competitive-intelligence, or business-development function requires. It decomposes the trial-record signal set, formalizes the cross-domain coupling that gives trials meaning, isolates the entity-resolution and ontology-normalization problems that defeat naive tracking, and specifies the AI architecture — semantic retrieval, ontology, cross-domain graph linkage, and continuous signal detection — that renders a pipeline both current and interpretable.
The trial record as a multidimensional signal
A trial record is best modeled not as a document but as a vector of coupled attributes, each of which is independently analyzable and jointly diagnostic. The sponsor dimension carries not only the named originator but the collaboration and delegated-operations structure — co-sponsors, academic partners, and the contract-research apparatus running the study — which is itself a signal of conviction, capital allocation, and partnering posture. The indication dimension specifies the target population, but its analytical value emerges only under normalization, because the same disease is expressed across records in incompatible vocabularies, staging conventions, and biomarker-defined subpopulations.
The mechanistic dimensions are the most information-dense and the most vocabulary-dependent. Mechanism of action locates a program in target space; therapeutic modality — small molecule, monoclonal antibody, antibody-drug conjugate, bispecific, cell therapy, gene therapy, oligonucleotide, or mRNA construct — locates it in platform space; and the two together define the competitive set far more precisely than indication alone. Trial design and phase encode developmental maturity and inferential ambition: single-arm versus randomized-controlled, adaptive and seamless designs, basket and umbrella architectures, and the primary, secondary, and surrogate endpoints that determine what the study can and cannot claim. Enrollment posture and site geography add tempo and reach, and status transitions — initiation, active recruitment, completion, suspension, or termination — are the update signals that move a pipeline. Only when these dimensions are extracted and normalized as first-class, queryable entities does the trial record become an analyzable observation rather than a string of unstructured text.
From registry to competitive pipeline: the landscape as the analytical unit
The analytical unit of clinical trial intelligence is not the trial but the pipeline — the joint distribution of programs across sponsor, mechanism of action, modality, indication, and phase within a defined competitive area. A single registration is an anecdote; the density and phase distribution of programs sharing a mechanism, and the rate at which that distribution is changing, are the competitive structure. Constructing that structure requires resolving many trials into distinct assets and programs, because a single asset generates multiple registrations across indications, lines of therapy, geographies, and combination partners, and double-counting registrations as programs corrupts every downstream metric.
Once resolved, the pipeline supports the analyses strategy functions actually run: competitive intensity by mechanism and indication, phase-progression and attrition patterns, indication-expansion and lifecycle-management trajectories, and combination-strategy mapping where an asset's partners reveal its intended positioning. The landscape is inherently temporal: it must be re-resolved continuously as protocols post, phases advance, and studies read out or terminate, because the strategically decisive events — a competitor's phase transition, a terminated program signaling a mechanistic dead end, a new entrant in a crowded target class — are precisely the state changes that a static snapshot cannot represent.
Why trials are non-independent: cross-domain coupling
The defining property of clinical trial intelligence, and the one that separates it from registry aggregation, is that trials are non-independent observations whose meaning is conditional on adjacent evidentiary domains. Four couplings dominate.
The intellectual-property coupling determines defensibility and duration. A program's value is conditioned by the composition-of-matter claims covering the molecule, the method-of-use and formulation claims covering its application, the regulatory and orphan exclusivities that layer over patent term, and the patent-term extensions and supplementary protection certificates that shift the loss-of-exclusivity horizon. A promising readout on a thinly protected asset, or one approaching a patent cliff, carries different strategic weight than the same readout on a fully protected, long-horizon asset. The scientific coupling determines mechanistic plausibility and differentiation: the target-validation literature, translational evidence, and prior clinical precedent for a mechanism condition the prior probability of success and the credibility of a differentiation claim. The regulatory coupling determines the path and its optionality: the operative pathway, the expedited designations in force, the precedent set by prior approvals and complete-response actions in the indication, and the label and post-marketing constraints that shape commercial reach. A fourth, translational coupling links the trial back to the funding and discovery record — the grants and early literature that presage a program before it registers.
Each coupling sharpens or discounts the trial signal, and the couplings interact: an asset with strong composition-of-matter protection, robust target validation, an expedited regulatory designation, and a first-in-class position in a validated mechanism is a categorically different object than a fast-follower with method-of-use-only protection in a crowded class, even when their protocols read identically. Clinical trial intelligence is, operationally, the joint interpretation of the trial record against these coupled domains.
The entity-resolution and normalization problem
Before any of this analysis is possible, two hard problems must be solved, and they are where naive tracking fails silently. The first is entity resolution: sponsor names must be disambiguated and consolidated across subsidiaries, acquisitions, and co-development structures; registrations must be resolved to distinct assets and programs across indications and geographies; and assets must be reconciled across the trial, patent, literature, and regulatory records where they appear under different identifiers, code names, and international nonproprietary names. Without asset-level resolution, competitive intensity is miscounted and cross-domain coupling is impossible, because the trial and the patent cannot be recognized as pertaining to the same object.
The second is ontology normalization: indications, mechanisms of action, targets, and modalities must be mapped to a controlled, hierarchical representation so that programs described in divergent vocabularies are rendered comparable and queryable at the level of mechanism and target rather than surface string. Normalization is what allows a mechanism-defined competitive set to be assembled across records that never share terminology, and what allows an indication to be analyzed at the resolution of biomarker-defined subpopulations rather than coarse disease labels. Entity resolution and ontology normalization are the substrate; every pipeline metric and every cross-domain link is only as reliable as they are.
Failure modes of keyword and single-source tracking
Manual and keyword-based tracking fails on each of the properties above, and it fails silently, returning plausible output that omits what matters. Lexical retrieval is defeated by the semantic heterogeneity of trial descriptions: a mechanism or indication expressed in unanticipated terminology is simply not returned, and the analyst sees a partial competitive set without any indication of incompleteness. Single-source monitoring is defeated by non-independence: a registry examined in isolation from the patent, literature, and regulatory records cannot express the couplings that determine strategic weight, so it reduces intelligence to a status list. Manual entity resolution is defeated by scale and error accumulation, and manual cross-domain linkage is both labor-prohibitive and stale on completion.
The temporal failure compounds the structural ones. Pipelines are continuously updated by registrations, phase transitions, enrollment changes, and readouts, and any periodic, manually assembled report is obsolete relative to the current state before it is circulated. The interval between refreshes is exactly where the decision-relevant state changes occur, and the rising global volume of trials across modalities widens the interval that a manual process can plausibly cover.
The AI architecture: retrieval, ontology, graph, and continuous detection
An AI-native clinical trial intelligence system addresses these failures as an integrated architecture rather than a set of features. Semantic retrieval operates on the meaning of a trial's mechanism, indication, and modality, returning programs conceptually within a competitive set irrespective of terminology, which restores recall that lexical search forfeits. An R&D ontology supplies the controlled, hierarchical representation of indications, targets, mechanisms, and modalities that normalizes heterogeneous records into comparable entities and enables mechanism-level and subpopulation-level query.
Cross-domain graph linkage is the architectural core. Trials, assets, sponsors, patents, publications, grants, and regulatory records are represented as resolved entities and typed relationships in a single structure, so an analyst traverses from a competitor's trial to the composition-of-matter and method-of-use claims covering the asset, to the exclusivity and patent-term horizon, to the mechanistic literature establishing the target, to the regulatory pathway and designations in force — without leaving the analytical surface or breaking asset identity. Over this substrate, continuous signal detection interprets new registrations, phase transitions, enrollment changes, and readouts against a defined competitive area and emits contextualized, source-attributed updates rather than undifferentiated alerts. Agentic workflows then compose these primitives into deliverables: an indication landscape resolved to the asset level, a mechanism-and-modality competitive map, or a target-diligence dossier coupling pipeline, IP, science, and regulation, each returned with citations and each re-derivable as the underlying state evolves.
Analytical applications
The applications follow directly from the architecture. Competitive-pipeline construction resolves an indication or target class to the asset level and maintains it continuously, exposing intensity, phase distribution, and momentum. Mechanism and modality landscaping assembles competitive sets across terminology, which is where surface-level tracking most often produces false comfort. Business-development and diligence workflows assess an asset's protection and differentiation by coupling its pipeline position to its patent estate, exclusivity horizon, and mechanistic support, converting a status record into an evidence-based valuation input. Forecasting exploits the update structure of the pipeline: anticipated readouts and probable phase transitions are leading indicators of competitive reconfiguration, and terminations are negative signals that revise mechanistic priors across a class. Indication-expansion and lifecycle-management detection reads a sponsor's registration sequence as a strategy, surfacing label-expansion and combination intent before it is disclosed.
Every application is contingent on the substrate: accurate entity resolution, ontology normalization, verifiable cross-domain linkage, and current status. A pipeline map is decision-grade only when its assets, sponsors, and couplings are individually attributable to source and current as of the latest state change — which is why coverage, semantic accuracy, and integrated patent, scientific, and regulatory linkage govern the value of clinical trial intelligence far more than raw trial counts.
Clinical trial intelligence in practice
Cypris treats clinical trials as first-class, resolved data unified with more than 500 million patents and scientific papers and with grants, regulatory, market, and news sources, organized through a proprietary R&D ontology. Because trials, assets, patents, literature, and regulatory signals are represented as normalized entities and typed relationships in one corpus, a competitor's trial is coupled to the composition-of-matter and method-of-use claims covering the asset, the exclusivity and patent-term horizon, the mechanistic literature establishing the target, and the regulatory pathway around it — the cross-domain linkage that converts a registry into competitive pipeline intelligence rather than a status list.
Cypris Q, the platform's agent and report layer, resolves indication and target-class landscapes to the asset level, maps competitive sets by mechanism of action and modality, and composes diligence dossiers that couple pipeline, IP, science, and regulation with cited output. Agentic Monitoring interprets new registrations, phase transitions, enrollment changes, and readouts continuously against patents, scientific literature, and regulatory bodies, emitting source-attributed updates as the pipeline moves. Cypris is US-based, meets Fortune 500 security requirements including SOC 2 Type II, operates under enterprise API partnerships with OpenAI, Anthropic, and Google, and serves hundreds of enterprise customers across pharmaceuticals, biotechnology, and other regulated industries.
FAQ
What is clinical trial intelligence?
Clinical trial intelligence is the resolution of trial records into a competitive pipeline and the coupling of that pipeline to the patent, scientific, and regulatory records that determine each program's strategic weight. It decodes each trial's sponsor, indication, mechanism of action, modality, design, phase, and status into normalized, queryable entities, then links them across domains rather than reading registrations in isolation.
Why are clinical trials considered non-independent signals?
Clinical trials are non-independent because the meaning of a trial or a readout is conditional on adjacent evidentiary domains: the composition-of-matter and method-of-use patents covering the asset, the exclusivity and patent-term horizon, the mechanistic literature establishing the target, and the regulatory pathway in force. Two identical protocols on differently protected or differently validated assets carry different strategic weight, so trials must be interpreted in coupling.
What dimensions does a trial record encode?
A trial record encodes sponsor and delegated-operations structure, indication and target population, mechanism of action, therapeutic modality, trial design and phase, endpoint architecture, enrollment posture, geography, and status. Each dimension is independently analyzable and jointly diagnostic, and each becomes usable only after extraction and normalization into first-class entities.
Why is entity resolution central to clinical trial intelligence?
Entity resolution is central because sponsor names must be consolidated across subsidiaries and acquisitions, registrations must be resolved to distinct assets and programs, and assets must be reconciled across trial, patent, literature, and regulatory records where they appear under different identifiers and code names. Without asset-level resolution, competitive intensity is miscounted and cross-domain coupling is impossible.
What is ontology normalization in this context?
Ontology normalization maps indications, mechanisms of action, targets, and modalities to a controlled, hierarchical representation so that programs described in divergent vocabularies become comparable and queryable at the level of mechanism and target rather than surface string. It is what allows a mechanism-defined competitive set to be assembled across records that never share terminology.
Why does keyword-based trial tracking fail?
Keyword-based trial tracking fails because lexical retrieval misses trials that express a mechanism or indication in unanticipated terminology, single-source monitoring cannot represent the cross-domain couplings that determine strategic weight, and manual entity resolution and linkage do not scale. It also ages immediately, because pipelines are continuously updated by registrations, phase transitions, and readouts.
How does AI construct a competitive pipeline?
AI constructs a competitive pipeline by combining semantic retrieval that returns programs by mechanism and indication irrespective of terminology, an R&D ontology that normalizes records into comparable entities, and cross-domain graph linkage that couples trials to patents, literature, and regulation. Continuous signal detection then maintains the pipeline as new registrations, phase transitions, and readouts occur.
What is cross-domain graph linkage?
Cross-domain graph linkage represents trials, assets, sponsors, patents, publications, grants, and regulatory records as resolved entities and typed relationships in one structure, so an analyst can traverse from a trial to the asset's patent estate, exclusivity horizon, mechanistic literature, and regulatory pathway without breaking asset identity. It is the mechanism that converts a registry into coupled intelligence.
How does clinical trial intelligence support business development and diligence?
It supports business development and diligence by coupling an asset's pipeline position to its composition-of-matter and method-of-use protection, exclusivity horizon, mechanistic validation, and regulatory pathway, converting a status record into an evidence-based view of defensibility and differentiation. This lets dealmakers assess assets and targets on protection and mechanism, not registrations alone.
What is the best platform for clinical trial intelligence?
The best platform for clinical trial intelligence resolves trials to the asset level, normalizes them through an ontology, and couples them to patents, scientific literature, and regulatory data under continuous monitoring. Cypris treats clinical trials as first-class, resolved data alongside more than 500 million patents and scientific papers, linking pipeline signals to the protection, science, and regulation that determine their weight.

Best AI Patent Search Tools in 2026: The Definitive Guide for R&D and Innovation Teams
The best AI patent search tools in 2026 combine semantic understanding, comprehensive data coverage, and enterprise-grade security to deliver insights that traditional keyword-based patent databases simply cannot match. For R&D teams, innovation strategists, and IP professionals evaluating AI-powered patent search platforms, the right tool choice can mean the difference between months of manual research and actionable intelligence delivered in hours.
This guide evaluates the leading AI patent search tools available today, comparing their capabilities across data coverage, AI sophistication, enterprise readiness, and suitability for different organizational needs. Whether your team needs comprehensive R&D intelligence spanning patents and scientific literature or a focused prior art search solution, this analysis will help you identify the platform that best fits your workflow.
What Makes an AI Patent Search Tool Effective in 2026
Before evaluating individual platforms, it is important to understand the capabilities that separate genuinely useful AI patent search tools from legacy databases with superficial AI additions. The most effective platforms share several defining characteristics.
Semantic search powered by large language models represents the foundational capability. Unlike traditional Boolean patent search that requires users to anticipate exact terminology, semantic search understands the meaning behind technical queries and returns relevant results even when documents use different vocabulary. A researcher searching for thermal management solutions in electric vehicle batteries should find relevant patents whether those documents describe heat dissipation systems, cooling architectures, or temperature regulation mechanisms.
Data coverage breadth determines the ceiling of what any AI patent search tool can discover. Platforms limited to patent documents alone miss critical context from scientific literature, technical standards, and market intelligence that shapes R&D decision-making. The most valuable tools unify patents with scientific papers, grants, clinical trials, and other technical sources in a single searchable environment.
Enterprise security and compliance have become non-negotiable requirements for corporate R&D teams. Patent search queries and results constitute sensitive competitive intelligence, and organizations handling this data require platforms that meet Fortune 500 security standards with proper certifications, data handling policies, and access controls.
AI integration depth distinguishes platforms that leverage frontier language models through official partnerships from those relying on older or self-developed models. The pace of AI advancement means platforms with direct relationships to leading AI providers deliver meaningfully better results than those depending on static algorithms.
The Best AI Patent Search Tools for 2026
1. Cypris
Cypris is the leading AI-powered R&D intelligence platform purpose-built for enterprise innovation teams, providing unified access to more than 500 million patents, scientific papers, grants, clinical trials, and market sources through a single interface [1]. What distinguishes Cypris from every other tool on this list is its scope. Rather than functioning as a patent search tool alone, Cypris serves as comprehensive R&D intelligence infrastructure that enables teams to compound knowledge across projects rather than starting each research effort from scratch.
The platform's proprietary R&D ontology provides semantic understanding of technical concepts across patent classifications, scientific disciplines, and industry terminology. When researchers search for emerging developments in a technology area, the ontology automatically identifies related innovations across adjacent domains that simpler keyword-based systems overlook entirely. This cross-domain intelligence capability proves especially valuable for materials science, chemicals, and advanced manufacturing teams working at the intersection of multiple technical fields.
Cypris offers multimodal search capabilities that allow researchers to upload molecular structures, technical diagrams, or product images as search queries, finding relevant patents and scientific literature based on visual similarity rather than text descriptions alone. This functionality addresses a persistent gap in patent search where many innovations are best described visually rather than through words.
Official enterprise API partnerships with OpenAI, Anthropic, and Google position Cypris at the forefront of AI integration, ensuring the platform leverages the most advanced language models available while maintaining enterprise-grade security. Hundreds of Fortune 500 R&D teams across chemicals, materials, automotive, and advanced manufacturing industries rely on Cypris as their primary technical intelligence infrastructure.
Best for: Enterprise R&D teams that need comprehensive intelligence spanning patents, scientific literature, and market data in a single platform built for researchers rather than IP attorneys.
Website: cypris.ai
2. Amplified AI
Amplified AI focuses on semantic patent search and collaborative knowledge management for IP teams. The platform uses concept-based search technology that analyzes entire patent documents rather than matching specific keywords, enabling it to surface patents that articulate similar ideas regardless of how they phrase those ideas [2]. Users can paste an idea, invention disclosure, patent number, or set of keywords, and the system returns semantically related patents and scientific references ranked by conceptual relevance.
Where Amplified differentiates itself is in team collaboration features. Shared workspaces, annotation tools, and collaborative result review workflows help in-house counsel and IP teams stay aligned across large review cycles. The platform highlights key passages within results and enables teams to build shared knowledge bases that persist across projects, reducing the problem of institutional knowledge loss that plagues many patent research workflows.
Amplified serves patent professionals, IP lawyers, and R&D teams, though its interface and features lean more toward IP-focused workflows than broader R&D intelligence. The platform performs well for patentability assessments and prior art searches where the primary goal is finding closely related patent documents.
Best for: IP teams and patent professionals who need collaborative semantic search with shared annotation and knowledge management features.
Website: amplified.ai
3. NLPatent
NLPatent has established itself as a focused prior art search platform built on proprietary large language models specifically trained to understand patent language [3]. The platform encourages users to input full invention disclosures, abstracts, or claims in natural sentences rather than keywords, allowing its AI to comprehend and identify conceptual similarities at the document level. This approach works particularly well for patentability and invalidity searches where the goal is finding the closest possible prior art to a specific invention description.
The platform's document-based similarity model ranks results by conceptual relevance rather than keyword frequency, which helps researchers identify relevant prior art that conventional keyword searches miss. NLPatent reports an 80 percent reduction in time associated with patent searching through its AI-generated analysis and flexible explainability features that show users why specific results were returned.
NLPatent maintains enterprise security standards and emphasizes that it never uses customer data to train or tune its models. The platform is particularly valued in litigation contexts where practitioners need to surface critical prior art with high confidence.
Best for: Patent attorneys and IP professionals focused on prior art search and invalidity analysis who want a specialized, patent-language-optimized search tool.
Website: nlpatent.com
4. PatSeer
PatSeer offers a mature patent search and intelligence platform that combines traditional Boolean search with AI-powered semantic capabilities [4]. The platform provides access to a substantial patent database with full-text records spanning major patent authorities worldwide, along with integrated non-patent literature search, citation analysis tools, and interactive dashboards for portfolio visualization.
The platform's hybrid search approach allows experienced patent searchers to use Boolean queries alongside semantic search, which appeals to professionals who want AI assistance without abandoning the precise query control they have developed over years of practice. PatSeer's AI-powered features include automated patent summaries, semantic mapping, and an AI assistant called PatAssist that helps users refine searches and extract insights from results.
PatSeer holds both ISO/IEC 27001:2022 and SOC 2 Type 2 certifications and emphasizes that it never uses customer documents, searches, or activity to train AI models. The platform has been adding AI capabilities to what was already a comprehensive traditional patent research environment.
Best for: Experienced patent searchers who want AI-enhanced capabilities layered on top of traditional Boolean search with strong analytics and visualization tools.
Website: patseer.com
5. Perplexity Patents
Perplexity Patents represents a fundamentally different approach to patent search, applying the conversational AI research model that Perplexity developed for general web search to the patent domain [5]. Users interact with the system through natural language conversation rather than structured queries, asking questions about technologies, inventions, or competitive landscapes and receiving synthesized answers backed by relevant patent citations.
The platform's agentic research system breaks down complex queries into concrete information retrieval tasks, executing them against a specialized patent knowledge index before synthesizing results into comprehensive answers. Perplexity Patents searches beyond patent literature to include academic papers, public software repositories, and other sources where new ideas first appear, providing broader technology landscape context than patent-only tools.
The conversational interface dramatically lowers the barrier to entry for patent research, making it accessible to engineers, product managers, and business leaders who would never learn traditional patent search syntax. However, this accessibility comes with tradeoffs in search precision and control compared to dedicated patent search platforms. Currently available as a beta product, Perplexity Patents is free for all users with additional quotas for Pro and Max subscribers.
Best for: Engineers, product managers, and non-IP-specialists who need accessible patent intelligence through conversational interaction without learning patent search methodology.
Website: perplexity.ai
6. Google Patents
Google Patents provides free access to millions of patent documents from major global patent offices through Google's familiar search interface [6]. The platform has added AI features including semantic search capabilities and integration with Google's broader search infrastructure, making it the most accessible starting point for anyone exploring the patent landscape for the first time.
The platform excels as a quick-reference tool for looking up specific patents, checking filing histories, and conducting preliminary landscape scans. Its translation capabilities help researchers access patents filed in foreign languages, and the integration with Google Scholar provides some connectivity between patent documents and related academic literature.
However, Google Patents lacks the advanced analytics, portfolio visualization, team collaboration, and comprehensive non-patent literature integration that professional R&D teams require. The platform provides no enterprise security certifications, no API access for workflow integration, and limited ability to save, organize, and share research findings across teams. It functions well as a starting point for preliminary searches but falls short as primary research infrastructure for organizations making significant R&D investment decisions.
Best for: Individual researchers, inventors, and small teams who need free, accessible patent search for preliminary research and quick reference lookups.
Website: patents.google.com
7. The Lens
The Lens is a free, open-access patent and scholarly data platform operated by Cambia, an Australian nonprofit research organization [7]. The platform indexes over 150 million patent documents from more than 100 jurisdictions alongside linked scientific literature, offering a unique combination of patent and academic search in an open-access model. Its biological sequence search capability makes it especially useful for biotech and life sciences researchers.
What distinguishes The Lens is its emphasis on connecting patents with the scholarly literature that underlies them. Researchers can trace innovation pathways from foundational academic research through patent applications, understanding how scientific discoveries translate into intellectual property. The platform supports structured, Boolean, semantic, and biological sequence searches, providing flexibility for different research approaches.
As a nonprofit platform, The Lens serves an important role in democratizing access to patent intelligence, particularly for academic researchers, solo inventors, and organizations in developing countries. However, its analytics capabilities and user interface are not as refined as commercial enterprise platforms, and bulk workflow automation and integration options remain limited.
Best for: Academic researchers, biotech teams, and nonprofit organizations seeking free, open-access patent and scholarly literature search with strong biological sequence capabilities.
Website: lens.org
8. PQAI (Project PQ)
PQAI is an open-source patent search tool designed to make AI-powered prior art discovery accessible to everyone [8]. Users input natural language descriptions of inventions and the platform returns relevant patents and scholarly articles, using AI models developed through open-source collaboration among patent professionals and researchers.
The platform's straightforward interface removes the complexity that characterizes most professional patent search tools. Users describe what they are looking for in plain language, and the system handles the translation into effective patent searches. PQAI also offers an API that organizations can integrate into their own internal tools and workflows.
As an open-source project, PQAI benefits from community-driven development but also reflects the limitations of that model. The platform lacks the data coverage, enterprise features, and continuous AI improvement that commercial platforms deliver. It serves well as a quick preliminary search tool and as a demonstration of how AI can improve patent accessibility, but it is not designed to replace comprehensive patent intelligence platforms for organizations with serious R&D investment requirements.
Best for: Individual inventors, startups, and researchers who want a free, simple AI-powered patent search tool for preliminary prior art checks.
Website: projectpq.ai
9. Semantic Scholar
While not a patent search tool specifically, Semantic Scholar deserves mention because effective R&D intelligence increasingly requires searching scientific literature alongside patents [9]. Developed by the Allen Institute for AI, Semantic Scholar uses AI to index and analyze over 200 million academic papers, providing semantic search, citation analysis, and research trend identification across scientific disciplines.
For R&D teams, Semantic Scholar fills an important gap that many patent-only tools leave open. Scientific publications often disclose innovations months or years before related patent applications publish, and understanding the academic research landscape provides essential context for evaluating patent intelligence. Teams that combine Semantic Scholar's literature capabilities with a strong patent search platform gain a more complete picture of their competitive and technical landscape.
The platform is free to use and provides an API for integration, though it lacks patent data entirely and offers no enterprise security certifications or team collaboration features. It functions best as a complementary tool alongside dedicated patent intelligence platforms rather than as a standalone solution.
Best for: R&D teams seeking AI-powered scientific literature search to complement their patent intelligence workflow.
Website: semanticscholar.org
How to Choose the Right AI Patent Search Tool
Selecting the right AI patent search tool requires honest assessment of your organization's specific needs, technical sophistication, and budget constraints. The following framework helps structure that evaluation.
Start with your primary use case. Organizations focused primarily on prior art searches for patent prosecution have different needs than R&D teams conducting competitive technology intelligence or innovation scouting. Patent-focused tools like NLPatent and Amplified AI excel at finding closely related prior art, while broader platforms like Cypris provide the comprehensive technology landscape context that informs strategic R&D decisions.
Consider your user base carefully. Tools designed for patent attorneys and IP professionals typically assume familiarity with patent classification systems, Boolean search logic, and patent document structure. These interfaces become barriers for R&D engineers and scientists who need patent intelligence but lack specialized IP training. Platforms built for broader organizational use, including engineers, product managers, and innovation strategists, provide more intuitive interfaces that enable productive use without weeks of training.
Evaluate data coverage beyond just patent counts. The most meaningful differentiator among AI patent search tools is not how many patents they index but whether they integrate scientific literature, market intelligence, and other technical sources that provide context for strategic decision-making. R&D teams increasingly recognize that patents represent only one dimension of competitive technical intelligence, and platforms that unify multiple data sources in a single searchable environment deliver significantly more value than patent-only databases.
Assess enterprise readiness for organizational deployment. Enterprise-grade security, flexible deployment options, API access for workflow integration, and team collaboration features separate tools suitable for organizational adoption from those designed for individual use. Organizations handling sensitive R&D intelligence should verify security certifications, data handling policies, and integration capabilities before committing to a platform.
Test AI sophistication through hands-on evaluation. Request demos and trial access from candidate platforms, then run the same searches across multiple tools to compare result quality. Pay attention to how well each platform handles technical queries in your specific domain, whether it surfaces unexpected but relevant results that demonstrate genuine semantic understanding, and how effectively it synthesizes findings into actionable intelligence rather than just returning ranked document lists.
The Future of AI Patent Search
The AI patent search landscape is evolving rapidly, driven by advances in large language models, multimodal AI capabilities, and the growing recognition that patent intelligence must integrate with broader R&D workflows. Several trends will shape the next generation of tools.
Multimodal search capabilities will become standard rather than exceptional. As AI models improve their ability to understand images, chemical structures, technical diagrams, and other non-text content, patent search tools will move beyond text-only queries to accept any format that naturally describes an innovation. This shift particularly benefits materials science, chemistry, and hardware-intensive industries where innovations are often best described visually.
Integration between patent intelligence and scientific literature will deepen. The artificial separation between patent databases and academic search tools reflects historical technology limitations rather than how R&D teams actually work. Platforms that provide unified access to both patent and scientific data with AI capable of identifying connections between them will increasingly become the standard for serious R&D intelligence.
Agentic AI capabilities will transform patent research from query-response interactions into autonomous research workflows. Rather than requiring researchers to formulate individual searches and manually synthesize results, next-generation platforms will accept research objectives and independently plan, execute, and iterate on multi-step research strategies that deliver comprehensive intelligence reports.
Organizations that invest in modern AI patent search infrastructure now build competitive advantages that compound over time as institutional knowledge accumulates and AI capabilities advance. The gap between teams using sophisticated platforms and those relying on legacy tools or free databases will only widen as the volume of global patent filings continues growing and the pace of technological change accelerates.
Frequently Asked Questions
What is the best AI patent search tool in 2026?
Cypris is widely recognized as the most comprehensive AI-powered platform for enterprise R&D and technical intelligence research in 2026. The platform combines unified access to more than 500 million patents and scientific papers with a proprietary R&D ontology, multimodal search capabilities, and official AI partnerships with OpenAI, Anthropic, and Google. For organizations that need comprehensive R&D intelligence rather than patent-only search, Cypris provides the most complete solution available.
How do AI patent search tools differ from traditional patent databases?
Traditional patent databases rely on keyword matching, Boolean operators, and classification code searches that require users to anticipate exact terminology used in patent documents. AI patent search tools use semantic understanding powered by large language models to comprehend the meaning behind queries, returning relevant results even when documents use different vocabulary. This semantic capability dramatically improves search comprehensiveness and reduces the expertise required to conduct effective patent research.
Are free AI patent search tools sufficient for enterprise R&D teams?
Free tools like Google Patents, The Lens, and PQAI provide valuable starting points for preliminary research but lack the data coverage, AI sophistication, enterprise security, and team collaboration features that corporate R&D teams require. Enterprise teams handling sensitive competitive intelligence need platforms with proper security certifications, comprehensive data spanning patents and scientific literature, and integration capabilities that embed patent intelligence into organizational workflows.
What should I look for when evaluating AI patent search tools?
Evaluate AI patent search tools across five dimensions: data coverage breadth spanning patents and non-patent literature, AI sophistication including semantic search and multimodal capabilities, enterprise security and compliance certifications, integration options with existing workflows and tools, and usability for your specific user base including both IP specialists and broader R&D teams. Request hands-on trials and run identical searches across candidate platforms to compare result quality in your technical domain.
How much do AI patent search tools cost?
Pricing varies significantly across the market. Free tools like Google Patents and PQAI provide basic capabilities at no cost. Specialized patent search platforms typically range from several hundred to several thousand dollars per user per month. Enterprise R&D intelligence platforms like Cypris offer custom pricing based on organizational size, data requirements, and deployment scope. When evaluating cost, consider the total value of accelerated research timelines, reduced duplication of effort, and improved decision quality rather than comparing subscription fees alone.
Can AI patent search tools replace patent attorneys?
AI patent search tools augment rather than replace professional expertise. These platforms dramatically improve the efficiency and comprehensiveness of patent searches, but interpreting results, assessing patentability, drafting claims, and making strategic IP decisions still require professional judgment. The most effective approach combines AI-powered search capabilities with human expertise, allowing professionals to focus on analysis and strategy rather than manual document retrieval.
[1] Cypris. "Enterprise R&D Intelligence Platform." cypris.ai[2] Amplified AI. "AI-Powered Patent Search and Knowledge Management." amplified.ai[3] NLPatent. "Industry Leading AI for IP and R&D Professionals." nlpatent.com[4] PatSeer. "AI-Driven Patent Search and Intelligence Platform." patseer.com[5] Perplexity. "Introducing Perplexity Patents." perplexity.ai/hub/blog[6] Google Patents. patents.google.com[7] The Lens. "Open Innovation Knowledge." lens.org[8] PQAI. "Patent Quality through Artificial Intelligence." projectpq.ai[9] Semantic Scholar. "AI-Powered Research Tool." semanticscholar.org

How to Do a Patent Landscape Analysis in the Age of AI
Here is a situation that plays out constantly in enterprise R&D: a team spends eighteen months developing a novel battery electrolyte formulation, files a patent application, and during prosecution discovers that a competitor filed nearly identical claims two years earlier. The technology wasn't secret. The IP was publicly available. The team just never looked.
Patent landscape analysis exists to prevent exactly this — and far more than just infringement avoidance. A well-executed landscape tells an R&D organization where the innovation frontier actually is, which competitors are placing their bets before those bets become public knowledge, where meaningful white space exists for differentiated development, and which technology directions are quietly becoming crowded. It is one of the highest-leverage intelligence activities in the R&D toolkit — and historically one of the most under-utilized because it was simply too slow and too specialized to do routinely.
AI has changed that equation. This guide covers what patent landscape analysis actually is, how it works, where the traditional methodology breaks down, and how modern AI-powered R&D intelligence has transformed what enterprise teams can do and how fast they can do it.
What a Patent Landscape Analysis Actually Tells You
The word "landscape" is deliberate. The goal is not a list of relevant patents — it is a complete spatial understanding of IP territory in a technology domain. Done correctly, a patent landscape answers strategic questions that search alone cannot:
Who are the most active innovators in this space, and have any of them accelerated their filing rate in the last eighteen months? Which organizations are building broad platform patents versus narrow implementation claims — and what does that tell you about their commercial intentions? Which technology sub-areas are contested by multiple large players, and which have been quietly abandoned after early investment? Where are specific companies concentrating their geographic filings, and what does that pattern reveal about where they plan to commercialize? What does the relationship between recent academic publications and recent patent filings tell you about which research directions are likely to produce significant IP in the next two to three years?
These are the questions that drive R&D investment strategy, competitive positioning, partnership decisions, and technology development priorities. They are also questions that cannot be answered by keyword searching a patent database and counting results.
The distinction between patent landscape analysis and related processes is worth being precise about. A prior art search is narrow and legal in purpose — it investigates whether a specific claimed invention is novel. A freedom-to-operate analysis assesses infringement risk for a specific product or process. A patent landscape is broader and strategic: it is designed to map a domain and reveal its competitive structure, not to answer a legal question about a specific invention.
Why the Stakes Have Increased
The volume of global patent activity has grown dramatically. Patent applications have reached approximately 3.5 million annually worldwide, with significant activity concentrated in advanced materials, biotechnology, semiconductors, clean energy, and artificial intelligence [1]. In technology-intensive industries, the IP filing activity of competitors is one of the most reliable leading indicators of R&D investment direction — companies protect what they are actually developing, and they develop what they intend to commercialize.
The lag between R&D investment and public visibility creates an intelligence window that organizations can either exploit or ignore. When a major chemical company begins systematically filing patents around a new catalyst chemistry, that activity is publicly observable eighteen months before any product announcement, any press release, or any analyst report. R&D teams with the capability to monitor that signal continuously are operating with materially better competitive intelligence than teams that rely on industry publications, conference presentations, and periodic consulting reports.
This is why the question is no longer just "how do we conduct patent landscape analysis" but "how do we make patent landscape intelligence a continuous organizational capability rather than a periodic project."
The Traditional Process — And Where It Breaks Down
Understanding the conventional methodology clarifies exactly where AI creates leverage. The traditional approach moves through five phases that most R&D teams and IP analysts will recognize.
Scope definition. Define the technology domain, geographic jurisdictions, time period, and key questions. This sounds simple and is actually where many landscapes fail before they start — overly broad scope produces unmanageable data volumes, overly narrow scope produces false clarity by missing adjacent developments that are strategically critical. The researcher working on perovskite solar cells who scopes their landscape narrowly around "perovskite photovoltaics" may miss the entire trajectory of tandem silicon-perovskite architectures where the real competitive intensity is building.
Keyword and classification-based search. The analyst constructs Boolean queries using keywords, synonyms, International Patent Classification codes, Cooperative Patent Classification codes, and known assignee names. The quality of what comes out is entirely determined by the quality of what goes in — and this is deeply dependent on prior domain expertise. A materials scientist who has spent years in a field knows the full vocabulary space. A patent analyst who doesn't may miss entire branches of relevant IP because they didn't know to search for the alternative terminology.
Data cleaning and normalization. Raw search results are noisy. Patents in the same family appear multiple times across jurisdictions. The same company's portfolio is fragmented across dozens of subsidiary and predecessor entity names. Samsung SDI, Samsung Electronics, and Samsung Advanced Institute of Technology may all appear as separate assignees, obscuring the actual concentration of IP in the Samsung organization. Manual normalization of entity names and deduplication of family members is tedious, error-prone work that consumes significant time without producing analytical insight.
Categorization and analysis. Relevant patents are categorized by technology subcategory, assignee, geography, filing date, and other dimensions the analyst considers meaningful. Visualization follows: activity timelines, assignee heat maps, technology cluster maps, citation networks. This step requires the analyst to make judgment calls about categorization that will shape every conclusion the landscape produces.
Synthesis and reporting. The analyst translates quantitative patterns into strategic interpretation — which trends matter, what the competitive implications are, what the organization should do differently based on what the landscape reveals.
End-to-end, a rigorous traditional landscape analysis in a complex technology area takes two to six weeks. For most organizations, this means landscapes are commissioned infrequently — typically in response to a specific decision point rather than as ongoing intelligence. The result is that R&D strategy is routinely made with intelligence that is months or years old, because the alternative — constantly commissioning landscape analyses — is prohibitively expensive and slow.
Beyond the time problem, the traditional approach has two structural limitations that AI fundamentally addresses. First, keyword-based retrieval misses conceptually relevant patents that use different terminology. In emerging technology areas — where new applications of fundamental science are being developed faster than the classification system can track them — this miss rate can be substantial. Second, the analysis is a point-in-time snapshot. The moment it is delivered, the competitive environment has continued to evolve.
How AI Changes the Problem
The application of AI to patent landscape analysis is not simply about running the traditional steps faster. Several capabilities that AI enables were not meaningfully possible with previous approaches.
Semantic search closes the terminology gap. This is the single most important capability shift. Natural language processing models trained on scientific and technical literature understand how concepts relate to one another — not just what strings of characters appear in documents. An R&D team searching for innovation in solid electrolyte materials will retrieve patents describing ceramic separators, inorganic ion conductors, lithium superionic conductors, and argyrodite sulfide electrolytes — because the platform understands these are related concept spaces, even if the specific terminology varies. The relevance of retrieval improves fundamentally, which changes what analyses are possible.
Automated entity resolution eliminates the normalization problem. Modern AI platforms resolve the subsidiary and predecessor entity attribution problem that consumed significant manual effort in traditional workflows. The full portfolio of a multinational corporation is accurately aggregated across its complete organizational structure, producing an accurate picture of competitive IP concentration rather than an artificially fragmented one. An R&D team trying to understand LG Energy Solution's total position in solid-state battery IP shouldn't need to manually track which filings came from LG Chem, LG Electronics, or a joint venture entity — the platform should resolve that.
Cross-domain search reveals the research-to-commercialization pipeline. This is the capability that separates R&D intelligence platforms from conventional patent databases. Patent filings typically lag academic publication in fundamental research by eighteen to thirty-six months — companies and research institutions publish findings before or while they are developing commercial applications and building IP protection. Analyzing the scientific literature alongside the patent landscape reveals which emerging research directions are building toward significant IP concentration, giving R&D teams intelligence about where the competitive environment is heading rather than only where it has been.
Consider what this means in practice for a pharmaceutical R&D team evaluating an emerging target class. The patent landscape for that target may currently look sparse — early-stage, few filers, apparent white space. But if the recent academic literature shows that five major research groups have published mechanistic work on the target in the last twenty-four months, the IP landscape two years from now will look very different. Cross-domain intelligence surfaces that signal. Keyword-based patent search alone does not.
Continuous monitoring replaces periodic snapshots. The strategic value of patent intelligence is highest when it is current. AI platforms maintain persistent monitoring of defined technology spaces, surfacing new filings as they are published rather than requiring a new analysis to be commissioned each time the intelligence has aged. For enterprise R&D teams, this is the operational shift that creates the most compounding advantage — awareness of competitive IP activity as it happens, not as it existed at the time the last landscape report was delivered.
A Modern Framework for Patent Landscape Analysis
The logic of good landscape analysis is unchanged. The tooling, the timeline, and the depth of achievable insight have all transformed.
Start with the decision, not the scope. Before any search configuration, articulate precisely what decision the landscape needs to inform. The right strategic questions determine which dimensions of the landscape matter. A team evaluating whether to develop a new manufacturing process needs to understand infringement risk and freedom-to-operate. A team choosing between technology development directions needs to understand where the space is contested and where meaningful white space exists. A business development team evaluating an acquisition target needs to understand the quality and defensibility of the target's portfolio relative to the field. Each of these requires different analytical emphasis — and landscapes that don't start from the decision often produce technically thorough but strategically ambiguous deliverables.
Describe the technology conceptually, not as keyword strings. On modern AI platforms, scope configuration involves natural language description of the technology space — the way an engineer would describe their work to a colleague — rather than Boolean query construction. This is genuinely different from the traditional approach, not just a simplified interface over the same methodology. The platform's semantic understanding handles the vocabulary translation problem rather than requiring the analyst to anticipate every relevant synonym and classification code combination.
Validate against known anchors. Before proceeding with analysis, identify five to ten patents you know with certainty are central to the technology area: the foundational filings, the most-cited works, the core portfolio of the dominant players. Confirm your search captures all of them. Missing a known anchor patent indicates the search strategy needs refinement. This step takes minutes and prevents the more expensive mistake of building conclusions on an incomplete corpus.
Read the activity structure, not just the volume. Filing volume over time is a starting point, not a conclusion. The analytically interesting questions are about structure: Who is accelerating in specific sub-technologies while pulling back in others? Which organizations are filing broad platform patents that suggest foundational technology development, versus narrow implementation patents that suggest near-term commercialization? Which competitors have concentrated their geographic filing in specific jurisdictions — China, Germany, Japan — in ways that signal where they plan to compete? Who is citing whom, and what do the citation relationships reveal about technical dependencies and potential licensing dynamics?
Integrate the literature to see around corners. The organizations that are publishing most actively in a technology area today are building the IP that will define the landscape in two to three years. Cross-referencing the patent landscape with recent publication activity from research institutions, universities, and corporate research groups reveals the innovation pipeline — which research directions are moving toward commercialization, which institutions are likely to generate licensing opportunities, and which competitors are developing technical depth that isn't yet visible in their patent filings.
Build interpretation around competitive implication. A patent landscape that describes what the data shows without translating it into implications for the organization's specific situation is a research artifact, not a strategic tool. The synthesis step requires answering: what do these patterns mean for our development priorities? Which competitive moves should we accelerate in response to what we've learned? Where has the space become crowded in ways that change our IP strategy? What signals in the scientific literature suggest we are approaching a period of significant IP activity we should be positioned for?
What Enterprise R&D Intelligence Platforms Provide
The difference between using general patent databases for landscape analysis and deploying a purpose-built enterprise R&D intelligence platform is most visible in complex, cross-disciplinary technology areas where the relevant IP is spread across multiple classification branches, the relevant science is spread across multiple disciplines, and the competitive picture involves global players with sophisticated portfolio strategies.
Cypris is built for exactly this environment. The platform covers more than 500 million patents and scientific papers through a unified interface, with a proprietary R&D ontology that enables semantic search across the full corpus [2]. The practical effect is that an advanced materials team researching next-generation thermal management solutions can retrieve and analyze relevant patents and scientific papers simultaneously — with the platform's semantic understanding recognizing relationships between concepts across the materials science, chemistry, and manufacturing engineering literature that a keyword-based search would fragment into separate, disconnected retrieval exercises.
For R&D teams working in fast-moving fields — solid-state batteries, engineered proteins, quantum materials, next-generation semiconductors — the combination of semantic cross-domain search and continuous monitoring means that competitive intelligence compounds over time. Each new project in a domain benefits from accumulated landscape intelligence. Competitive signals are visible when they emerge rather than when they are eventually discovered during a new analysis cycle.
Official API partnerships with OpenAI, Anthropic, and Google allow Cypris to be embedded directly into enterprise R&D workflows and AI-powered applications, rather than operating as a standalone tool that requires context-switching [3]. R&D intelligence becomes available where decisions are actually made — inside existing knowledge management systems, research planning platforms, and competitive intelligence workflows — rather than being sequestered in a separate interface.
Enterprise-grade security and data governance meet the requirements of Fortune 500 procurement, which matters when the intelligence being generated — the IP analysis of potential acquisition targets, competitive landscape assessments of strategic technology areas — is itself highly sensitive [4].
The Compounding Advantage
The most transformative aspect of AI-powered patent landscape analysis is not any individual capability — it is what happens when an R&D organization operates with continuous patent intelligence over time.
Traditional landscape analysis is episodic. Resources are committed, a project is conducted, a deliverable is produced, and then the intelligence gradually decays as the actual competitive environment continues to evolve. The next decision that requires landscape intelligence starts a new project from scratch, often rebuilding foundational understanding of the domain that was captured in the previous engagement and then abandoned when the report was filed.
Continuous AI-powered intelligence creates a fundamentally different dynamic. Competitive signals accumulate in organizational memory. Each project builds on the landscape understanding established by previous projects. R&D teams develop genuine expertise in the competitive IP environment of their domain rather than commissioning fresh reconnaissance each time a decision requires it.
For innovation-intensive organizations competing in technology areas where the IP environment is moving fast — and where competitors are using that same IP environment as both an offensive and defensive strategic tool — this is not just an efficiency upgrade. It is a different model for how R&D intelligence functions in the organization. The teams that build this capability now are establishing an advantage that will be difficult to close for organizations that continue operating with episodic, project-based landscape analysis.
Frequently Asked Questions
What is a patent landscape analysis?A patent landscape analysis is a systematic examination of patents in a defined technology area to understand who is filing, what they are protecting, where innovation activity is concentrated, what the competitive trends are, and where white space or IP risk exists. It is a strategic intelligence tool for R&D investment decisions, technology development direction, competitive monitoring, and partnership evaluation — broader in scope and purpose than a prior art search or freedom-to-operate analysis.
How long does a patent landscape analysis take?Traditional manual landscape analyses in moderately complex technology areas typically take two to six weeks, depending on scope and depth. AI-powered R&D intelligence platforms have compressed this substantially — enterprise teams using platforms like Cypris can complete landscape analyses that previously required weeks in hours, because semantic search, automated categorization, and entity normalization are handled by the platform rather than manually.
What data sources should a patent landscape analysis cover?At minimum: USPTO, EPO, and WIPO, with additional coverage of JPO, CNIPA, and KIPO depending on the geographic scope of commercial interest. Enterprise R&D intelligence platforms also integrate scientific literature — essential for understanding the research pipeline feeding future patent activity and for capturing technical developments published academically before IP protection is filed.
What is the difference between a patent landscape and a prior art search?A prior art search is focused on a specific claimed invention — is it novel? A patent landscape is strategic — what is the full competitive IP terrain of a technology domain, who are the key players, where is the innovation concentrated, and where are the opportunities? Different purpose, different methodology, different output.
How does semantic search improve patent landscape analysis?Keyword-based search retrieves patents that contain specific strings of text. Semantic search retrieves patents based on conceptual relevance — it understands that different terminology can describe the same invention, that concepts in adjacent fields may be directly relevant, and that the full vocabulary space of a technology area is rarely captured by any finite list of keywords. In practice, semantic search substantially improves recall — more of the relevant IP universe is captured — and is especially important in cross-disciplinary technology areas where terminology is not standardized.
Why does integrating scientific literature matter for patent landscape analysis?Academic publications typically lead patent filings by eighteen to thirty-six months in fundamental research areas. Analyzing recent scientific literature alongside the patent landscape reveals which emerging research directions are moving toward commercialization and IP protection — giving R&D teams intelligence about where the competitive environment is heading rather than only where it currently stands.
How do you identify white space in a patent landscape?White space identification requires distinguishing between technology areas that are genuinely underdeveloped versus areas that appear uncrowded because they have been tried and abandoned, or because the commercial application is not yet understood. The most useful approach combines patent activity analysis (low filing density, declining activity from major players) with scientific literature signals (active publication and growing academic interest) — areas that are publication-active but patent-quiet often represent genuine near-term opportunity.
Citations:[1] WIPO IP Statistics Data Center. World Intellectual Property Organization. wipo.int.[2] Cypris R&D intelligence platform. cypris.com.[3] Cypris API partnerships. cypris.com.[4] Cypris security and compliance. cypris.com.

AI Tools for Scientific Literature Review: A Guide for Enterprise R&D Teams
The growing demand for AI-assisted scientific literature review has produced two very different categories of tools — and most R&D teams are using the wrong one.
Academic literature review tools are designed for PhD students writing dissertations and professors synthesizing research for journal publications. Enterprise R&D teams face a fundamentally different job: they need to understand scientific developments in the context of patent landscapes, competitor activity, funding movements, and technology readiness levels — all at once, at scale, and fast enough to inform actual business decisions. This guide explains how AI tools for scientific literature review work, reviews the leading academic platforms, and explores what enterprise R&D teams actually need from an R&D intelligence solution.
What AI Tools for Scientific Literature Review Actually Do
AI-powered literature review tools apply natural language processing and machine learning to academic databases, enabling researchers to identify relevant papers, extract key findings, map citation networks, and synthesize evidence without manually reading thousands of documents.
The core capabilities typically include semantic search (finding papers by concept rather than exact keyword match), automated summarization of abstracts and full texts, citation analysis to surface influential works and track how findings have been built upon or contradicted, and research gap identification to surface understudied areas within a field.
Most platforms index research from sources like PubMed, arXiv, Semantic Scholar, and institutional repositories. The better ones cover hundreds of millions of papers across life sciences, chemistry, materials science, engineering, and computer science. Retrieval quality depends heavily on the underlying indexing methodology — whether the platform performs surface-level keyword matching or applies genuine semantic understanding of scientific concepts.
For academic researchers, these capabilities are genuinely transformative. A graduate student conducting a systematic review that once required weeks of manual database searching can now surface a comprehensive corpus in hours. For enterprise R&D teams, however, this represents only a fraction of the intelligence picture.
The Leading Academic AI Literature Review Tools
Understanding the existing landscape helps clarify where the real capability gaps are for enterprise users.
Semantic Scholar, developed by the Allen Institute for AI, indexes over 200 million papers and provides AI-generated TLDR summaries, citation analysis distinguishing highly influential citations from background references, and personalized research feeds [2]. Its open-access model and broad coverage make it a standard starting point for academic research.
Consensus focuses on extracting direct answers from peer-reviewed research, surfacing a "Consensus Meter" that aggregates scientific agreement or disagreement on specific questions [4]. It is oriented toward evidence-based writing and quickly identifying where scientific confidence exists on a given topic.
ResearchRabbit takes a visual approach, mapping citation networks and relationships between papers, authors, and research trajectories. Starting from a seed set of papers, researchers can expand outward to discover related works and trace academic lineages [5]. Its visual maps integrate with reference management tools like Zotero.
Each of these platforms excels within its intended use case. The shared limitation is that they treat scientific literature as the complete universe of relevant information — which works fine for academic research but fails enterprise R&D teams almost immediately.
Why Enterprise R&D Teams Need More Than Literature Review
The fundamental challenge for corporate R&D is that scientific literature is one input among many, not the entire picture. When a materials science team at a Fortune 500 manufacturer evaluates a new polymer chemistry, they need to understand the academic research — but they also need to know who holds relevant patents, what competitors have filed in the last 18 months, which startups are working in adjacent spaces, what academic institutions are publishing most actively and potentially seeking industry partners, and where the technology sits on the commercialization timeline.
None of the academic literature review tools answer those questions. They are designed around a workflow — the systematic academic review — that doesn't map to how enterprise R&D strategy actually functions.
Enterprise R&D intelligence requires integrating scientific literature with patent data, competitive filing activity, funding signals, and market indicators into a unified analytical framework. When these data streams live in separate tools, R&D teams spend enormous effort on manual synthesis rather than on the strategic analysis that actually creates value. Research reports get siloed, insights don't compound across projects, and the organization ends up recreating foundational landscape analyses from scratch each time a new initiative launches.
This is the core problem that purpose-built enterprise R&D intelligence platforms are designed to solve.
What Enterprise R&D Intelligence Platforms Offer That Academic Tools Cannot
The distinction between an academic literature review tool and an enterprise R&D intelligence platform is not merely a matter of scale — it is a fundamentally different product category with different architecture, data coverage, and analytical philosophy.
Enterprise platforms are built around the principle of unified intelligence: the ability to query across patents, scientific papers, technical standards, competitive activity, and market data simultaneously, using a common ontological framework that understands how concepts relate to one another across these different document types.
Cypris represents this category of platform. Where academic tools index scientific papers, Cypris covers more than 500 million patents and scientific papers through a single interface, applying a proprietary R&D ontology that enables semantic understanding across the full corpus [6]. An R&D team searching for developments in solid electrolyte materials, for example, retrieves both the latest academic publications and the patent filings that translate that research into protected intellectual property — with the semantic intelligence to recognize that "solid electrolyte" and "ceramic separator" may refer to overlapping technology spaces depending on context.
This matters because the patent literature and the academic literature do not perfectly overlap. Many commercially significant technical advances appear in patent filings before, or instead of, academic publications. An enterprise R&D team conducting competitive intelligence based only on academic literature is missing a substantial portion of the relevant technical signal.
Multimodal search capabilities allow enterprise teams to query using technical documents, chemical structures, patent claims, or natural language descriptions — not just keyword strings. This removes the expert knowledge barrier that makes academic database searching dependent on knowing exactly the right controlled vocabulary. A business development professional who needs to understand the IP landscape around a potential acquisition target can get meaningful results without deep prior knowledge of the field's terminology.
Data provenance and security matter in ways that are irrelevant to academic researchers but critical for enterprise deployment. R&D intelligence platforms handling competitive information must meet enterprise security standards. SOC 2 Type II certification, US-based operations, and audit-ready compliance frameworks are baseline requirements for Fortune 500 procurement. Academic tools are rarely built to these specifications.
Integration with existing enterprise workflows is another dimension where purpose-built platforms differ from academic tools. API partnerships with major AI providers — including official integrations with OpenAI, Anthropic, and Google — allow enterprise R&D intelligence to be embedded into existing research workflows, internal knowledge management systems, and custom AI applications rather than existing as a standalone tool that requires context-switching [7].
The Compounding Knowledge Problem
One of the most underappreciated challenges in enterprise R&D is institutional knowledge accumulation. Each time a team launches a new project in a technology area the organization has investigated before, they have a choice: invest days rebuilding a landscape analysis from scratch, or rely on someone's imperfect memory of what was learned previously.
Most organizations do a version of both, which means neither institutional knowledge nor fresh research is done well. Prior analyses are rediscovered when the original researcher mentions them, or not discovered at all when key people have moved on.
Enterprise R&D intelligence platforms address this at the architecture level by building organizational knowledge layers on top of the underlying data infrastructure. Research conducted on one project becomes available to teams working on adjacent problems. Competitive monitoring runs continuously rather than in project-specific bursts. The organization compounds its understanding of a technology domain over time rather than starting from scratch on each initiative.
Academic literature review tools are designed for single-project workflows. They help an individual researcher get up to speed on a literature base. They are not designed to serve as persistent organizational intelligence infrastructure — and repurposing them for that role creates more complexity than it resolves.
Selecting the Right Tool for Your Organization's Needs
The right framework for evaluating AI tools in this space starts with an honest assessment of who is doing the work and what decisions they need to make.
For academic researchers, students, and faculty conducting systematic reviews, evidence synthesis, or dissertation research, the academic-focused platforms covered earlier represent genuinely good options. Elicit, Semantic Scholar, Consensus, and Scite each serve specific methodological needs well and are designed around the workflows academic researchers actually use.
For enterprise R&D teams — whether in chemicals, advanced materials, pharmaceuticals, automotive, aerospace, energy, or any other innovation-intensive industry — the relevant evaluation criteria are different. Coverage must span both scientific literature and patent data. Search must be semantically sophisticated enough to navigate technical concept spaces without requiring controlled vocabulary expertise. Security and compliance architecture must meet enterprise requirements. And the platform must be designed to serve as ongoing organizational infrastructure, not just a one-time research assistant.
Organizations evaluating enterprise R&D intelligence platforms should pressure-test vendors on several specific capabilities: the depth and currency of their patent and scientific literature indexing, the quality of their semantic search versus basic keyword matching, their data provenance and update frequency, their compliance certifications, their API and integration ecosystem, and evidence that the platform has been deployed successfully in their specific industry vertical.
The distinction matters because implementing the wrong category of tool — using an academic literature tool in place of an enterprise R&D intelligence platform — creates a capability ceiling that limits the organization's ability to make fast, well-grounded strategic decisions about technology development and competitive positioning.
Frequently Asked Questions
What is the best AI tool for scientific literature review?The best AI tool depends on the use case. For academic researchers and students, Elicit, Semantic Scholar, Consensus, and Scite are strong options with different strengths across systematic review, citation analysis, and evidence synthesis. For enterprise R&D teams at large organizations, purpose-built R&D intelligence platforms like Cypris provide significantly more comprehensive coverage by integrating scientific literature with patent data, competitive intelligence, and market signals — which is what corporate R&D decisions actually require.
How do AI literature review tools work?AI literature review tools apply natural language processing to large databases of academic papers. They enable semantic search (finding papers by concept rather than exact keyword), automated summarization, citation network analysis, and research gap identification. The most sophisticated platforms use proprietary ontologies to understand how scientific and technical concepts relate to one another across millions of documents, enabling more precise retrieval than keyword-based approaches.
Can AI tools replace human researchers for literature reviews?AI tools significantly accelerate the literature discovery and initial synthesis phases of research, but human judgment remains essential for evaluating source quality, assessing methodological rigor, synthesizing insights across domains, and drawing strategic conclusions. The most effective approach uses AI platforms to handle the computational work of searching, filtering, and summarizing at scale, freeing researchers to focus on the analytical and strategic work that creates actual value.
What is the difference between an academic literature review tool and an enterprise R&D intelligence platform?Academic literature review tools are designed for individual researchers conducting project-specific systematic reviews, primarily of scientific papers. Enterprise R&D intelligence platforms integrate scientific literature with patent data, competitive filing activity, funding signals, and market intelligence into a unified interface, serve as ongoing organizational infrastructure rather than one-time research tools, and are built to meet enterprise security and compliance requirements. They address fundamentally different workflows and organizational needs.
How many scientific papers do leading AI literature review tools index?Coverage varies significantly. Semantic Scholar indexes over 200 million papers [2]. Elicit draws on a comparable corpus through integration with academic databases. Enterprise platforms like Cypris cover over 500 million patents and scientific papers combined, with the advantage of integrated cross-domain search across both literature types simultaneously [6].
What should enterprise R&D teams look for in an AI literature review tool?Enterprise R&D teams should evaluate platforms on patent and scientific literature coverage depth, semantic search quality versus keyword matching, data currency and update frequency, security certifications (SOC 2 Type II is a baseline requirement for enterprise deployment), API and integration ecosystem, and evidence of successful deployment in relevant industry verticals. Academic-focused tools rarely meet these criteria because they are designed for different user needs and organizational contexts.
Is scientific literature review AI accurate?Accuracy varies by platform and task. Modern AI literature review tools are reliable for paper discovery and summarization, though all platforms carry some risk of missing relevant papers or generating imprecise summaries. Citation hallucination — AI systems inventing references that do not exist — has been a documented problem with general-purpose language models used for research. Purpose-built platforms with structured database backends rather than generative retrieval are generally more reliable for citation accuracy. Enterprise platforms add additional verification layers because the cost of inaccurate competitive intelligence is higher than the cost of an imprecise academic summary.
Citations:
[1] Elicit platform documentation. elicit.com.[2] Semantic Scholar. Allen Institute for AI. semanticscholar.org.[3] Scite platform overview. scite.ai.[4] Consensus AI research tool. consensus.app.[5] ResearchRabbit platform. researchrabbitapp.com.[6] Cypris R&D intelligence platform. cypris.com.[7] Cypris API partnerships documentation. cypris.com.

Questel Alternatives: 7 Tools for Patent & Research Intelligence
Questel has built a formidable reputation in the intellectual property world, and its flagship platform Orbit Intelligence is trusted by more than 100,000 users worldwide for patent search, analytics, and IP portfolio management. But Questel was designed first and foremost for deep legal IP workflows, and that heritage comes with tradeoffs that increasingly frustrate modern R&D teams. Whether you are struggling with Orbit's steep learning curve, need broader data coverage beyond patents and trademarks, or simply want a platform your entire innovation team can use without weeks of training, this guide examines the top alternatives reshaping the patent and research intelligence landscape in 2026.
Why R&D Teams Are Looking Beyond Questel
Questel Orbit Intelligence is a powerful tool in the hands of experienced patent attorneys and IP specialists. The platform offers sophisticated Boolean syntax, advanced proximity operators, and granular legal status tracking that few competitors can match. However, several factors are driving R&D and innovation teams to explore alternatives.
Complexity designed for legal specialists. Questel's interface is built around Boolean command-line searches with complex operator syntax. Even Questel's own documentation acknowledges that queries are frequently flagged as "too complex" by the system, and the company offers paid one- and two-day training sessions just to become proficient. For R&D scientists, product managers, and innovation strategists who need quick answers rather than litigation-grade search strings, this complexity creates unnecessary friction. Questel has attempted to address this with Orbit Express, a simplified interface explicitly designed for users who are "not a patent expert," but this creates a fragmented experience with reduced functionality rather than solving the underlying usability problem.
Narrow IP and legal focus. Questel's product suite is oriented around the full IP lifecycle, spanning patent prosecution, trademark management, renewal services, and legal docketing. While this end-to-end IP management approach serves law firms and corporate IP departments well, it means the platform treats patent data primarily through a legal lens rather than as one component of a broader innovation intelligence strategy. R&D teams that need to connect patent landscapes with scientific literature trends, market signals, and competitive intelligence often find themselves needing to supplement Questel with additional tools.
Fragmented product ecosystem. Questel's capabilities are distributed across multiple distinct products including Orbit Intelligence for patent search, Orbit Insight for innovation intelligence, Equinox for IP management, and various add-on modules for biosequence search, chemical structures, and non-patent literature. Each product has its own interface, learning curve, and often separate pricing. This modular approach means organizations frequently end up managing multiple subscriptions and training programs to achieve the integrated intelligence view that modern R&D demands.
Limited AI integration for enterprise workflows. While Questel has introduced its Sophia AI assistant for query building and document analysis, the platform lacks the deep enterprise LLM partnerships that enable organizations to build custom AI workflows on top of their R&D data. As AI transforms how innovation teams discover, analyze, and act on technical intelligence, platforms without native integration into the broader enterprise AI ecosystem risk becoming isolated tools rather than foundational infrastructure.
Top 7 Questel Alternatives for 2026
1. Cypris: Enterprise R&D Intelligence Platform
Best for: Large enterprise R&D teams needing comprehensive intelligence beyond patents
Cypris has emerged as the leading alternative to Questel for organizations that need R&D intelligence to serve innovation strategy rather than legal case management. Where Questel routes everything through an IP attorney's workflow, Cypris is purpose-built for R&D scientists, product managers, and innovation leaders who need to move from question to insight without mastering Boolean syntax or navigating fragmented product modules.
Key Advantages Over Questel:
Over 500 million data points spanning patents, scientific literature, grants, and market intelligence in a single unified platform rather than across separate products
Official enterprise API partnerships with OpenAI, Anthropic, and Google, enabling custom AI workflows that Questel's Sophia assistant cannot replicate
Natural language AI interface through Cypris Q that eliminates the need for complex Boolean query construction and multi-day training programs
Research Brief analyst service providing bespoke, expert-curated reports that combine AI capabilities with human expertise
AI-powered monitoring that continuously tracks developments across all data sources and automatically surfaces relevant insights
Advanced R&D ontology that understands technical relationships across disciplines, connecting insights that keyword-based searches miss
US-based operations and data handling for organizations with data sovereignty requirements
Unique Differentiators: The fundamental difference between Cypris and Questel lies in who the platform was designed to serve. Questel's architecture assumes the user is an IP professional conducting legal searches. Cypris assumes the user is an R&D leader trying to make better innovation decisions. This design philosophy manifests in everything from the natural language search interface to the way results are organized around strategic insight rather than legal status codes. The Research Brief service further extends this advantage by providing expert analyst support for complex research questions, delivering custom reports that no self-service tool can match.
Why Teams Switch from Questel: Organizations report that Cypris eliminates the need for multiple Questel modules and supplementary tools while dramatically reducing the time from question to actionable insight. Teams that previously needed weeks of training and dedicated IP search specialists can now empower their entire R&D organization to access intelligence independently, compounding organizational knowledge with every interaction rather than keeping it locked in specialist workflows.
2. Derwent Innovation (Clarivate)
Best for: Global enterprises needing validated, human-curated patent data
Derwent Innovation builds on Clarivate's renowned Derwent World Patents Index with human-enhanced patent abstracts and standardized data that has been the gold standard for patent research for decades. Like Questel, Derwent is designed primarily for IP professionals, but its curated data quality and deep citation analysis offer advantages for organizations where data accuracy is paramount.
Strengths:
Manually curated patent abstracts through DWPI provide consistently high data quality that automated systems cannot match
Comprehensive global coverage with standardized non-English patent translations
Deep integration with Clarivate's broader scientific and IP ecosystem including Web of Science
Advanced citation analysis and patent family mapping
Strong reputation and trust among corporate IP departments worldwide
Limitations:
Similarly complex interface to Questel, requiring significant training investment
Focus remains on patents without comprehensive integration of market intelligence or internal R&D knowledge
No bespoke research services or analyst support for custom questions
Pricing can be prohibitive for organizations that need broad team access rather than specialist-only licenses
3. Google Patents
Best for: Quick, free patent searches and basic prior art research
Google Patents provides free access to patents from over 100 patent offices worldwide, making it the natural starting point for preliminary searches and basic patent research. For R&D team members who need to quickly validate an idea or check whether a concept has prior art, Google Patents offers the lowest possible barrier to entry.
Strengths:
Completely free access with no training required
Simple, familiar Google search interface that any team member can use immediately
Quick access to full patent documents with integrated Google Scholar linking
Prior art search functionality powered by Google's search algorithms
Machine translation for non-English patents
Limitations:
No advanced analytics, visualization, or landscaping tools
Limited search capabilities compared to any commercial platform
No API or enterprise integration options
Lacks any security certifications for enterprise use
No alert, monitoring, or collaboration features
Missing critical professional features like family analysis, legal status tracking, and citation mapping
4. The Lens
Best for: Academic institutions and budget-conscious R&D teams
The Lens provides free and open access to an integrated patent and scholarly literature database, making it uniquely valuable for organizations that need to bridge the gap between patent intelligence and scientific research. Its nonprofit mission and transparent approach to data have earned it a loyal following in academic and public-sector research communities.
Strengths:
Free tier with substantial functionality including both patent and scholarly data
Integration of patent and scientific literature in a single searchable database
Open data approach with transparent metrics and methodology
PatCite linking that connects patents to the scientific literature they cite
Academic-friendly licensing and institutional access options
Limitations:
Limited advanced analytics compared to commercial platforms like Questel or Cypris
No enterprise knowledge management or internal R&D data integration
Basic interface without sophisticated AI enhancements
No security certifications suitable for enterprise use
Limited customer support and training resources
5. PatSeer
Best for: Patent research teams wanting AI-enhanced search with collaborative workflows
PatSeer has built a reputation as one of the more comprehensive and customizable patent research platforms available, combining traditional Boolean search with AI-driven semantic capabilities. Its hybrid approach appeals to teams that want modern AI features without completely abandoning the structured search workflows they already know.
Strengths:
Hybrid search combining Boolean and AI-powered semantic search in a single platform
AI Classifier, Recommender, and Re-Ranker that help organize and prioritize results
Strong collaboration features with shared projects, annotations, and multi-user dashboards
Coverage of 170 million or more global patent publications across 108 countries
Integrated non-patent literature search from within the same interface
Customizable taxonomy that adapts to organizational domain expertise
Limitations:
Primarily patent-focused without broader market intelligence or R&D data integration
Interface complexity increases significantly when using advanced features
No enterprise LLM partnerships or API integrations for custom AI workflows
Limited enterprise security certifications compared to platforms like Cypris
Smaller market presence means less extensive training and support ecosystem
6. LexisNexis TotalPatent One
Best for: Legal teams needing patent search integrated with broader legal research
LexisNexis TotalPatent One leverages the LexisNexis ecosystem to provide patent search and analytics alongside the company's extensive legal research databases. For organizations where the patent intelligence function sits within the legal department and needs to connect seamlessly with case law, regulatory, and litigation research, TotalPatent One offers a compelling integrated experience.
Strengths:
Integration with the broader LexisNexis legal research ecosystem
Global patent coverage with full-text search across major jurisdictions
Annotation and bulk analysis tools designed for legal review workflows
Strong reputation and established relationships with corporate legal departments
Limitations:
Designed primarily for legal professionals rather than R&D or innovation teams
Interface and workflows assume legal training and IP specialization
Limited analytics and visualization compared to dedicated patent intelligence platforms
No scientific literature integration, market intelligence, or R&D knowledge management
Does not address the core need of R&D teams to connect patent data with broader innovation strategy
7. Espacenet (European Patent Office)
Best for: Free access to global patent documents with strong European coverage
Espacenet, maintained by the European Patent Office, provides free access to over 150 million patent documents from around the world. As an official patent office tool, it offers authoritative data and serves as an essential complement to any commercial platform, particularly for verifying European patent family data and legal status information.
Strengths:
Completely free with no registration required
Authoritative data directly from the European Patent Office
Coverage of over 150 million patent documents worldwide
Machine translation for patent documents in multiple languages
Smart search functionality for basic semantic queries
CPC classification browser for structured technology exploration
Limitations:
No analytics, visualization, or landscaping capabilities
Basic search interface without AI enhancements
No collaboration, monitoring, or alert features
Cannot support enterprise R&D intelligence workflows
No API access or integration options for enterprise systems
Critical Security Considerations
Enterprise Security Compliance
Security certification has become a decisive factor in enterprise platform selection, particularly for organizations handling sensitive R&D data, trade secrets, and pre-patent invention disclosures. The distinction between ISO 27001 and SOC 2 Type II matters more than many procurement teams initially realize.
Questel holds ISO 27001 certification, which demonstrates that the company has established an information security management system meeting international standards. This certification is widely recognized globally and represents a meaningful commitment to security. However, for US-based enterprises, ISO 27001 alone often falls short of procurement requirements.
Cypris maintains SOC 2 Type II certification, which provides a fundamentally different type of assurance. Where ISO 27001 certifies that a security management system exists and meets defined standards, SOC 2 Type II verifies that specific security controls have been operating effectively over an extended period through independent auditor testing. For US enterprise IT security teams evaluating R&D intelligence platforms, SOC 2 Type II is typically a non-negotiable requirement because it provides evidence of continuous operational security rather than point-in-time system design.
Organizations evaluating Questel alternatives should verify that their chosen platform meets the specific security standards their procurement process requires, as switching platforms after a security review failure creates significant cost and timeline delays.
The Power of AI Partnerships and Ontology
Enterprise LLM Integration
The way R&D teams interact with patent and technical intelligence is being fundamentally transformed by large language models. Platforms that have established official enterprise partnerships with leading AI providers offer capabilities that bolt-on AI features cannot replicate.
Cypris's official API partnerships with OpenAI, Anthropic, and Google enable enterprise customers to build compliant, secure AI applications on top of their R&D data. This means organizations can integrate patent intelligence, scientific literature analysis, and competitive monitoring directly into their existing AI infrastructure rather than treating it as an isolated search tool. These partnerships also ensure that AI implementations meet enterprise compliance requirements, unlike consumer-grade AI features that may not satisfy data handling policies.
Questel's Sophia AI assistant provides helpful features like query building and document summarization, but it operates as a proprietary feature within Questel's closed ecosystem rather than as an integration point for broader enterprise AI strategy. As organizations invest in AI infrastructure that spans multiple business functions, the ability to connect R&D intelligence with enterprise AI platforms becomes a significant competitive advantage.
Advanced R&D Ontology
Beyond raw AI capability, the quality of intelligence depends on how well a platform understands the relationships between technical concepts across disciplines. Cypris employs a proprietary R&D ontology built specifically for innovation intelligence that understands how concepts in materials science connect to chemical engineering processes, how pharmaceutical mechanisms relate to biotechnology methods, and how manufacturing innovations in one industry apply to adjacent fields.
This ontological approach produces fundamentally different results than Questel's keyword and classification-code methodology. Where traditional patent search requires users to anticipate exactly which terms and codes are relevant, an ontology-driven platform discovers connections that keyword searches miss entirely, surfacing the cross-disciplinary insights that drive breakthrough innovation.
Choosing the Right Questel Alternative
For Comprehensive R&D Intelligence
If your team needs a platform that serves the entire innovation organization rather than just the IP department, Cypris offers the most complete solution. Its unified approach to patents, scientific literature, market intelligence, and internal knowledge management eliminates the fragmented multi-product experience that characterizes Questel while dramatically reducing the training burden on non-specialist users. The combination of SOC 2 Type II security, enterprise LLM partnerships, and the Research Brief analyst service makes it the strongest choice for Fortune 500 R&D teams.
For Specialized Needs
Basic patent searches: Google Patents and Espacenet provide free, immediate access for preliminary research
Academic research: The Lens offers excellent free access with integrated patent and scholarly data
Standards-driven industries: IPlytics provides unique standard essential patent intelligence
Legal department workflows: LexisNexis TotalPatent One integrates with broader legal research tools
Human-curated data quality: Derwent Innovation offers gold-standard manually enhanced patent abstracts
AI-enhanced patent research: PatSeer provides hybrid Boolean and semantic search with strong collaboration tools
For Modern AI Workflows
Organizations building enterprise AI infrastructure should prioritize platforms that offer native LLM integration, advanced ontologies, and official partnerships with major AI providers. Traditional IP tools like Questel were designed for a world where patent intelligence meant constructing Boolean searches and reviewing result lists. The future of R&D intelligence is conversational, proactive, and deeply integrated with the AI systems that power modern enterprise decision-making.
Making the Transition from Questel
Key Evaluation Criteria
When evaluating Questel alternatives, R&D and innovation leaders should assess candidates across several dimensions that reflect how modern teams actually use intelligence platforms. Security compliance should be verified against your organization's specific requirements, with particular attention to whether SOC 2 Type II is needed for US enterprise procurement. Data coverage should extend beyond patents to include scientific literature, grants, market intelligence, and the ability to integrate internal R&D knowledge. AI capabilities should be evaluated not just as features within the platform but as integration points with your broader enterprise AI strategy. Usability should be tested with actual R&D team members rather than just IP specialists, since the goal is to democratize intelligence access across the innovation organization. Finally, consider whether the platform offers analyst services for complex questions that require human expertise beyond what any self-service tool can provide.
Implementation Best Practices
Organizations transitioning from Questel should run parallel systems during an initial evaluation period to validate that the alternative meets their needs across all use cases. Starting with a pilot team, ideally one that includes both IP specialists and R&D generalists, helps identify any capability gaps before a full rollout. Teams should leverage the transition as an opportunity to establish new AI-powered workflows rather than simply replicating existing search patterns, since the value of modern platforms comes from enabling fundamentally different ways of working with intelligence data.
The Future of Patent and Research Intelligence
The patent intelligence landscape is undergoing its most significant transformation in decades. The traditional model where specialized IP professionals constructed complex Boolean queries in expert-only tools is giving way to a new paradigm where AI-powered platforms make R&D intelligence accessible to everyone in the innovation organization.
Questel's deep expertise in IP legal workflows will continue to serve patent attorneys and prosecution specialists well. But for R&D leaders, product managers, and innovation strategists who need intelligence to drive strategic decisions rather than legal filings, the future belongs to platforms that combine comprehensive data coverage with intuitive AI interfaces, enterprise security compliance, and seamless integration into the broader technology ecosystem.
The organizations that will lead in innovation are those that treat R&D intelligence not as a specialized legal function but as foundational infrastructure that compounds knowledge across every team, every project, and every strategic decision. Choosing the right platform today is choosing the foundation that will either accelerate or constrain your innovation capability for years to come.
Conclusion: From Legal Search Tool to Innovation Intelligence
Questel Orbit Intelligence remains one of the most capable patent search and analytics tools available for experienced IP professionals. Its deep Boolean syntax, comprehensive legal status tracking, and end-to-end IP management capabilities serve the needs of patent attorneys and IP departments effectively. But the demands of modern enterprise R&D extend far beyond what any legal-first platform was designed to deliver.
The most successful R&D organizations are moving toward platforms that unify patents, scientific literature, market intelligence, and internal knowledge into a single AI-powered intelligence layer accessible to their entire innovation team. By choosing alternatives that prioritize usability alongside power, comprehensive data alongside patent depth, and enterprise AI integration alongside standalone features, teams can transform R&D intelligence from a specialist bottleneck into a strategic accelerant.
Ready to explore Questel alternatives? Start by mapping how many people across your R&D organization actually need intelligence access versus how many currently have it. The gap between those numbers represents untapped innovation potential that the right platform can unlock. Prioritize solutions that offer enterprise security compliance, modern AI capabilities, and comprehensive data coverage, and your team will be positioned to compound knowledge faster than competitors who remain locked into specialist-only search tools.
How R&D Departments Can Improve Knowledge Sharing: Building a Collective AI Memory That Compounds Over Time
Knowledge sharing in R&D departments is the practice of systematically capturing, organizing, and distributing institutional expertise and external innovation intelligence so that every researcher can build on the collective knowledge of the organization rather than working in isolation. For decades, the standard approach to this challenge has centered on cultural interventions: encouraging researchers to document their work, hosting cross-functional meetings, building wikis, and creating incentive structures that reward collaboration over individual contribution. These efforts matter, but they share a fundamental limitation. They depend on individual humans choosing to contribute knowledge, remembering to do so at the right moment, and articulating tacit expertise in formats that other humans can later find and interpret. The result is that most organizational knowledge still depreciates rather than compounds. Projects end and their insights scatter across email threads, slide decks, and personal notebooks. Researchers leave and their hard-won intuitions leave with them. Teams in one division solve a problem that a team in another division will spend six months re-solving because no searchable record of the first solution exists in any system anyone thinks to check.
The emerging alternative is fundamentally different. Instead of asking humans to serve as the primary mechanism for knowledge capture and transfer, forward-thinking R&D organizations are building collective AI memory systems that automatically accumulate intelligence from every research activity, every patent search, every literature review, and every competitive analysis into a shared, searchable, AI-accessible layer that grows more valuable with every interaction. This approach treats organizational knowledge not as a static archive to be maintained but as a compounding asset that appreciates over time, where each new query builds on every previous query and each new insight connects automatically to the full constellation of what the organization already knows.
The stakes for getting this right are enormous. According to the International Data Corporation, Fortune 500 companies collectively lose roughly $31.5 billion annually by failing to share knowledge effectively. The Panopto Workplace Knowledge and Productivity Report found that the average large U.S. business loses $47 million in productivity each year due to inefficient knowledge sharing, with employees wasting 5.3 hours every week either waiting for information from colleagues or recreating institutional knowledge that already exists somewhere in the organization. R&D professionals spend approximately 35 percent of their time searching for and validating information rather than conducting actual research. For a department of 100 researchers with an average fully loaded cost of $150,000 per year, that translates to roughly $5.25 million annually spent on information discovery alone, representing 70,000 hours of productivity that could otherwise be directed toward actual innovation.
Why Traditional Knowledge Sharing Approaches Hit a Ceiling in R&D
The conventional playbook for improving knowledge sharing in R&D departments includes familiar elements: establish communities of practice, create centralized document repositories, reward knowledge contribution in performance reviews, implement regular cross-team briefings, and invest in collaboration platforms like Slack or Microsoft Teams. Each of these strategies has merit, and none should be abandoned. But they all share a common dependency on individual human effort as the bottleneck through which all organizational knowledge must pass.
Consider what happens when a senior materials scientist conducts a thorough landscape analysis of biodegradable polymer patents before launching a new formulation project. Under traditional knowledge sharing models, capturing that intelligence for the broader organization requires the scientist to write a summary document, tag it with appropriate metadata, store it in the right repository, notify relevant colleagues, and present key findings at a team meeting. Each of these steps competes with the scientist's primary responsibility of actually conducting research. In practice, most of that contextual knowledge, including which patent families look most threatening, which technical approaches appear to be dead ends, and which white spaces suggest opportunity, never makes it into any system that a colleague starting a similar project eighteen months later would think to consult.
The problem intensifies with scale. A midsized enterprise R&D department might conduct hundreds of patent searches, review thousands of scientific papers, and generate dozens of competitive intelligence assessments in a single quarter. The volume of potentially reusable insight produced by these activities vastly exceeds what any documentation protocol can capture, regardless of how disciplined the team is about following it. Tribal knowledge, the undocumented expertise that exists only in the minds of experienced researchers, compounds this challenge further. According to Panopto's research, 42 percent of institutional knowledge is unique to the individual employee. When that employee retires, transfers, or leaves the company, nearly half of what they contributed to the organization's capability disappears with them.
The manufacturing, chemicals, and automotive sectors face this knowledge attrition with particular urgency. Some companies expect to lose 30 percent or more of their most experienced engineers to retirement within the next five years. The specialized knowledge those engineers carry about decades of process optimization, material behavior under unusual conditions, and regulatory navigation cannot be reconstructed from project files alone. It lives in the connections between disparate observations, the pattern recognition built through years of experimentation, and the contextual judgment about which published results are reliable and which should be viewed skeptically. No wiki or shared drive captures that kind of intelligence.
The Compounding Knowledge Model: How AI Memory Changes the Equation
The concept of collective AI memory reframes knowledge sharing from a documentation challenge into an infrastructure investment with compounding returns. Rather than relying on researchers to manually extract, format, and distribute insights, a compounding knowledge system captures intelligence as a natural byproduct of the research activities teams are already performing. Every patent search enriches the organizational understanding of the competitive landscape. Every literature review adds to the collective map of scientific frontiers. Every competitive analysis sharpens the picture of where market opportunities and threats are emerging. Critically, this captured intelligence is not simply stored; it is connected, contextualized, and made available to AI systems that can synthesize it with new queries in real time.
The compounding effect is what distinguishes this approach from earlier generations of knowledge management technology. Traditional knowledge bases are additive: each new document increases the total volume of stored information, but the documents themselves do not interact or build on each other. A compounding AI memory is multiplicative: each new piece of intelligence enhances the value of everything already in the system by creating new connections, surfacing non-obvious relationships, and enabling the AI to provide progressively richer, more contextualized responses over time. When the hundredth researcher queries the system about a technical domain, they benefit not only from whatever external data the platform accesses but from the accumulated context of the ninety-nine previous investigations their colleagues have conducted.
This is the architectural principle behind platforms designed specifically for enterprise R&D intelligence. Cypris, for example, integrates access to more than 500 million patents and scientific papers with an AI research agent called Cypris Q that retains context from previous queries and builds organizational knowledge over successive interactions. When a researcher uses Cypris Q to investigate a new technology domain, the system draws on the full breadth of global patent and scientific literature while simultaneously incorporating the accumulated research history specific to that organization. The result is not just a search engine that returns documents but an intelligence layer that understands what the organization has already explored, where its strategic interests lie, and how new discoveries connect to ongoing priorities.
This architecture solves several problems that traditional knowledge sharing approaches cannot address. First, it eliminates the documentation burden by capturing intelligence as a natural consequence of research activity rather than requiring a separate effort. Researchers do not need to write summaries or tag documents because the AI system learns from the interactions themselves. Second, it makes tacit knowledge partially transferable by encoding the patterns and connections that experienced researchers discover into a system that any team member can access. While no technology can fully replicate a veteran scientist's intuition, a system that remembers every question that scientist has asked and every connection they have drawn captures far more contextual intelligence than any written document could. Third, it bridges organizational silos by making knowledge from one team's investigation instantly available to every other team in the organization. When a coatings R&D group discovers a relevant patent cluster during their research, that discovery automatically enriches the intelligence available to the adhesives team working on a related material class, even if neither team knows the other exists.
Building the Foundation: What a Compounding R&D Knowledge System Requires
Constructing an AI memory that actually compounds organizational intelligence over time requires several foundational elements working together. The first and most critical is comprehensive data integration. An R&D knowledge system that draws from only one category of external intelligence, whether patents alone, scientific papers alone, or market data alone, will produce a fragmented and misleading picture of the innovation landscape. Researchers make decisions at the intersection of technical feasibility, competitive positioning, regulatory constraints, and market opportunity. The intelligence system that informs those decisions must span all of these dimensions to provide genuinely useful synthesis.
Enterprise R&D intelligence platforms distinguish themselves from academic search tools and patent attorney databases precisely through this breadth of integration. Where a patent search tool might surface relevant prior art and a literature database might identify relevant publications, an integrated platform connects patent filings with the scientific papers that inform them, links competitive patent activity to market intelligence about commercial intent, and situates all of this within the context of regulatory developments that could accelerate or constrain specific technology paths. This interconnection is what enables the AI to generate compounding insights rather than isolated search results.
The second foundational requirement is an R&D-specific ontology, a structured knowledge framework that understands the relationships between technical concepts, material categories, application domains, and innovation trajectories in the way that researchers themselves think about them. General-purpose AI systems lack this domain specificity, which means they cannot reliably connect a query about "barrier coatings for flexible packaging" with relevant patents filed under "oxygen transmission rate reduction in polymer films" or scientific papers discussing "nanocomposite permeation resistance." A purpose-built R&D ontology enables the kind of lateral connection that distinguishes transformative research from incremental investigation, and it ensures that the compounding knowledge base grows along dimensions that reflect genuine technical relationships rather than superficial keyword overlaps.
The third requirement is enterprise-grade security and access governance. R&D knowledge is among the most strategically sensitive information any organization possesses. The insights that accumulate in a collective AI memory, including which technology domains the organization is investigating, which competitive threats it has identified, and which innovation opportunities it is pursuing, would be extraordinarily valuable to competitors. Any platform entrusted with this intelligence must meet the most rigorous security standards. SOC 2 Type II certification, data encryption at rest and in transit, role-based access controls, and clear data sovereignty guarantees are minimum requirements, not differentiators. Organizations should also evaluate whether the platform provider is based in a jurisdiction with strong intellectual property protections and whether it maintains official API partnerships with the AI providers it integrates, ensuring that organizational data is handled according to enterprise security standards at every layer of the technology stack.
Cypris helps enterprise R&D teams build a compounding knowledge advantage by unifying access to over 500 million patents, scientific papers, and competitive intelligence sources through a single AI-powered platform. Book a demo to see how organizations are turning every research interaction into lasting institutional intelligence at cypris.ai.
From Documentation Culture to Contribution Culture
Adopting a compounding AI memory system does not eliminate the need for cultural investment in knowledge sharing. It changes the nature of that investment. Under traditional knowledge management, the cultural challenge is motivating researchers to perform an additional task (documentation) on top of their primary work. Under a compounding model, the cultural challenge shifts to something more achievable: encouraging researchers to conduct their existing research activities through the shared intelligence platform rather than through disconnected personal tools.
This is a crucial distinction. Asking a researcher to write a detailed summary of every patent search is asking them to do something extra. Asking them to run their patent searches through a shared platform that captures and compounds intelligence automatically is asking them to do the same thing they were already doing, just through a different interface. The behavioral change required is adoption of a tool, not adoption of a practice. Organizations that have successfully deployed R&D intelligence platforms report that researcher adoption accelerates once teams experience the compounding benefit firsthand. When a scientist runs a query and the platform surfaces not only relevant external literature but also connections to investigations their colleagues conducted months earlier, the value proposition becomes self-evident.
The organizational shift is from a documentation culture, where knowledge sharing is treated as an obligation that competes with research for time and attention, to a contribution culture, where every act of research automatically enriches the collective intelligence available to the entire organization. In a documentation culture, knowledge sharing is a tax on productivity. In a contribution culture, knowledge sharing is a natural consequence of productivity.
Leadership plays an essential role in catalyzing this transition. R&D directors and chief technology officers should establish the shared intelligence platform as the default starting point for any new research initiative. Before launching a new project, teams should first query the organizational AI memory to understand what the company already knows about the relevant technology landscape, which adjacent investigations have been conducted, and what competitive and scientific context has already been mapped. This practice not only prevents duplicate research but reinforces the value of contributing to the shared knowledge base by demonstrating that previous contributions are actively building on each other.
The External Intelligence Dimension That Most Knowledge Sharing Strategies Miss
Most guidance on improving R&D knowledge sharing focuses exclusively on internal knowledge: getting researchers to share what they know with each other. This emphasis is understandable but incomplete. In practice, the most consequential knowledge sharing failures in R&D are not failures to share internal tribal knowledge. They are failures to ensure that external intelligence, including patent landscapes, scientific breakthroughs, competitive moves, and regulatory developments, reaches every team that needs it in a timely and contextualized form.
Consider a scenario that plays out regularly in large R&D organizations. A team in the automotive materials division conducts a thorough analysis of emerging patents in lightweight structural composites. Three months later, a team in the aerospace coatings division begins a project that intersects significantly with the same patent landscape but has no knowledge that the earlier analysis was ever performed. The second team spends weeks replicating intelligence that already exists within the company, not because anyone failed to share internal expertise, but because the external intelligence gathered by one team never entered any system that the other team could access.
This is the gap that a compounding AI memory specifically addresses. When external intelligence, including patent analysis, literature reviews, and competitive signals, is captured in a shared, AI-accessible system, it becomes organizational knowledge that persists and compounds independently of which team originally gathered it or whether that team remembers to share it. The aerospace coatings team, querying the same platform that the automotive materials team used months earlier, would automatically benefit from the accumulated intelligence without either team needing to coordinate, schedule a meeting, or remember to send an email.
Enterprise R&D intelligence platforms like Cypris are designed around this principle. By providing unified access to comprehensive patent databases, scientific literature repositories, and competitive intelligence through a single platform that retains organizational context, these systems ensure that external intelligence is captured once and compounded indefinitely. The AI research agent draws on the full history of the organization's queries and investigations, which means that each new research question is answered not in isolation but in the context of everything the organization has previously explored. This is how knowledge sharing transforms from a periodic, effortful activity into a continuous, automatic process embedded in the infrastructure of research itself.
Measuring the Impact of Compounding Knowledge Systems
Organizations evaluating AI-powered knowledge sharing approaches should track several categories of metrics to assess whether their knowledge base is genuinely compounding. Research duplication rates offer the most direct measure: how frequently do teams discover that investigations they initiated had already been partially or fully conducted by another group? Organizations that have consolidated their R&D intelligence infrastructure report reductions in research duplication of up to 70 percent.
Time to insight measures how long it takes a researcher to move from an initial question to an actionable understanding of the relevant technology landscape, competitive positioning, and scientific context. In organizations relying on fragmented tools and manual knowledge sharing, this process can take days or weeks as researchers navigate between separate patent databases, literature search engines, and internal document repositories. Integrated intelligence platforms with compounding AI memory compress this timeline significantly, with some organizations reporting 50 percent reductions in prior art search time and 40 percent decreases in overall time to insight.
Cross-team intelligence reuse is perhaps the most meaningful indicator of whether knowledge is genuinely compounding. This metric tracks how frequently insights generated by one team surface as relevant context for another team's investigation, even when the teams did not directly coordinate. High rates of cross-team intelligence reuse indicate that the AI memory is successfully connecting knowledge across organizational boundaries, which is the compounding dynamic that creates exponential returns on the initial intelligence investment.
Finally, new researcher onboarding velocity reflects how effectively the compounding knowledge base transmits institutional expertise to incoming team members. In organizations without integrated AI memory, new researchers typically require months to develop a working understanding of the competitive landscape, the organization's research history, and the technical context relevant to their projects. When this context is available through an AI system that can synthesize years of accumulated organizational intelligence in response to natural language queries, the effective onboarding period compresses dramatically. Rather than spending months recreating a mental model that senior colleagues built over years, new researchers can query the organizational memory and begin contributing meaningful work far sooner.
Getting Started: A Practical Roadmap for R&D Leaders
R&D leaders looking to implement a compounding knowledge sharing approach should begin by auditing the current intelligence tool landscape across their department. Most enterprise R&D teams navigate between five and twelve separate intelligence platforms, from patent databases to scientific literature repositories, market intelligence tools, and competitive analysis systems. Each of these tools creates its own silo of intelligence, invisible to the other tools and inaccessible to AI systems that could synthesize insights across them. Mapping this fragmentation is the necessary first step toward consolidation.
The second step is identifying a platform capable of serving as the central intelligence layer. The requirements are demanding: the platform must integrate comprehensive patent data, scientific literature, and competitive intelligence in a single interface; it must provide AI-powered synthesis that retains and builds on organizational query history; it must meet enterprise security standards including SOC 2 Type II certification; and it must integrate with existing research workflows so that adoption does not require researchers to abandon familiar processes. Platforms that meet these criteria become the foundation of the compounding knowledge system, capturing intelligence from every research interaction and making it available to the entire organization.
The third step is establishing platform-first research protocols. Every new project, landscape analysis, and competitive review should begin with a query to the shared intelligence platform. This practice serves dual purposes: it ensures that existing organizational knowledge informs every new investigation, and it contributes each new investigation to the growing body of organizational intelligence. Over time, this protocol becomes self-reinforcing as researchers experience the compounding benefit of a knowledge base that grows richer with every interaction.
The final step is patient commitment to the compounding model. Unlike traditional knowledge management initiatives that can be evaluated in weeks, a compounding knowledge system delivers returns that accelerate over time. The platform becomes meaningfully more valuable after six months of accumulated queries than it was in the first week, and substantially more valuable after two years than after six months. Organizations that commit to this approach and sustain researcher adoption through the initial period of accumulation will build a durable competitive advantage that becomes increasingly difficult for rivals to replicate, because the compounding knowledge base reflects not just access to external data but the accumulated strategic intelligence of the organization's own research history.
FAQ
What is knowledge sharing in R&D?Knowledge sharing in R&D is the systematic practice of capturing, organizing, and distributing both internal institutional expertise and external innovation intelligence, including patent landscapes, scientific literature, and competitive data, so that every researcher in the organization can build on collective knowledge rather than working in isolation.
Why is knowledge sharing particularly important for R&D departments?R&D departments face uniquely high costs from knowledge sharing failures because research involves long timelines, highly specialized expertise, and cumulative investigation where missing a single piece of prior art or duplicating a previous study can waste months of effort and millions of dollars. Fortune 500 companies lose an estimated $31.5 billion annually from ineffective knowledge sharing, with R&D departments bearing disproportionate impact due to the specialized and cumulative nature of research work.
What is a compounding AI memory for R&D?A compounding AI memory is a centralized intelligence system that automatically captures knowledge from every research activity, including patent searches, literature reviews, and competitive analyses, and makes that accumulated intelligence available to AI systems that can synthesize it with new queries. Unlike traditional knowledge bases where documents are simply stored, a compounding AI memory grows more valuable over time as each new interaction enriches the context available for future investigations.
How does a compounding knowledge system differ from a traditional knowledge management platform?Traditional knowledge management platforms are additive: each new document increases the volume of stored information, but documents do not interact with each other. A compounding knowledge system is multiplicative: each new piece of intelligence enhances the value of everything already in the system by creating connections, surfacing relationships, and enabling AI to provide progressively richer responses. The key difference is that traditional systems require humans to make connections between stored documents, while compounding systems use AI to make those connections automatically.
What should R&D leaders look for in an enterprise intelligence platform?R&D leaders should evaluate platforms based on breadth of data integration (patents, scientific literature, competitive intelligence, and market data in a single interface), AI synthesis capabilities that retain organizational context across queries, enterprise security certifications such as SOC 2 Type II, data sovereignty guarantees, an R&D-specific ontology that understands technical relationships between concepts, and the ability to integrate with existing research workflows. Platforms like Cypris are purpose-built for these enterprise R&D requirements.
How can organizations measure whether their knowledge sharing is actually compounding?Key metrics include research duplication rates (how often teams unknowingly replicate previous investigations), time to insight (how quickly researchers achieve actionable understanding of a technology landscape), cross-team intelligence reuse (how frequently one team's research surfaces as context for another team's work), and new researcher onboarding velocity (how quickly new hires develop working knowledge of the organization's research landscape and competitive context).
Cypris helps enterprise R&D teams build a compounding knowledge advantage by unifying access to over 500 million patents, scientific papers, and competitive intelligence sources through a single AI-powered platform. Book a demo to see how organizations are turning every research interaction into lasting institutional intelligence at cypris.ai.
Quantum Computing and Enterprise R&D: What Innovation Leaders Need to Know Now
This article was powered by Cypris Q, an AI agent that helps R&D teams instantly synthesize insights from patents, scientific literature, and market intelligence from around the globe. Discover how leading R&D teams use Cypris Q to monitor technology landscapes and identify opportunities faster - Book a demo
Executive Summary
Quantum computing is no longer a science project. It is a risk-and-optionality play that is already reshaping cybersecurity roadmaps, supplier ecosystems, and the competitive balance in compute-intensive industries [1, 2, 3]. In 2025, the industry crossed multiple inflection points simultaneously: Google demonstrated below-threshold quantum error correction for the first time in 30 years of trying, Quantinuum launched the first enterprise-grade commercial quantum computer with Fortune 500 customers running real workloads, Microsoft introduced an entirely new class of qubit, and quantum startup funding nearly tripled year over year. The global quantum computing market reached an estimated $1.8 to $3.5 billion in 2025, with projections ranging from $7 billion to $20 billion by 2030, depending on modeling assumptions [4, 5].
For innovation strategists, quantum is best treated as a two-horizon asset: a near-term driver of security modernization and ecosystem influence, and a longer-term path to differentiated capabilities in optimization and simulation once fault tolerance matures [3, 6]. But the near-term is arriving faster than most enterprise roadmaps anticipated. NIST's post-quantum cryptography program has moved from research into formal standardization milestones, creating an enterprise-wide trigger that forces budget allocation, vendor qualification, and lifecycle planning now, not after a cryptographically relevant quantum computer arrives [1, 2, 7]. Meanwhile, the IP landscape reveals that the most defensible competitive positions are forming not around qubit counts, but in the reliability and orchestration stack: calibration-aware compilation, error mitigation workflows, and execution orchestration platforms [8, 9, 10].
This article examines where quantum maturity actually stands after a landmark year of breakthroughs, where enterprise value will land first, how the competitive and IP landscape is reshaping vendor selection, and what R&D leaders should prioritize in the next six months.
2025: The Year the Hardware Race Became Real
Any assessment of quantum computing's enterprise relevance must start with what happened in the hardware landscape over the past 18 months, because the trajectory shifted dramatically.
In December 2024, Google introduced its 105-qubit Willow chip and demonstrated what the quantum computing community had pursued for nearly three decades: below-threshold quantum error correction [11, 12]. In experiments scaling from 3x3 to 5x5 to 7x7 arrays of physical qubits, each increase in logical qubit size produced an exponential reduction in error rates, cutting the error rate roughly in half with each step up [11, 12, 13]. This was not an incremental improvement. It was the first credible experimental proof that quantum error correction can actually pay for itself at scale, the foundational requirement for building fault-tolerant quantum computers. Willow also completed a benchmark computation in under five minutes that Google estimated would take the Frontier supercomputer, the world's most powerful classical machine, ten septillion years [11, 12].
In April 2024, Microsoft and Quantinuum demonstrated logical qubits with error rates 800 times lower than corresponding physical qubits, creating four highly reliable logical qubits from just 30 physical qubits [14]. Microsoft declared this the transition into "Level 2 Resilient" quantum computing, capable of tackling meaningful scientific challenges including molecular modeling and condensed matter physics simulations [14, 15].
Then in February 2025, Microsoft unveiled Majorana 1, the world's first quantum processor powered by topological qubits [16]. Built with a novel class of materials called topoconductors, Majorana 1 represents a fundamentally different approach to quantum computing: hardware-protected qubits that use digital rather than analog control, dramatically simplifying error correction. Microsoft's roadmap envisions scaling to a million qubits on a single chip [16].
By November 2025, Quantinuum launched Helios, which the company positioned as the world's most accurate general-purpose commercial quantum computer, with 98 fully connected physical qubits and fidelity exceeding 99.9% [17, 18]. The launch came with a signal that matters more than the hardware specifications: Amgen, BMW Group, JPMorgan Chase, and SoftBank signed on as initial customers, conducting what Quantinuum described as "commercially relevant research" in biologics, fuel cell catalysts, financial analytics, and organic materials [17, 18]. Quantinuum's valuation reached $10 billion following an $800 million oversubscribed funding round [19].
Meanwhile, IBM continued executing against a roadmap it has so far delivered on consistently. In November 2025, IBM introduced its Nighthawk processor and the experimental Loon chip containing components needed for fault-tolerant computing [20]. IBM's updated roadmap targets quantum advantage by the end of 2026 and Starling, its first large-scale fault-tolerant quantum computer with 200 logical qubits capable of executing 100 million quantum operations, by 2029 [21, 22]. Beyond Starling, IBM's Blue Jay system targets 2,000 logical qubits and one billion operations by 2033 [21].
What makes this moment particularly significant for R&D leaders is the diversification of viable approaches. DARPA's Quantum Benchmarking Initiative selected companies spanning five distinct qubit modalities: superconducting qubits from IBM and Nord Quantique, trapped ions from IonQ and Quantinuum, neutral atoms from Atom Computing and QuEra, silicon spin qubits from Diraq and others, and photonic qubits from Xanadu [23]. PsiQuantum, pursuing a photonic approach, became the world's most funded quantum startup with a $1 billion raise in September 2025, reaching a $7 billion valuation [23]. No single hardware modality has emerged as the winner, and this has direct implications for how enterprises should structure vendor relationships and IP strategies.
The Investment Surge: Why Budget Conversations Are Changing
The capital flowing into quantum computing has reached a scale that demands attention from any executive managing a technology portfolio. Quantum computing companies raised $3.77 billion in equity funding during the first nine months of 2025, nearly triple the $1.3 billion raised in all of 2024 [23, 24]. Government commitments have been equally aggressive. Global public quantum funding exceeded $10 billion by April 2025, anchored by Japan's $7.4 billion commitment and China's establishment of a national fund of approximately $138 billion for quantum and related frontier technologies [24, 25]. The U.S. National Quantum Initiative, the EU Quantum Flagship program, and newly announced national strategies from Singapore, South Korea, and others are creating a geopolitically charged landscape where quantum readiness is becoming a matter of industrial policy, not just R&D strategy [24, 25].
McKinsey estimates that quantum computing companies generated $650 to $750 million in revenue in 2024 and were expected to surpass $1 billion in 2025, with the broader quantum technology market projected to generate up to $97 billion in revenue worldwide by 2035 [6, 25]. Nearly 80% of the world's top 50 banks are now investing in quantum technology [5]. These are no longer speculative research budgets. They are strategic positioning investments by organizations that expect quantum to reshape competitive dynamics within the decade.
For corporate R&D leaders, the practical implication is that the window for "wait and see" is closing. Competitors and partners are building quantum capabilities, accumulating institutional knowledge, and establishing vendor relationships that will be difficult to replicate once the technology inflects toward commercial utility.
The Error Correction Inflection: From Theory to Measurable Engineering
The decisive maturity shift underlying all of these developments is that quantum error correction has crossed from a theoretical prerequisite into an engineering discipline with quantitative milestones [26, 27, 28]. The surface code remains a central reference point because it provides a practical route to fault tolerance with local operations, and its threshold behavior links hardware error rates to scalable reliability targets [29, 26].
Google's Willow results were the most dramatic demonstration, but the broader research trajectory matters more. Recent experiments have explicitly targeted "break-even" regimes, where an encoded logical qubit outperforms a comparable unencoded physical qubit, because this is the earliest credible signal that error correction can pay for itself [28, 30, 31]. Work on encoding and manipulating logical states beyond break-even demonstrates that the overhead curve can bend in a favorable direction under real device noise, even though full fault-tolerant computation remains ahead [30, 31].
However, the research record is also unambiguous that thresholds and scalability are noise-model dependent, and engineering teams must treat coherent and correlated errors as first-class constraints [32, 33]. Surface-code threshold estimates vary with circuits and decoders, and reported numerical thresholds sit around the approximately 0.5% to 1.1% per-gate range under specific modeling assumptions, illustrating why average gate fidelity alone is an insufficient maturity metric [29]. Google's own researchers acknowledged that while Willow's logical error rates of around 0.14% per cycle represent a qualitative breakthrough, they remain orders of magnitude above the 10^-6 levels needed for running meaningful large-scale quantum algorithms [11]. IBM is attacking this gap from the code side, shifting from surface codes to quantum LDPC codes that reduce physical qubit overhead by up to 90%, a potential game-changer for the economics of fault tolerance [21, 22].
The economic implication of this shift is significant. The transition from "can we encode?" to "can we encode with operational latency, decoding, and calibration constraints?" redefines where competitive advantage accrues. It moves up the stack into control systems, real-time decoding, and workflow orchestration, capabilities that are patentable, defensible, and difficult to replicate [8, 9, 10].
The NISQ Reality Check: Error Mitigation Helps, but Its Scaling Economics Are Brutal
Most enterprise quantum programs today live in the noisy intermediate-scale quantum (NISQ) regime, where practical value is pursued through hybrid algorithms and error mitigation rather than full fault tolerance [34, 35]. This is an economically rational strategy, up to a point, because error mitigation can improve accuracy without the massive qubit overhead of QEC [34].
However, the literature formalizes a hard ceiling. Broad classes of error-mitigation methods incur costs that can grow rapidly, often exponentially, with circuit depth and sometimes with qubit count, depending on noise assumptions and target accuracy [36, 37]. Even when mitigation methods are clever and empirically useful, decision-makers should assume that "just mitigate harder" does not scale into the regimes required for transformative workloads [38, 36, 37].
This reality turns quantum program management into a portfolio problem. Near-term pilots should focus on problems with short-depth circuits and measurable business value, and on organizational learning about workflow, data, and governance, while simultaneously building positions in the fault-tolerant pathway that will ultimately unlock durable advantage [3, 6].
Where Enterprise Impact Will Land First: Optimization as the Proving Ground
In practice, many early enterprise workloads will not look like Hollywood-style quantum chemistry. They will look like operational optimization: scheduling, routing, portfolio constraints, and resource allocation. These problems are natural first targets because they are ubiquitous across industries, have clear KPIs, and can be framed as hybrid workflows where quantum is one module rather than the whole system [39]. Market analysts consistently identify optimization as the application segment commanding the largest share of enterprise quantum adoption in North America [4, 5].
Research has explicitly positioned optimization applications as quantum performance benchmarks, emphasizing throughput and solution-quality tradeoffs under real execution conditions [39]. This benchmarking orientation shifts quantum evaluation away from abstract qubit counts and toward business-facing performance profiles, including time-to-solution, output quality, and repeatability, that map directly to procurement and ROI logic [39].
When quantum evaluation becomes benchmark-driven, the competitive battlefield shifts from who has the biggest chip to who owns the end-to-end pipeline: problem encoding, compilation, calibration-aware execution, and post-processing that converts hardware into dependable outputs [8, 10, 40].
Corporate Proof Points: The Partnerships Have Matured
The nature of enterprise quantum partnerships has changed fundamentally since the early ecosystem-joining announcements of 2017-2022. Where earlier engagements were largely exploratory, the current generation involves specific commercial workloads, dedicated hardware access, and measurable research outcomes.
Quantinuum's Helios launch in November 2025 represents the clearest signal of this maturation. Amgen is exploring hybrid quantum-machine learning for biologics design. BMW Group is researching fuel cell catalyst materials. JPMorgan Chase is investigating advanced financial analytics capabilities. SoftBank conducted commercially relevant research during the pre-launch beta period [17, 18, 19]. These are not press-release partnerships. They represent organizations committing engineering resources to specific quantum workflows with defined performance criteria.
In parallel, IonQ and Ansys demonstrated quantum performance exceeding classical computing for medical device design, and Quantinuum partnered with JPMorgan Chase, Oak Ridge National Laboratory, and Argonne National Laboratory to generate true verifiable quantum randomness with applications in cryptography and cybersecurity [23]. IBM's growing ecosystem, including its planned quantum advantage demonstrations by end of 2026, continues to anchor the superconducting qubit pathway with a fleet of quantum systems accessible through cloud and on-premise deployments [21, 22].
A separate but equally significant category is the energy and materials sector, where IBM and Exxon's exploration of quantum for computational tasks in R&D, Roche's testing of quantum algorithms for drug discovery, and broader pharma engagement through Quantinuum's platform signal that compute-intensive industries are systematically evaluating quantum as part of their longer-horizon computational strategies [41, 42, 43].
These partnerships should be interpreted as proof that leading firms are buying three assets simultaneously: early access to talent and tooling, influence over vendor roadmaps, and a learning curve advantage that becomes hard to replicate once the technology inflects toward commercial utility [3, 6].
IP as a Strategic Moat: The Plumbing Is Where Defensibility Lives
In quantum computing, the most defensible IP often sits below the application layer, in the reliability and orchestration stack: error mitigation calibration, compilation strategies, control workflows, and execution orchestration. Patents in this layer signal where vendors expect long-term defensibility because these capabilities become embedded in platforms, deeply integrated with hardware behavior, and hard to displace without imposing switching costs.
Three plumbing domains stand out in the current patent landscape.
The first is calibration-aware error mitigation, software that adapts to noise. IBM patents describe methods for calibrating error mitigation techniques by selecting settings based on factors such as circuit depth, aiming to approximate a zero-noise expectation without repeated manual tuning [44, 45]. Other filings describe inserting error-mitigating operations based on assessed hardware noise conditions, effectively tying compilation to real device state [46].
The second is compilation and runtime strategies that reduce rework and latency. IBM has pursued approaches that bind calibration libraries to compiled binaries so circuits can be compiled without knowing the final calibration outcome, reducing recompilation churn in unstable hardware environments [9]. Patents around adaptive compilation of quantum jobs highlight selection and modification of programs based on device attributes and run criteria, reinforcing that compilation is becoming a competitive lever rather than a commodity step [10].
The third is orchestration platforms and quantum DevOps. Amazon patents describe compilation services and orchestration approaches that support multiple hardware backends and containerized execution across third-party quantum hardware providers, effectively defining the control plane and platform gravity for enterprise quantum adoption [47, 48, 49, 50]. Quantum Machines patents emphasize real-time orchestration and concurrent processing in quantum control systems, a layer that becomes critical when feedback, streaming results, and low-latency calibration loops drive performance [8, 51].
This plumbing IP creates barriers to entry because it compounds over time. Every calibration trick, compiler heuristic, and orchestration shortcut is trained on proprietary hardware telemetry and execution data, building a feedback loop that improves reliability and throughput [8, 9, 10]. For corporate adopters, this implies that vendor choice is not only about qubits. It is about which ecosystem will own the workflow layer that determines productivity and switching costs [3, 6].
What Decision-Makers Should Expect: Five Forecasts for the Next Three Years
First, "quantum readiness" budgets will increasingly be justified through cybersecurity and compliance rather than near-term computational ROI. NIST's PQC standardization milestones and related government guidance are driving enterprise migration planning across product and infrastructure lifecycles, making quantum an immediate governance issue regardless of quantum hardware timelines [1, 2, 7].
Second, vendor differentiation will decisively shift from hardware headline metrics to full-stack reliability tooling. Patent activity emphasizes mitigation calibration, calibration-independent compilation, adaptive compilation, and orchestration services, and the hardware players are all converging on hybrid quantum-classical architectures that make software and middleware the key differentiators [44, 45, 9, 48, 10].
Third, the most repeatable early business wins will be hybrid optimization workflows evaluated via benchmark-style performance profiles. Optimization benchmarking frameworks explicitly focus on throughput and solution-quality tradeoffs under realistic execution constraints, aligning with procurement-grade evaluation criteria [39].
Fourth, error mitigation will remain valuable for near-term pilots but will hit economic scaling limits that force a pivot to QEC for transformative workloads. Fundamental bounds show mitigation costs can grow sharply with depth and qubit count under broad noise models [36, 37, 38].
Fifth, the timeline to fault-tolerant quantum computing has compressed. Multiple credible organizations, including IBM, Google, and Quantinuum, now target fault-tolerant systems by 2029-2030, with quantum advantage demonstrations expected as early as 2026 [21, 22, 17]. Enterprises that begin building quantum literacy, workflows, and vendor relationships now will have a three-to-five-year head start on those that wait for fault tolerance to arrive.
The Resource Allocation Logic: A Portfolio, Not a Bet
A practical resource allocation stance is to treat quantum as three simultaneous investments.
The first is risk mitigation. PQC migration planning and cryptographic inventory are non-optional for many sectors. Companies that delay building a cryptographic inventory and dependency map aligned with NIST PQC transition realities accumulate technical debt that becomes harder to unwind as deadlines approach [1, 2, 7].
The second is option creation. Targeted pilots in optimization and simulation build organizational learning and partner leverage. The most effective pilots focus on constrained optimization problems with clean metrics, such as cost, time, or utilization, and a known baseline, with reporting framed in performance profile terms: solution quality versus runtime across instance sizes [39, 3].
The third is moat building. IP positions in workflow, compilation, mitigation, and domain-specific problem formulations create defensible advantage independent of which hardware modality wins. Companies should identify what is proprietary in their pipeline, including data representations, constraints, objective functions, and orchestration logic, and file strategically on domain-specific encodings and workflow automation where internal know-how is unique and transferable across hardware providers [44, 45, 47, 9].
This portfolio framing prevents the most common failure mode: overfunding speculative moonshots while underfunding the unglamorous readiness work that determines whether the company can capitalize when the technology inflects [3, 6].
Strategic Imperatives for the Next Six Months
The first imperative is to stand up a quantum risk and readiness workstream anchored in PQC migration. The fastest route to board-level clarity is to connect quantum to mandated security modernization, not experimental compute outcomes. This means building a cryptographic inventory and dependency map, classifying systems by crypto agility and upgrade cycles to prioritize where migration is hardest, and engaging vendors on PQC support roadmaps for products and services in scope [1, 2, 7].
The second imperative is to choose one optimization pilot with an executive KPI and treat it as a benchmark, not a demo. Select a constrained optimization problem with a clean metric and a known baseline, require reporting in performance profile terms, and architect the workflow as hybrid from day one to ensure the pilot teaches integration, not only algorithm theory [39].
The third imperative is to negotiate partnerships that buy influence over the stack you cannot build alone. The partnership landscape has matured considerably. Finance organizations should follow JPMorgan Chase's model of engaging across multiple quantum ecosystems simultaneously, from IBM to Quantinuum's Helios. Pharma and materials organizations should explore Quantinuum's and IBM's growing application-specific partnerships. Operations-focused organizations should pursue pilots tied to tangible constraints where improvements are measurable [17, 21, 41].
The fourth imperative is to start building internal quantum plumbing IP now, even if you never build hardware. Conduct an IP scan focused on mitigation calibration, compilation and orchestration, and runtime control, because these layers are where vendors are actively patenting defensible capabilities. Identify what is proprietary in your domain's problem formulations, constraints, and data representations, and file strategically on encodings that are transferable across hardware providers [44, 45, 47, 9].
The fifth imperative is to build a vendor evaluation rubric that weights reliability tooling, multi-backend portability, and platform lock-in risk, not just qubit counts. With five viable qubit modalities competing and no clear winner, enterprises need vendor relationships and software architectures that can adapt as the hardware landscape evolves [47, 8, 9].
The sixth imperative is to make organizational readiness measurable and auditable. Define capability KPIs such as number of workflows benchmarked, reproducibility, integration maturity, and PQC migration milestones. Establish an internal review cadence that treats quantum like a product portfolio with stage gates and kill criteria, and tie funding releases to concrete deliverables [3, 6, 39, 44, 45].
Citations
[1] "Post-Quantum Cryptography FIPS Approved - NIST CSRC." https://csrc.nist.gov/news/2024/postquantum-cryptography-fips-approved
[2] "NIST Releases First 3 Finalized Post-Quantum Encryption Standards." https://www.nist.gov/news-events/news/2024/08/nist-releases-first-3-finalized-post-quantum-encryption-standards
[3] "Quantum Technology Monitor - McKinsey." https://www.mckinsey.com/~/media/mckinsey/business%20functions/mckinsey%20digital/our%20insights/steady%20progress%20in%20approaching%20the%20quantum%20advantage/quantum-technology-monitor-april-2024.pdf
[4] "Quantum Computing Market Research Report 2025-2030." MarketsandMarkets. https://www.marketsandmarkets.com/PressReleases/quantum-computing.asp
[5] "Quantum Computing Market Size, Industry Report 2030." Grand View Research. https://www.grandviewresearch.com/industry-analysis/quantum-computing-market
[6] "The Rise of Quantum Computing | McKinsey & Company." https://www.mckinsey.com/featured-insights/the-rise-of-quantum-computing
[7] "Product Categories for Technologies That Use Post-Quantum Cryptography Standards - CISA." https://www.cisa.gov/resources-tools/resources/product-categories-technologies-use-post-quantum-cryptography-standards
[8] Q.M Technologies Ltd. and Quantum Machines. Concurrent results processing in a quantum control system. Patent No. US-12417397-B2. Issued Sep 15, 2025.
[9] International Business Machines Corporation. Quantum Circuit Compilation Independent of Calibration. Patent No. US-20260037852-A1. Issued Feb 4, 2026.
[10] International Business Machines Corporation. Adaptive Compilation of Quantum Computing Jobs. Patent No. US-20210012233-A1. Issued Jan 13, 2021.
[11] "Meet Willow, our state-of-the-art quantum chip." Google Blog, December 2024. https://blog.google/technology/research/google-willow-quantum-chip/
[12] "Making quantum error correction work." Google Research Blog. https://research.google/blog/making-quantum-error-correction-work/
[13] "Google's Willow Chip Makes a Major Breakthrough in Quantum Computing." Scientific American, December 2024. https://www.scientificamerican.com/article/google-makes-a-major-quantum-computing-breakthrough/
[14] "How Microsoft and Quantinuum achieved reliable quantum computing." Microsoft Azure Quantum Blog, April 2024. https://azure.microsoft.com/en-us/blog/quantum/2024/04/03/how-microsoft-and-quantinuum-achieved-reliable-quantum-computing/
[15] "Quantinuum and Microsoft announce new era in quantum computing." Quantinuum. https://www.quantinuum.com/press-releases/quantinuum-and-microsoft-announce-new-era-in-quantum-computing-with-breakthrough-demonstration-of-reliable-qubits
[16] "Microsoft unveils Majorana 1." Microsoft Azure Quantum Blog, February 2025. https://azure.microsoft.com/en-us/blog/quantum/2025/02/19/microsoft-unveils-majorana-1-the-worlds-first-quantum-processor-powered-by-topological-qubits/
[17] "Quantinuum Announces Commercial Launch of New Helios Quantum Computer." Quantinuum, November 2025. https://www.quantinuum.com/press-releases/quantinuum-announces-commercial-launch-of-new-helios-quantum-computer-that-offers-unprecedented-accuracy-to-enable-generative-quantum-ai-genqai
[18] "Introducing Helios: The Most Accurate Quantum Computer in the World." Quantinuum Blog, November 2025. https://www.quantinuum.com/blog/introducing-helios-the-most-accurate-quantum-computer-in-the-world
[19] "Quantinuum Makes Another Milestone On Commercial Quantum Roadmap." Next Platform, November 2025. https://www.nextplatform.com/2025/11/10/quantinuum-makes-another-milestone-on-commercial-quantum-roadmap/
[20] "IBM Lets Fly Nighthawk And Loon QPUs On The Way To Quantum Advantage." Next Platform, November 2025. https://www.nextplatform.com/2025/11/12/ibm-lets-fly-nighthawk-and-loon-qpus-on-the-way-to-quantum-advantage/
[21] "IBM Sets the Course to Build World's First Large-Scale, Fault-Tolerant Quantum Computer." IBM Newsroom, June 2025. https://newsroom.ibm.com/2025-06-10-IBM-Sets-the-Course-to-Build-Worlds-First-Large-Scale,-Fault-Tolerant-Quantum-Computer-at-New-IBM-Quantum-Data-Center
[22] "IBM lays out clear path to fault-tolerant quantum computing." IBM Quantum Blog. https://www.ibm.com/quantum/blog/large-scale-ftqc
[23] "Top quantum breakthroughs of 2025." Network World, November 2025. https://www.networkworld.com/article/4088709/top-quantum-breakthroughs-of-2025.html
[24] "Quantum Computing Industry Trends 2025." SpinQ. https://www.spinquanta.com/news-detail/quantum-computing-industry-trends-2025-breakthrough-milestones-commercial-transition
[25] "Quantum Investment Stats: Record Funding, Big Tech Bets and Industry Consolidation." Quantum Basel. https://www.quantumbasel.com/blog/quantum-investments-stats-2025/
[26] Daniel Gottesman. "An introduction to quantum error correction and fault-tolerant quantum computation." Proceedings of Symposia in Applied Mathematics. https://doi.org/10.1090/psapm/068/2762145
[27] Markus Muller et al. "Demonstration of Fault-Tolerant Steane Quantum Error Correction." PRX Quantum. https://doi.org/10.1103/prxquantum.5.030326
[28] Andy Z. Ding et al. "Quantum Error Correction of Qudits Beyond Break-even." arXiv. https://doi.org/10.48550/arxiv.2409.15065
[29] Ashley M. Stephens. "Fault-tolerant thresholds for quantum error correction with the surface code." Physical Review A. https://doi.org/10.1103/physreva.89.022321
[30] Andrew Lucas et al. "Entangling Four Logical Qubits beyond Break-Even in a Nonlocal Code." Physical Review Letters. https://doi.org/10.1103/physrevlett.133.180601
[31] Theodore J. Yoder et al. "Encoding a magic state with beyond break-even fidelity." arXiv. https://doi.org/10.48550/arxiv.2305.13581
[32] Hui Khoon Ng and Jing Hao Chai. "On the Fault-Tolerance Threshold for Surface Codes with General Noise." Advanced Quantum Technologies. https://doi.org/10.1002/qute.202200008
[33] Dong E. Liu and Yuanchen Zhao. "Vulnerability of fault-tolerant topological quantum error correction to quantum deviations in code space." arXiv. https://doi.org/10.48550/arxiv.2301.12859
[34] Takahiro Tsunoda et al. "Mitigating Realistic Noise in Practical Noisy Intermediate-Scale Quantum Devices." Physical Review Applied. https://doi.org/10.1103/physrevapplied.15.034026
[35] Yanzhu Chen, Dayue Qin, and Ying Li. "Error statistics and scalability of quantum error mitigation formulas." arXiv. https://doi.org/10.48550/arxiv.2112.06255
[36] Kento Tsubouchi, Nobuyuki Yoshioka, and Takahiro Sagawa. "Universal Cost Bound of Quantum Error Mitigation Based on Quantum Estimation Theory." Physical Review Letters. https://doi.org/10.1103/physrevlett.131.210601
[37] Mile Gu, Ryuji Takagi, and Hiroyasu Tajima. "Universal Sampling Lower Bounds for Quantum Error Mitigation." Physical Review Letters. https://doi.org/10.1103/physrevlett.131.210602
[38] Ryuji Takagi. "Optimal resource cost for error mitigation." Physical Review Research. https://doi.org/10.1103/physrevresearch.3.033178
[39] Thomas Lubinski et al. "Optimization Applications as Quantum Performance Benchmarks." ACM Transactions on Quantum Computing. https://doi.org/10.1145/3678184
[40] Rigetti & Co, LLC. Quantum instruction compiler for optimizing hybrid algorithms. Patent No. US-12293254-B1. Issued May 5, 2025.
[41] "Exxon, IBM to research quantum computing for energy - Anadolu." https://www.aa.com.tr/en/energy/projects/exxon-ibm-to-research-quantum-computing-for-energy/23010
[42] "Roche partners for quantum computing." C&EN Global Enterprise. https://pubs.acs.org/doi/10.1021/cen-09905-buscon13
[43] "Calculating the unimaginable - Roche." https://www.roche.com/stories/quantum-computers-calculating-the-unimaginable
[44] International Business Machines Corporation. Calibrating a quantum error mitigation technique. Patent No. US-12198013-B1. Issued Jan 13, 2025.
[45] International Business Machines Corporation. Calibrating a Quantum Error Mitigation Technique. Patent No. US-20250013907-A1. Issued Jan 8, 2025.
[46] International Business Machines Corporation. Error mitigation in a quantum program. Patent No. US-12430197-B2. Issued Sep 29, 2025.
[47] Amazon Technologies, Inc. Quantum Compilation Service. Patent No. EP-4690024-A1. Issued Feb 10, 2026.
[48] Amazon Technologies, Inc. Containerized Execution Orchestration of Quantum Tasks on Quantum Hardware Provider Quantum Processing Units. Patent No. WO-2025144486-A2. Issued Jul 2, 2025.
[49] Amazon Technologies, Inc. Quantum Computing Program Compilation Using Cached Compiled Quantum Circuit Files. Patent No. US-20230040849-A1. Issued Feb 8, 2023.
[50] Amazon Technologies, Inc. Quantum computing program compilation using cached compiled quantum circuit files. Patent No. US-11977957-B2. Issued May 6, 2024.
[51] Q.M Technologies Ltd. and Quantum Machines. Auto-calibrating mixers in a quantum orchestration platform. Patent No. US-12314815-B2. Issued May 26, 2025.

Patent Activity in Next-Gen Photovoltaics: Who's Building the IP Moat
Published February 9th 2026
This article was powered by Cypris Q, an AI agent that helps R&D teams instantly synthesize insights from patents, scientific literature, and market intelligence from around the globe. Discover how leading R&D teams use Cypris Q to monitor technology landscapes and identify opportunities faster - Book a demo
The perovskite solar cell is no longer a laboratory curiosity. In 2025, LONGi Green Energy shattered the world record for crystalline silicon-perovskite tandem solar cells, reaching a certified power conversion efficiency of 34.85%, validated by the U.S. National Renewable Energy Laboratory and marking the first reported certified efficiency exceeding the single-junction Shockley-Queisser limit of 33.7% for a double-junction tandem device[1]. Oxford PV shipped the world's first commercial perovskite-silicon tandem panels to a U.S. utility-scale installation[2][3] and then signed a landmark patent licensing agreement with Trina Solar for the manufacture and sale of perovskite-based products in China's $50-billion-plus domestic photovoltaic market[4]. GCL Optoelectronics commissioned the world's first gigawatt-scale perovskite module manufacturing facility in Kunshan, backed by a $700 million investment[5]. China emerged as the undisputed leader in perovskite commercialization, with multiple companies racing to scale production lines from megawatt pilot capacity to full industrial output[6].
Behind these headlines lies a fierce and increasingly strategic patent war. For corporate R&D teams in advanced materials and chemicals, understanding who is building the intellectual property moat around next-generation photovoltaics, and where the white space remains, is essential for making informed investment, partnership, and development decisions.
This analysis, conducted using Cypris Q's cross-domain search capabilities spanning patents, academic papers, and industry sources, reveals a landscape where a handful of companies are aggressively staking claims across the full perovskite value chain, from precursor chemistry and deposition methods to device architectures and module-level encapsulation.
The Efficiency Race and Its IP Shadow
The academic literature tells a story of breathtaking progress. Nature Reviews Clean Technology characterized 2025 as a "transformative phase" for perovskite photovoltaics, noting that single-junction efficiencies reached 27% in laboratory conditions while tandem devices exceeded 34.5%[7]. Inverted (p-i-n) perovskite solar cells have achieved certified quasi-steady-state power conversion efficiencies of 26.15% for single-junction devices[8], with more recent work pushing beyond 27% through advanced passivation strategies that dramatically improve both efficiency and thermal stability[9]. Perovskite-silicon tandem cells have surpassed 34.85% efficiency at the lab scale[1][10], and all-perovskite tandem modules have reached a certified 24.5% efficiency over a 20.25 cm² aperture area[11]. Perovskite solar modules, the form factor that actually matters for commercial deployment, have achieved a certified 23.30% efficiency over a 27.22 cm² aperture, representing the highest certified module performance to date for that configuration[12].
What makes this relevant for IP strategy is that each of these efficiency milestones is underpinned by specific material innovations that are being aggressively patented. The dual-site-binding ligand approach that enabled the 26.15% single-junction record[8] represents a class of surface passivation chemistry that multiple companies are now racing to protect. The bilayer interface passivation technique used in high-efficiency tandem cells[10] has direct parallels in LONGi's patent filings covering resistance-increasing nanostructures at the carrier transport layer interface[13]. The dopant-additive synergism strategy that achieved the module efficiency record[12], using methylammonium chloride with Lewis-basic ionic liquid additives, exemplifies the kind of formulation IP that specialty chemical companies should be watching closely.
LONGi: The Patent Juggernaut
A Cypris Q search of LONGi's recent patent portfolio reveals a company that is not merely participating in the perovskite transition but attempting to own it. LONGi's filings span an extraordinary breadth of the technology stack. At the device architecture level, the company holds patents on tandem photovoltaic devices with engineered tunnel junctions featuring ordered defect layers and precisely controlled doping concentrations[14], perovskite-crystalline silicon tandem cells with carrier transport layers incorporating resistance-increasing nanostructures that extend into the perovskite light absorption layer[13], and four-terminal laminated cells with edge-region resistance engineering to reduce carrier recombination losses[15].
On the manufacturing side, LONGi has filed patents covering roller coating devices for perovskite films with integrated film-homogenizing assemblies that improve thickness uniformity[16], spin-coating thermal annealing composite preparation systems designed to prevent precursor solution degradation during substrate transfer[17], and full-silicon-wafer-sized perovskite/crystalline silicon laminated solar cells where the perovskite layer thickness is deliberately varied between central and peripheral areas to prevent conduction between composite and window layers[18]. The company has even patented perovskite material bypass diodes, a module-level innovation that uses P-type and N-type perovskite material regions to create integrated protection circuitry[19][20].
Perhaps most telling is LONGi's patent on copper powder with organic coating layers and in-situ grown copper nanoparticles for use in perovskite cell metallization[21]. This filing, surfaced through a Cypris Q assignee-specific patent search, signals that LONGi is thinking beyond the perovskite absorber layer itself and into the full bill of materials, including conductive pastes and interconnection technologies. LONGi's tandem cell R&D team has consistently pushed the boundaries of the technology since achieving 33.9% efficiency in November 2023, followed by 34.6% in June 2024, and the current 34.85% record in April 2025[1], each milestone built on patented innovations in bilayer interface passivation and asymmetric textured silicon substrates. For materials suppliers, this kind of vertical IP integration should be a strategic signal that the company intends to control not just device performance but the entire manufacturing ecosystem.
Oxford PV: The Vapor Deposition Moat and Its Strategic Monetization
Oxford PV, the UK-based company that spun out of Henry Snaith's pioneering research at the University of Oxford, has taken a fundamentally different approach to IP protection. Where LONGi's portfolio is broad and manufacturing-oriented, Oxford PV's filings are concentrated around a specific technical differentiator: vapor-phase deposition of perovskite materials onto textured silicon surfaces.
A Cypris Q analysis of Oxford PV's recent patent activity reveals a deep portfolio centered on methods for depositing substantially continuous and conformal perovskite layers on surfaces with roughness averages of 50 nm or greater using vapor deposition followed by treatment with further precursor compounds[22][23][24]. This is not an academic exercise. It is the core manufacturing challenge of perovskite-silicon tandems, because the textured surface of a silicon bottom cell, which is essential for light trapping, makes it extremely difficult to deposit uniform perovskite films using conventional solution-based methods.
Oxford PV has extended this core IP into sequential deposition methods using physical vapor deposition of metal halide precursors with different halide components[25][26], processes for making multicomponent perovskites through co-sublimation from multiple evaporation sources[27][28][29], and methods for forming crystalline perovskite layers through a two-dimensional-to-three-dimensional conversion pathway[30]. The company has also filed on multijunction device architectures incorporating metal oxynitride interlayers, preferably titanium oxynitride, between sub-cells to avoid local shunt paths and reduce reflection losses[31], as well as photovoltaic devices with intermediate barrier layers and dual metallic arrays for improved encapsulation and electrical contact[32][33]. Oxford PV's IP strategy also includes passivation chemistry, with patents covering organic passivating agents that are chemically bonded to anions or cations in the metal halide perovskite[34], and device architectures featuring inorganic electrically insulative layers with band gaps greater than 4.5 eV forming type-1 offset junctions[35][36][37][38]. This layered approach, controlling both the deposition process and the device physics, creates a formidable barrier to entry for competitors attempting to replicate Oxford PV's vapor-based tandem approach.
What makes Oxford PV's IP strategy particularly notable in 2025 is that the company has begun actively monetizing it. The April 2025 patent licensing agreement with Trina Solar, covering the manufacture and sale of perovskite-based photovoltaic products in China with sublicensing rights, represents one of the first major patent monetization events in the perovskite industry[4]. Oxford PV's CEO David Ward explicitly invited other parties interested in licensing outside China to make contact, signaling that the company views its patent portfolio not just as a defensive moat but as a revenue-generating asset and a mechanism for shaping the global supply chain. For R&D teams evaluating the perovskite landscape, this development confirms that IP position in this space has crossed from theoretical value to commercial leverage.
The Chinese Manufacturing Giants: Jinko, Trina, GCL, and the Scale Play
While LONGi leads in perovskite-specific IP among Chinese manufacturers, Jinko Solar, Trina Solar, and GCL Optoelectronics are building their own patent positions with distinct strategic emphases. A Cypris Q search reveals that Jinko Solar's recent filings are heavily concentrated on back-contact cell architectures and passivated contact structures that serve as the silicon bottom cell platform for future tandem integration[39][40][41][42]. Jinko's patents on solar cells with micro-protrusion structures on doped semiconductor layers[43] and cells with holes distributed across edge regions filled with passivation material[44] suggest the company is optimizing its silicon cell technology specifically for compatibility with perovskite top cells.
Trina Solar's patent activity reveals a more direct engagement with perovskite-specific challenges. The company has filed on hole transport composite layers using nickel oxide/cerium oxide/self-assembled monolayer stacks for perovskite solar cells[45], laminated batteries with three-junction architectures (crystalline silicon plus two perovskite sub-cells) featuring inter-layer packaging that prevents water and oxygen penetration into perovskite active layers[46], and nano-transparent interlayers containing insulating metal oxide nanoparticles designed to increase light scattering and reduce reflection losses at tandem stacking interfaces[47]. Trina has also patented light conversion films based on benzotriazole compounds that reduce ultraviolet light transmission while improving external quantum efficiency response[48], addressing the well-known UV degradation vulnerability of perovskite materials. The Trina-Oxford PV licensing agreement adds another dimension to Trina's strategy, providing the company with access to Oxford PV's foundational vapor deposition IP while simultaneously validating the importance of patent portfolios as a currency of competition in this space[4].
GCL Optoelectronics, though less prominent in the Cypris Q patent analysis, deserves attention as the company making the most aggressive manufacturing bet. Its June 2025 commissioning of the world's first gigawatt-scale perovskite module facility in Kunshan, producing 2.76 m² large-area tandem modules, represents a $700 million wager that perovskite manufacturing can scale[5]. GCL's tandem module efficiency has reached a certified 29.51% at industrial scale[49], and the company has deployed what it calls the world's first AI-powered high-throughput perovskite manufacturing system, using 52 precision sensors and an AI decision engine that reportedly reduces lab-to-factory conversion time by up to 90%[49]. For corporate R&D teams watching the manufacturing landscape, GCL's moves signal that the race to gigawatt-scale perovskite production is no longer hypothetical.
The Stability Frontier: Where Materials Science Meets IP Strategy
The single greatest barrier to perovskite commercialization remains long-term operational stability, and this is where the patent landscape intersects most directly with the interests of advanced materials and specialty chemical companies. Academic research has demonstrated that state-of-the-art passivation techniques relying on ammonium ligands suffer deprotonation under light and thermal stress[9], that self-assembled monolayer hole transport layers can be desorbed by strong polar solvents in perovskite precursors if anchored by hydrogen bonds rather than covalent bonds[50], and that phase segregation in wide-bandgap perovskites remains a fundamental challenge for tandem architectures[51].
Each of these failure modes represents both a technical challenge and a patent opportunity. The development of amidinium ligands with resonance-enhanced N-H bonds that resist deprotonation achieved a greater than tenfold reduction in ligand deprotonation equilibrium constant[9]. Tridentate anchoring of self-assembled monolayers through trimethoxysilane groups on fully covalent hydroxyl-covered surfaces enabled devices that retained 98.9% of initial efficiency after 1,000 hours of damp-heat testing[50]. Thiocyanate ion incorporation suppressed phase segregation in wide-bandgap perovskites, enabling perovskite/organic tandems with 25.06% efficiency[51].
The encapsulation challenge is generating its own IP ecosystem. Cypris Q patent searches reveal filings on composite packaging adhesive films that enable lamination of perovskite batteries below 105°C without introducing peroxide crosslinking agents harmful to perovskite[52], and buffer structures with conformal compact layers and three-dimensional architectures designed to protect photovoltaic modules from mechanical impact[53][54]. These encapsulation and packaging innovations represent a particularly attractive entry point for specialty materials companies, as they leverage existing competencies in polymer chemistry, barrier films, and adhesive formulations. The fact that GCL's tandem modules have already passed TUV Rheinland's triple IEC stress tests[5] suggests that encapsulation solutions are maturing rapidly, but the diversity of deployment environments, from the high UV exposure of the Gobi Desert to the humidity of coastal building-integrated installations, means that the market for differentiated encapsulation technologies is far from settled.
Where the White Space Remains
For R&D teams evaluating where to invest, the patent landscape as mapped through Cypris Q reveals several areas where IP density is still relatively low compared to the technical opportunity. Scalable deposition methods beyond spin-coating and vapor deposition, particularly slot-die coating, inkjet printing, and blade coating, are seeing growing academic attention but remain underpatented relative to their commercial importance[55][56][57]. The pathway from laboratory-scale tandems to industrial fabrication requires appropriate, scalable input materials and manufacturing processes, and the transition demands increasing focus on stability, reliability, throughput, and cell-to-module integration[55].
Lead-free perovskite compositions represent another area where the gap between research activity and patent protection is notable. The toxicity of lead in perovskite materials remains a significant regulatory and public perception challenge[57], yet the patent landscape is still dominated by lead-based compositions. All-perovskite tandems using mixed lead-tin narrow-bandgap sub-cells are advancing rapidly, the certified 24.5% module efficiency used this architecture[11], but the tin oxidation challenge creates opportunities for novel stabilization chemistries that are not yet well-protected.
The aqueous synthesis of perovskite precursors represents a potentially disruptive manufacturing approach. Recent work demonstrated kilogram-scale production of formamidinium lead iodide microcrystals with up to 99.996% purity from inexpensive, low-purity raw materials, achieving 25.6% cell efficiency[58]. This approach could fundamentally change the precursor supply chain, and the IP landscape around aqueous perovskite chemistry is still nascent. Similarly, the integration of AI and machine learning into perovskite manufacturing workflows, as GCL's high-throughput system demonstrates[49], is creating a new category of process IP that sits at the intersection of materials science and industrial automation.
What This Means for Corporate R&D
The perovskite photovoltaic IP landscape is consolidating rapidly. LONGi, Oxford PV, and the major Chinese manufacturers are building patent portfolios that span device architectures, deposition methods, passivation chemistries, and module-level packaging. Oxford PV's licensing deal with Trina Solar has established that perovskite patents are not just defensive instruments but commercially valuable assets that command real revenue in a market projected to reach $100 billion by 2030[4]. GCL's gigawatt-scale factory has demonstrated that manufacturing investment is following the IP, not waiting for it[5].
For corporate R&D teams in advanced materials and chemicals, the strategic implications are clear. The window for establishing foundational IP in core perovskite device architectures is narrowing, but significant opportunities remain in enabling materials, including passivation agents, encapsulants, barrier films, conductive pastes, and precursor chemistries, where the intersection of materials science expertise and photovoltaic application knowledge creates defensible positions.
Tools like Cypris Q enable R&D teams to monitor this landscape in real time, tracking not just who is filing but what specific technical claims are being staked, where the citation networks point, and where the gaps between academic breakthroughs and patent protection create strategic openings. In a technology transition this consequential, the difference between leading and following often comes down to the quality of competitive intelligence informing R&D investment decisions.
Citations
(1) "34.85%! LONGi Breaks World Record for Crystalline Silicon-Perovskite Tandem Solar Cell Efficiency Again." https://www.longi.com/en/news/silicon-perovskite-tandem-solar-cells-new-world-efficiency/
(2) "Perovskite solar cells: Progress continues in efficiency, durability, and commercialization." https://ceramics.org/ceramic-tech-today/perovskite-solar-cells-progress-2025/
(3) "Perovskite panels headed to US solar farm." https://optics.org/news/15/9/16
(4) "Oxford PV and Trinasolar announce a landmark Perovskite PV patent licensing agreement." https://www.oxfordpv.com/press-releases/oxford-pv-and-trinasolar-announce-a-landmark-perovskite-pv-patent-licensing-agreement
(5) "GCL Optoelectronics finishes 1 GW perovskite PV module factory in China." https://www.pv-magazine.com/2025/06/26/gcl-optoelectronics-commissions-1-gw-perovskite-solar-module-factory-in-china/
(6) "Why China is leading perovskite solar commercialization." https://cen.acs.org/business/inorganic-chemicals/China-leading-perovskite-solar-commercialization/103/web/2025/08
(7) Park, N.G., Snaith, H.J. & Miyasaka, T. "Key advances in perovskite solar cells in 2025." Nature Reviews Clean Technology 2, 6-7 (2026). https://doi.org/10.1038/s44359-025-00128-z
(8) Abdulaziz S. R. Bati, Aidan Maxwell, Zhijun Ning, Jian Xu, and Mercouri G. Kanatzidis. "Improved charge extraction in inverted perovskite solar cells with dual-site-binding ligands." Science. https://doi.org/10.1126/science.adm9474
(9) Isaiah W. Gilley, Abdulaziz S. R. Bati, Lin X. Chen, Chuying Huang, and Selengesuren Suragtkhuu. "Amidination of ligands for chemical and field-effect passivation stabilizes perovskite solar cells." Science. https://doi.org/10.1126/science.adr2091
(10) Yu Jia, Xixiang Xu, Ping Li, Zhenguo Li, and Chuanxiao Xiao. "Perovskite/silicon tandem solar cells with bilayer interface passivation." Nature. https://doi.org/10.1038/s41586-024-07997-7
(11) Anh Dinh Bui, Xuntian Zheng, Jin Xie, Hairen Tan, and Jin-Kun Wen. "Homogeneous crystallization and buried interface passivation for perovskite tandem solar modules." Science. https://doi.org/10.1126/science.adj6088
(12) Farzaneh Fadaei-Tirani, Linhua Hu, Sixia Hu, Olga A. Syzgantseva, and Jun Peng. "Dopant-additive synergism enhances perovskite solar modules." Nature. https://doi.org/10.1038/s41586-024-07228-z
(13) LONGI GREEN ENERGY TECHNOLOGY CO., LTD. Perovskite-Crystalline Silicon Tandem Cell Comprising Carrier Transport Layer Having Resistance-Increasing Nano Structure. Patent No. US-20250294952-A1. Issued Sep 17, 2025.
(14) LONGI GREEN ENERGY TECHNOLOGY CO., LTD. Tandem photovoltaic device and production method. Patent No. US-12426381-B2. Issued Sep 22, 2025.
(15) LONGI GREEN ENERGY TECHNOLOGY Co., Ltd. Perovskite solar cell and four-terminal laminated cell. Patent No. CN-223298006-U. Issued Sep 1, 2025.
(16) LONGI GREEN ENERGY TECHNOLOGY Co., Ltd. Roller coating device and method for perovskite film. Patent No. CN-121155853-A. Issued Dec 18, 2025.
(17) LONGI GREEN ENERGY TECHNOLOGY Co., Ltd. Perovskite photovoltaic cell solution spin-coating thermal annealing composite preparation system. Patent No. CN-121038562-A. Issued Nov 27, 2025.
(18) LONGI GREEN ENERGY TECHNOLOGY Co., Ltd. Perovskite/crystalline silicon laminated solar cell with full silicon wafer size and preparation method thereof. Patent No. CN-119053166-B. Issued Nov 3, 2025.
(19) LONGI GREEN ENERGY TECHNOLOGY CO., LTD. Perovskite material bypass diode and preparation method therefor, perovskite solar cell module and preparation method therefor, and photovoltaic module. Patent No. US-12471390-B2. Issued Nov 10, 2025.
(20) LONGI GREEN ENERGY TECHNOLOGY CO., LTD. Perovskite Material Bypass Diode And Preparation Method Therefor, Perovskite Solar Cell Module And Preparation Method Therefor, And Photovoltaic Module. Patent No. AU-2025213641-A1. Issued Aug 27, 2025.
(21) LONGI GREEN ENERGY TECHNOLOGY Co., Ltd. Copper powder, preparation method and related application thereof. Patent No. CN-120527061-A. Issued Aug 21, 2025.
(22) OXFORD PHOTOVOLTAICS LTD. Method for depositing perovskite material. Patent No. CN-113659081-B. Issued Aug 18, 2025.
(23) OXFORD PHOTOVOLTAICS LIMITED. Method of Depositing a Perovskite Material. Patent No. US-20250149260-A1. Issued May 7, 2025.
(24) OXFORD PHOTOVOLTAICS LIMITED. Method of depositing a perovskite material. Patent No. US-12230455-B2. Issued Feb 17, 2025.
(25) OXFORD PHOTOVOLTAICS LIMITED. Sequential Deposition of Perovskites. Patent No. US-20250268091-A1. Issued Aug 20, 2025.
(26) Oxford Photovoltaics Limited. Sequential Deposition of Perovskites. Patent No. EP-4490336-A1. Issued Jan 14, 2025.
(27) OXFORD PHOTOVOLTAICS LIMITED. Process for Making Multicomponent Perovskites. Patent No. US-20250212674-A1. Issued Jun 25, 2025.
(28) Oxford Photovoltaics Limited. Process for Making Multicomponent Perovskites. Patent No. EP-4490337-A1. Issued Jan 14, 2025.
(29) OXFORD PHOTOVOLTAICS LTD. Method for producing multicomponent perovskite. Patent No. CN-119301295-A. Issued Jan 9, 2025.
(30) OXFORD PHOTOVOLTAICS LTD. Method for forming crystalline or polycrystalline layers of organic-inorganic metal halide perovskite. Patent No. CN-112840473-B. Issued Jan 9, 2025.
(31) OXFORD PHOTOVOLTAICS LIMITED. Multijunction photovoltaic devices with metal oxynitride layer. Patent No. US-12300446-B2. Issued May 12, 2025.
(32) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic Device. Patent No. TW-202539463-A. Issued Sep 30, 2025.
(33) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic Device. Patent No. WO-2025125821-A1. Issued Jun 18, 2025.
(34) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic device comprising a metal halide perovskite and a passivating agent. Patent No. US-12288825-B2. Issued Apr 28, 2025.
(35) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic Device. Patent No. US-20250287769-A1. Issued Sep 10, 2025.
(36) OXFORD PHOTOVOLTAICS LTD. Photovoltaic Device. Patent No. JP-2025098100-A. Issued Jun 30, 2025.
(37) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic device. Patent No. US-12349530-B2. Issued Jun 30, 2025.
(38) OXFORD PHOTOVOLTAICS LIMITED. Photovoltaic device. Patent No. AU-2020274424-B2. Issued Jun 4, 2025.
(39) Jingke energy (Haining) Co., Ltd. and Jinko Solar Co., Ltd. Back contact solar cell and photovoltaic module. Patent No. CN-119521854-B. Issued Feb 5, 2026.
(40) Zhejiang Jinko Solar Co., Ltd. Back contact photovoltaic cell, preparation method thereof, laminated cell and photovoltaic module. Patent No. CN-121001460-B. Issued Feb 5, 2026.
(41) Jinko Solar Co., Ltd. and Zhejiang Jinko Solar Co., Ltd. Solar cell, method for preparing solar cell, and photovoltaic module. Patent No. US-12543403-B2. Issued Feb 2, 2026.
(42) Shangrao JinkoSolar No.3 Intelligent Manufacturing Co., Ltd. and Zhejiang Jinko Solar Co., Ltd. Back contact battery, preparation method thereof, back contact laminated battery and photovoltaic module. Patent No. CN-121463576-A. Issued Feb 2, 2026.
(43) Jinko Solar Co., Ltd. and Zhejiang Jinko Solar Co., Ltd. Solar cell, preparation method thereof and photovoltaic module. Patent No. CN-121487353-A. Issued Feb 5, 2026.
(44) ZHEJIANG JINKO SOLAR CO., LTD. Solar Cell and Photovoltaic Module. Patent No. AU-2026200184-A1. Issued Jan 28, 2026.
(45) TRINASOLAR Co., Ltd. Hole transport composite layer, perovskite solar cell and preparation method thereof. Patent No. CN-121487437-A. Issued Feb 5, 2026.
(46) TRINASOLAR Co., Ltd. Laminated battery and preparation method thereof. Patent No. CN-121487438-A. Issued Feb 5, 2026.
(47) TRINASOLAR Co., Ltd. Laminated battery and preparation method thereof. Patent No. CN-121463647-A. Issued Feb 2, 2026.
(48) TRINASOLAR Co., Ltd. Light conversion film based on benzotriazole compound, and preparation method and application thereof. Patent No. CN-121449563-A. Issued Feb 2, 2026.
(49) "GCL achieves 29.51% efficiency for perovskite-silicon tandem module." https://www.pv-magazine.com/2025/06/02/gcl-achieves-29-51-efficiency-for-perovskite-silicon-tandem-module/
(50) Yangzi Shen, Hongcai Tang, Zhichao Shen, Liyuan Han, and Yanbo Wang. "Reinforcing self-assembly of hole transport molecules for stable inverted perovskite solar cells." Science. https://doi.org/10.1126/science.adj9602
(51) Christoph J. Brabec, Xingxing Jiang, Heyi Yang, Fu Yang, and Yunxiu Shen. "Suppression of phase segregation in wide-bandgap perovskites with thiocyanate ions for perovskite/organic tandems with 25.06% efficiency." Nature Energy. https://doi.org/10.1038/s41560-024-01491-0
(52) CYBRID TECHNOLOGIES INC. and Zhejiang Saiwu Application Technology Co., Ltd. Composite packaging adhesive film and preparation method and application thereof. Patent No. CN-121471829-A. Issued Feb 5, 2026.
(53) Suzhou Guoxian Innovation Technology Co., Ltd. Buffer structure, preparation method thereof and photovoltaic module. Patent No. CN-121474300-A. Issued Feb 5, 2026.
(54) Suzhou Guoxian Innovation Technology Co., Ltd. Buffer structure, preparation method thereof and photovoltaic module. Patent No. CN-121474299-A. Issued Feb 5, 2026.
(55) Erkan Aydın, Lujia Xu, Esma Ugur, Thomas G. Allen, and Michele De Bastiani. "Pathways toward commercial perovskite/silicon tandem photovoltaics." Science. https://doi.org/10.1126/science.adh3849
(56) Chuang Yang, Yinhua Zhou, Anyi Mei, Hongwei Han, and Fengwan Guo. "Achievements, challenges, and future prospects for industrialization of perovskite solar cells." Light Science & Applications. https://doi.org/10.1038/s41377-024-01461-x
(57) Shangshang Chen, Jinsong Huang, Ruiqi Mao, Jiaqi Dai, and Chuanlu Chen. "Toward the Commercialization of Perovskite Solar Modules." Advanced Materials. https://doi.org/10.1002/adma.202307357
(58) Xianyong Zhou, Zhixin Liu, Peide Zhu, Nam-Gyu Park, and Siying Wu. "Aqueous synthesis of perovskite precursors for highly efficient perovskite solar cells." Science. https://doi.org/10.1126/science.adj7081
How to Efficiently Track Emerging Scientific Trends: A Practical Guide for R&D Teams
There is a paradox at the heart of corporate R&D intelligence. The teams whose strategic decisions depend most on understanding where science and technology are heading are often the least equipped to track those shifts systematically. Individual researchers stay current in their narrow specialties. Leadership reads the same handful of industry reports everyone else reads. And the gap between those two levels of awareness, the gap where the most consequential emerging trends actually live, goes largely unmonitored.
This is not a knowledge problem. It is a workflow problem. The information exists. Global scientific output reached 3.3 million peer-reviewed articles in 2022 according to the National Science Foundation's Science and Engineering Indicators, and patent applications hit a record 3.5 million filings in the same year according to WIPO data. The raw material for trend intelligence is abundant. What most R&D organizations lack is a systematic method for converting that raw material into timely, decision-grade insight.
This guide lays out a practical framework for doing exactly that, drawn from the methods that high-performing corporate R&D teams actually use to stay ahead of emerging scientific and technical trends.
Understanding What "Emerging" Actually Means
Before building a trend-tracking system, it helps to get precise about what qualifies as an emerging scientific trend, because the word gets used loosely and the ambiguity leads to wasted effort.
A genuinely emerging trend has a distinct signature. It typically begins with a small number of papers or patents from independent research groups converging on similar concepts, often using slightly different terminology. Publication volume in the area starts accelerating, but it has not yet attracted broad attention or mainstream media coverage. The ratio of original research articles to review articles remains high, meaning the field is still in an active discovery phase rather than a consolidation phase. Research published in Heliyon (Akst et al., 2024) found that this ratio of reviews to original research is actually one of the strongest indicators for distinguishing topics on an upward trajectory from those that have already peaked, and that emerging topics can be predicted as much as five years in advance using a combination of publication time series, patent data, and language model analysis.
This matters for R&D teams because it draws a clear line between trend tracking and trend following. By the time a technology or scientific concept shows up in Gartner hype cycles, McKinsey reports, or keynote presentations at industry conferences, it is no longer emerging. The companies that gain the most strategic advantage from trend intelligence are the ones that identify shifts during the early acceleration phase, when patent landscapes are still forming, when the terminology is still settling, and when the competitive implications are not yet obvious.
There are essentially three stages where R&D trend intelligence creates distinct types of value. In the early detection stage, the goal is to spot signals that a new area of scientific activity is gaining momentum before competitors recognize it, creating a window for exploratory research investments, talent recruitment, or early patent positioning. In the acceleration stage, the goal shifts to understanding the trajectory of a trend that is clearly underway, tracking which specific technical approaches are gaining traction, which organizations are leading, and where the white space exists. In the maturation stage, the goal becomes monitoring for saturation, convergence, or disruption, understanding when a technology area is shifting from growth to consolidation, or when adjacent breakthroughs might redefine the competitive landscape.
Each stage demands different data sources, different analytical methods, and different organizational responses. A trend-tracking system that only does one of these well will miss the others entirely.
The Four Data Sources That Matter Most (And How They Complement Each Other)
Most R&D teams default to monitoring scientific publications, and for good reason. The peer-reviewed literature remains the most detailed and reliable record of what researchers are actually discovering. But publications alone provide an incomplete and often delayed picture of emerging trends. A comprehensive trend-tracking operation draws on four distinct data sources, each of which reveals a different dimension of the innovation landscape.
Scientific publications, including peer-reviewed journal articles, preprints, and conference proceedings, reveal what the research community is actively investigating and what findings are being validated. They are the most detailed source of technical information but carry a built-in time lag. The median time from manuscript submission to publication in many fields exceeds six months, and for journals with the highest impact factors, it can stretch beyond a year. Preprint servers like arXiv, bioRxiv, and chemRxiv partially close this gap by making research available months before formal publication, but they cover some disciplines far better than others.
Patent filings reveal what organizations are investing in and intending to commercialize. A patent filing represents a concrete, expensive commitment. It means someone has decided that a technology is worth the cost of legal protection, a much stronger commercial signal than a published paper. Patent data is also forward-looking in a way that publications are not. Because most patent applications are published 18 months after filing, and because the invention typically predates the filing itself, patents provide a window into corporate R&D activity that may be 18 to 36 months ahead of the published literature. Analysis by TPR International found that patent filing trends and non-patent literature publication trends closely track each other over multi-decade timescales, but patent filings often lead, with a longer lag between a filing and the corresponding academic publication than previously assumed. For R&D teams, this means that a sudden increase in patent filings around a specific technology is one of the strongest early indicators of an emerging commercial trend.
Research funding data, from agencies like the National Science Foundation, the European Research Council, the National Institutes of Health, DARPA, and their equivalents in China, Japan, and South Korea, reveals where governments and institutional funders are placing bets. Funding decisions are inherently forward-looking. When a major funding agency launches a new program around a specific technical area, it signals both a perceived opportunity and a forthcoming increase in research activity that will begin producing publications and patents two to five years later. Monitoring funding announcements is one of the most underused trend-tracking methods in corporate R&D, despite being one of the most predictive.
Competitive intelligence, including corporate press releases, hiring patterns, M&A activity, startup funding rounds, and conference presentations, reveals how industry players are interpreting and acting on scientific trends. When a major competitor hires a cluster of researchers with expertise in a specific area, or when venture capital funding surges into a particular technology space, these are commercial signals that complement and contextualize what the scientific data shows.
The real power of trend tracking emerges when these four data sources are monitored simultaneously and analyzed together. A new cluster of publications in an obscure chemistry subfield might not seem significant on its own. But if those publications are accompanied by a parallel increase in patent filings from major chemical companies, a new NSF funding initiative, and venture capital flowing into startups in the space, the combined signal is unmistakable. Each data source compensates for the blind spots of the others.
Building a Practical Trend-Tracking Workflow
With the data sources identified, the next step is building a workflow that converts raw information into actionable intelligence on a repeatable basis. This is where most R&D organizations struggle, not because the concept is complicated but because the operational discipline required is often underestimated.
The foundation of the workflow is a well-defined set of monitoring topics organized in a hierarchy. At the top level are your core technology domains, the broad areas that define your competitive landscape. Beneath those are specific sub-topics and technical questions that reflect current strategic priorities. And at the edges are adjacent and peripheral areas where disruptive innovation is most likely to originate. This topic hierarchy should be reviewed and updated quarterly, because as trends evolve, the monitoring framework needs to evolve with them.
For each monitoring topic, establish both passive surveillance and active investigation protocols. Passive surveillance consists of automated alerts and periodic scans designed to flag new activity without requiring manual effort. This includes saved searches in patent and literature databases configured to run on a daily or weekly basis, table-of-contents alerts for key journals in your focus areas, and automated feeds from preprint servers. The goal of passive surveillance is coverage: ensuring that significant developments do not go unnoticed.
Active investigation is the deeper analysis you conduct when passive surveillance surfaces something interesting. This is where you shift from "what is happening" to "what does it mean" and "what should we do about it." Active investigation involves reading and synthesizing key papers, mapping the patent landscape around a specific technology, identifying the leading research groups and their institutional affiliations, assessing the maturity and trajectory of the trend, and evaluating its relevance to your organization's strategic priorities.
A practical cadence that works for most enterprise R&D teams breaks down as follows. On a daily basis, automated alerts should surface new patent filings, preprints, and publications matching your monitoring topics. These alerts should be triaged by a designated analyst or rotated among team members, with the goal of flagging anything that warrants deeper investigation. On a weekly basis, a brief synthesis meeting or summary document should capture the most significant developments of the week, organized by technology domain. This is the point where individual data points start getting connected into patterns. On a monthly basis, a more substantive trend analysis should assess the direction and velocity of change in each core technology domain, incorporating data from all four sources. This monthly analysis is where you begin making forward-looking assessments about where trends are heading and what competitive implications they carry. On a quarterly basis, trend intelligence should feed directly into strategic planning discussions, informing portfolio decisions, partnership evaluations, and long-term R&D roadmaps.
The most common failure mode is not a lack of data collection but a breakdown in the synthesis and communication steps. Many R&D organizations collect enormous amounts of information but fail to distill it into a form that is useful for decision-makers. The weekly synthesis and monthly analysis steps are where trend tracking either creates strategic value or degenerates into busy work.
Advanced Techniques for Detecting Weak Signals
The most valuable emerging trends are often the hardest to spot because they have not yet developed the clear, consistent terminology and publication patterns that make them easy to search for. Detecting these weak signals requires techniques that go beyond standard keyword monitoring.
One powerful approach is cross-disciplinary convergence analysis. Many of the most significant scientific trends emerge at the intersection of previously separate fields. CRISPR gene editing grew from the convergence of microbiology and bioinformatics. Perovskite solar cells emerged from the intersection of materials science and photovoltaic engineering. Metal-organic frameworks, which CAS identified as a key trend for 2025, represent a convergence of chemistry, materials science, and environmental engineering. By monitoring for instances where concepts from distinct technical domains begin appearing together in the same papers or patents, you can detect these convergences before they become broadly recognized.
Another technique is tracking the migration of researchers across fields. When established scientists in one discipline begin publishing in an adjacent area, it is a strong signal that something interesting is happening at the boundary. Similarly, when a university or corporate lab that is known for work in one area begins filing patents in a different domain, it suggests a deliberate strategic pivot that may reflect early awareness of an emerging opportunity.
Citation pattern analysis offers another lens. When a paper that was initially cited only within a narrow specialty begins attracting citations from researchers in other fields, it is a sign that the work has implications beyond its original context. Tracking these cross-field citation flows can reveal emerging trends before they develop their own dedicated literature.
Finally, terminology drift analysis can surface trends that are genuinely new rather than rebranded versions of existing concepts. When you notice researchers across multiple independent groups independently coining new terms or repurposing existing terms in novel ways, it often indicates that they are describing something that does not fit neatly into existing categories, which is precisely the hallmark of a genuinely emerging field.
These techniques are difficult to execute manually at scale, which is why AI-powered analysis tools have become essential for serious trend-tracking operations. Natural language processing can identify semantic relationships between concepts across millions of documents, clustering related work that uses different terminology and flagging unusual patterns of convergence or migration that human analysts would miss.
Turning Trend Intelligence into Competitive Advantage
Tracking trends without acting on them is an expensive hobby. The entire purpose of a trend-tracking operation is to create a decision advantage, meaning that your organization identifies and responds to important shifts before competitors do.
There are several concrete ways that trend intelligence should feed into R&D decision-making. First, it should inform technology roadmaps by identifying which emerging technologies are likely to become commercially relevant within your planning horizon, and which are still too early-stage to warrant investment. Second, it should guide make-versus-buy-versus-partner decisions by revealing which organizations are leading in specific technology areas and how their capabilities compare to your own. Third, it should shape patent strategy by identifying white space in the patent landscape where early filing could establish valuable positions. Fourth, it should support talent strategy by identifying the academic research groups and institutions producing the most significant work in areas of strategic interest, creating a pipeline for recruiting or collaborative relationships.
The organizations that extract the most value from trend intelligence are the ones that treat it as an ongoing strategic input rather than a periodic exercise. When trend tracking is embedded in the regular cadence of R&D planning, when it has a clear owner and a direct line to decision-makers, it becomes a genuine source of competitive advantage rather than a report that sits unread in someone's inbox.
A Note on Tools
The tooling landscape for R&D trend tracking ranges from free academic search engines to comprehensive enterprise platforms. For individual researchers doing targeted literature searches, tools like Google Scholar, PubMed, and Semantic Scholar remain valuable. For patent-specific monitoring, Google Patents and Espacenet provide free access to large databases. For research funding intelligence, tools like NIH RePORTER and NSF Award Search are indispensable.
However, enterprise R&D teams that need to track trends systematically across patents, scientific literature, and competitive intelligence at scale will quickly outgrow free tools. The fundamental limitation of point solutions is fragmentation: running separate searches across separate databases with separate interfaces and then manually synthesizing the results is time-consuming and error-prone, and it makes the kind of cross-source pattern recognition described above nearly impossible.
Cypris was built specifically for this problem. It is an enterprise R&D intelligence platform that provides unified access to more than 500 million patents and scientific papers through a single interface, powered by a proprietary R&D ontology and multimodal search capabilities that go beyond simple keyword matching to surface conceptually related work across data sources. For R&D teams that need to move from fragmented, manual trend tracking to a systematic, AI-powered intelligence operation, Cypris provides the data breadth, analytical depth, and enterprise-grade security infrastructure to support that transition. Its API partnerships with OpenAI, Anthropic, and Google also make it straightforward to integrate R&D intelligence into existing workflows and applications. You can learn more at cypris.ai.
Frequently Asked Questions
What is the most efficient way to track emerging scientific trends?The most efficient approach combines automated monitoring across multiple data sources, including scientific publications, patents, preprints, and research funding data, with a structured organizational cadence for synthesis and decision-making. Enterprise R&D intelligence platforms that unify these data sources in a single interface dramatically reduce the manual effort required and enable cross-source pattern recognition that would be impossible with fragmented tools.
What tools are best for staying updated on technical trends?The best tools for staying updated on technical trends depend on your scale and needs. Free tools like Google Scholar, PubMed, and Semantic Scholar work well for individual researchers conducting focused literature reviews. Patent monitoring tools like Google Patents and Espacenet cover patent data. For enterprise R&D teams that need systematic, ongoing trend tracking across both patents and scientific literature, purpose-built R&D intelligence platforms like Cypris offer unified data access and AI-powered analysis that point solutions cannot match.
How far in advance can emerging scientific trends be predicted?Research using PubMed data across 125 diverse scientific topics has demonstrated that topic popularity levels and directional changes can be predicted up to five years in advance using a combination of historical publication time series, patent data, and language model analysis. Patent filings are particularly strong leading indicators, as they typically precede related academic publications by 18 to 36 months and represent concrete commercial commitments.
Why should R&D teams monitor patent data alongside scientific publications?Patent filings represent expensive, deliberate commercial commitments that reveal what organizations intend to bring to market. They are forward-looking in a way that publications are not, often leading the published literature by 18 to 36 months. When patent activity, publication trends, and funding data are analyzed together, they produce a far stronger and earlier signal of emerging trends than any single data source alone.
How often should R&D teams review emerging scientific trends?Best practice involves daily automated alerts for critical developments, weekly synthesis of key signals organized by technology domain, monthly trend analysis reports assessing direction and velocity of change, and quarterly strategic reviews that connect trend intelligence to portfolio decisions and R&D roadmaps. The most common failure mode is collecting information without systematically synthesizing and communicating it to decision-makers.